BTW, DOWNLOAD part of EduDump DP-750 dumps from Cloud Storage: https://drive.google.com/open?id=11W4exuY6Bd4xkseyUmIIPCMX-AS085Nx
Passing the DP-750 Exam is a challenging task, but with EduDump Microsoft Practice Test engine, you can prepare yourself for success in one go. The DP-750 online practice test engine offers an interactive learning experience and includes Microsoft DP-750 Practice Questions in a real DP-750 Exam scenario. This allows you to become familiar with the DP-750 exam format and identify your weak areas to improve them.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Topic 2: Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Topic 3: Prepare and process data | 30–35% | - Ingest and transform data
|
| Topic 4: Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
>> New Microsoft DP-750 Exam Question <<
There are multiple choices on the versions of our DP-750 learning guide to select according to our interests and habits since we have three different versions of them: the PDF, the Software and the APP online. The PDF version of our DP-750 exam dumps can be printed. And the Software and APP online versions of our DP-750 Preparation materials can be practiced on computers or phones. They are new developed for the reason that electronics products have been widely applied to our life and work style.
NEW QUESTION # 79
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You need to configure Cluster1 to meet the following requirements:
- The cluster must scale up automatically when workloads increase.
- The cluster must scale down automatically when workloads decrease.
The solution must minimize costs.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,D
Explanation:
Enabling autoscaling and setting a 30-minute auto-termination timeout is the correct configuration to meet the goals.
Autoscaling handles fluctuating workloads, while auto-termination prevents you from paying for idle compute resources.
Dynamic Scaling: Autoscaling automatically adds workers during high loads and removes them when demand drops.
Cost Control: The 30-minute termination window ensures the cluster shuts down completely if no jobs are running, stopping all compute charges.
Reference:
https://community.databricks.com/t5/get-started-discussions/cluster-auto-termination-best- practices/td-p/75826
NEW QUESTION # 80
Which feature provides end-to-end tracking of data movement in Databricks?
Answer: C
Explanation:
Unity Catalog provides data lineage tracking across ingestion, transformation, and consumption layers. It helps visualize dependencies and compliance auditing. Spark logs are low-level and not structured for lineage. Query history is partial only.
NEW QUESTION # 81
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2. You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.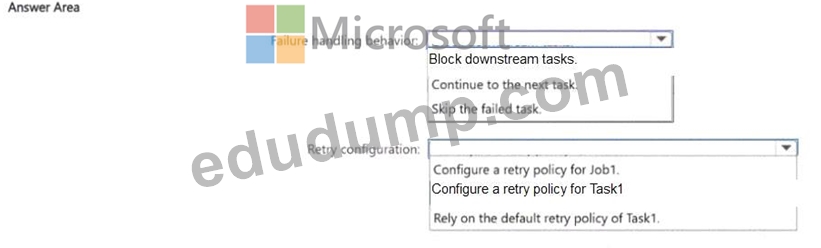
Answer:
Explanation: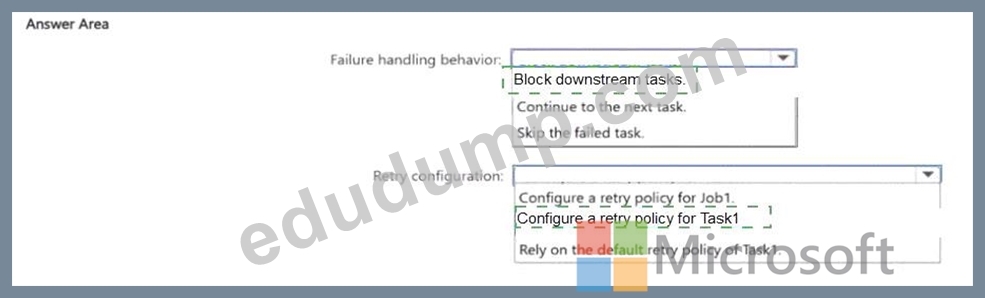
Explanation:
Two task-level settings solve this:
Task1 retry policy: configure Task1 with a maximum number of retries and a retry interval. When Task1 fails, Lakeflow Jobs automatically re-runs it up to the retry limit without any manual intervention. This handles transient infrastructure failures transparently.
Task2 run condition set to 'All succeeded' with Task1 as its dependency: this means Task2 only starts when Task1 has succeeded. If Task1 fails and exhausts all retries, Task2 remains blocked - it never runs on data from a failed upstream ingestion. The dependency is declared in Task2's 'Depends on' setting in the job configuration.
These two settings are independent and composable. Task1's retry policy gives it multiple chances to recover.
Task2's dependency and run condition ensure the downstream transformation only runs on clean, successfully ingested data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#task-retries
NEW QUESTION # 82
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named Catalog 1. Catalog 1 contains a table named Transactions. Transactions contains the following columns:
* transaction_id
* customet_name
* email address
* credit_card_number
* transaction_amount
You need to ensure that business analysts can query all the tows in the Transactions table. The solution must meet the following requirements:
* Prevent the analysts from seeing the full values in the email_address and credit_catd_number columns.
* Ensure that the analysts can see only the values after the @ character in each email address.
* Ensure that the analysts can see only the last four digits of each credit card number.
* Enable the analysts to query the table without errors.
* Follow the principle of least privilege.
What should you do?
Answer: B
Explanation:
The correct answer is C. Column masks are the right tool when you need to partially expose sensitive data rather than hide it entirely. A column mask is a SQL function attached to a column that rewrites the returned value based on who is querying. For email_address, the mask returns only the substring after '@'. For credit_card_number, it returns only the last four digits. Business analysts get useful data without seeing anything sensitive, and they can still query the table without errors.
Option A (row-level filters) controls which rows a user sees, not the values within a row - it can't partially redact a column. Option B (grant SELECT only on non-sensitive columns) removes the columns entirely, so analysts can't see even partial email or card values - that doesn't meet the 'can see only partial values' requirement. Option D (column-level encryption) requires key management infrastructure and decryption at query time, which is significantly more complex than column masking for this use case.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/row-and-column- filters
NEW QUESTION # 83
What improves join performance for small lookup tables?
Answer: D
NEW QUESTION # 84
......
The Microsoft DP-750 certification is on trending nowadays, and many Microsoft aspirants are trying to get it. Success in the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) test helps you land well-paying jobs. Additionally, the Microsoft DP-750 certification exam is also beneficial to get promotions in your current company. But the main problem that every applicant faces while preparing for the DP-750 Certification test is not finding updated Microsoft DP-750 practice questions.
DP-750 Exam Dumps Collection: https://www.edudump.com/exams/Microsoft/DP-750/
2026 Latest EduDump DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=11W4exuY6Bd4xkseyUmIIPCMX-AS085Nx