What's more, part of that LatestCram DP-100 dumps now are free: https://drive.google.com/open?id=1LrHZvEtpxUzq2BMUoiYbdx9Ir-HGZ7Nn
The company is preparing for the test candidates to prepare the DP-100 exam guide professional brand, designed to be the most effective and easiest way to help users through their want to get the test DP-100 certification and obtain the relevant certification. In comparison with similar educational products, our training materials are of superior quality and reasonable price, so our company has become the top enterprise in the international market. Our DP-100 practice materials have been well received by the users, mainly reflected in the following advantages.
| Section | Weight | Objectives |
|---|---|---|
| Optimize language models for AI applications | 25-30% | - Optimize with Retrieval Augmented Generation
|
| Explore data and run experiments | 20-25% | - Implement pipelines
|
| Train and deploy models | 25-30% | - Deploy models
|
| Design and prepare a machine learning solution | 20-25% | - Manage Azure Machine Learning workspace
|
>> Reliable DP-100 Exam Price <<
We have handled professional DP-100 practice materials for over ten years. Our experts have many years’ experience in this particular line of business, together with meticulous and professional attitude towards jobs. Their abilities are unquestionable, besides, DP-100 Exam Questions are priced reasonably with three kinds: the PDF, Software and APP online. Though the content is the same, but their displays are totally different and functionable.
NEW QUESTION # 418
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You create a model to forecast weather conditions based on historical data.
You need to create a pipeline that runs a processing script to load data from a datastore and pass the processed data to a machine learning model training script.
Solution: Run the following code: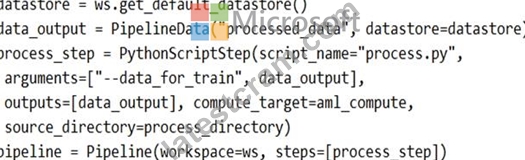
Does the solution meet the goal?
Answer: B
Explanation:
train_step is missing.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-pipeline-core/azureml.pipeline.core.pipelinedata?view=azu
NEW QUESTION # 419
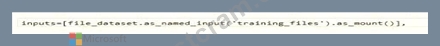
You register a file dataset named csvjolder that references a folder. The folder includes multiple com ma- separated values (CSV) files in an Azure storage blob container. You plan to use the following code to run a script that loads data from the file dataset. You create and instantiate the following variables: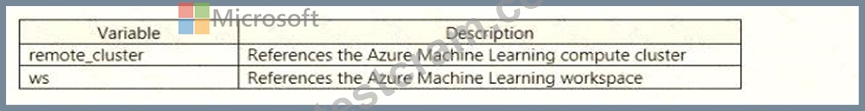
You have the following code: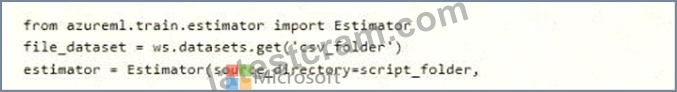
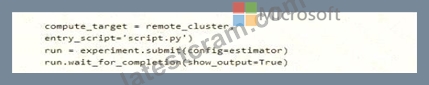
You need to pass the dataset to ensure that the script can read the files it references. Which code segment should you insert to replace the code comment?



Answer: B
Explanation:
Example:
from azureml.train.estimator import Estimator
script_params = {
# to mount files referenced by mnist dataset
'--data-folder': mnist_file_dataset.as_named_input('mnist_opendataset').as_mount(),
'--regularization': 0.5
}
est = Estimator(source_directory=script_folder,
script_params=script_params,
compute_target=compute_target,
environment_definition=env,
entry_script='train.py')
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/tutorial-train-models-with-aml
NEW QUESTION # 420
You register a file dataset named csvjolder that references a folder. The folder includes multiple com ma- separated values (CSV) files in an Azure storage blob container. You plan to use the following code to run a script that loads data from the file dataset. You create and instantiate the following variables: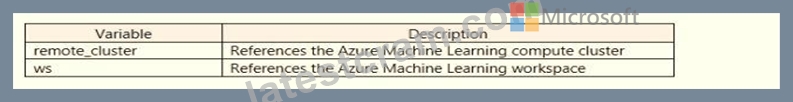
You have the following code: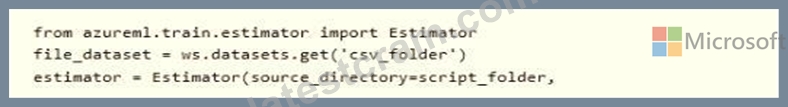
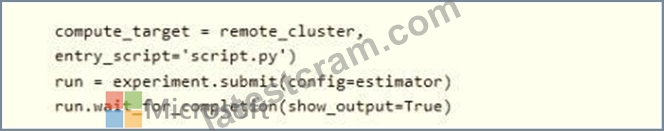
You need to pass the dataset to ensure that the script can read the files it references. Which code segment should you insert to replace the code comment?
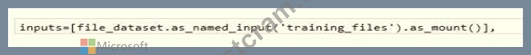



Answer: C
Explanation:
Example:
from azureml.train.estimator import Estimator
script_params = {
# to mount files referenced by mnist dataset
' --data-folder ' : mnist_file_dataset.as_named_input( ' mnist_opendataset ' ).as_mount(),
' --regularization ' : 0.5
}
est = Estimator(source_directory=script_folder,
script_params=script_params,
compute_target=compute_target,
environment_definition=env,
entry_script= ' train.py ' )
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/tutorial-train-models-with-aml
NEW QUESTION # 421
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are using Azure Machine Learning to run an experiment that trains a classification model.
You want to use Hyperdrive to find parameters that optimize the AUC metric for the model. You configure a HyperDriveConfig for the experiment by running the following code: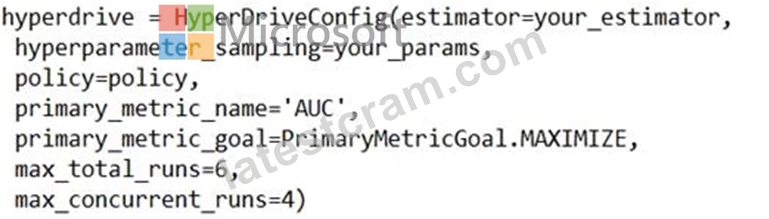
You plan to use this configuration to run a script that trains a random forest model and then tests it with validation data. The label values for the validation data are stored in a variable named y_test variable, and the predicted probabilities from the model are stored in a variable named y_predicted.
You need to add logging to the script to allow Hyperdrive to optimize hyperparameters for the AUC metric.
Solution: Run the following code: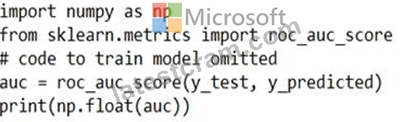
Does the solution meet the goal?
Answer: B
Explanation:
Use a solution with logging.info(message) instead.
Note: Python printing/logging example:
logging.info(message)
Destination: Driver logs, Azure Machine Learning designer
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-debug-pipelines
NEW QUESTION # 422
You are developing a linear regression model in Azure Machine Learning Studio. You run an experiment to compare different algorithms.
The following image displays the results dataset output: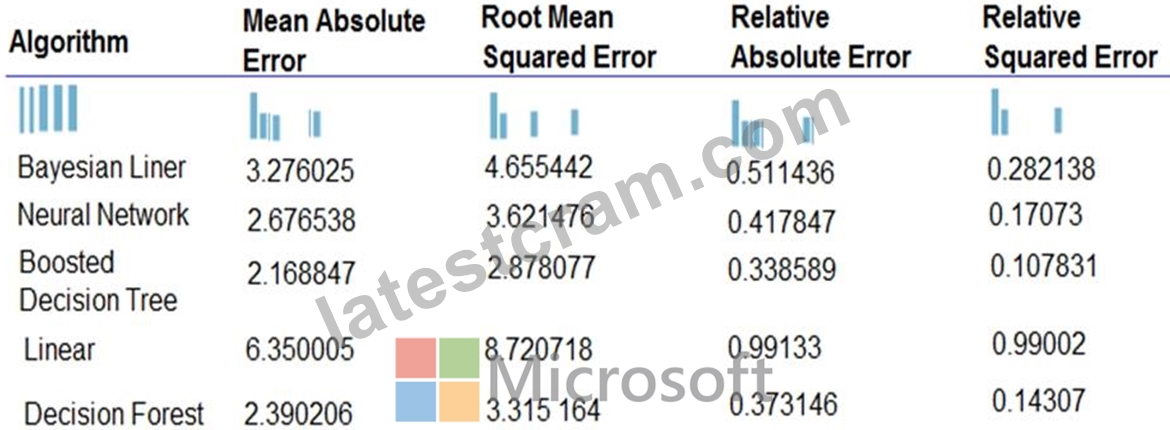
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the image.
NOTE: Each correct selection is worth one point.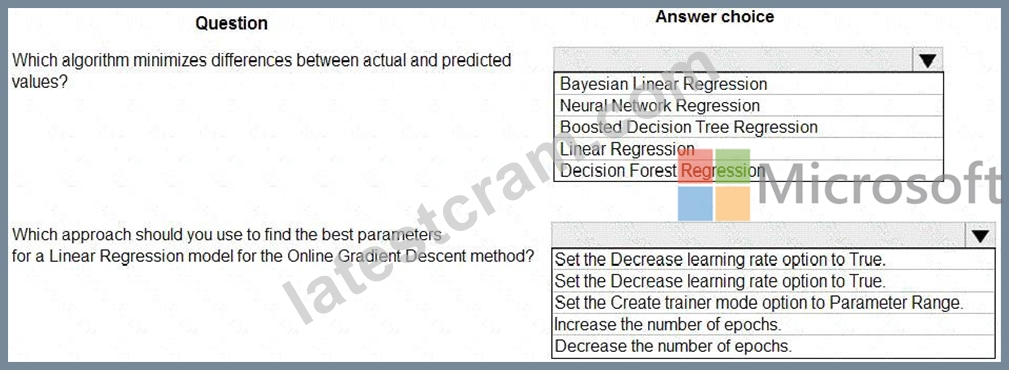
Answer:
Explanation: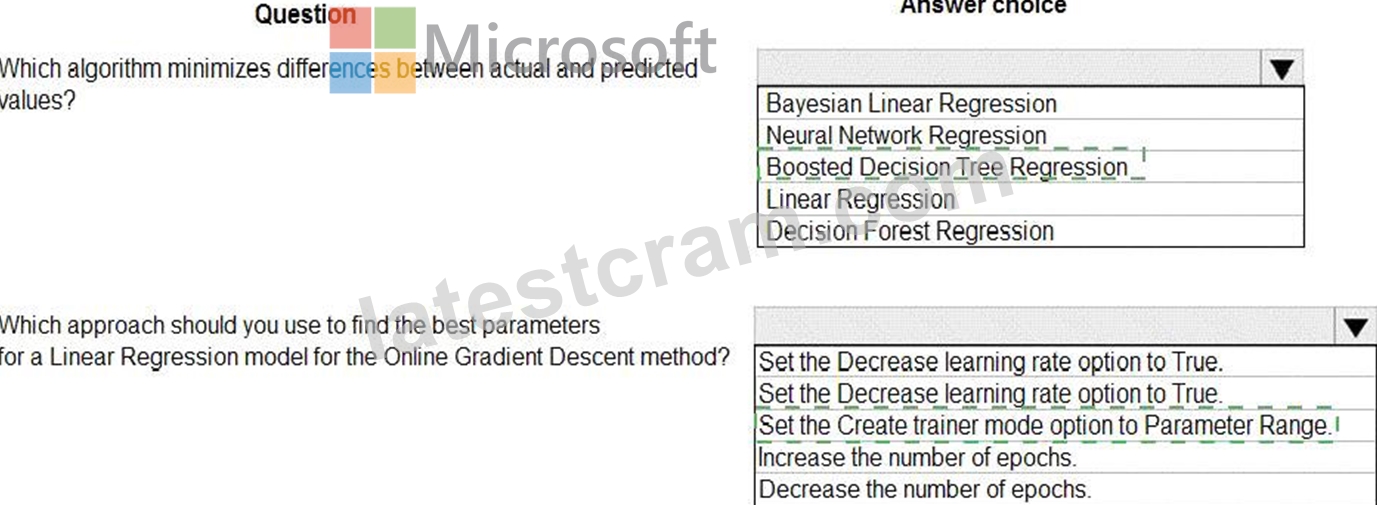
Explanation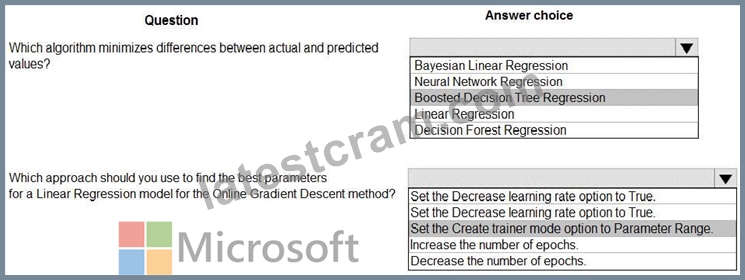
Box 1: Boosted Decision Tree Regression
Mean absolute error (MAE) measures how close the predictions are to the actual outcomes; thus, a lower score is better.
Box 2:
Online Gradient Descent: If you want the algorithm to find the best parameters for you, set Create trainer mode option to Parameter Range. You can then specify multiple values for the algorithm to try.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/evaluate-model
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/linear-regression
NEW QUESTION # 423
......
It is not easy to absorb the knowledge we learn, so, we often forget these information. When you choose our Microsoft DP-100 Practice Test, you will know that it is your necessity and you have to purchase it. You can easily pass the exam. To trust in LatestCram, it will help you to open a new prospect.
Reliable DP-100 Test Labs: https://www.latestcram.com/DP-100-exam-cram-questions.html
DOWNLOAD the newest LatestCram DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1LrHZvEtpxUzq2BMUoiYbdx9Ir-HGZ7Nn