2026 Latest Exams4sures DP-800 PDF Dumps and DP-800 Exam Engine Free Share: https://drive.google.com/open?id=1aeDk3WpDVL0X_8EjwJxNNW9c8RGmMO3R
One can start using product of Exams4sures instantly after buying. The 24/7 support system is available for the customers so that they don't stick to any problems. If they do so, they can contact the support system, which will assist them in the right way and solve their issues. A lot of Developing AI-Enabled Database Solutions (DP-800) exam applicants have used the Developing AI-Enabled Database Solutions (DP-800) practice material. They are satisfied with it because it is updated.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Microsoft DP-800 Reliable Guide Files <<
When you are hesitating whether to purchase our DP-800 exam software, why not try our free demo of DP-800. Once you have tried our free demo, you will ensure that our product can guarantee that you successfully Pass DP-800 Exam. Our professional IT team of Exams4sures continues updating and improving DP-800 exam dumps in order to guarantee you win the exam while you are preparing for the exam.
NEW QUESTION # 75
You have a database that contains production data. The schema is stored in a Git repository as an SDK-style SQL database project and contains the following reference data.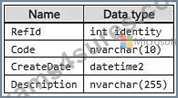
A deployment pipeline can be rerun automatically when a transient failure occurs.
You need to deploy the reference data as part of the same CI/CD process. Rerunning the pipeline must produce the same outcome and must NOT create duplicate rows.
What should you do?
Answer: C
Explanation:
To ensure your reference data deployment is idempotent (safe to rerun) and prevents duplicates within an SDK-style SQL project, you should use a Post-Deployment Script combined with a MERGE statement.
The Core Strategy: MERGE Statement
The MERGE command allows you to synchronize a target table with a source (your hardcoded data) in a single atomic operation. It checks for existing records based on a unique key and decides whether to insert, update, or delete.
Implementation Steps
1. Create a Seed Script
Add a file named Script.PostDeployment.sql to your project.
Set the Build Action to PostDeploy in the file properties.
2. Handle the Identity Column
Since RefID is an IDENTITY column, you must use SET IDENTITY_INSERT [Table] ON to specify exact IDs.
This ensures RefID values remain consistent across environments.
3. Write the Idempotent Logic
Define your reference data in a Common Table Expression (CTE) or a virtual table.
Use the sCode or RefID as the join key to find matches.
Reference:
https://www.mssqltips.com/sqlservertip/5648/including-predetermined-datasets-in-a-microsoft- database-project/
NEW QUESTION # 76
You are developing an Azure SQL database solution from a locally cloned GitHub repository by using Microsoft Visual Studio Code and GitHub Copilot Chat.
You need to ensure that GitHub Copilot Chat can call the hosted GitHub MCP Server tools by using OAuth. The MCP server configuration must be scoped to the repository.
What should you do in Visual Studio Code?
Answer: A
Explanation:
To connect GitHub Copilot Chat to an Azure SQL Database using a hosted GitHub MCP (Model Context Protocol) Server, follow these steps. This setup ensures that Copilot can interact directly with your repository and database schema using OAuth.
Step 1: Configure the MCP Server in VS Code
You must set the scope to the Workspace level to ensure the server is restricted to your specific repository.
Open your locally cloned GitHub repository in VS Code.
Open the Command Palette (Ctrl+Shift+P or Cmd+Shift+P).
Type and select: MCP: Add Server.
Select HTTP (HTTP or Server-Sent Events).
Enter the URL: https://api.githubcopilot.com/mcp/
Crucial: When prompted for the configuration scope, select Workspace Settings.
This saves the config to .vscode/settings.json, binding the server to this repo.
Step 2: Authenticate via OAuth
Once the server is added, Copilot needs permission to act on your behalf.
Open the GitHub Copilot Chat panel.
You will see a notification or a prompt within the chat asking to Authorize the MCP server.
Follow the browser prompts to sign in and grant OAuth permissions.
This allows the hosted MCP server to "see" your repository's code and metadata.
Reference:
https://skywork.ai/skypage/en/The-Ultimate-Guide-to-GitHub's-MCP-Server:-Bridging-AI-and- Your-Codebase/1970685991323758592
NEW QUESTION # 77
Case Study 2 - Fabrikam
Existing Environment
Azure Environment
Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables:
* Patients
* Employees
* Procedures
* Transactions
* UsefulPrompts
* ProcedureDocuments
You store a column master key as a secret in Azure Key Vault.
You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements
Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent.
Requirements
Planned Changes
Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration.
Security Requirements
Fabrikam identifies the following security requirements:
* The TransactionProcessing application must use a passwordless connection to DB1.
* The Employees table contains two columns named TaxID and Salary that must be encrypted at rest.
* Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data.
Database Performance Requirements
Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing
Fabrikam identifies the following AI-related requirements:
* Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
* Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric.
* The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements
Fabrikam identifies the following development requirements:
* Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total.
* Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API:
- Read data from the procedures table without authentication.
- Read and insert data into the Transactions table once authenticated.
- Execute the sp_UpdateProcedurePatient stored procedure.
* Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days.
* Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.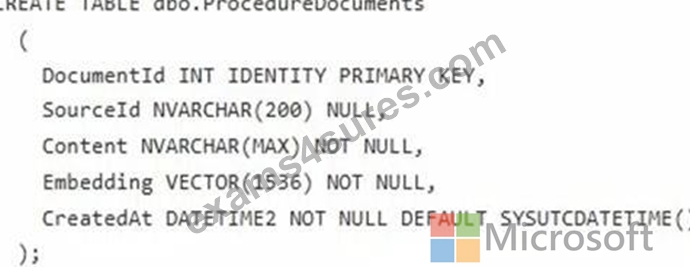
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.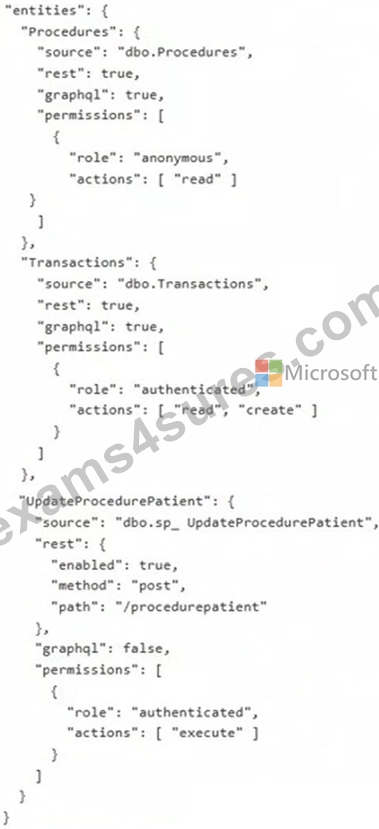
You need to recommend a solution for the TransactionProcessing application that meets the security requirements. What should you include in the recommendation?
Answer: D
Explanation:
Scenario:
You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Security Requirements: Fabrikam identifies the following security requirements: The TransactionProcessing application must use a passwordless connection to DB1.
The most appropriate security solution for an on-premises application connecting to an Azure SQL Database without passwords is Microsoft Entra ID authentication. Specifically, you should implement one of the following Entra-based mechanisms depending on your application's environment and architecture:
*-> 1. Microsoft Entra Service Principal with Certificate
This is the standard "passwordless" approach for non-Azure (on-premises) applications.
How it works: You register the application in Microsoft Entra ID. Instead of a client secret (password), you use a certificate for authentication.
Benefit: No secrets are stored in your code or configuration files. The application uses the certificate to obtain an access token from Entra ID to connect to the database.
2. Microsoft Entra Integrated Authentication
3. Managed Identity (via Azure Arc)
For a more modern approach, you can register your on-premises server with Azure Arc.
How it works: Azure Arc extends Azure's Managed Identity capabilities to on-premises hardware.
Benefit: This is the "gold standard" for passwordless security, as Azure handles the identity, rotation, and lifecycle of the credentials automatically.
Reference:
https://learn.microsoft.com/en-us/azure/developer/java/spring-framework/migrate-sql-database- to-passwordless-connection
NEW QUESTION # 78
You have an Azure SQL database named SalesDB that contains tables named Sales.Orders and Sales.
OrderLines. Both tables contain sales data
You have a Retrieval Augmented Generation (RAG) service that queries SalesDB to retrieve order details and passes the results to a large language model (ILM) as JSON text. The following is a sample of the JSON.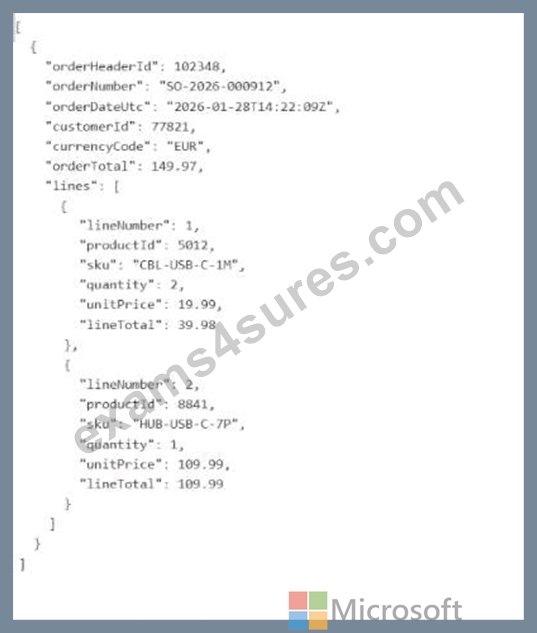
You need to return one 1SON document per order that includes the order header fields and an array of related order lines. The LIM must receive a single JSON array of orders, where each order contains a lines property that is a JSON array of line Items.
Which transact-SQL commands should you use to produce the required JSON shape from the relational tables? To answer, drag the appropriate commands to the correct operations. Each command may be used once, more than once, or not at all. Vou may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.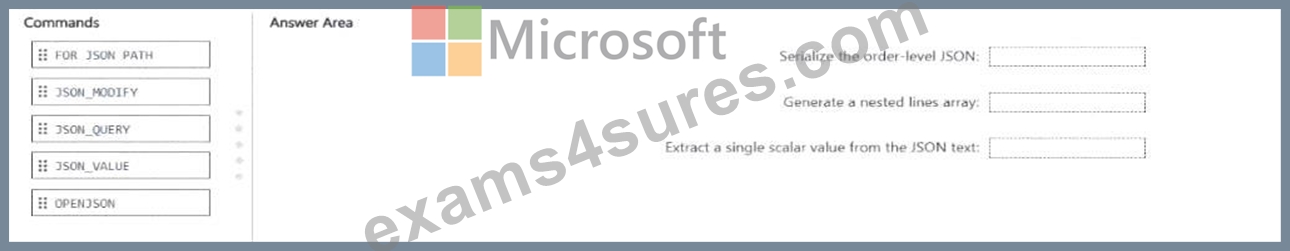
Answer:
Explanation: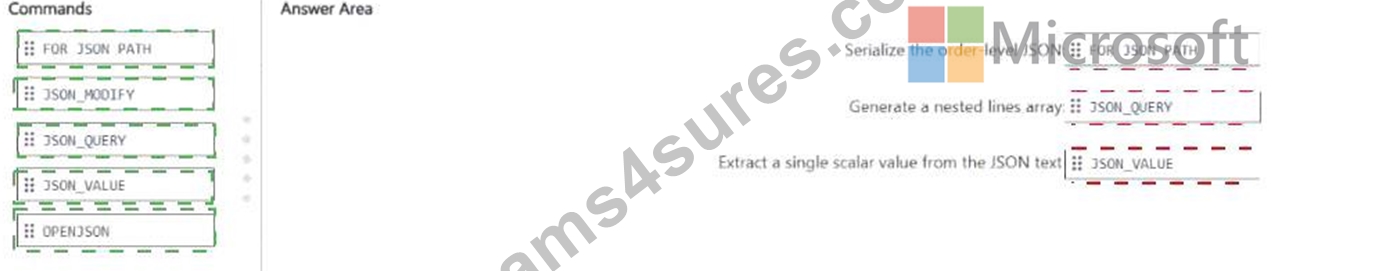
Explanation:
* Serialize the order-level JSON : FOR JSON PATH
* Generate a nested lines array : JSON_QUERY
* Extract a single scalar value from the JSON text : JSON_VALUE
The correct mapping is based on how SQL Server and Azure SQL JSON functions are designed to shape relational data into JSON for AI and RAG scenarios.
To serialize the order-level JSON , use FOR JSON PATH . Microsoft documents that FOR JSON PATH gives you full control over the JSON output shape and formats the result as an array of JSON objects . It is the standard way to turn relational query results into the JSON structure needed by downstream consumers such as APIs and LLM-based RAG services. It also supports nested output through subqueries and aliases.
To generate a nested lines array , use JSON_QUERY . Microsoft explains that JSON_QUERY returns a JSON object or array from JSON text, and it is used when you want to preserve a JSON fragment instead of treating it as plain text. In this scenario, the nested lines property must be emitted as a proper JSON array inside each order document, so JSON_QUERY is the correct command to embed that array in the final JSON shape.
To extract a single scalar value from the JSON text , use JSON_VALUE . Microsoft explicitly states that JSON_VALUE extracts a scalar value from a JSON string, while JSON_QUERY is for objects or arrays. So whenever the requirement is to pull out one property such as an order number, currency code, or customer ID from JSON text, JSON_VALUE is the correct function.
The unused commands are not the best fit here:
* OPENJSON is primarily for parsing JSON into rows and columns, not for shaping relational tables into nested output.
* JSON_MODIFY is for updating JSON text, not generating the required output structure.
So the drag-and-drop answers are:
* Serialize the order-level JSON # FOR JSON PATH
* Generate a nested lines array # JSON_QUERY
* Extract a single scalar value from the JSON text # JSON_VALUE
NEW QUESTION # 79
You have an Azure SQL database that supports an OLTP application.
You need to write Transact-SQL code that returns blocking chain details. The output must return only sessions that ate blocked or are blocking other sessions.
How should you complete the code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.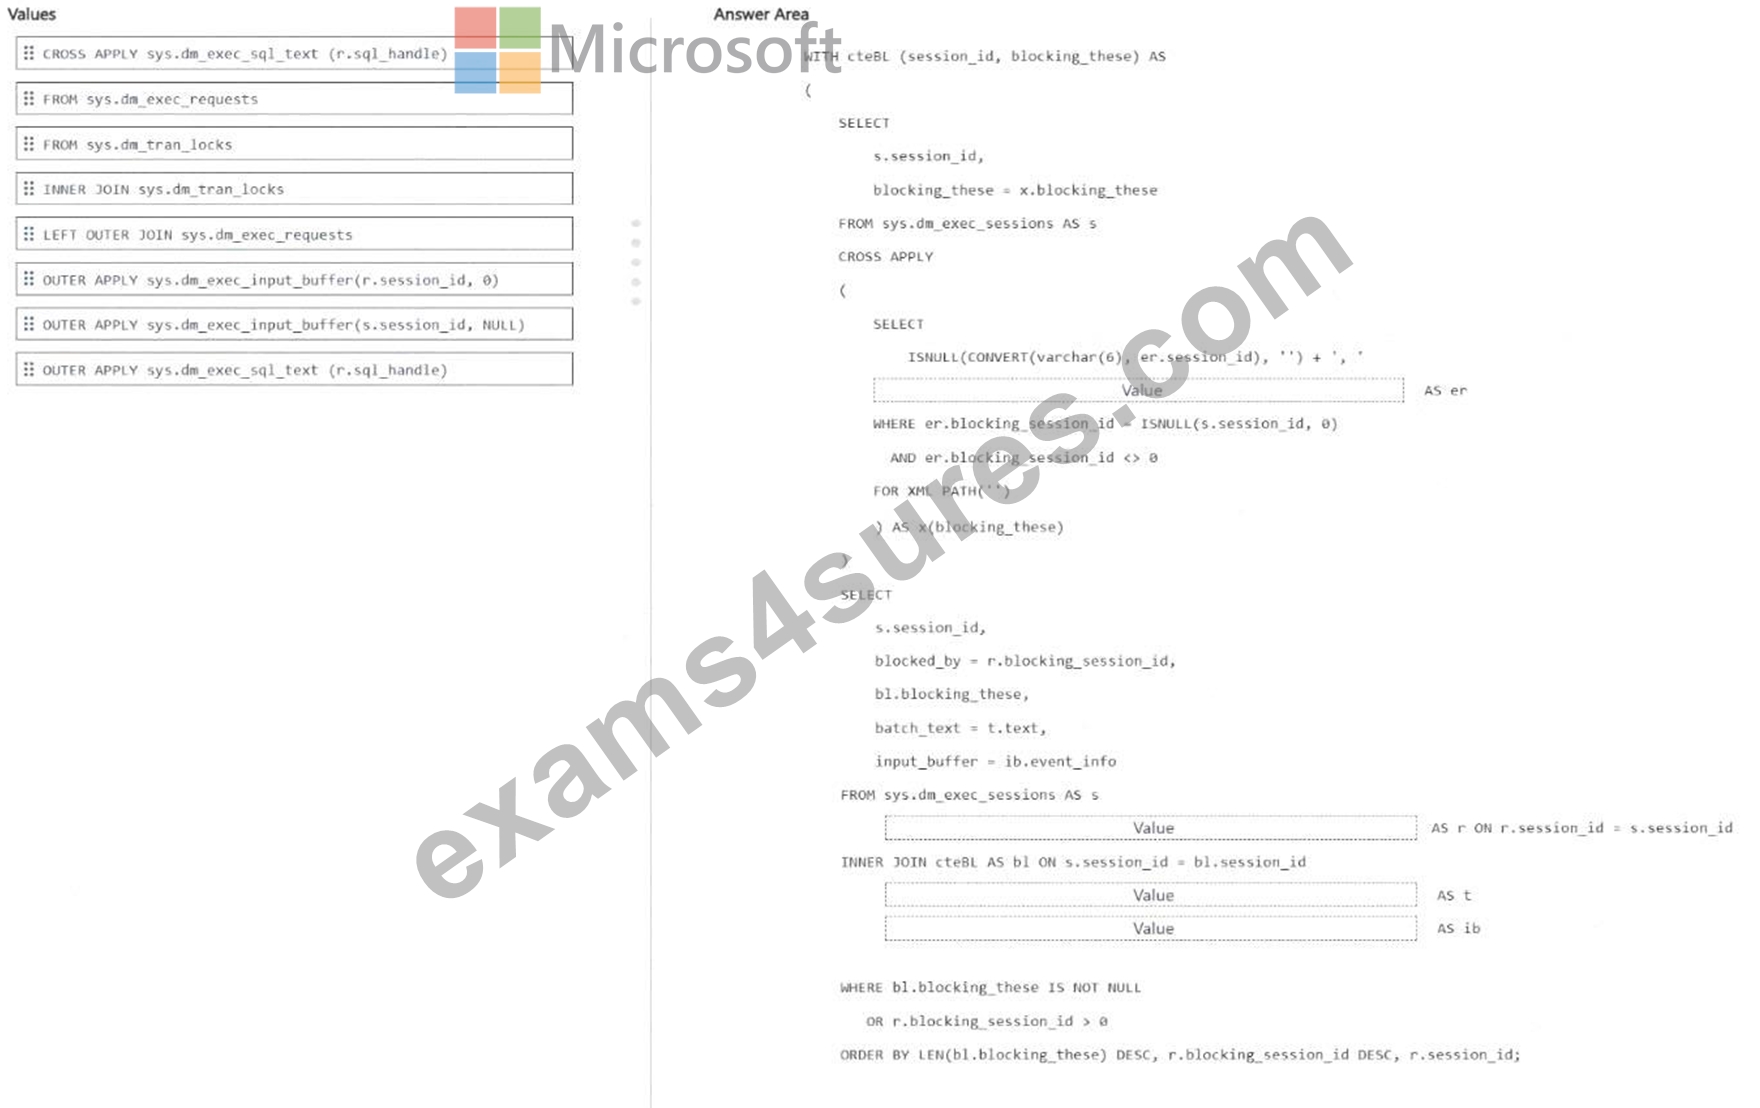
Answer:
Explanation: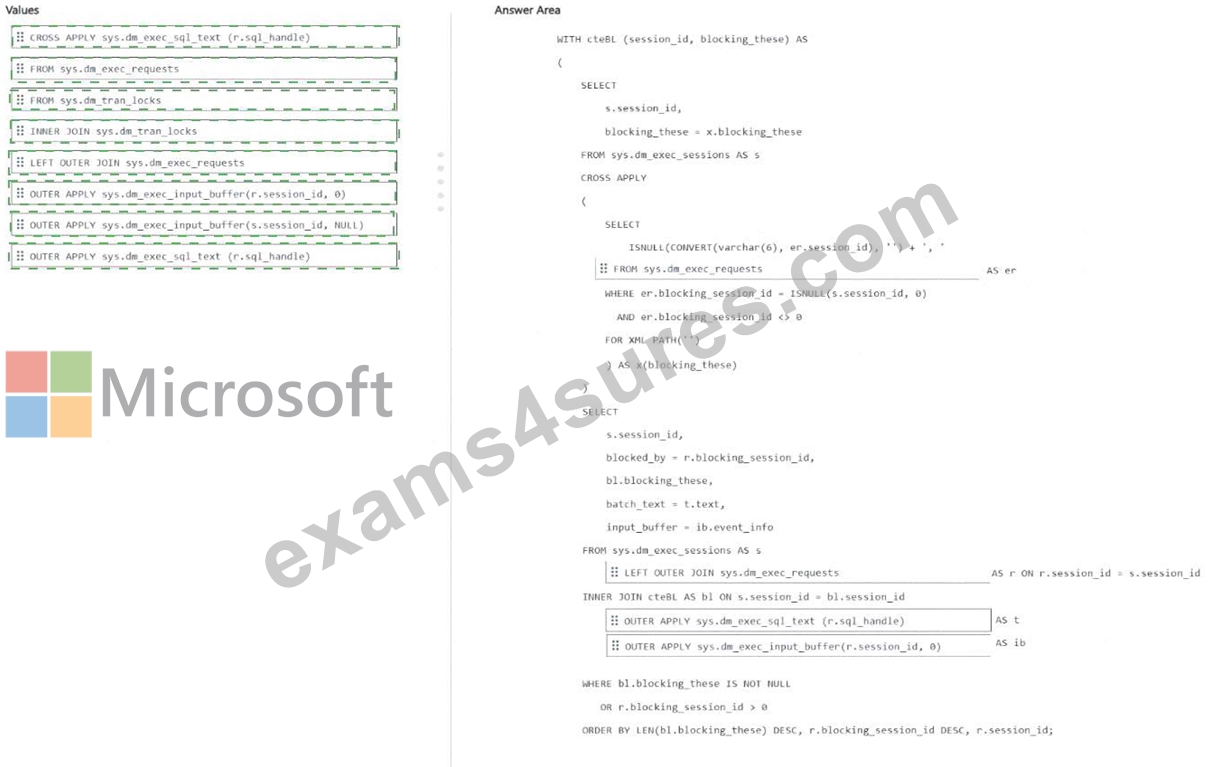
Explanation:
* CTE inner source # FROM sys.dm_exec_requests
* Join after sys.dm_exec_sessions AS s # LEFT OUTER JOIN sys.dm_exec_requests
* Text retrieval # OUTER APPLY sys.dm_exec_sql_text(r.sql_handle)
* Input buffer retrieval # OUTER APPLY sys.dm_exec_input_buffer(r.session_id, r.request_id) The correct drag-and-drop choices are based on how blocking-chain details are normally assembled in Azure SQL Database.
The CTE must read from sys.dm_exec_requests because the alias er is used with er.session_id and er.
blocking_session_id, and those columns come from sys.dm_exec_requests. Microsoft documents that sys.
dm_exec_requests returns information about executing requests and includes the blocking_session_id column used to identify blockers.
After FROM sys.dm_exec_sessions AS s, the correct join is LEFT OUTER JOIN sys.dm_exec_requests so the query can still return sessions from sys.dm_exec_sessions even when a current request row is missing.
This is useful when showing sessions that are blocked or blocking, while still attempting to attach current request details when available.
For batch text, use OUTER APPLY sys.dm_exec_sql_text(r.sql_handle) because Microsoft documents sys.
dm_exec_sql_text(sql_handle) as the function that returns the SQL batch text for the specified sql_handle.
For the input buffer, use OUTER APPLY sys.dm_exec_input_buffer(r.session_id, r.request_id) because Microsoft documents that sys.dm_exec_input_buffer takes session_id and request_id and returns event_info, which is commonly used when sys.dm_exec_sql_text is null or when you want the last command text.
So the completed code uses:
* FROM sys.dm_exec_requests
* LEFT OUTER JOIN sys.dm_exec_requests
* OUTER APPLY sys.dm_exec_sql_text(r.sql_handle)
* OUTER APPLY sys.dm_exec_input_buffer(r.session_id, r.request_id)
NEW QUESTION # 80
......
Our DP-800 study quiz boosts high quality and we provide the wonderful service to the client. We boost the top-ranking expert team which compiles our DP-800 guide prep elaborately and check whether there is the update every day and if there is the update the system will send the update automatically to the client. The content of our DP-800 Preparation questions is easy to be mastered and seizes the focus to use the least amount of answers and questions to convey the most important information.
New DP-800 Dumps Questions: https://www.exams4sures.com/Microsoft/DP-800-practice-exam-dumps.html
P.S. Free 2026 Microsoft DP-800 dumps are available on Google Drive shared by Exams4sures: https://drive.google.com/open?id=1aeDk3WpDVL0X_8EjwJxNNW9c8RGmMO3R