그 외, ITDumpsKR SPS-C01 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=1gWt4Bmaa0vRphn-K8SVVtGlCJMm1c-vx
Snowflake인증SPS-C01시험을 패스함으로 취업에는 많은 도움이 됩니다. ITDumpsKR는Snowflake인증SPS-C01시험패스로 꿈을 이루어주는 사이트입니다. 우리는Snowflake인증SPS-C01시험의 문제와 답은 아주 좋은 학습자료로도 충분한 문제집입니다. 여러분이 안전하게 간단하게Snowflake인증SPS-C01시험을 응시할 수 있는 자료입니다.
| Section | Weight | Objectives |
|---|---|---|
| Snowpark API for Python | 30% | - User-Defined Functions (UDFs) and Stored Procedures - Establishing connections and session management - Working with Semi-structured data - DataFrame creation and manipulation - Reading and writing data |
| Performance Optimization and Best Practices | 20% | - Caching strategies - Debugging and explain plans - Vectorized UDFs - Warehouse sizing for Snowpark - Query pushdown and optimization - Minimizing data transfer |
| Data Transformations and DataFrame Operations | 35% | - Filtering, Aggregating, and Joining DataFrames - Using built-in functions - Window functions - Persisting transformed data - Complex data pipelines |
| Snowpark Concepts | 15% | - Transformations vs. Actions - Client-side vs. Server-side execution - Snowpark Sessions and connection management - Snowpark DataFrames and query plans - Stored procedures and conditional logic - Snowpark architecture and core concepts |
ITDumpsKR는 고품질의 IT Snowflake SPS-C01시험공부자료를 제공하는 차별화 된 사이트입니다. ITDumpsKR는Snowflake SPS-C01응시자들이 처음 시도하는Snowflake SPS-C01시험에서의 합격을 도와드립니다. 가장 적은 시간은 투자하여 어려운Snowflake SPS-C01시험을 통과하여 자격증을 많이 취득하셔서 IT업계에서 자신만의 가치를 찾으세요.
질문 # 100
You have developed a Snowpark application that processes a large volume of customer interaction data'. The application uses a vectorized UDF to classify the sentiment of text-based interactions. Initial tests show the application is performing slowly. Which of the following strategies would be MOST effective for optimizing the performance of sentiment analysis using a vectorized UDF?
정답:D
설명:
Optimizing the vectorized UDF code itself offers the most direct and significant performance gains for sentiment analysis. By streamlining computations, reducing memory allocations, and avoiding unnecessary function calls within the UDF's vectorized function, the processing time for each batch of data can be substantially reduced. Mini-batching (B) is already implicit with vectorization with pandas series/dataframe. Increaseing Number of cores allocated to the virtual warehouse can provide some help but it depends on other factor also. Other oprions may not have impact
질문 # 101
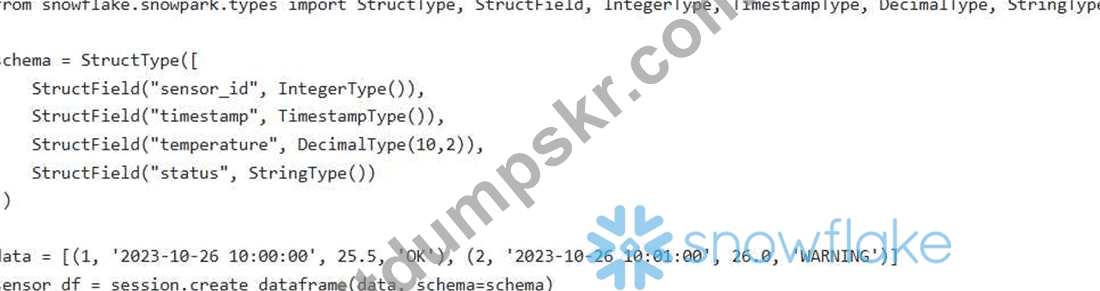
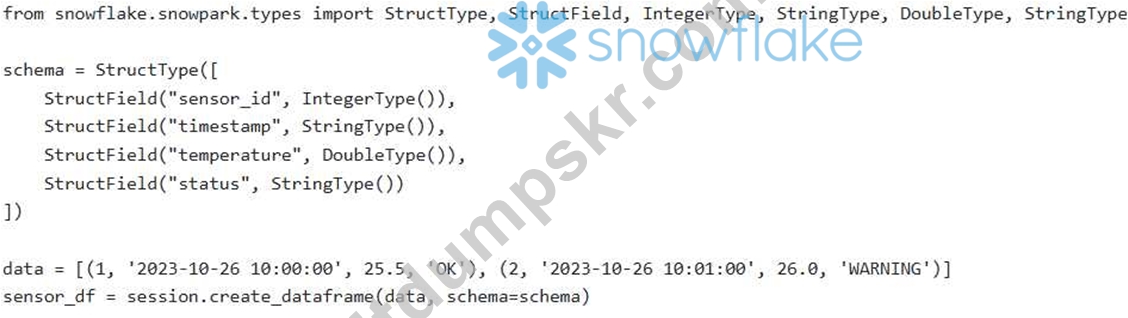
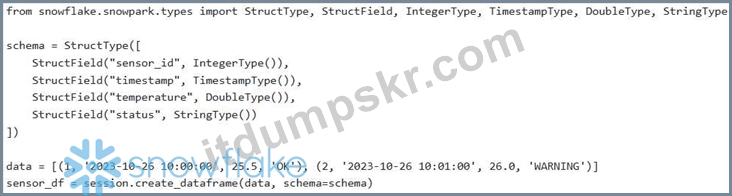
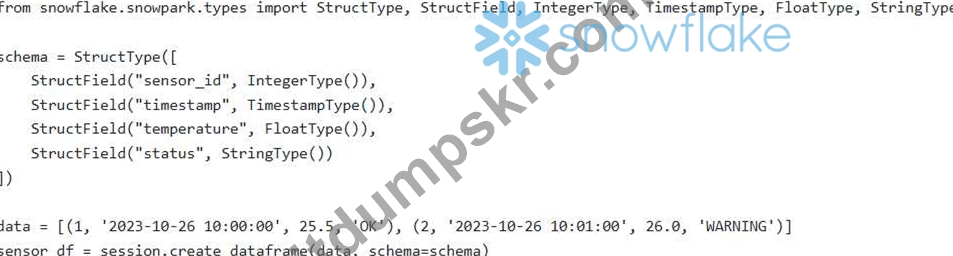
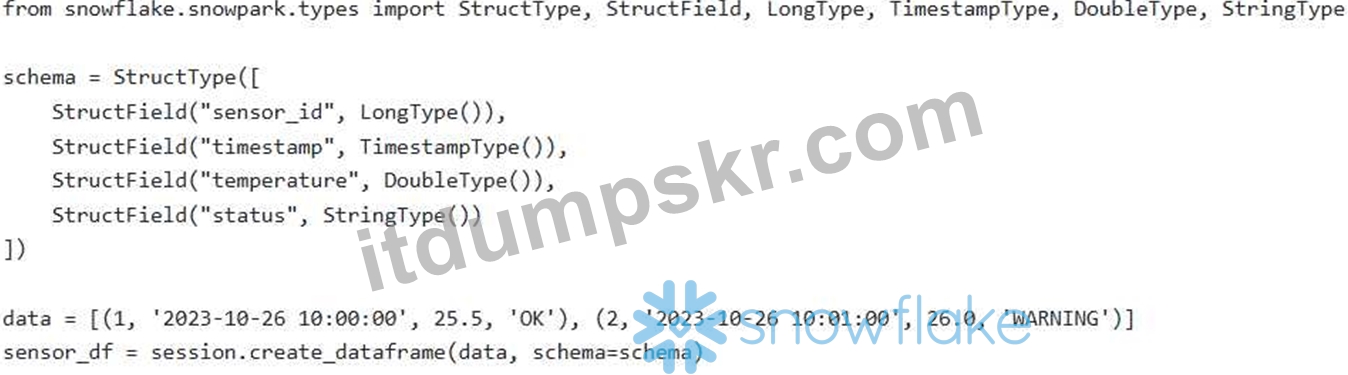
You are working with sensor data in Snowpark. Your data contains (Integer), 'timestamp' (Timestamp), 'temperature' (Double), and 'status' (String). You need to create a Snowpark DataFrame named representing this data'. Which of the following is the most efficient and type-safe way to create the DataFrame from a list of Python tuples using an explicitly defined schema, assuming you need to maintain maximum precision for temperature readings and that all data types should map to the most efficient and appropriate Snowflake data type?
정답:C
설명:
Option B is the most efficient and type-safe way to create the DataFrame. It correctly maps each data element to its most appropriate Snowpark data type: Integer Type for 'sensor_id' , TimestampType for 'timestamp' , DoubleType for 'temperature' (as it offers more precision than FloatType for Snowflake), and StringType for 'status'. While DecimalType could be considered for representing exact numeric values, it's often used for currency or financial data where exact representation is critical. In this case, DoubleType is sufficient for temperature readings. Timestamp values are automatically converted from the string representation. FloatType has less precision than DoubleType. Using LongType for sensor_id might be overkill if the IDs are reasonably small integers. Using StringType for timestamp will require later conversion for time based calculation.
질문 # 102
You are developing a Snowpark application using Visual Studio Code and the Snowflake VS Code extension. You want to configure the extension to automatically detect and use a specific Anaconda environment for your Snowpark development. Assuming you have already created an Anaconda environment named 'snowpark_env', which configuration setting in the VS Code settings.json file would correctly specify the Python path for the Snowflake extension?
정답:E
설명:
Option D is the correct configuration setting. The 'python.defaultlnterpreterPath' setting in VS Code's 'settings.json' file is used to specify the Python interpreter path that VS Code should use for all Python-related tasks, including running and debugging Snowpark applications. Options A and C are incorrect because the Snowflake extension uses standard VS Code Python settings. Option E is for SnowSQL and not directly related to Snowpark Python development within VS Code. The path needs to point to the python executable inside your conda enviornment.
질문 # 103
You have a Snowpark DataFrame 'df sales' containing sales data with columns like 'order id', 'product id', 'quantity', and 'sale_price' You want to persist this data into a Snowflake table named "SALES DATA'. You also want to create a dynamic table on top of this base table for faster analytics. You need to choose the appropriate persistence strategy and consider the implications of using a dynamic table. Which of the following options represents the BEST approach?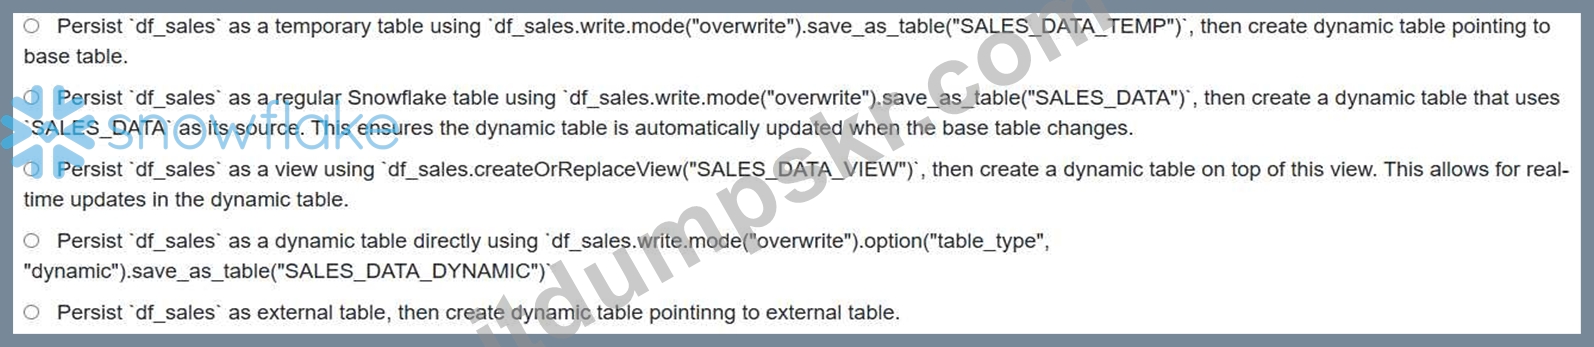
정답:C
설명:
Option B is the best approach because it combines the advantages of persistence with the benefits of dynamic tables. Regular Table Persistence: Persisting as a regular table using DATA") ensures the data is stored durably in Snowflake. This serves as the foundation for the dynamic table. Dynamic Table Creation: Creating a dynamic table that uses 'SALES DATA' as its source provides a materialized view that automatically updates when the base table changes. This allows for faster analytics as the data is pre-computed and optimized for querying. Avoidance of Temporary Tables: Option A uses a temporary table, which is not suitable for long-term storage or scenarios where the data needs to persist beyond the session. Views vs. Dynamic Tables: Option C uses a view, which is not materialized. While views provide real-time access to the data, they can be slower for complex queries compared to dynamic tables. Option D isn't correct as 'table_type' is not a valid option for in Snowpark. Option E isnt valid scenario
질문 # 104
You are building a Snowpark Python application to perform complex data transformations and want to leverage external packages not pre-installed in the Snowflake environment. You need to ensure these packages are available within your Snowpark session. Which of the following methods are valid for deploying and using these third-party packages within your Snowpark Python environment? (Select TWO)
정답:C,D
설명:
Options B and D are the correct approaches for deploying and using external packages in Snowpark. Option B, using 'conda' environment files and , allows defining dependencies in a standard way. Option D, using with Snowflake's Anaconda integration, leverages Snowflake's managed environment. Option A is not the best and can lead to versioning issues. Option C is not possible as you don't have direct access to compute pool nodes. Option E relies on snowCLl, which is related to using the packages in UDFs and procedures, not necessarily for direct session use with external packages. Snowpark Sessions use to add packages directly.
질문 # 105
......
Snowflake인증 SPS-C01시험을 어떻게 공부하면 패스할수 있을지 고민중이시면 근심걱정 버리시고ITDumpsKR 의 Snowflake인증 SPS-C01덤프로 가보세요. 문항수가 적고 적중율이 높은 세련된Snowflake인증 SPS-C01시험준비 공부자료는ITDumpsKR제품이 최고입니다.
SPS-C01시험패스 가능 덤프공부: https://www.itdumpskr.com/SPS-C01-exam.html
참고: ITDumpsKR에서 Google Drive로 공유하는 무료, 최신 SPS-C01 시험 문제집이 있습니다: https://drive.google.com/open?id=1gWt4Bmaa0vRphn-K8SVVtGlCJMm1c-vx