TorrentVCE is website that can take you access to the road of success. TorrentVCE can provide the quickly passing Microsoft certification AI-200 exam training materials for you, which enable you to grasp the knowledge of the certification exam within a short period of time, and pass Microsoft Certification AI-200 Exam for only one-time.
| Section | Weight | Objectives |
|---|---|---|
| Secure, monitor, and optimize AI solutions | 20% | - Manage security and configuration
|
| Develop containerized AI solutions on Azure | 25% | - Implement container hosting environments
|
| Develop AI solutions using Azure data services | 30% | - Design and optimize data access and retrieval
|
| Integrate backend services and build event-driven architectures | 25% | - Build serverless APIs and workflows
|
You can download TorrentVCE Microsoft AI-200 PDF dumps file on your desktop computer, laptop, tab, or even on your smartphone. Just download the AI-200 PDF questions file after paying affordable Prepare for your Developing AI Cloud Solutions on Azure (AI-200) exam questions charges and start Developing AI Cloud Solutions on Azure (AI-200) exam preparation anytime and anywhere.
NEW QUESTION # 34
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You plan to deploy a container to an Azure App Service API app named api1. You host the source code for api1 in a GitHub repository. The container uses the API key at runtime to connect to a backend service.
The container must be able to retrieve the API key at runtime without exposing it in the source repository or Git commit history.
You need to ensure that the API key remains outside of Git commit history and is available to the container at runtime.
Solution: Store the API key as a GitHub repository secret.
Does the solution meet the goal?
Answer: B
Explanation:
Correct:
* Store the API key in Azure Key Vault and reference it from an App Service application setting.
Storing the API key in Azure Key Vault and referencing it via App Service application settings is the recommended, secure approach. This strategy completely removes sensitive credentials from your GitHub repository and Git commit history while injecting them safely into your container environment at runtime.
Incorrect:
* Embed the API key as a hardcoded environment variable in the Dockerfile.
* Store the API key as a GitHub repository secret.
Reference:
https://www.qservicesit.com/full-stack-applications-on-azure
NEW QUESTION # 35
You need to configure a connection string for the partner-facing service according to the technical requirements.
What should you use?
Answer: B
Explanation:
Detailed Explanation: Azure Key Vault references in App Service settings satisfy the requirement to keep secrets out of container images, source control, and directly stored application configuration. App Service resolves the referenced secret at runtime by using the app identity, so the application can consume the value as a normal setting without embedding credentials in the image. GitHub secrets are build/deployment secrets rather than a runtime App Service secret-delivery mechanism. Dockerfile ENV instructions would place secret material in the image configuration and violate the case requirements.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Use Key Vault references for App Service and Functions | Managed identities for Azure resources
Topic 2, Fabrikam Inc
Background - Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure. The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security. The solution must meet strict performance, scalability, and security requirements. Current environment - Application architecture - The Recommendation engine is a customer- facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA). Embeddings are stored in Azure Database for PostgreSQL by using pgvector. Semantic retrieval uses metadata filtering combined with vector similarity search. Azure Managed Redis is used as a caching layer. Front-end and API workloads are deployed to Azure Container Apps (ACA). Batch model retraining workloads run in Azure Kubernetes Service (AKS). Container and CI/CD - Container images are stored in Azure Container Registry (ACR). CI/CD uses ACR Tasks to build images on commit. ACA environments support revision management. AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring - Logs are collected in Azure Monitor. Teams inspect container logs and Kubernetes events when troubleshooting. Developers write KQL queries to analyze latency spikes. Business requirements - Customer experience: Maintain a seamless, low-latency recommendation experience for end-users, even during unpredictable seasonal traffic spikes. Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs. Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction. Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets. Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers. Technical requirements - Performance: Semantic search latency must remain under 200 milliseconds at peak load. Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput.
Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints. Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization. Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates. Identity: Use managed identities for all service-to-service and service-to-database authentication. Plain-text credentials in configuration files are strictly prohibited. Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy. Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero. CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits. Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
NEW QUESTION # 36
You are developing an Azure Function that calls external APIs by providing an access token for the API. The access token is stored in a secret named token in an Azure Key Vault named mykeyvault.
You need to ensure the Azure Function can access the token. Which value should you store in the Azure Functions app configuration?
Answer: B
NEW QUESTION # 37
An ACA app processes messages from an Azure Storage queue.
The app must scale automatically based on messages in a specific Azure Storage queue by using a Kubernetes Event-driven Autoscaler (KEDA) custom scale rule. You need to configure the required scale rule values.
Which two values should you configure? Each correct answer presents part of the solution. Choose two.
NOTE: Each correct selection is worth one point.
Answer: A,B
Explanation:
Detailed Explanation: A KEDA custom scale rule must identify what scaler to use and which resource within that scaler should be observed. For Azure Storage queues, the trigger type selects the Storage Queue scaler and the queue name identifies the specific queue whose message count drives scaling. Polling interval and maximum replicas are general scaling controls, but they do not define the required queue-specific trigger.
Therefore trigger type and queue name are the essential rule values tested here.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Set scaling rules in Azure Container Apps
NEW QUESTION # 38
You have an Azure web app that uses Azure Cosmos DB as a data store. You create a Cosmos DB container by running the following PowerShell script: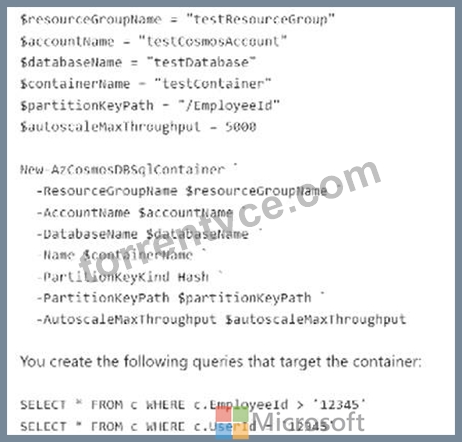
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.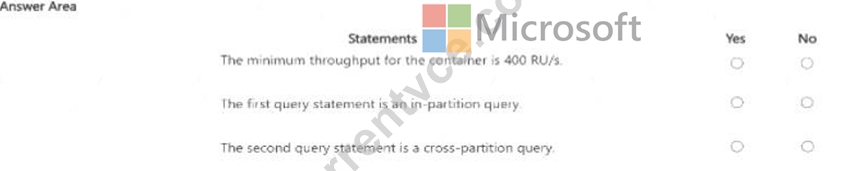
Answer:
Explanation: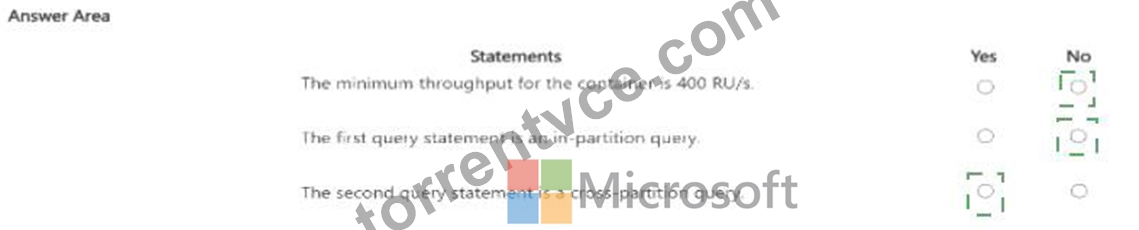
Explanation: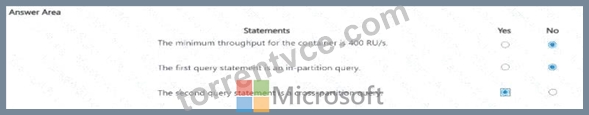
The question maps directly to the AI-200 objective "Develop AI solutions by using Azure Cosmos DB for NoSQL," which includes running queries and optimizing query performance and Request Unit (RU) consumption.
Statement 1: No - The minimum throughput is not 400 RU/s.
The PowerShell command provisions the container with:
-AutoscaleMaxThroughput 5000
Azure Cosmos DB autoscale operates between approximately 10% and 100% of the configured maximum throughput . Microsoft documentation specifically gives the example of an autoscale container provisioned with 5,000 RU/s scaling between 500 RU/s and 5,000 RU/s . Therefore, for this container, the minimum operating autoscale throughput is 500 RU/s , not 400 RU/s.
Therefore:
"The minimum throughput for the container is 400 RU/s." # No
Statement 2: No - The first query is not an in-partition query.
The container uses:
/EmployeeId
as its partition key.
The first query is:
SELECT * FROM c WHERE c.EmployeeId > ' 12345 '
Although the query references the partition key, it uses a range predicate ( > ) , not an equality predicate.
Microsoft explicitly states that a range filter on a partition key is not scoped to a single physical partition .
To qualify as an in-partition query, the filter must identify the applicable partition, typically through an equality predicate such as:
WHERE c.EmployeeId = ' 12345 '
Microsoft ' s documentation provides essentially the same example: a query using DeviceId > ... against a container partitioned by DeviceId is not an in-partition query .
Therefore:
"The first query statement is an in-partition query." # No
Statement 3: Yes - The second query is a cross-partition query.
The second query is:
SELECT * FROM c WHERE c.UserId = ' 12345 '
The container ' s partition key is /EmployeeId, not /UserId. Because the query contains no filter on the partition key , Azure Cosmos DB cannot route it to one logical partition. It must fan out the query across the applicable physical partitions and combine the results.
Microsoft describes this behavior directly: when a query does not contain a filter on the partition key, it must execute across the partitions.
Therefore:
"The second query statement is a cross-partition query." # Yes
NEW QUESTION # 39
......
It is apparent that a majority of people who are preparing for the AI-200 exam would unavoidably feel nervous as the exam approaching, If you are still worried about the coming exam, since you have clicked into this website, you can just take it easy now, I can assure you that our company will present the antidote for you--our AI-200 Learning Materials. Our company has spent more than 10 years on compiling study materials for the exam in this field, and now we are delighted to be here to share our study materials with all of the candidates for the exam in this field.
Guaranteed AI-200 Passing: https://www.torrentvce.com/AI-200-valid-vce-collection.html