P.S. Pass4TestがGoogle Driveで共有している無料かつ新しいWorkday-Pro-Integrationsダンプ:https://drive.google.com/open?id=1qzqQ1WAWAPR2a--ZxaRvLdEuuKKeXiwa
お客様のさまざまなニーズにお応えするために、Workday-Pro-Integrations試験資料の3つのバージョンを作成しました。もちろん、Workday-Pro-Integrations試験資料の3つのバージョンの内容はまったく同じです。あなたが好きなバージョンを選択できます。、Workday-Pro-Integrations試験資料の3つのバージョンの違いがわからない場合は、弊社とご連絡いただきます。 また、あなたは弊社のウエブサイトでWorkday-Pro-Integrations試験資料のデモを無料でダウンロードできます。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
>> Workday-Pro-Integrations対策学習 <<
テストに関する最も有用で効率的なWorkday-Pro-Integrationsトレーニング資料を提供するために最善を尽くし、クライアントが効率的に学習できるように複数の機能と直感的な方法を提供します。 Workday-Pro-Integrationsの有用なテストガイドを学習すれば、時間と労力はほとんどかかりません。合格率とヒット率はどちらも高いため、テストに合格するための障害はほとんどありません。 Webで紹介を読んだ後、Workday-Pro-Integrations学習実践ガイドをさらに理解できます。
質問 # 66
Refer to the following XML data source to answer the question below.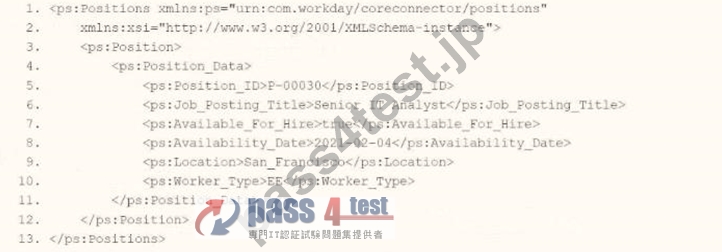
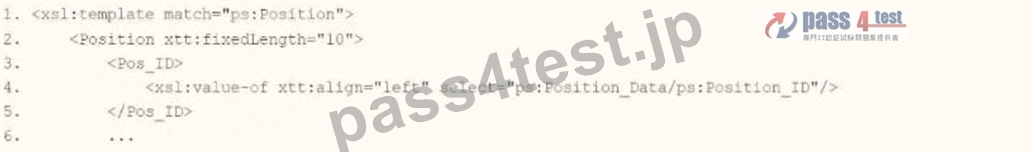
You need the integration file to format the ps:Position_ID field to 10 characters, truncate the value if it exceeds, and align everything to the left.
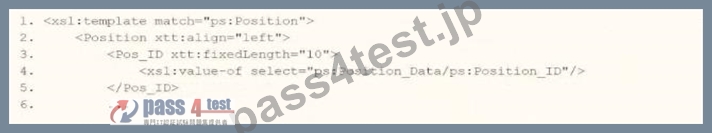
How will you start your template match on ps:Position to use Document Transformation (DT) to do the transformation using XTT?
正解:A
解説:
In Workday integrations, Document Transformation (DT) using XSLT with Workday Transformation Toolkit (XTT) attributes is used to transform XML data, such as the output from a Core Connector or EIB, into a specific format for third-party systems. In this scenario, you need to transform the ps:Position_ID field within the ps:Position element to a fixed length of 10 characters, truncate the value if it exceeds 10 characters, and align the output to the left. The template must match the ps:Position element and apply these formatting rules using XTT attributes.
Here's why option A is correct:
Template Matching: The <xsl:template match="ps:Position"> correctly targets the ps:Position element in the XML, as shown in the provided snippet, ensuring the transformation applies to the appropriate node.
XTT Attributes:
xtt:fixedLength="10" specifies that the Pos_ID field should be formatted to a fixed length of 10 characters. If the ps:Position_ID value exceeds 10 characters, it will be truncated (by default, XTT truncates without raising an error unless explicitly configured otherwise), meeting the requirement to truncate if the value exceeds.
xtt:align="left" ensures that the output is left-aligned within the 10-character field, aligning with the requirement to align everything to the left.
XPath Selection: The <xsl:value-of select="ps:Position_Data/ps:Position_ID"/> correctly extracts the ps:Position_ID value (e.g., "P-00030") from the ps:Position_Data child element, as shown in the XML structure.
Output Structure: The <Position><Pos_ID>...</Pos_ID></Position> structure ensures the transformed data is wrapped in meaningful tags for the target system, maintaining consistency with Workday integration practices.
Why not the other options?
B .
xml
WrapCopy
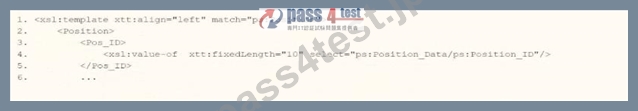
<xsl:template xtt:align="left" match="ps:Position">
<Position>
<Pos_ID xtt:fixedLength="10">
<xsl:value-of select="ps:Position_Data/ps:Position_ID"/>
</Pos_ID>
</Position>
</xsl:template>
This applies xtt:align="left" to the xsl:template element instead of the Pos_ID element. XTT attributes like fixedLength and align must be applied directly to the element being formatted (Pos_ID), not the template itself, making this incorrect.
C .
xml
WrapCopy
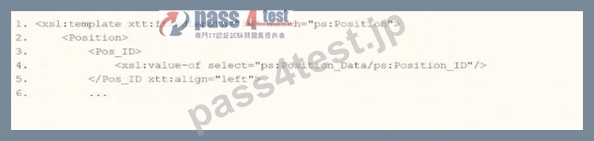
<xsl:template match="ps:Position">
<Position xtt:fixedLength="10">
<Pos_ID xtt:align="left">
<xsl:value-of select="ps:Position_Data/ps:Position_ID"/>
</Pos_ID>
</Position>
</xsl:template>
This applies xtt:fixedLength="10" to the Position element and xtt:align="left" to Pos_ID. However, XTT attributes like fixedLength and align should be applied to the specific field being formatted (Pos_ID), not the parent element (Position). This misplacement makes it incorrect.
D .
xml
WrapCopy
<xsl:template xtt:fixedLength="10" match="ps:Position">
<Position>
<Pos_ID xtt:align="left">
<xsl:value-of select="ps:Position_Data/ps:Position_ID"/>
</Pos_ID>
</Position>
</xsl:template>
This applies xtt:fixedLength="10" to the xsl:template element and xtt:align="left" to Pos_ID. Similar to option B, XTT attributes must be applied to the specific element (Pos_ID) being formatted, not the template itself, making this incorrect.
To implement this in XSLT for a Workday integration:
Use the template from option A to match ps:Position, apply xtt:fixedLength="10" and xtt:align="left" to the Pos_ID element, and extract the ps:Position_ID value using the correct XPath. This ensures the ps:Position_ID (e.g., "P-00030") is formatted to 10 characters, truncated if necessary, and left-aligned, meeting the integration file requirements.
:
Workday Pro Integrations Study Guide: Section on "Document Transformation (DT) and XTT" - Details the use of XTT attributes like fixedLength and align for formatting data in XSLT transformations, including truncation behavior.
Workday Core Connector and EIB Guide: Chapter on "XML Transformations" - Explains how to use XSLT templates with XTT attributes to transform position data, including fixed-length formatting and alignment.
Workday Integration System Fundamentals: Section on "XTT in Integrations" - Covers the application of XTT attributes to specific fields in XML for integration outputs, ensuring compliance with formatting requirements like length and alignment.
質問 # 67
Refer to the following XML to answer the question below.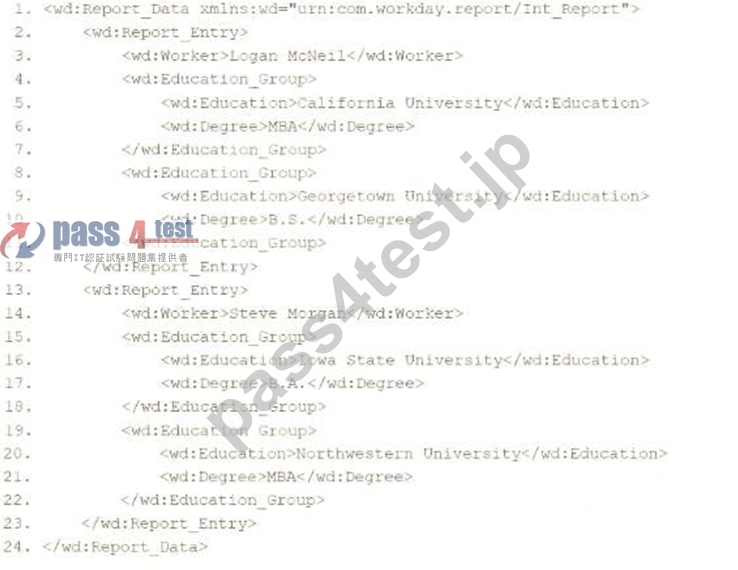
Within the template which matches on wd:Report_Entry, you would like to conditionally process the wd:
Education_Group elements by using an <xsl:apply-templates> element. What XPath syntax would be used for the select to iterate over only the wd:Education_Group elements where the Degree is an MBA?
正解:D
解説:
In Workday integrations, XSLT is used to transform XML data, such as the output from a web service- enabled report or EIB, into a desired format for third-party systems. In this scenario, you need to write XSLT to process wd:Education_Group elements within a template matching wd:Report_Entry, using an <xsl:apply- templates> element to iterate only over wd:Education_Group elements where the wd:Degree is "MBA." The correct XPath syntax for the select attribute is critical to ensure accurate filtering.
Here's why option A is correct:
* XPath Syntax Explanation: In XPath, square brackets [ ] are used to specify predicates or conditions to filter elements. The condition wd:Degree='MBA' checks if the wd:Degree child element has the value
"MBA." When applied to wd:Education_Group, the expression wd:Education_Group[wd:
Degree='MBA'] selects only those wd:Education_Group elements that contain a wd:Degree child element with the value "MBA."
* Context in XSLT: Within an <xsl:apply-templates> element in a template matching wd:Report_Entry, the select attribute uses XPath to specify which nodes to process. This syntax ensures that the template only applies to wd:Education_Group elements where the degree is "MBA," aligning with the requirement to conditionally process only those specific education groups.
* XML Structure Alignment: Based on the provided XML snippet, wd:Education_Group contains wd:
Education and wd:Degree child elements (e.g., <wd:Degree>MBA</wd:Degree>). The XPath wd:
Education_Group[wd:Degree='MBA'] correctly navigates to wd:Education_Group and filters based on the wd:Degree value, matching the structure and requirement.
Why not the other options?
* B. wd:Education_Group/wd:Degree='MBA': This is not a valid XPath expression for a predicate. It attempts to navigate to wd:Degree as a child but does not use square brackets [ ] to create a filtering condition. This would be interpreted as selecting wd:Degree elements under wd:Education_Group, but it wouldn't filter based on the value "MBA" correctly within an <xsl:apply-templates> context.
* C. wd:Report_Entry/wd:Education_Group/wd:Degree='MBA' 1:Degree='MBA': This is syntactically incorrect and unclear. It includes a malformed condition (1:Degree='MBA') and does not use proper XPath predicate syntax. It fails to filter wd:Education_Group elements based on wd:Degree='MBA' and is not valid for use in select.
* D. wd:Report_Entry/wd:Education_Group[wd:Degree='MBA' 1:Degree='MBA']: This is also syntactically incorrect due to the inclusion of 1:Degree='MBA' within the predicate. The 1: prefix is not valid XPath syntax and introduces an error. The correct predicate should only be wd:Degree='MBA' to filter the wd:Education_Group elements.
To implement this in XSLT:
* Within your template matching wd:Report_Entry, you would write an <xsl:apply-templates> element with the select attribute set to wd:Education_Group[wd:Degree='MBA']. This ensures that only wd:
Education_Group elements with a wd:Degree value of "MBA" are processed by the corresponding templates, effectively filtering out other degrees (e.g., B.S., B.A.) in the transformation.
This approach ensures the XSLT transformation aligns with Workday's XML structure and integration requirements for processing education data in a report output.
Workday Pro Integrations Study Guide: Section on "XSLT Transformations for Workday Integrations" - Details the use of XPath in XSLT for filtering XML elements, including predicates for conditional processing based on child element values.
Workday EIB and Web Services Guide: Chapter on "XML and XSLT for Report Data" - Explains the structure of Workday XML (e.g., wd:Education_Group, wd:Degree) and how to use XPath to navigate and filter data.
Workday Reporting and Analytics Guide: Section on "Web Service-Enabled Reports" - Covers integrating report outputs with XSLT for transformations, including examples of filtering elements based on specific values like degree types.
質問 # 68
You have been asked to create a report that will be used by the EIB to output only workers with Child Dependents.
How do you configure the custom report to meet these requirements?
正解:D
解説:
For an EIB that uses a custom report, the report must return only the correct worker population before the integration extracts the data. Because "Dependents" is a related multi-instance object, the correct approach is to use a subfilter on the Dependents business object to restrict the related dependent records to the Child relationship. Then the report-level filter ensures that the Dependents field is not empty after the subfilter is applied. This combination prevents workers without child dependents from being included. A filter alone on the Worker business object would not correctly evaluate the dependent relationship detail, and prompting the user for "Child" is unnecessary because the requirement is fixed. This is a reporting configuration issue used to control integration output.
質問 # 69
Refer to the following XML to answer the question below.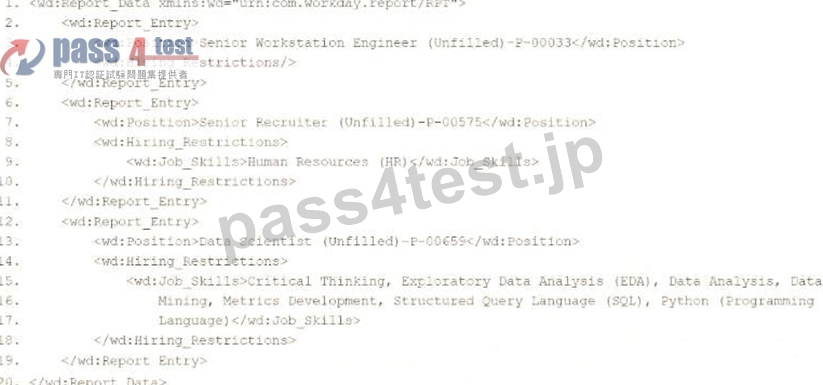
You are an integration developer and need to write X8LT to transform the output of an ElB which is using a web service enabled report to output position data along with hiring restrictions around skills. You currently have a template which matches on wd:Report Data/wd: Report .Entry for creating a record from each report entry.
Within the template which matches on wd:Report_Entry you would like to conditionally process the wd:
Job_Skills element by using a series of <xsl:if> elements so as to categorize the job skills data.
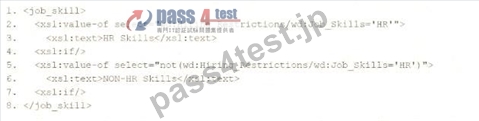
Assuming all jobs will have the wd:Job_Skills element, what XSLT syntax would be used to output the text HR Skills if the value of wd:Job_Skills contains the text HR and output NON-HR Skills if the value of wd:
Job_Skills does not contain the text HR?
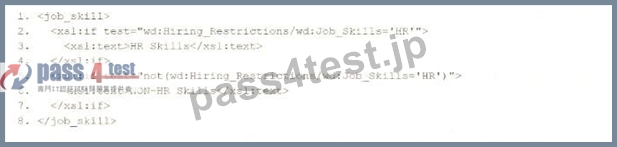
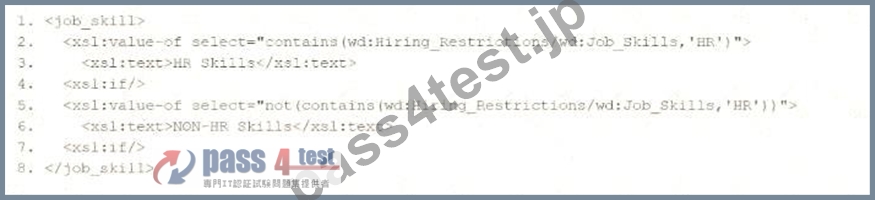
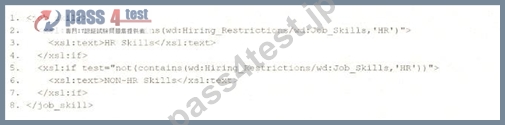
正解:D
解説:
The task is to write XSLT within a template matching wd:Report_Data/wd:Report_Entry to categorize wd:
Job_Skills data, outputting "HR Skills" if the value contains "HR" and "NON-HR Skills" if it does not, using a series of <xsl:if> elements. The correct syntax must use the contains() function to check for the substring
"HR" within wd:Job_Skills, as the question implies partial matching (e.g., "HR Specialist" or "Senior HR"), not exact equality.
Let's analyze each option:
* Option A:
xml
<job_skill>
<xsl:value-of select="wd:Hiring_Restrictions/wd:Job_Skills='HR'">
<xsl:text>HR Skills</xsl:text>
<xsl:if/>
<xsl:value-of select="not(wd:Hiring_Restrictions/wd:Job_Skills='HR')">
<xsl:text>NON-HR Skills</xsl:text>
<xsl:if/>
</job_skill>
* Issues:
* <xsl:value-of> is misused here. It outputs the result of the expression (e.g., "true" or "false" for a comparison), not the conditional text. The <xsl:text> inside won't execute as intended.
* The = operator checks for exact equality (e.g., wd:Job_Skills must be exactly "HR"), not substring presence, which contradicts the requirement to check if "HR" is contained within the value.
* <xsl:if/> is malformed (self-closing without a test attribute) and misplaced.
* Verdict: Incorrect syntax and logic.
* Option B:
xml
<job_skill>
<xsl:value-of select="contains(wd:Hiring_Restrictions/wd:Job_Skills, 'HR')">
<xsl:text>HR Skills</xsl:text>
<xsl:if/>
<xsl:value-of select="not(contains(wd:Hiring_Restrictions/wd:Job_Skills, 'HR'))">
<xsl:text>NON-HR Skills</xsl:text>
<xsl:if/>
</job_skill>
* Issues:
* Similar to A, <xsl:value-of> outputs the boolean result of contains() ("true" or "false"), not the conditional text "HR Skills" or "NON-HR Skills."
* The <xsl:text> elements are inside invalid <xsl:if/> tags (self-closing, no test), rendering them ineffective.
* While contains() is correct for substring checking, the structure fails to meet the <xsl:if> requirement.
* Verdict: Incorrect structure despite using contains().
* Option C:
xml
<job_skill>
<xsl:if test="wd:Hiring_Restrictions/wd:Job_Skills='HR'">
<xsl:text>HR Skills</xsl:text>
</xsl:if>
<xsl:if test="not(wd:Hiring_Restrictions/wd:Job_Skills='HR')">
<xsl:text>NON-HR Skills</xsl:text>
</xsl:if>
</job_skill>
* Analysis:
* Uses <xsl:if> correctly with test attributes, satisfying the "series of <xsl:if> elements" requirement.
* However, wd:Job_Skills='HR' tests for exact equality, not whether "HR" is contained within the value. For example, "HR Specialist" would fail this test, outputting "NON-HR Skills" incorrectly.
* Verdict: Semantically incorrect due to exact matching instead of substring checking.
* Option D:
xml
<job_skill>
<xsl:if test="contains(wd:Hiring_Restrictions/wd:Job_Skills, 'HR')">
<xsl:text>HR Skills</xsl:text>
</xsl:if>
<xsl:if test="not(contains(wd:Hiring_Restrictions/wd:Job_Skills, 'HR'))">
<xsl:text>NON-HR Skills</xsl:text>
</xsl:if>
</job_skill>
* Analysis:
* Correctly uses <xsl:if> with test attributes, aligning with the question's requirement.
* The contains() function properly checks if "HR" is a substring within wd:Job_Skills (e.g.,
"HR Manager" or "Senior HR" returns true).
* not(contains()) ensures the opposite condition, covering all cases (mutually exclusive).
* <xsl:text> outputs the exact strings "HR Skills" or "NON-HR Skills" as required.
* Note: The closing tag </xs1:if> is a typo in the option (should be </xsl:if>), but in context, it's an obvious formatting error, not a substantive issue.
* Verdict: Correct logic and syntax, making D the best answer.
Correct Implementation in Context:
xml
<xsl:template match="wd:Report_Data/wd:Report_Entry">
<job_skill>
<xsl:if test="contains(wd:Hiring_Restrictions/wd:Job_Skills, 'HR')">
<xsl:text>HR Skills</xsl:text>
</xsl:if>
<xsl:if test="not(contains(wd:Hiring_Restrictions/wd:Job_Skills, 'HR'))">
<xsl:text>NON-HR Skills</xsl:text>
</xsl:if>
</job_skill>
</xsl:template>
* Example Input: <wd:Job_Skills>Senior HR Analyst</wd:Job_Skills> # Output: <job_skill>HR Skills<
/job_skill>
* Example Input: <wd:Job_Skills>IT Specialist</wd:Job_Skills> # Output: <job_skill>NON-HR Skills<
/job_skill>
Workday Pro Integrations Study Guide: "Configure Integration System - TRANSFORMATION" section, detailing <xsl:if> and contains() for conditional XSLT logic in Workday.
Workday Documentation: "XSLT Transformations in Workday" under EIB, confirming wd: namespace usage and string functions.
W3C XSLT 1.0 Specification: Section 9.1, "Conditional Processing with <xsl:if>," and Section 11.2, "String Functions" (contains()).
Workday Community: Examples of substring-based conditionals in XSLT for report transformations.
質問 # 70
You have been asked to create an integration using the Core Connector: Worker with DIS template. The vendor has requested that you only include employees who are based in the San Francisco area that are on leave.
How do you configure your integration so that only workers who meet the requirements are included in the output file?
正解:D
解説:
When using Core Connector: Worker with DIS, to restrict the population to employees who:
Are on leave, and
Are located in San Francisco
You must configure Population Eligibility, which is the only place to filter the worker population included in the connector output.
From Workday Pro documentation:
"The Population Eligibility section defines which workers are eligible for extraction in the integration based on location, status, organization, and other conditions. Boolean calculated fields can be used here to define complex eligibility criteria." In this case:
Create a Boolean calculated field that returns true for "On Leave AND Location = San Francisco" Use that field in Population Eligibility Why the others are incorrect:
A, D. Field Overrides and Field Attributes only modify what data is extracted-not who is included.
C . Integration Attributes don't control population filtering.
質問 # 71
......
どうやって安くて正確性の高いWorkdayのWorkday-Pro-Integrations問題集を買いますか。Pass4Testは最も安い値段で正確性の高いWorkdayのWorkday-Pro-Integrations問題集を提供します。Pass4Testの学習教材はベストセラーになって、他のサイトをずっと先んじています。私たちのWorkdayのWorkday-Pro-Integrations問題集を使ったら、WorkdayのWorkday-Pro-Integrations認定試験に合格できる。Pass4Testを選んだら、成功を選ぶのに等しいです。
Workday-Pro-Integrations無料試験: https://www.pass4test.jp/Workday-Pro-Integrations.html
2026年Pass4Testの最新Workday-Pro-Integrations PDFダンプおよびWorkday-Pro-Integrations試験エンジンの無料共有:https://drive.google.com/open?id=1qzqQ1WAWAPR2a--ZxaRvLdEuuKKeXiwa