What's more, part of that ActualPDF AI-103 dumps now are free: https://drive.google.com/open?id=1mf8ZzrjP-8ulCNFmMIPQgStDfsrK-o_S
The AI-103 test materials are mainly through three learning modes, Pdf, Online and software respectively.The AI-103 test materials have a biggest advantage that is different from some online learning platform which has using terminal number limitation, the AI-103 quiz torrent can meet the client to log in to learn more, at the same time, the user can be conducted on multiple computers online learning, greatly reducing the time, and people can use the machine online of AI-103 Test Prep more conveniently at the same time.
| Section | Weight | Objectives |
|---|---|---|
| Implement information extraction and knowledge mining | 10–15% | - Extract structured data from documents
|
| Implement generative AI and agentic solutions | 30–35% | - Design and implement intelligent agents
|
| Implement computer vision solutions | 10–15% | - Build multimodal solutions
|
| Plan and manage Azure AI solutions | 25–30% | - Manage AI solution development lifecycle
|
| Implement text and speech analysis solutions | 10–15% | - Implement speech capabilities
|
>> Exam AI-103 Passing Score <<
Our AI-103 training prep can be applied to different groups of people. Whether you are trying this exam for the first time or have experience, our AI-103 learning materials are a good choice for you. Whether you are a student or an employee, our AI-103 exam questions can meet your needs. This is due to the fact that our AI-103 Learning Materials are very user-friendly and express complex information in easy-to-understand language. We assure you that once you choose our AI-103 practice materials, your learning process is very easy.
NEW QUESTION # 22
You have a Microsoft Foundry project that contains a Retrieval Augmented Generation (RAG) chat solution used by customer support agents.
You are adding an automated pre-production evaluation step to a CI/CD pipeline named Pipeline1. The evaluation will run against a labeled test dataset that contains support questions and the expected grounding context.
You need to ensure that Pipeline1 fails if unsupported content or a retrieval mismatch exceeds a defined threshold:
- responses include claims not supported by the retrieved source
content
- retrieved source content does not align with the labeled expected
context
Which two built-in evaluators should you use in Pipeline1? Each correct answer presents pat of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,C
Explanation:
The Groundedness Evaluator evaluator validates that the model's responses include only claims supported by the retrieved source content It flags ungrounded content or hallucinations. If the average score drops below your defined threshold, it triggers a pipeline failure.
The correct additional built-in evaluator appropriate for the pipeline is Retrieval (specifically, the RetrievalEvaluator or DocumentRetrievalEvaluator).
A standard RAG evaluation pipeline assesses both the generator (the LLM producing the answer) and the retriever (the search system pulling documentation). The CI/CD requirements specify two distinct failure thresholds:
Responses including claims not supported by the retrieved source content: This checks for model hallucinations and is handled by the Groundedness Evaluator.
Retrieved source content not aligning with the labeled expected context: This explicitly measures the performance of your search step against your ground-truth data. The built-in Retrieval evaluator maps to this requirement. It computes metrics like context recall to ensure your system successfully retrieves the exact reference documents specified in your labeled test dataset Reference:
https://learn.microsoft.com/en-us/microsoft-365/copilot/extensibility/evaluations-cli-evaluators
NEW QUESTION # 23
You have a Microsoft Foundry project that processes procurement documents submitted by suppliers.
You need to implement two pipelines by using Azure Content Understanding in Foundry Tools. The solution must meet the following requirements:
* Include a pipeline named Pipeline1 that supports cost-effective, high-volume processing of standalone PDF invoices.
* Include a pipeline named Pipeline2 that supports cross-document validation by using multi-step reasoning and reference data.
How should you configure each pipeline? To answer, drag the appropriate configurations to the correct pipelines. Each configuration may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.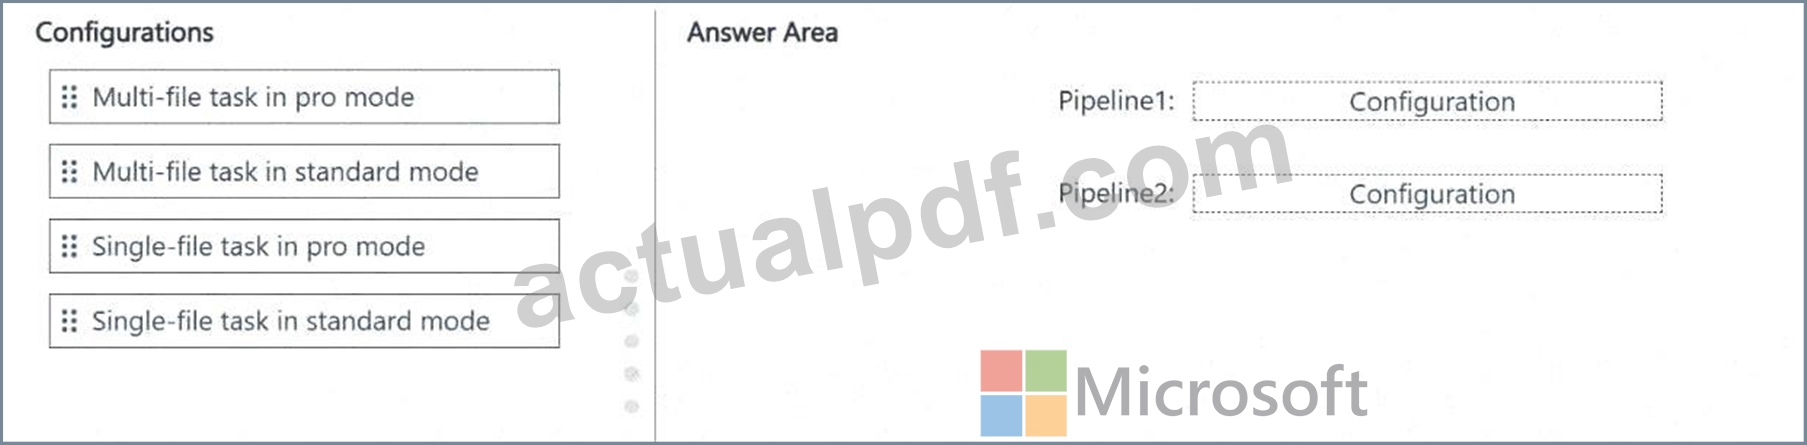
Answer:
Explanation: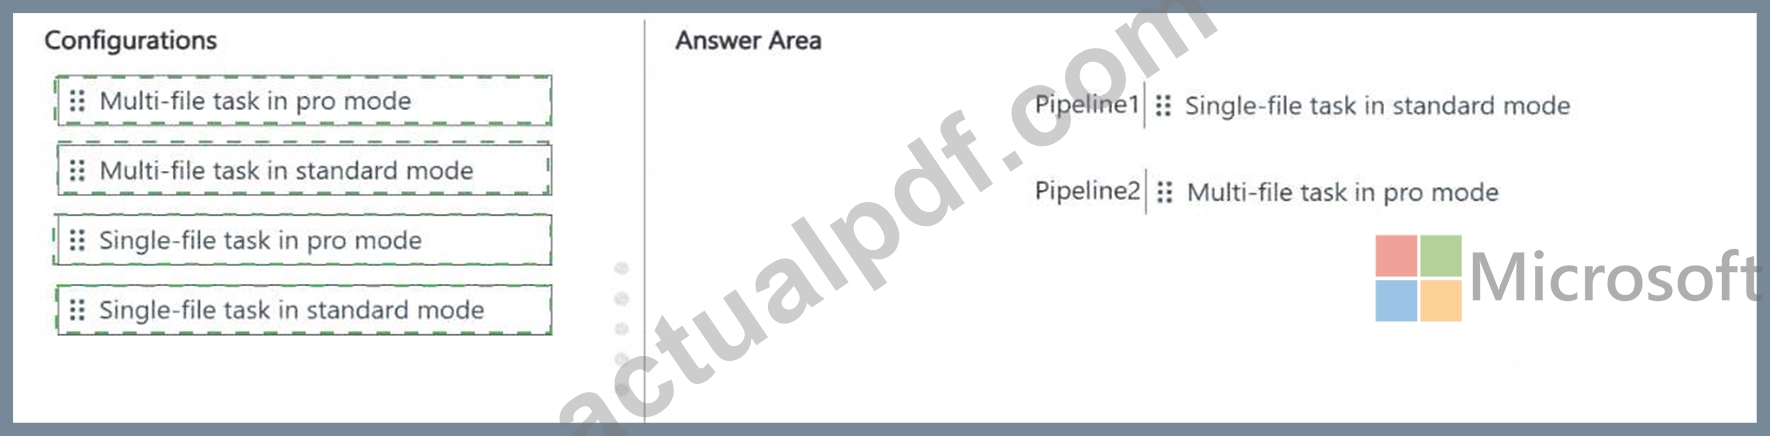
Explanation:
Pipeline1: Single-file task in standard mode
Pipeline2: Multi-file task in pro mode
Pipeline1 should use a single-file task in standard mode because the workload is high-volume processing of standalone PDF invoices. Azure Content Understanding standard mode is intended for individual files that require straightforward structured extraction, and Microsoft describes it as minimizing cost and latency for broad, data-centric processing scenarios. This makes it the best fit for cost-effective invoice extraction where each PDF can be processed independently.
Pipeline2 should use a multi-file task in pro mode because the requirement includes cross-document validation, multi-step reasoning, and reference data. Microsoft guidance states that pro mode is designed for advanced scenarios requiring multi-step reasoning and cross-file analysis, including processing multiple input files in a single request, validating or enriching data across documents, and using reference data to guide extraction and validation.
Single-file pro mode would add unnecessary capability for Pipeline1 and would not optimize for cost- effective high-volume standalone processing. Multi-file standard mode does not meet the pro-mode requirement for reference-data-based reasoning. Reference topics: Azure Content Understanding standard mode, pro mode, single-file tasks, multi-file tasks, field extraction, and procurement document validation.
NEW QUESTION # 24
You are creating an enrichment pipeline that will use Azure Al Search. The knowledge store contains unstructured JSON data and the text from scanned PDF documents.
Which projection type should you use for each data type? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.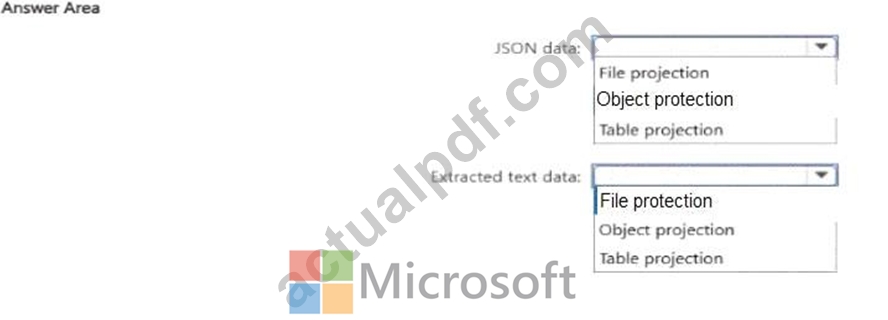
Answer:
Explanation: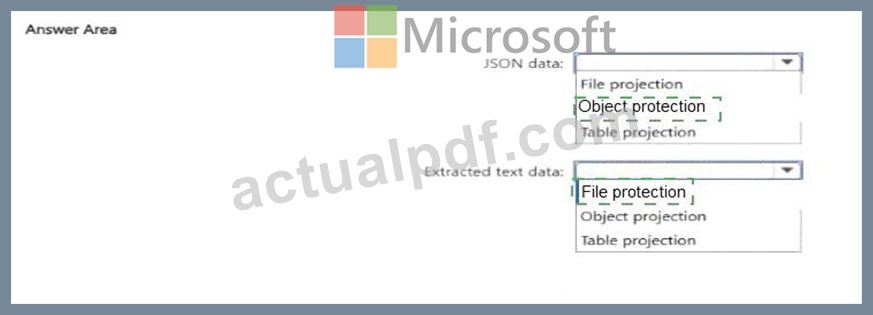
Explanation: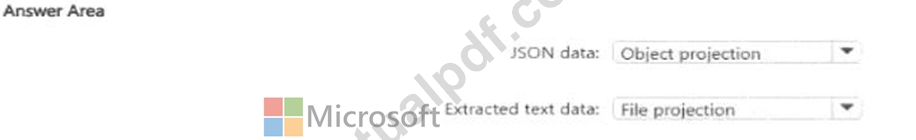
Use an object projection for the unstructured JSON data. Object projections store a JSON representation of an enrichment tree node in an Azure Blob Storage container. They preserve hierarchical fields and complex structures, making them appropriate when enriched document content must remain available as a complete JSON object rather than being decomposed into relational rows. Microsoft describes object projections as JSON representations that can be sourced from nodes in the enrichment tree.
For the scanned PDF content, use a file projection . During document cracking and OCR processing, scanned pages are represented through the /document/normalized_images/* collection. File projections write these binary normalized images to Blob Storage, preserving the page assets from which the text is extracted.
Microsoft specifies that file projections operate only on normalized images and contain binary data rather than JSON.
A table projection is intended for row-and-column structures used by analytical tools such as Power BI. It is not the appropriate choice for preserving hierarchical JSON or scanned-document image files.
Study Guide alignment: configure Azure AI Search enrichment pipelines, skillsets, knowledge stores, and table, object, and file projections .
NEW QUESTION # 25
You need to recommend a plan to create a customer support agent by using the Microsoft Foundry Agent Service. The agent must meet the following requirements:
* Retain user preferences across multiple conversations.
* Enable users to provide contextual grounding by directly uploading documents during a chat.
Which Foundry capability should you recommend for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.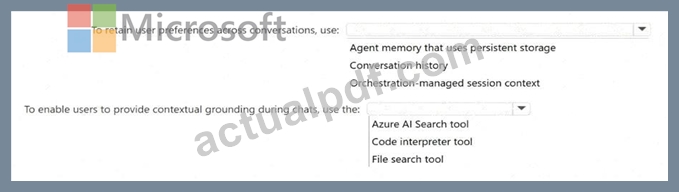
Answer:
Explanation: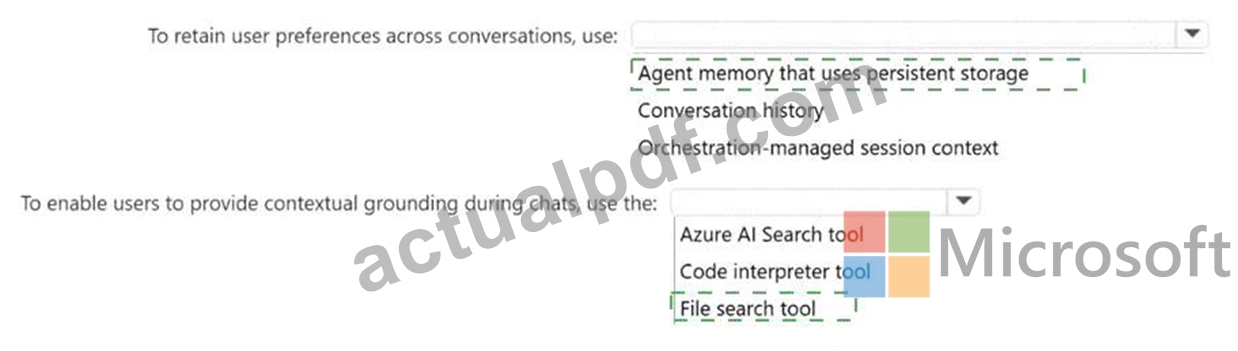
Explanation:
To retain user preferences across conversations, use: Agent memory that uses persistent storage To enable users to provide contextual grounding during chats, use the: file search tool The correct capability for retaining user preferences is agent memory that uses persistent storage .
Microsoft Foundry Agent Service memory is a managed long-term memory capability that enables continuity across sessions, devices, and workflows. It is specifically intended to let agents retain user preferences, maintain relevant historical context, and personalize responses across separate conversations. Memory stores provide the persistent storage layer, and scope can be used to segment memories for secure user-specific experiences.
The correct capability for contextual grounding from user-uploaded documents is the file search tool .
Microsoft describes file search as the tool that enables Foundry agents to search through documents and retrieve relevant information from outside the base model, including proprietary product information and user- provided documents. The file search workflow supports uploading files, creating a vector store, enabling the tool on the agent, and querying those documents through the agent.
Conversation history alone supports continuity within a conversation, but it is not durable preference memory across multiple conversations. An Azure AI Search tool is better for preconfigured enterprise indexes, while file search is the direct document-upload grounding capability. Reference topics: Foundry Agent Service memory, memory stores, File Search tool, vector stores, and grounded agent responses.
NEW QUESTION # 26
You have a Microsoft Foundry project that contains an agent.
The agent uses tools to retrieve internal content and call external APIs. The agent is configured to let the model decide when to call the tools.
You need to publish the agent for a compliance workflow. The solution must meet the following requirements:
* Each workflow run must include a retrieval step before generating a response.
* Tool calls must authenticate by using the published agent's own identity.
* Tool access must use an identity isolated from other project resources.
* Tool access must support audit tracing.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.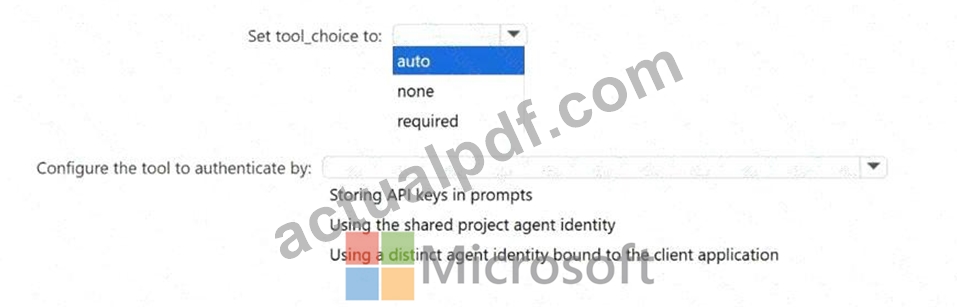
Answer:
Explanation: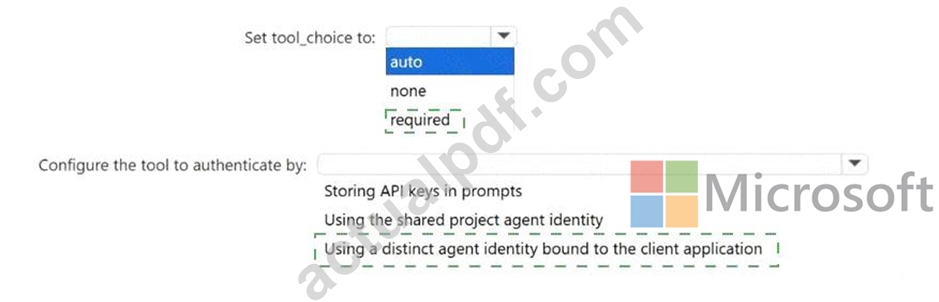
Explanation:
Set tool_choice to: required
Configure the tool to authenticate by: Using a distinct agent identity bound to the client application Set tool_choice to required because the compliance workflow must deterministically include a tool-based retrieval step before the agent generates a response. Microsoft Foundry Agent Service guidance states that tool_choice provides the most deterministic control over tool use: auto lets the model decide, none prevents tool calls, and required forces the model to call one or more tools. This directly corrects the current nondeterministic behavior where the model decides whether to call tools.
For authentication, use a distinct agent identity bound to the client application . Microsoft Foundry creates a shared identity for unpublished or in-development agents, but publishing an agent automatically creates a dedicated agent identity blueprint and agent identity associated with the agent application resource. Published agents authenticate tool calls by using that unique agent identity, and RBAC permissions must be assigned to the new identity. This provides isolation from the broader shared project identity and supports independent audit trails for compliance workflows.
Storing API keys in prompts violates security guidance and prevents robust audit attribution. The shared project agent identity is easier for development, but it has a broader blast radius and does not meet the isolation requirement. Reference topics: Foundry Agent Service tool choice, tool authentication, published agent identities, RBAC, and auditability.
NEW QUESTION # 27
......
Windows computers support the desktop practice test software. ActualPDF has a complete support team to fix issues of Microsoft AI-103 PDF QUESTIONS software users. ActualPDF practice tests (desktop and web-based) produce score report at the end of each attempt. So, that users get awareness of their Developing AI Apps and Agents on Azure (AI-103) preparation status and remove their mistakes.
Reliable AI-103 Exam Pdf: https://www.actualpdf.com/AI-103_exam-dumps.html
BONUS!!! Download part of ActualPDF AI-103 dumps for free: https://drive.google.com/open?id=1mf8ZzrjP-8ulCNFmMIPQgStDfsrK-o_S