当社Microsoftには多くの専門家や教授がいます。 当社のすべてのDP-750研究トレントは、It-Passportsさまざまな分野のこれらの優秀な専門家および教授によって設計されています。 DP-750テストトレントが他の学習教材よりも高い品質を持っていることを確認できます。 私たちのデザインの目的は、学習を改善し、最短時間でDP-750認定を取得できるようにすることです。 認定資格を取得したい場合は、Implementing Data Engineering Solutions Using Azure Databricksガイド急流が最適です。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Topic 2: Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Topic 3: Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Topic 4: Prepare and process data | 30–35% | - Optimize and manage data storage
|
Microsoft DP-750試験のAPPテストエンジンは、ほとんどの認定候補者がファッションであり、この新しい学習方法に簡単に適応できるため、少なくとも60%の受験者に人気があります。 DP-750試験のAPPテストエンジンは、いつでもどこでも使用できると考える人がいます。 また、候補者の一部は、このバージョンでは実際のテストで実際のシーンをシミュレートできると考えています。 ブラウザを開くことができれば、学ぶことができます。 また、オフラインで学習したい場合は、DP-750試験のAPPテストエンジンをダウンロードしてインストールした後、キャッシュをクリアしないでください。
質問 # 73
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Tabid.
Table! is written by batch jobs every hour and is queried frequently by filtering two columns named Customerld and EventDate.
You expect Table1 to grow significantly over time.
The rows in Table1 are frequently updated and deleted to support compliance requests.
You need to keep query performance consistent as Table1 grows. The solution must minimize update and deletion effort.
What should you include in the solution? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.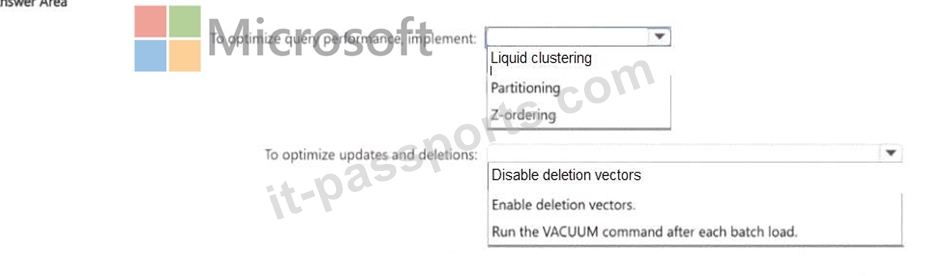
正解:
解説: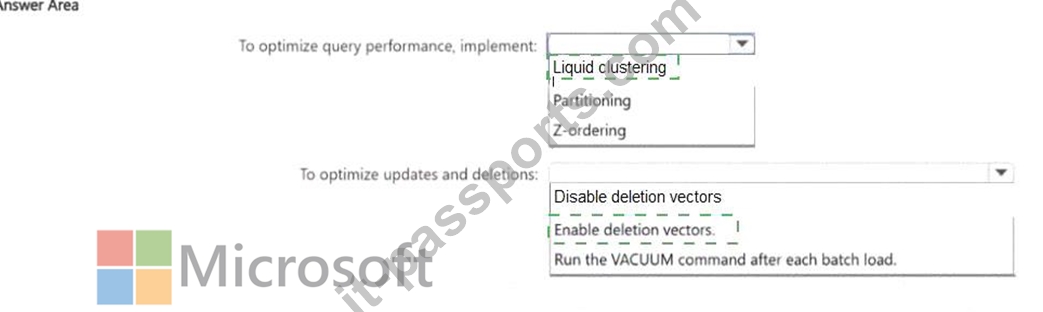
Explanation:
Two features work together to keep performance consistent and update costs low:
OPTIMIZE with ZORDER BY (CustomerId, EventDate). Z-Ordering co-locates rows with the same CustomerId and EventDate values in the same Parquet files. When a query filters on those columns, the Delta engine uses file statistics to skip files that can't possibly contain matching rows (data skipping). As the table grows, skipping scales proportionally - query time stays consistent.
Deletion Vectors (delta.enableDeletionVectors = true). When a row is updated or deleted, instead of rewriting the entire Parquet file, Delta marks the affected row in a small companion deletion vector file. This dramatically reduces write amplification for the frequent compliance-driven updates and deletions the question describes. Actual file rewrites are deferred to the next OPTIMIZE run.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/data-skipping
質問 # 74
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline in Azure Databricks. The pipeline ingests transaction data into a table named Table1.
You need to ensure that in the event of an invalid record, the pipeline continues to run. The solution must meet the following requirements:
- Invalid records must NOT be written to Table1.
- Invalid records must be preserved for review.
- Minimize development effort.
What should you do?
正解:C
解説:
To meet your pipeline requirements, use the expect_or_drop expectation constraint to ensure invalid records are not written to the table while allowing the pipeline to continue running. To preserve and review invalid records without custom development, capture the failed rows by isolating the inverse rule (expect_or_drop) in a quarantine flow.
Summary of the Behavior Matrix
Pipeline continues to run: Achieved via drop or warn behaviors (the fail policy is excluded because it halts execution).
Invalid records not written to the clean table: Achieved via the drop policy, which discards records from the downstream dataset.
Records preserved for review: Achieved by querying the automated, built-in Lakeflow Event Log Delta table, which automatically captures the details of any rejected or flagged rows without requiring custom code.
Minimized development: Eliminates the need to construct secondary "quarantine" storage tables manually.
Reference:
https://docs.databricks.com/aws/en/ldp/best-practices
質問 # 75
Which operation guarantees ACID compliance in Delta Lake?
正解:C
解説:
Delta Lake ensures ACID compliance through its transaction log (Delta log). It tracks all changes, enabling consistency, isolation, and rollback capabilities. File append operations alone are not transactional. RDD transformations are low-level and not ACID-aware.
質問 # 76
You need to configure resiliency for a job in Lakeflow Jobs named Job1 to meet the pipeline deployment and operation requirements.
What should you do?
正解:A
解説:
Task-level retries allow the ingestion task to recover automatically from transient failures without rerunning unrelated tasks or restarting the complete workflow. Downstream tasks remain governed by their dependencies and start only after ingestion succeeds. This provides focused failure recovery and reduces unnecessary compute consumption. Disabling retries and relying on manual execution directly contradicts the requirement for resilient, automated pipeline operation. Setting the retry count to zero also prevents automatic retry behavior. Restarting the workflow from the first task whenever any task fails would repeat completed processing, increase costs, and potentially reingest data unnecessarily. Lakeflow Jobs supports individual retry policies for tasks, including the number of retries and delay between attempts, making option D the most controlled and operationally efficient configuration. Microsoft Learn
質問 # 77
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to implement a data lifecycle and expiration solution that meets the following requirements:
- Transaction logs and deleted data files that are older than 90 days
must be removed from Delta tables to reclaim storage.
- All the tables must remain available for querying during the cleanup
process.
- Administrative effort must be minimized.
What should you do for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.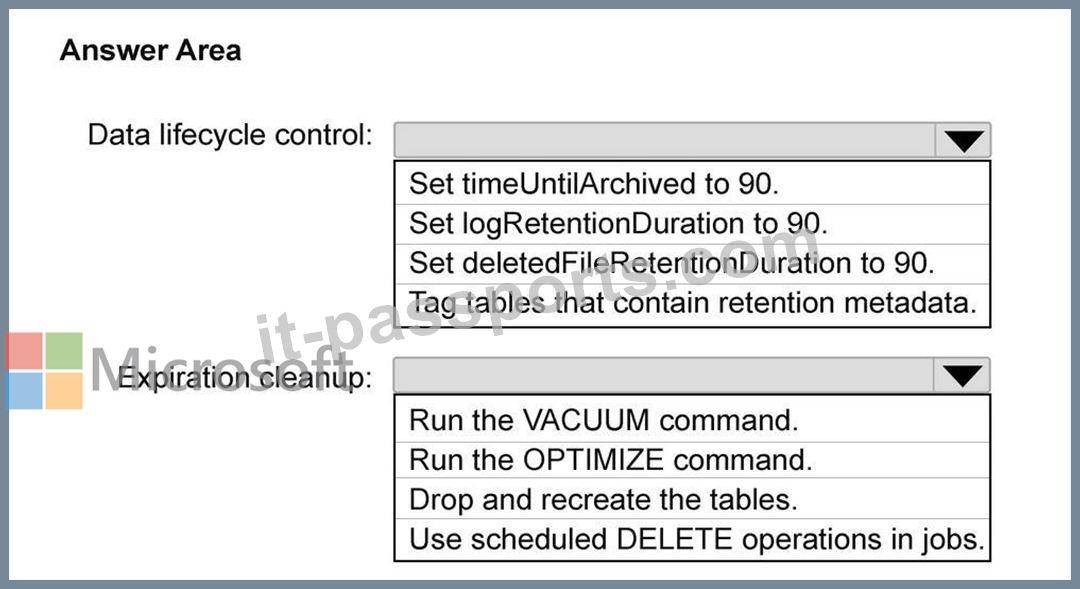
正解:
解説: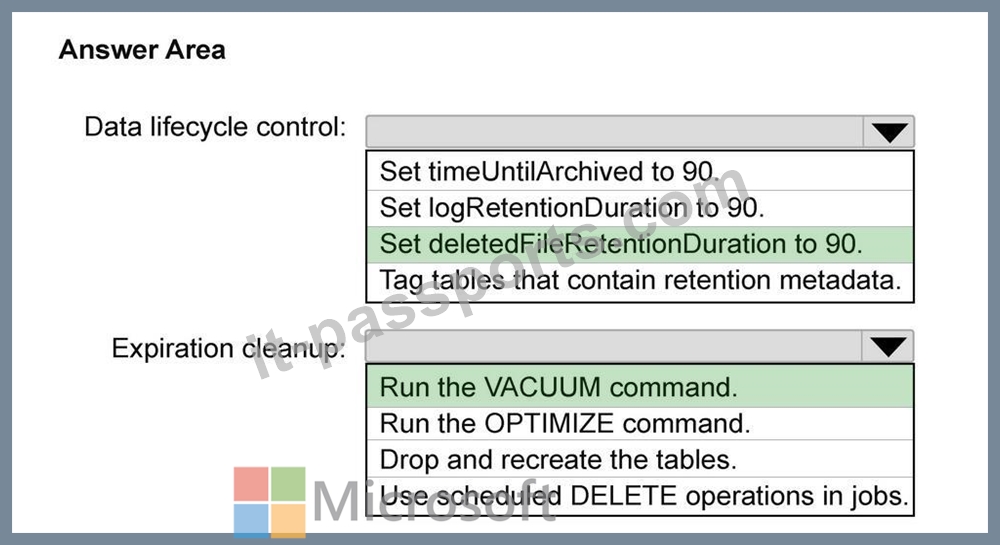
質問 # 78
......
世界経済の急速な発展とさまざまな国との頻繁な接触により、すべての人々にとって良い仕事を探すことはますます難しくなっています。良い仕事を探すには、DP-750認定を取得することが非常に必要です。労働市場での競争上の優位性を高め、他の求職者と差別化する必要があります。また、DP-750試験の質問は、最小限の時間と労力でDP-750試験に合格できるように特別に設計されています。 DP-750実践ガイドを購入してください。
DP-750日本語版対応参考書: https://www.it-passports.com/DP-750.html