BONUS!!! Download part of VCEPrep Databricks-Certified-Professional-Data-Engineer dumps for free: https://drive.google.com/open?id=1IHhasz11D1gjPqhUqPuS8AGkhmF6kP2t
VCEPrep Databricks-Certified-Professional-Data-Engineer practice material can be accessed instantly after purchase, so you won't have to face any excessive issues for preparation of your desired Databricks Databricks-Certified-Professional-Data-Engineer certification exam. The Databricks Databricks-Certified-Professional-Data-Engineer Exam Dumps of VCEPrep has been made after seeking advice from many professionals. Our objective is to provide you with the best learning material to clear the Databricks-Certified-Professional-Data-Engineer exam.
Databricks Certified Professional Data Engineer (Databricks-Certified-Professional-Data-Engineer) exam is designed for professionals who want to showcase their skills in building data pipelines and managing data workflows on Databricks. Databricks is a cloud-based data platform that provides powerful tools for data engineering, data science, and machine learning. Databricks Certified Professional Data Engineer Exam certification exam is intended to validate the candidates' ability to design, build, and maintain data processing systems using Databricks.
>> Databricks-Certified-Professional-Data-Engineer Certification Cost <<
The best way of passing Databricks actual test is choosing accurate exam braindumps. VCEPrep has latest test questions and accurate exam answers to ensure you clear Databricks-Certified-Professional-Data-Engineer Real Exam. You just need spend your spare time to practice Databricks top questions and review the key points of study guide, it will be easy to clear exam.
The Databricks Certified Professional Data Engineer Exam certification verifies that the candidate has significant experience in implementing big data solutions that operate on the Databricks Delta Architecture. To earn the certification, a candidate must pass a 90-minute exam consisting of up to 50 multiple-choice and multiple-select questions. The Databricks-Certified-Professional-Data-Engineer certification is valid for two years from the date of passing the exam.
Databricks is a leading cloud-based data platform that enables organizations to accelerate innovation and achieve their data-driven goals. To showcase their expertise in using the Databricks platform, data professionals can earn the Databricks-Certified-Professional-Data-Engineer (Databricks Certified Professional Data Engineer) certification. Databricks Certified Professional Data Engineer Exam certification is designed to validate the skills and knowledge required to design, build, and maintain data solutions on the Databricks platform.
NEW QUESTION # 93
Create a sales database using the DBFS location 'dbfs:/mnt/delta/databases/sales.db/'
Answer: A
Explanation:
Explanation
The answer is
CREATE DATABASE sales LOCATION 'dbfs:/mnt/delta/databases/sales.db/'
Note: with the introduction of the Unity catalog and three-layer namespace usage of SCHEMA and DATABASE is interchangeable
NEW QUESTION # 94
You had worked with the Data analysts team to set up a SQL Endpoint(SQL warehouse) point so they can easily query and analyze data in the gold layer, but once they started consuming the SQL Endpoint(SQL warehouse) you noticed that during the peak hours as the number of users increase you are seeing queries taking longer to finish, which of the following steps can be taken to resolve the issue?
*Please note Databricks recently renamed SQL endpoint to SQL warehouse.
Answer: E
Explanation:
Explanation
the answer is,
They can increase the maximum bound of the SQL endpoint's scaling range, when you increase the maximum bound you can add more clusters to the warehouse which can then run additional queries that are waiting in the queue to run, focus on the below explanation that talks about Scale-out.
The question is looking to test your ability to know how to scale a SQL Endpoint(SQL Warehouse) and you have to look for cue words or need to understand if the queries are running sequentially or concurrently. if the queries are running sequentially then scale up(Size of the cluster from 2X-Small to 4X-Large) if the queries are running concurrently or with more users then scale out(add more clusters).
SQL Endpoint(SQL Warehouse) Overview: (Please read all of the below points and the below diagram to understand )
1.A SQL Warehouse should have at least one cluster
2.A cluster comprises one driver node and one or many worker nodes
3.No of worker nodes in a cluster is determined by the size of the cluster (2X -Small ->1 worker, X-Small ->2 workers.... up to 4X-Large -> 128 workers) this is called Scale up
4.A single cluster irrespective of cluster size(2X-Smal.. to ...4XLarge) can only run 10 queries at any given time if a user submits 20 queries all at once to a warehouse with 3X-Large cluster size and cluster scaling (min
1, max1) while 10 queries will start running the remaining 10 queries wait in a queue for these 10 to finish.
5.Increasing the Warehouse cluster size can improve the performance of a query, example if a query runs for 1 minute in a 2X-Small warehouse size, it may run in 30 Seconds if we change the warehouse size to X-Small.
this is due to 2X-Small has 1 worker node and X-Small has 2 worker nodes so the query has more tasks and runs faster (note: this is an ideal case example, the scalability of a query performance depends on many factors, it can not always be linear)
6.A warehouse can have more than one cluster this is called Scale out. If a warehouse is con-figured with X-Small cluster size with cluster scaling(Min1, Max 2) Databricks spins up an additional cluster if it detects queries are waiting in the queue, If a warehouse is configured to run 2 clusters(Min1, Max 2), and let's say a user submits 20 queries, 10 queriers will start running and holds the remaining in the queue and databricks will automatically start the second cluster and starts redirecting the 10 queries waiting in the queue to the second cluster.
7.A single query will not span more than one cluster, once a query is submitted to a cluster it will remain in that cluster until the query execution finishes irrespective of how many clusters are available to scale.
Please review the below diagram to understand the above concepts:
SQL endpoint(SQL Warehouse) scales horizontally(scale-out) and vertical (scale-up), you have to understand when to use what.
Scale-out -> to add more clusters for a SQL endpoint, change max number of clusters If you are trying to improve the throughput, being able to run as many queries as possible then having an additional cluster(s) will improve the performance.
Databricks SQL automatically scales as soon as it detects queries are in queuing state, in this example scaling is set for min 1 and max 3 which means the warehouse can add three clusters if it detects queries are waiting.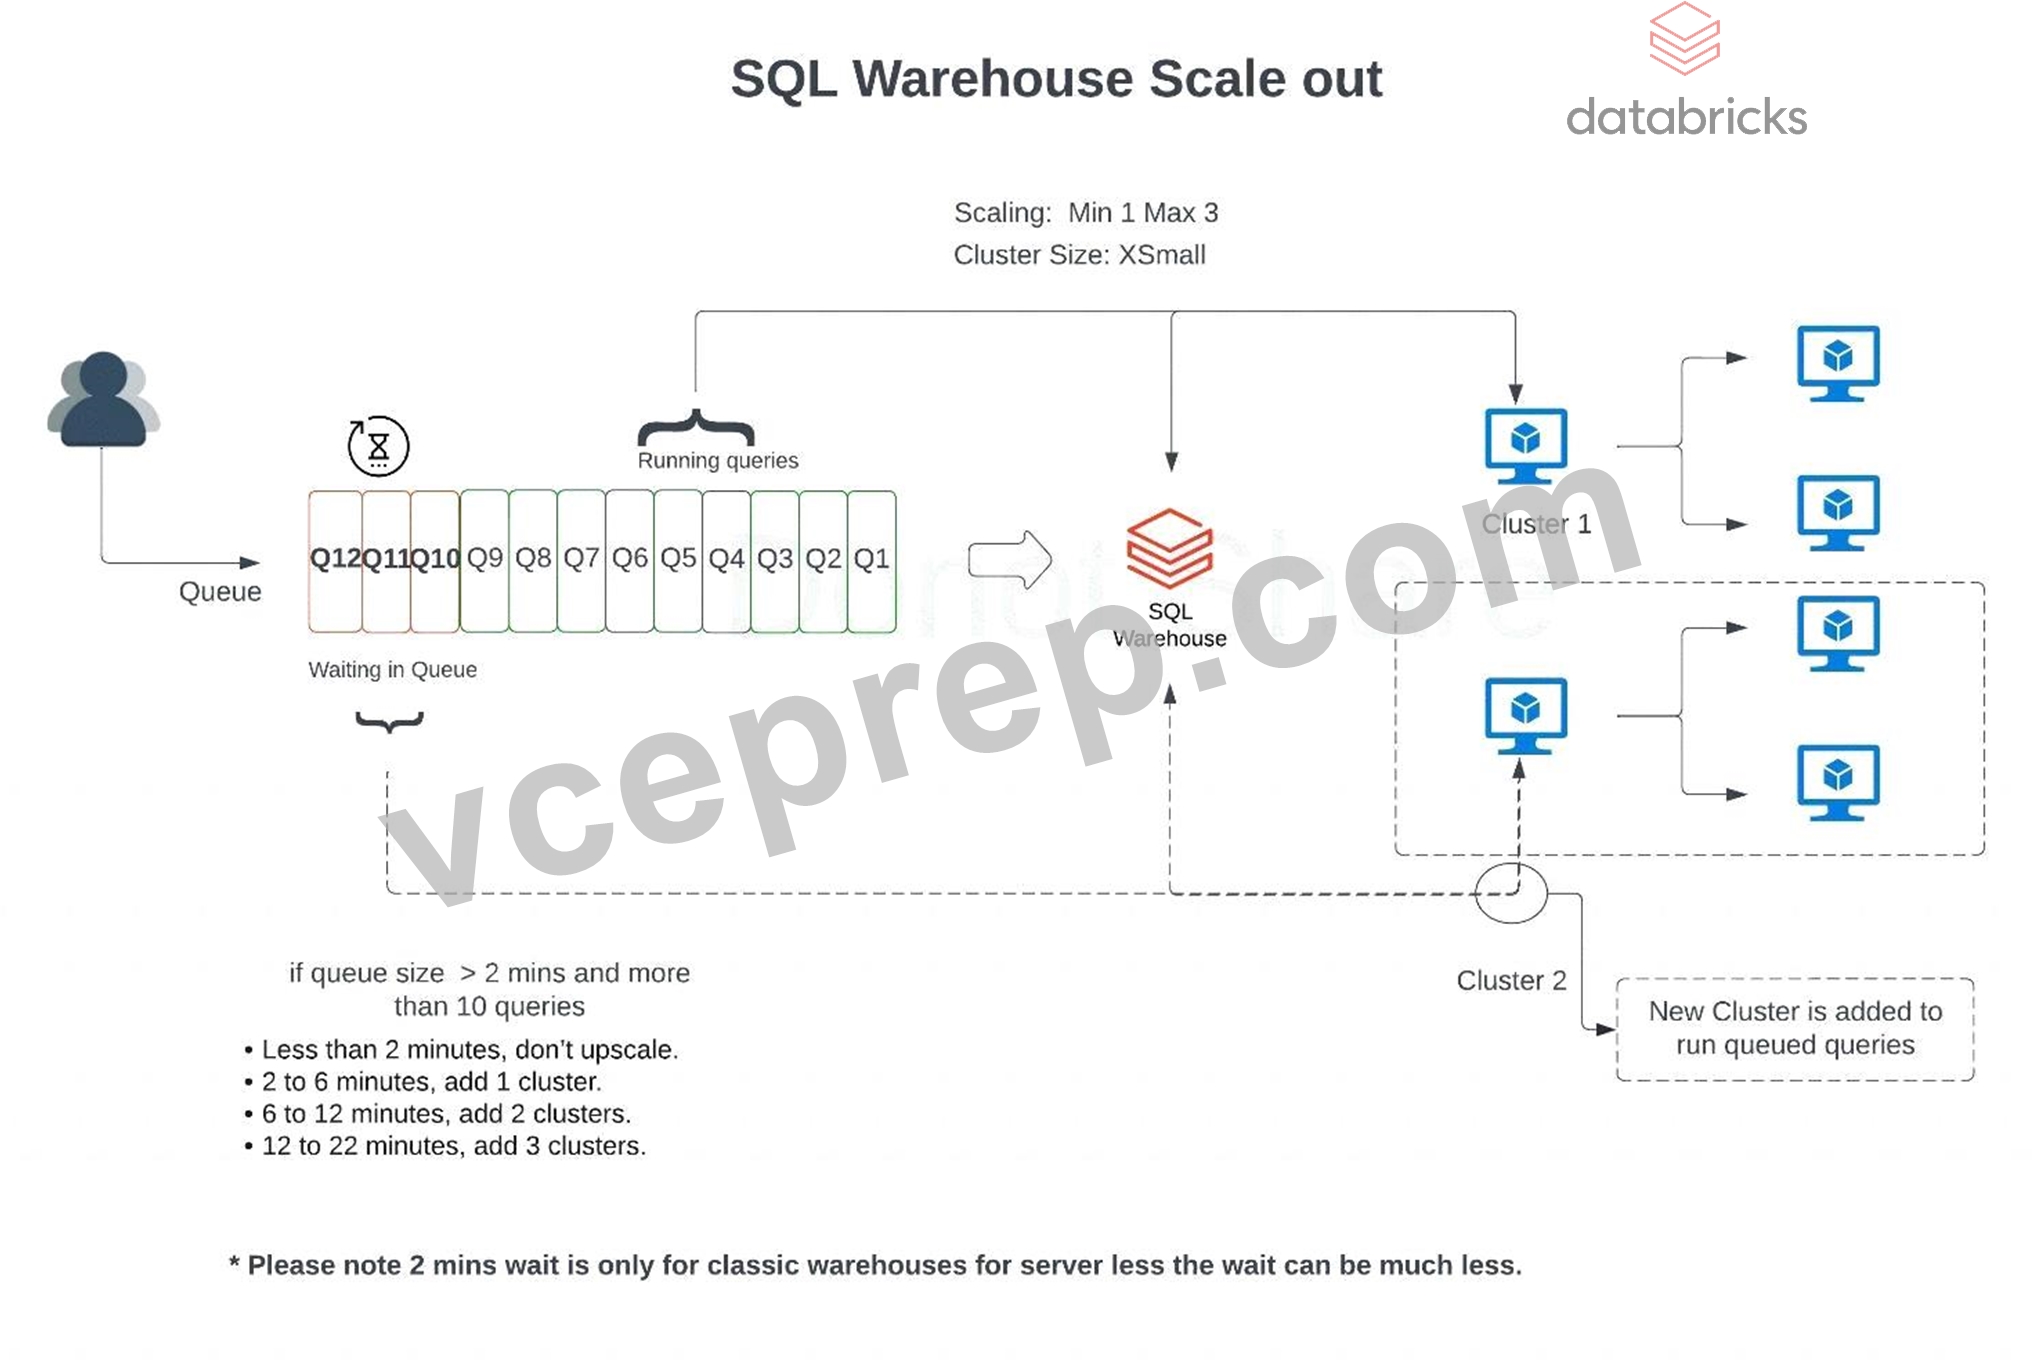
During the warehouse creation or after you have the ability to change the warehouse size (2X-Small....to
...4XLarge) to improve query performance and the maximize scaling range to add more clusters on a SQL Endpoint(SQL Warehouse) scale-out, if you are changing an existing warehouse you may have to restart the warehouse to make the changes effective.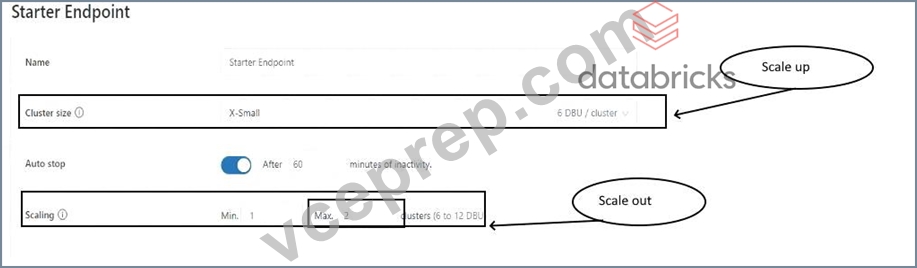
How do you know how many clusters you need(How to set Max cluster size)?
When you click on an existing warehouse and select the monitoring tab, you can see warehouse utilization information(see below), there are two graphs that provide important information on how the warehouse is being utilized, if you see queries are being queued that means your warehouse can benefit from additional clusters. Please review the additional DBU cost associated with adding clusters so you can take a well balanced decision between cost and performance.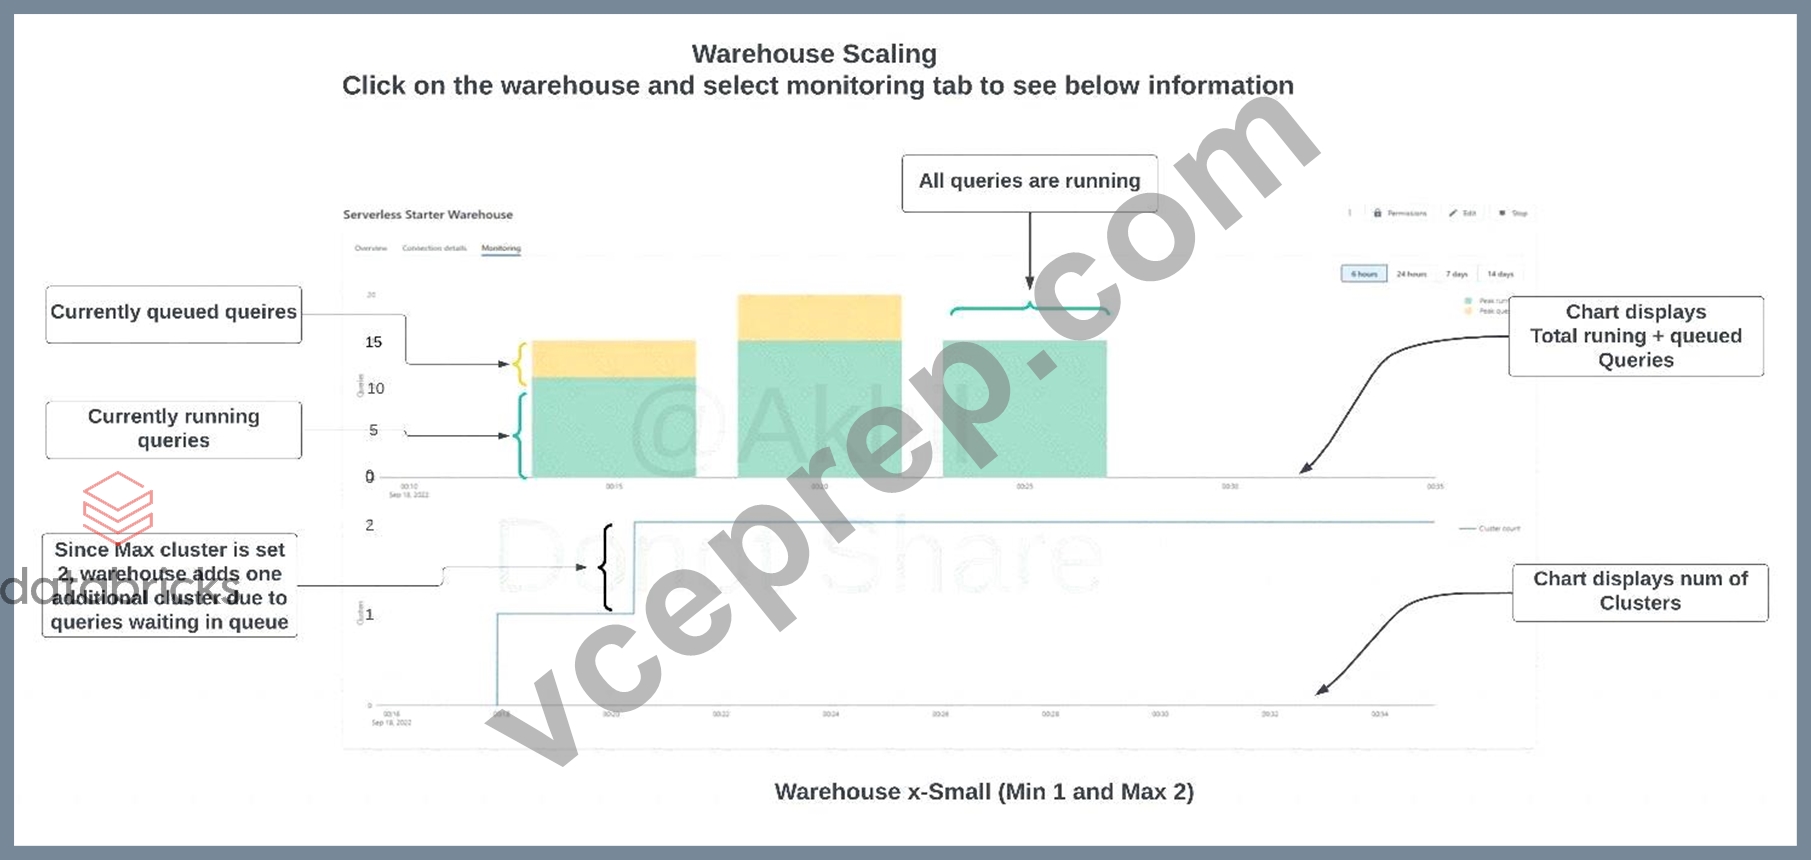
NEW QUESTION # 95
A data engineer is configuring a pipeline that will potentially see late-arriving, duplicate records.
In addition to de-duplicating records within the batch, which of the following approaches allows the data engineer to deduplicate data against previously processed records as it is inserted into a Delta table?
Answer: D
Explanation:
To deduplicate data against previously processed records as it is inserted into a Delta table, you can use the merge operation with an insert-only clause. This allows you to insert new records that do not match any existing records based on a unique key, while ignoring duplicate records that match existing records. For example, you can use the following syntax:
MERGE INTO target_table USING source_table ON target_table.unique_key = source_table.unique_key WHEN NOT MATCHED THEN INSERT * This will insert only the records from the source table that have a unique key that is not present in the target table, and skip the records that have a matching key. This way, you can avoid inserting duplicate records into the Delta table.
References:
* https://docs.databricks.com/delta/delta-update.html#upsert-into-a-table-using-merge
* https://docs.databricks.com/delta/delta-update.html#insert-only-merge
NEW QUESTION # 96
A data engineer is creating a data ingestion pipeline to understand where customers are taking their rented bicycles during use. The engineer noticed that, over time, data being transmitted from the bicycle sensors fail to include key details like latitude and longitude. Downstream analysts need both the clean records and the quarantined records available for separate processing.
The data engineer already has this code:
import dlt
from pyspark.sql.functions import expr
rules = {
"valid_lat": "(lat IS NOT NULL)",
"valid_long": "(long IS NOT NULL)"
}
quarantine_rules = "NOT({})".format(" AND ".join(rules.values()))
@dlt.view
def raw_trips_data():
return spark.readStream.table("ride_and_go.telemetry.trips")
How should the data engineer meet the requirements to capture good and bad data?
Answer: C
Explanation:
Comprehensive and Detailed
The requirement is that both valid (good) and invalid (bad) records must be captured and available separately for downstream processing. Invalid records should not simply be dropped; they must be quarantined in a dedicated table.
In Databricks Lakeflow Declarative Pipelines (DLT), this is achieved by creating separate output tables:
One table for valid records (Silver table) that pass the expectations.
Another quarantine table that explicitly captures records failing the expectations.
Option A correctly implements this by:
Declaring a DLT table trips_data_quarantine.
Using .filter(expr(quarantine_rules)) to isolate invalid records (records where latitude or longitude is NULL).
This ensures analysts can query both good records (from the main Silver pipeline table) and bad records (from the quarantine table).
Why not the others?
B: Uses @dlt.expect_or_drop, which drops invalid records instead of quarantining them. This violates the requirement that quarantined data should be available.
C: Same as B, but applies expectations in bulk with expect_all_or_drop. Again, bad data is dropped, not quarantined.
D: Adds an is_quarantined flag in the same table. While it marks bad records, it does not separate them into a distinct quarantine table as required by the business use case.
Therefore, Option A is the only solution aligned with Databricks documentation for quarantining invalid data into a dedicated table while keeping valid data in the main pipeline.
NEW QUESTION # 97
A Databricks job has been configured with 3 tasks, each of which is a Databricks notebook. Task A does not depend on other tasks. Tasks B and C run in parallel, with each having a serial dependency on task A.
If tasks A and B complete successfully but task C fails during a scheduled run, which statement describes the resulting state?
Answer: E
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the querycreates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The resulting state after running the second command is that an external table will be created in the storage container mounted to /mnt/finance_eda_bucket with the new name prod.sales_by_store. The command will not change any data or move any files in the storage container; it will only update the table reference in the metastore and create a new Delta transaction log for the renamed table. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under
"ALTER TABLE RENAME TO" section; Databricks Documentation, under "Create an external table" section.
NEW QUESTION # 98
......
Databricks-Certified-Professional-Data-Engineer Test Questions Pdf: https://www.vceprep.com/Databricks-Certified-Professional-Data-Engineer-latest-vce-prep.html
BONUS!!! Download part of VCEPrep Databricks-Certified-Professional-Data-Engineer dumps for free: https://drive.google.com/open?id=1IHhasz11D1gjPqhUqPuS8AGkhmF6kP2t