As you know, we are now facing very great competitive pressure. We need to have more strength to get what we want, and Databricks-Certified-Professional-Data-Engineer exam dumps may give you these things. After you use our study materials, you can get Databricks-Certified-Professional-Data-Engineer certification, which will better show your ability, among many competitors, you will be very prominent. Using Databricks-Certified-Professional-Data-Engineer Exam Prep is an important step for you to improve your soft power. I hope that you can spend a little time understanding what our study materials have to attract customers compared to other products in the industry.
Databricks Certified Professional Data Engineer exam is a certification program designed for data professionals who want to validate their expertise in building and maintaining data pipelines using Databricks. Databricks is a cloud-based data engineering platform that provides a unified analytics engine for big data processing, machine learning, and streaming analytics. Databricks-Certified-Professional-Data-Engineer Exam is designed to test a candidate's ability to design, build, and optimize data pipelines using Databricks, as well as their proficiency in data modeling, data warehousing, and data integration.
>> Clearer Databricks Databricks-Certified-Professional-Data-Engineer Explanation <<
ActualPDF offers a full refund guarantee according to terms and conditions if you are not satisfied with our Databricks-Certified-Professional-Data-Engineer product. You can also get free Databricks Dumps updates from ActualPDF within up to 365 days of purchase. This is a great offer because it helps you prepare with the Latest Databricks-Certified-Professional-Data-Engineer Dumps even in case of real Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam changes.
The Databricks Certified Professional Data Engineer Exam certification verifies that the candidate has significant experience in implementing big data solutions that operate on the Databricks Delta Architecture. To earn the certification, a candidate must pass a 90-minute exam consisting of up to 50 multiple-choice and multiple-select questions. The Databricks-Certified-Professional-Data-Engineer Certification is valid for two years from the date of passing the exam.
NEW QUESTION # 142
Which of the following is true of Delta Lake and the Lakehouse?
Answer: C
Explanation:
https://docs.delta.io/2.0.0/table-properties.html
Delta Lake automatically collects statistics on the first 32 columns of each table, which are leveraged in data skipping based on query filters 1 . Data skipping is a performance optimization technique that aims to avoid reading irrelevant data from the storage layer 1 . By collecting statistics such as min/max values, null counts, and bloom filters, Delta Lake can efficiently prune unnecessary files or partitions from the query plan 1 . This can significantly improve the query performance and reduce the I/O cost.
The other options are false because:
* Parquet compresses data column by column, not row by row 2 . This allows for better compression ratios, especially for repeated or similar values within a column 2 .
* Views in the Lakehouse do not maintain a valid cache of the most recent versions of source tables at all times 3 . Views are logical constructs that are defined by a SQL query on one or more base tables 3
. Views are not materialized by default, which means they do not store any data, but only the query definition 3 . Therefore, views always reflect the latest state of the source tables when queried 3 .
However, views can be cached manually using the CACHE TABLE or CREATE TABLE AS SELECT commands.
* Primary and foreign key constraints can not be leveraged to ensure duplicate values are never entered into a dimension table. Delta Lake does not support enforcing primary and foreign key constraints on tables. Constraints are logical rules that define the integrity and validity of the data in a table. Delta Lake relies on the application logic or the user to ensure the data quality and consistency.
* Z-order can be applied to any values stored in Delta Lake tables, not only numeric values. Z-order is a technique to optimize the layout of the data files by sorting them on one or more columns. Z-order can improve the query performance by clustering related values together and enabling more efficient data skipping. Z-order can be applied to any column that has a defined ordering, such as numeric, string, date, or boolean values.
References: Data Skipping , Parquet Format , Views , [Caching], [Constraints] , [Z-Ordering]
NEW QUESTION # 143
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
Answer: C
Explanation:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. These statistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.
Reference: Databricks documentation on Delta Lake optimization techniques, including data skipping and statistics collection (https://docs.databricks.com/delta/optimizations/index.html).
NEW QUESTION # 144
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings.
The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
Answer: C
Explanation:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. These statistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.References: Databricks documentation on Delta Lake optimization techniques, including data skipping and statistics collection (https://docs.databricks.com/delta/optimizations/index.html).
NEW QUESTION # 145
The viewupdatesrepresents an incremental batch of all newly ingested data to be inserted or updated in the customerstable.
The following logic is used to process these records.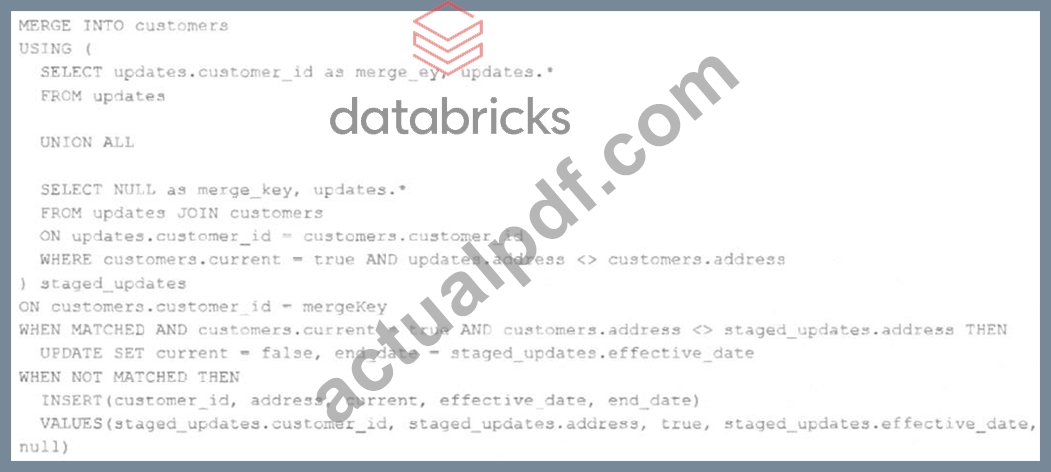
Which statement describes this implementation?
Answer: C
Explanation:
The logic uses the MERGE INTO command to merge new records from the view updates into the table customers. The MERGE INTO command takes two arguments: a target table and a source table or view. The command also specifies a condition to match records between the target and the source, and a set of actions to perform when there is a match or not. In this case,the condition is to match records by customer_id, which is the primary key of the customers table. The actions are to update the existing record in the target with the new values from the source, and set the current_flag to false to indicate that the record is no longer current; and to insert a new record in the target with the new values from the source, and set the current_flag to true to indicate that the record is current. This means that old values are maintained but marked as no longer current and new values are inserted, which is the definition of a Type 2 table. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Merge Into (Delta Lake on Databricks)" section.
NEW QUESTION # 146
A junior data engineer has configured a workload that posts the following JSON to the Databricks REST API endpoint2.0/jobs/create.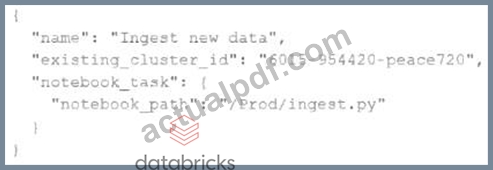
Assuming that all configurations and referenced resources are available, which statement describes the result of executing this workload three times?
Answer: A
Explanation:
This is the correct answer because the JSON posted to the Databricks REST API endpoint 2.0/jobs/create defines a new job with a name, an existing cluster id, and a notebook task. However, it does not specify any schedule or trigger for the job execution. Therefore, three new jobs with the same name and configuration will be created in the workspace, but none of them will be executed until they are manually triggered or scheduled.
Verified References: [Databricks Certified Data Engineer Professional], under "Monitoring & Logging" section; [Databricks Documentation], under "Jobs API - Create" section.
NEW QUESTION # 147
......
Databricks-Certified-Professional-Data-Engineer Test Cram Review: https://www.actualpdf.com/Databricks-Certified-Professional-Data-Engineer_exam-dumps.html