simulation tests of our CCAR-P learning materials have the functions of timing and mocking exams, which will allow you to adapt to the exam environment in advance and it will be of great benefit for subsequent exams. After you complete the learning task, the system of our CCAR-P test prep will generate statistical reports based on your performance so that you can identify your weaknesses and conduct targeted training and develop your own learning plan. For the complex part of our CCAR-P Exam Question, you may be too cumbersome, but our system has explained and analyzed this according to the actual situation to eliminate your doubts and make you learn better.
| Section | Weight | Objectives |
|---|---|---|
| Integration | 19% | - Integrate Claude with enterprise systems, APIs, and tools - Design authentication, authorization, and observability - Implement Model Context Protocol (MCP) integrations - Integrate with data pipelines and RAG systems |
| Governance, Safety & Risk Management | 14% | - Manage data privacy and security compliance - Ensure regulatory compliance (GDPR, HIPAA, etc.) - Implement guardrails and safety controls - Address ethical AI considerations and bias mitigation |
| Stakeholder Communication & Lifecycle Management | 14% | - Conduct structured discovery and requirement gathering - Document architectures and support full lifecycle phases - Communicate architectural decisions and trade-offs - Manage stakeholder feedback and expectation alignment |
| Developer Productivity & Operational Enablement | 7% | - Improve developer workflows with AI-assisted tooling - Support debugging, monitoring, and operational resolution - Configure Claude tools and environments for teams |
| Claude Models, Prompting & Context Engineering | 13% | - Apply context engineering and context management techniques - Mitigate prompt injection, leaks, and jailbreak risks - Design system prompts, templates, and guardrails - Select appropriate Claude models based on trade-offs |
| Solution Design & Architecture | 17% | - Select architectural patterns: workflow, agentic, augmented LLM - Translate business problems into Claude-based AI solutions - Align solutions to business value pillars - Design end-to-end architectures and feedback loops - Design multi-agent systems and orchestration strategies |
| Evaluation, Testing & Optimization | 16% | - Implement iterative improvement pipelines - Optimize performance, prompting, and model selection - Define evaluation metrics and success criteria - Test accuracy, reliability, latency, and cost |
The reason why many people choose DumpsReview is that DumpsReview brings more convenience. IT elites of DumpsReview use their professional eye to search the latest CCAR-P certification training materials, which ensure the accuracy of our CCAR-P Exam Dumps. If you still worry, you can download CCAR-P free demo before purchase.
NEW QUESTION # 74
You are selecting a model for a new production workload and must complete the upstream steps before testing candidate models empirically.
Which two steps must be completed BEFORE running a representative sample on a candidate model? (Select two.) Each correct answer presents part of the solution.
Answer: A,B
Explanation:
Empirical model testing requires a defined decision frame. Option D must occur first because the quality threshold, acceptable latency, expected request volume, and associated cost envelope determine what constitutes a successful result. Without these criteria, a representative-sample test can produce measurements but cannot support a defensible selection.
Option C is the next upstream step. Known model capabilities and the workload profile are used to identify a plausible candidate rather than testing models arbitrarily. Anthropic's model-selection guidance recommends evaluating capability, speed, cost, and effort requirements before narrowing the candidate set. Choosing the Right Model Option A occurs after empirical testing because the architect cannot know which lightest model consistently meets the quality bar until sample results have been evaluated. Option B belongs to ongoing lifecycle management after a new version becomes available. Option E is a deployment-governance activity that follows successful model selection, security review, and readiness validation.
The correct sequence is: define workload criteria, shortlist candidate models, run a representative evaluation, compare quality and operational metrics, select the least costly model that reliably satisfies all gates, and periodically retest the decision.
Study Guide references/topics: Requirements-driven model selection; representative sampling; quality thresholds; latency and volume requirements; capability-cost trade-offs; model lifecycle reassessment.
NEW QUESTION # 75
You are evaluating prompting claims in a peer's design document.
For each claim, select yes if the claim reflects sound practice. Otherwise, select no.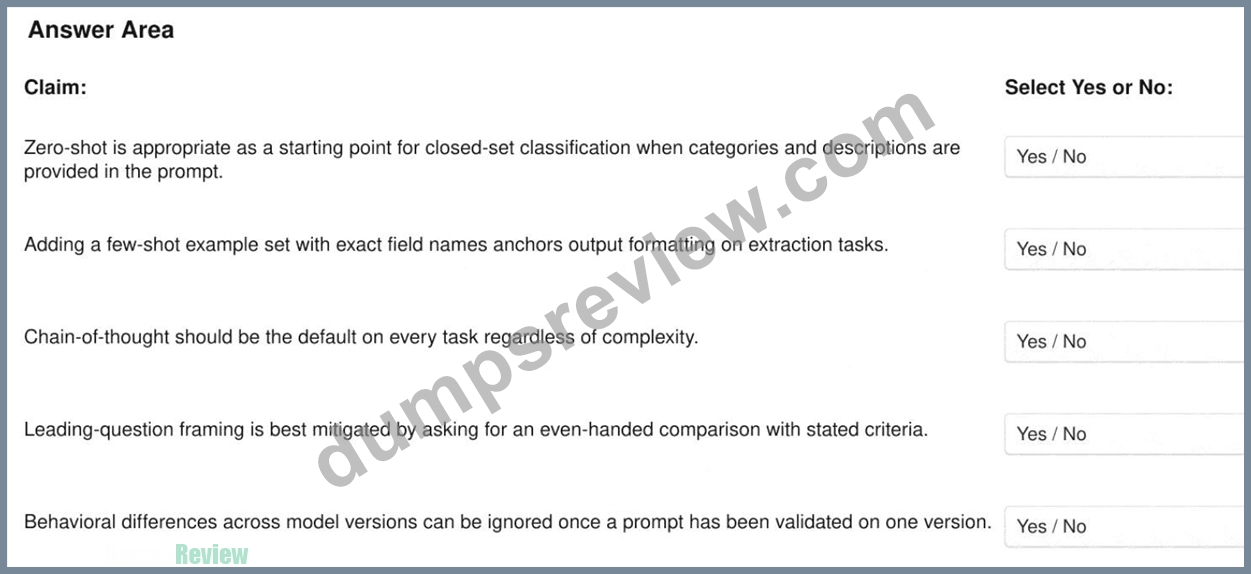
Answer:
Explanation: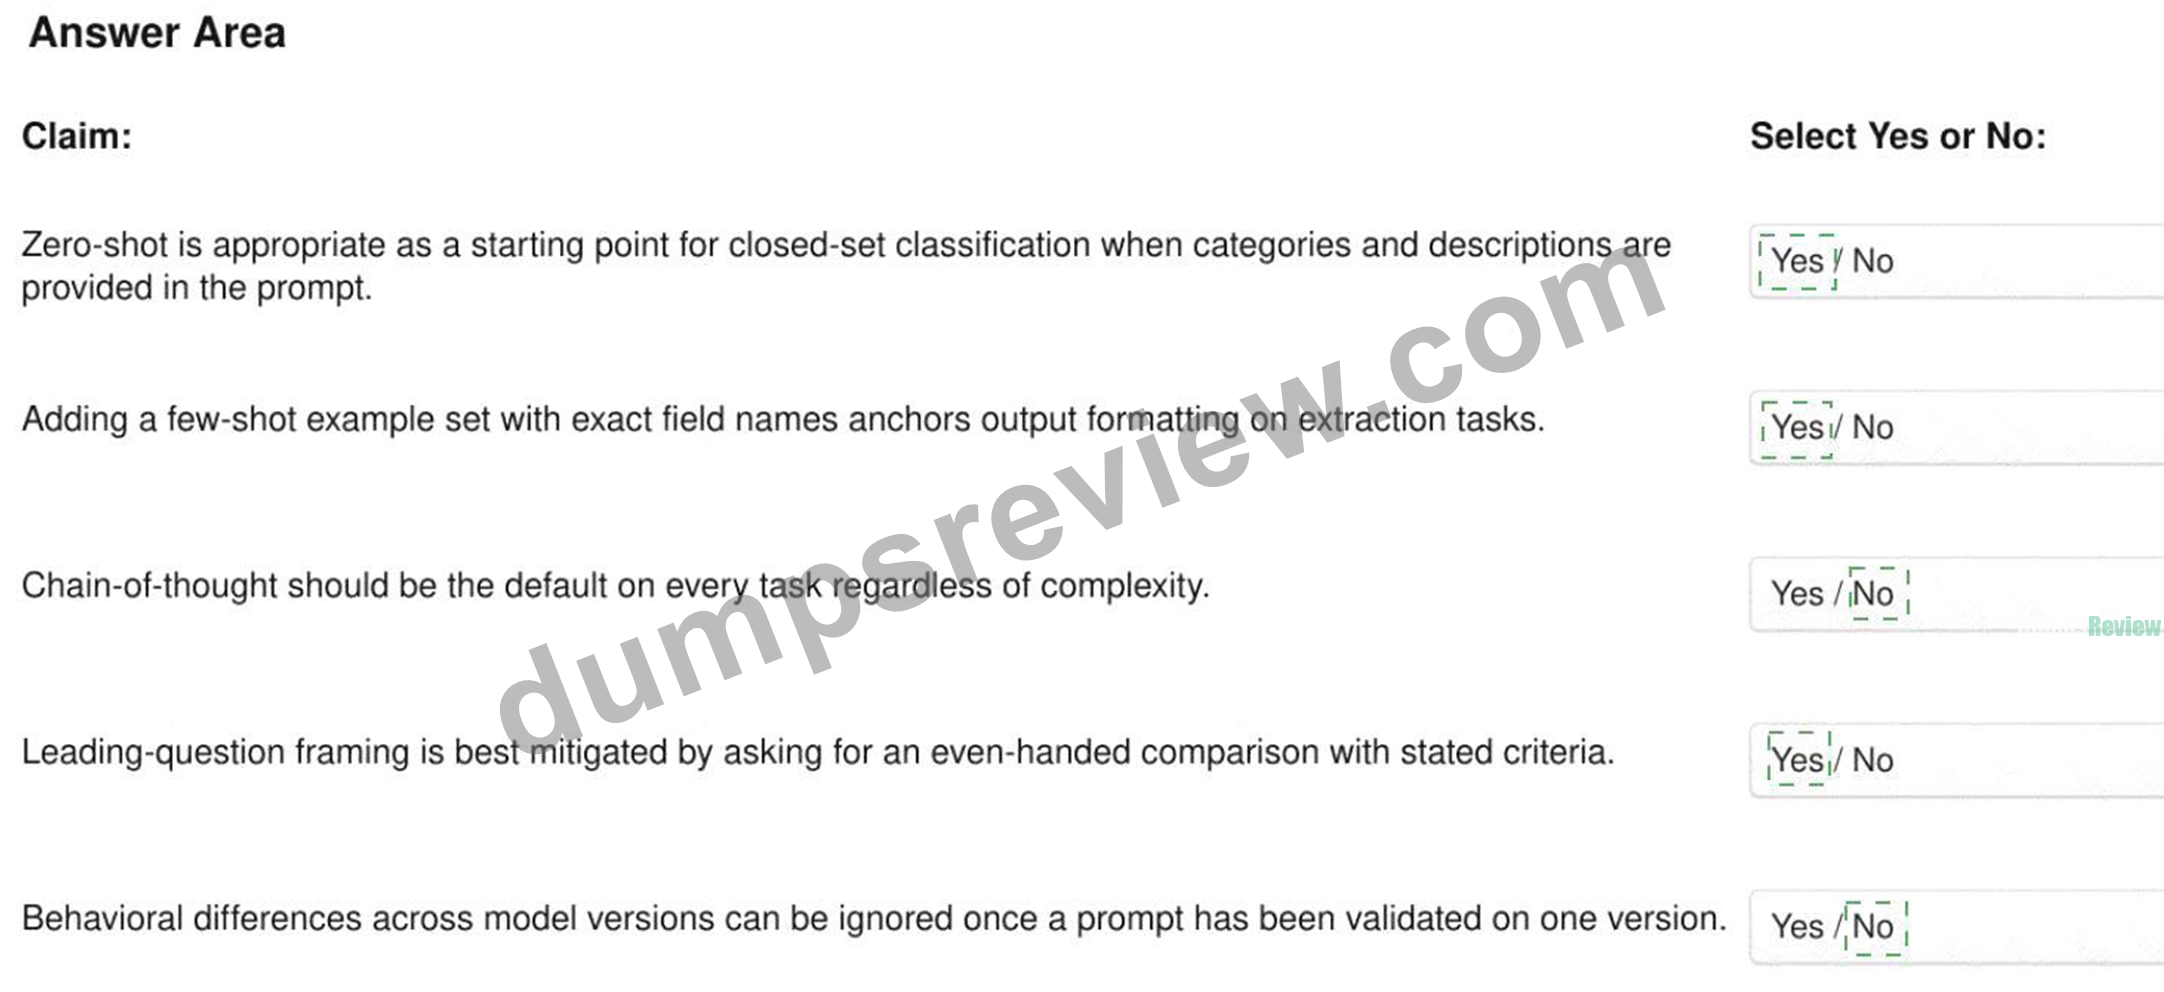
Explanation:
Yes, Yes, No, Yes, No
Zero-shot prompting is a reasonable baseline for a clearly defined closed-set classifier because the model receives both the permissible labels and their meanings. Performance should then be measured against an evaluation set before additional prompt complexity is introduced. Few-shot examples are also sound for extraction because examples containing the exact field names demonstrate the required schema and reduce formatting ambiguity. Anthropic identifies examples as one of the most reliable methods for steering output format, structure, and consistency. Prompting Best Practices Chain-of-thought is not an unconditional default. Additional reasoning is appropriate when the task requires substantive decomposition or complex judgment, but routine classification and extraction may gain little while consuming more tokens and increasing latency. The technique should be selected according to evaluated task requirements.
An even-handed comparison governed by explicit criteria mitigates leading-question bias by requiring symmetrical treatment of alternatives rather than presupposing a preferred conclusion. Finally, prompt validation is model-specific. New model versions may follow instructions differently, change formatting behavior, alter tool selection, or produce different latency and cost characteristics. Anthropic's migration guidance consequently recommends reevaluating prompts and workloads against the new baseline. Model Migration Guide Study Guide references/topics: Zero-shot prompting; few-shot examples; reasoning techniques; neutral framing; model migration and regression evaluation.
NEW QUESTION # 76
You are evaluating model-selection claims used by a peer team.
For each statement, select yes if the statement is generally true. Otherwise, select no.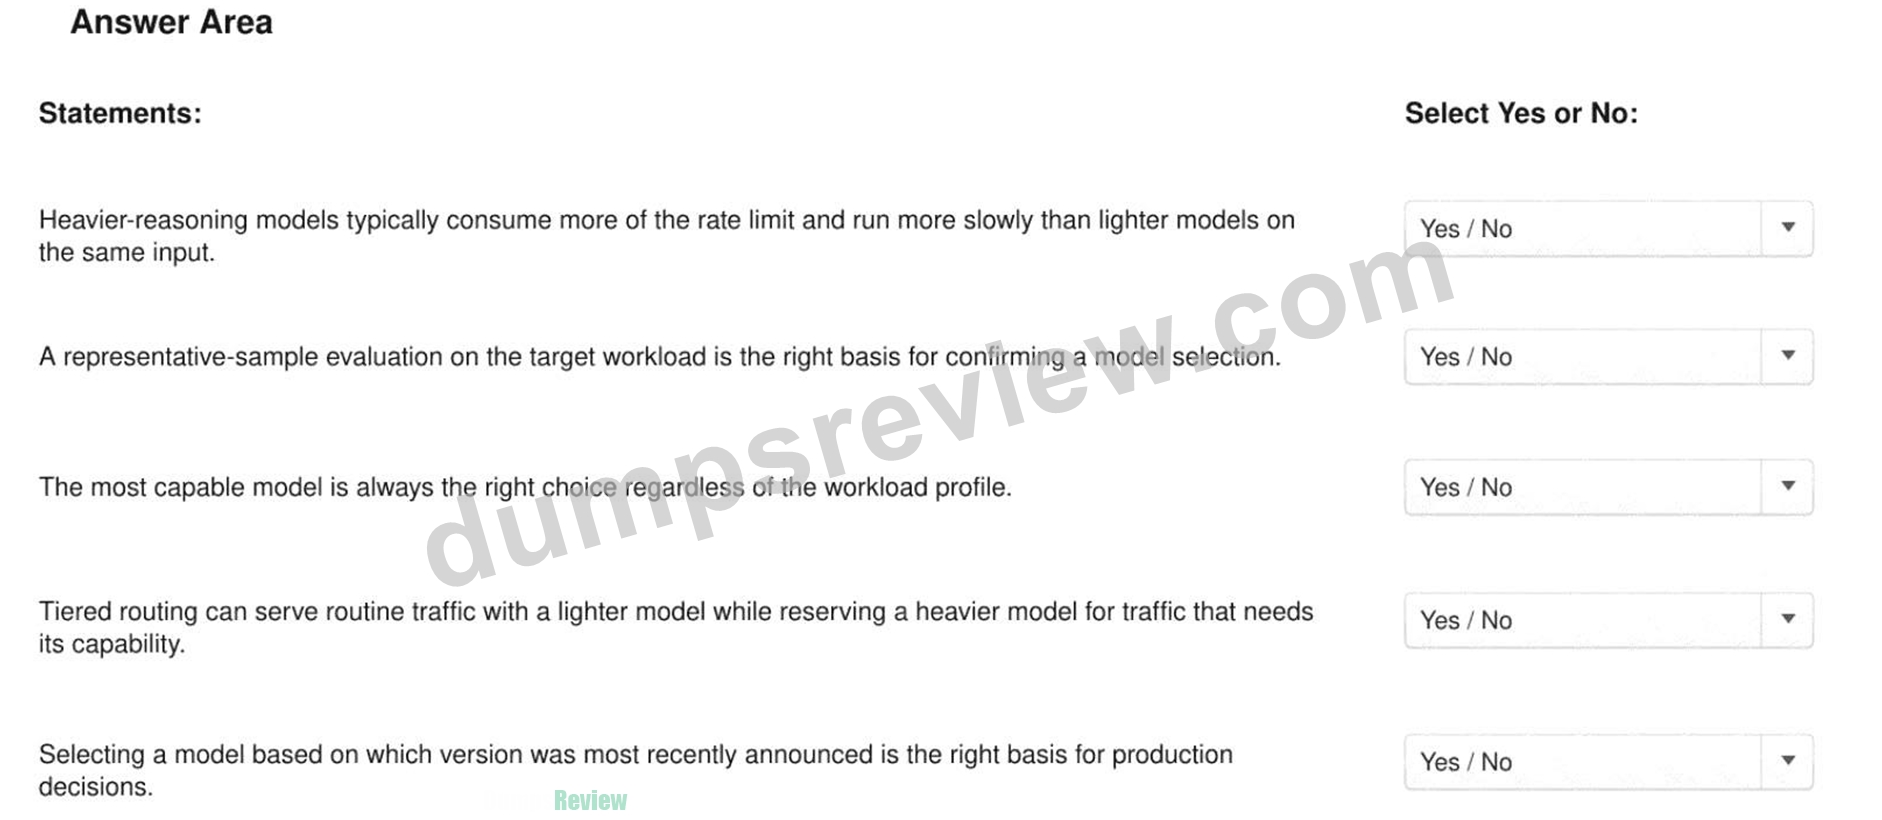
Answer:
Explanation: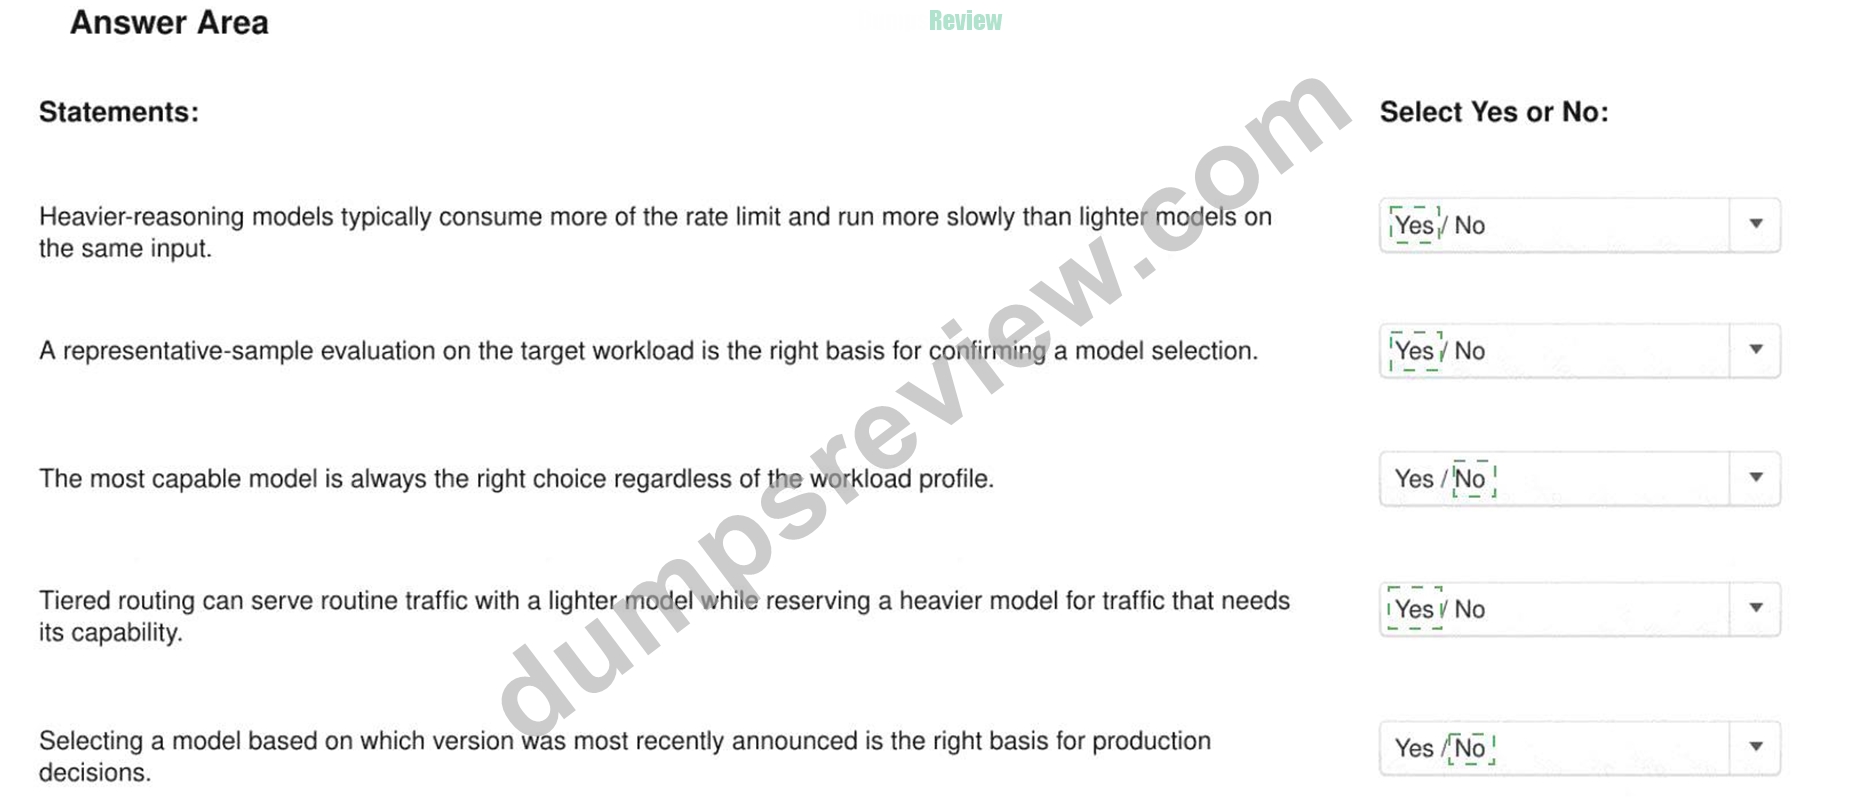
Explanation:
Yes, Yes, No, Yes, No
More capable reasoning configurations generally require greater computation, produce higher latency, and may consume larger token or rate-limit allocations than lighter alternatives. This makes the first statement generally accurate, although actual performance must be measured under the organization's specific provider and service tier.
Representative workload testing is essential because generic benchmark rankings do not establish performance on the organization's prompts, data, edge cases, tools, or required output format. Anthropic recommends benchmark tests specific to the use case, using actual prompts and data, followed by comparison of accuracy, quality, edge-case behavior, and cost. Choosing the Right Model The strongest model is not automatically the correct production choice. Model selection must balance capability, speed, cost, throughput, and operational constraints. Tiered routing implements this principle by serving predictable requests with an efficient model and escalating difficult cases to a more capable model.
Anthropic documents multi-model strategies in which lower-cost workers handle most traffic while harder decisions are escalated.
Recency is also not a valid selection criterion. A newly announced model must pass the workload's existing evaluation, security, latency, and cost gates before replacing a validated production model.
Study Guide references/topics: Model trade-offs; representative evaluations; tiered routing; escalation architectures; cost-capability optimization; model migration validation.
NEW QUESTION # 77
You are building an ethics-review checklist for deployments supported by artificial intelligence.
Which two checks belong on the list? (Select two.)
Each correct answer presents a complete solution.
Answer: B,C
Explanation:
An ethics review must examine unsupported generalizations, stereotyping, disparate treatment, and other conclusions about people that are not justified by the evidence. It must also preserve identifiable human accountability for consequential decisions; responsibility cannot be transferred to a probabilistic system.
Licensing is a legal and commercial-control question, while latency and throughput are operational requirements. Both remain important, but neither is the central ethical test presented here. Restricting review to low-confidence or threshold-triggering outputs is also inadequate because models can express harmful or biased conclusions with high confidence. Ethical review should cover representative populations, protected and intersectional groups, high-impact outcomes, override mechanisms, transparency, and channels for challenge or appeal.
Study Guide references/topics: Bias and unsupported generalization; human accountability; consequential decisions; ethical oversight.
NEW QUESTION # 78
A Claude architect is leading the discovery phase for a new AI-powered customer service solution.
Which two activities are characteristic of structured discovery and requirement gathering for a Claude-based deployment? (Select two.)
Answer: B,E
Explanation:
Structured discovery begins by eliciting constraints from the people who own the business outcome, operate the process, manage risk, and will use or support the deployed system. Stakeholder workshops in Option A identify measurable expectations concerning accuracy, latency, throughput, cost, privacy, compliance, escalation, and acceptable failure behavior before the solution is scoped.
Option D converts those expectations into production gates. Success criteria must be explicit enough to evaluate empirically, while failure thresholds must determine when the design requires remediation, human review, or rejection. Anthropic's evaluation guidance states that successful LLM applications begin with defined success criteria and evaluations that measure performance against them. It characterizes strong criteria as specific, measurable, achievable, and relevant. Define Success Criteria and Build Evaluations Option B prematurely selects a model before the workload profile is known. Option C can supplement discovery, but reaction-driven prototyping cannot replace documented requirements and acceptance criteria.
Option E postpones essential constraints until architectural commitments may already have been made.
The discovery output should create traceability from stakeholder objectives to requirements, evaluation metrics, architecture decisions, and deployment gates.
Study Guide references/topics: Structured discovery; stakeholder workshops; nonfunctional requirements; success criteria; failure thresholds; production readiness gates.
NEW QUESTION # 79
......
If you want to pass CCAR-P exam certification or improve your IT skills, DumpsReview will be your best choice. With many years'hard work, the passing rate of CCAR-P test of DumpsReview is 100%. Our CCAR-P Exam Dumps and training materials include complete restore and ensure you pass the CCAR-P exam certification easier.
Latest CCAR-P Exam Notes: https://www.dumpsreview.com/CCAR-P-exam-dumps-review.html