2026 Latest Pass4sures DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=1cyj4hVD2lbDxFQ3eGNUTzV-dvOmyTnsU
As what have been demonstrated in the records concerning the pass rate of our DP-750 free demo, our pass rate has kept the historical record of 98% to 99% from the very beginning of their foundation. During these years, our PDF version of our DP-750 study engine stays true to its original purpose to pursue a higher pass rate that has never been attained in the past. And you will be content about our considerate service on our DP-750 training guide. If you have any question, you can just contact us!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Data quality and validation
|
| Topic 2: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Topic 3: Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Topic 4: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
>> Microsoft DP-750 Vce Free <<
Download the free DP-750 demo of whatever product you want and check its quality and relevance by comparing it with other available study contents within your access. Pass4sures’s study guides and DP-750 Dump will prove their worth and excellence. Check also the feedback of our clients to know how our products proved helpful in passing the exam.
NEW QUESTION # 16
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named Catalog 1. Catalog 1 contains a table named Transactions. Transactions contains the following columns:
* transaction_id
* customet_name
* email address
* credit_card_number
* transaction_amount
You need to ensure that business analysts can query all the tows in the Transactions table. The solution must meet the following requirements:
* Prevent the analysts from seeing the full values in the email_address and credit_catd_number columns.
* Ensure that the analysts can see only the values after the @ character in each email address.
* Ensure that the analysts can see only the last four digits of each credit card number.
* Enable the analysts to query the table without errors.
* Follow the principle of least privilege.
What should you do?
Answer: C
Explanation:
The correct answer is C. Column masks are the right tool when you need to partially expose sensitive data rather than hide it entirely. A column mask is a SQL function attached to a column that rewrites the returned value based on who is querying. For email_address, the mask returns only the substring after '@'. For credit_card_number, it returns only the last four digits. Business analysts get useful data without seeing anything sensitive, and they can still query the table without errors.
Option A (row-level filters) controls which rows a user sees, not the values within a row - it can't partially redact a column. Option B (grant SELECT only on non-sensitive columns) removes the columns entirely, so analysts can't see even partial email or card values - that doesn't meet the 'can see only partial values' requirement. Option D (column-level encryption) requires key management infrastructure and decryption at query time, which is significantly more complex than column masking for this use case.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/row-and-column- filters
NEW QUESTION # 17
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to create a job in Lakeflow Jobs named Job1 that:
* Ingests data from cloud storage
* Runs two independent transformation tasks
The transformation tasks must run only after the ingestion completes and must run in parallel.
You need to design the task logic for Job1.
What should you configure?
Answer: A
Explanation:
Job1 should contain one ingestion task that acts as the common upstream dependency for two separate transformation tasks. Once ingestion succeeds, Lakeflow Jobs can start both downstream tasks concurrently because neither transformation depends on the other. This design represents the actual workflow, avoids duplicated ingestion, and reduces total execution time through parallelism. Creating two ingestion tasks would repeat the same source processing and could introduce inconsistent results or unnecessary costs. A single sequential task would prevent parallel transformation and make failures harder to isolate and retry. Defining three independent tasks without dependencies could allow transformations to start before ingestion has completed. An explicit directed task graph therefore provides the required execution order while preserving parallelism for independent downstream processing.
NEW QUESTION # 18
You have an Azure Databricks workspace that contains multiple all-purpose clusters.
You discover that some clusters remain idle for long periods after users finish their work.
You need to reduce compute costs without affecting active workloads.
What should you do?
Answer: A
Explanation:
To reduce compute costs from idle clusters without impacting active workloads, you must configure Auto-Termination and use Cluster Policies.
Core Remedies
*-> Auto-Termination: Set a strict inactivity timeout (e.g., 20-30 minutes) on all-purpose clusters to automatically shut them down when idle.
Cluster Policies: Enforce maximum auto-termination limits across the workspace so users cannot disable or set excessively long idle timeouts.
Single User Access Mode: Use this mode where possible, as it tracks idleness more accurately than Shared mode by monitoring the specific user's activity.
Reference:
https://medium.com/@sujathamudadla1213/databricks-lakehouse-platform-describe-how- clusters-are-terminated-and-the-impact-of-terminating-a-b6236689fd2e
NEW QUESTION # 19
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to ensure that data lineage is captured and can be reviewed for tables accessed by Databricks notebooks and jobs. The solution must minimize administrative effort.
Which compute configuration should you use to capture the data lineage, and what should you use to review the data lineage? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.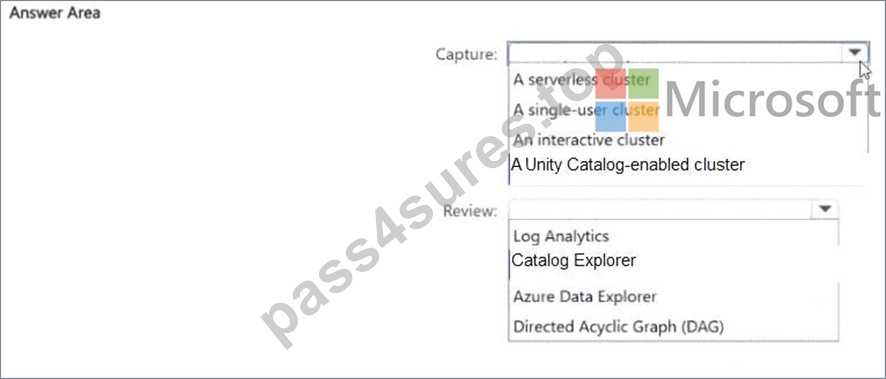
Answer:
Explanation: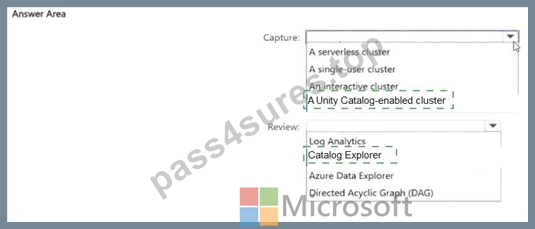
Explanation:
Data lineage in Unity Catalog is captured automatically - but only when jobs and notebooks run on clusters that are Unity Catalog-aware. Specifically, clusters must use 'Shared' or 'Single User' access mode. Clusters set to 'No Isolation Shared' or legacy 'High Concurrency' mode do not emit lineage events to the Unity Catalog lineage service.
No instrumentation, logging code, or external tools are required. The lineage service operates transparently, intercepting read and write operations at the Spark plan level and recording the table-to-table and column-to- column relationships.
To review captured lineage, open Catalog Explorer, navigate to the table, and select the Lineage tab. This shows the upstream sources that populate the table and the downstream consumers that read from it - all as an interactive graph, with no additional tooling needed. This built-in visibility is one of the core governance benefits Unity Catalog provides.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/data-lineage
NEW QUESTION # 20
Hotspot Question
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming. The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.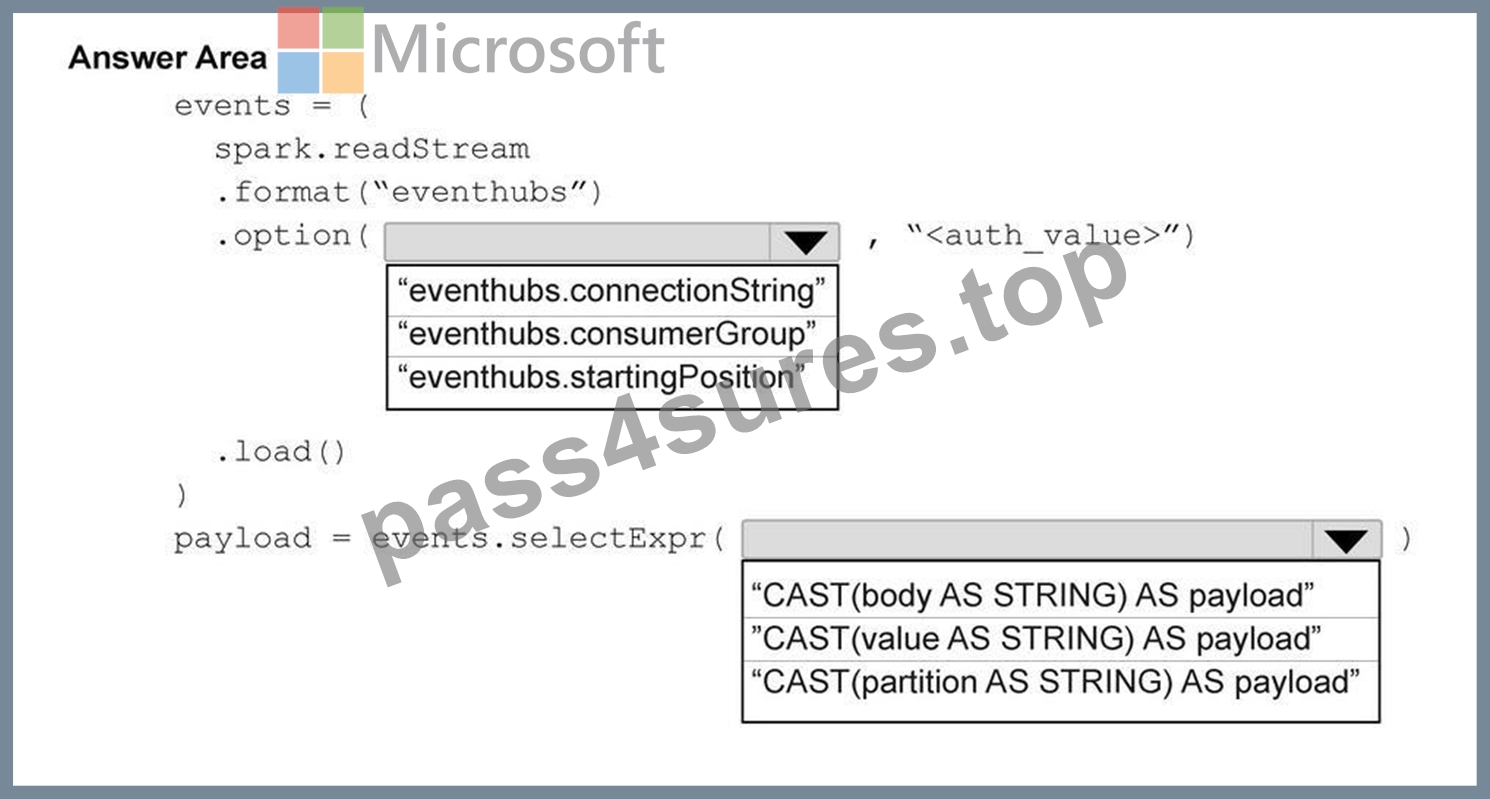
Answer:
Explanation: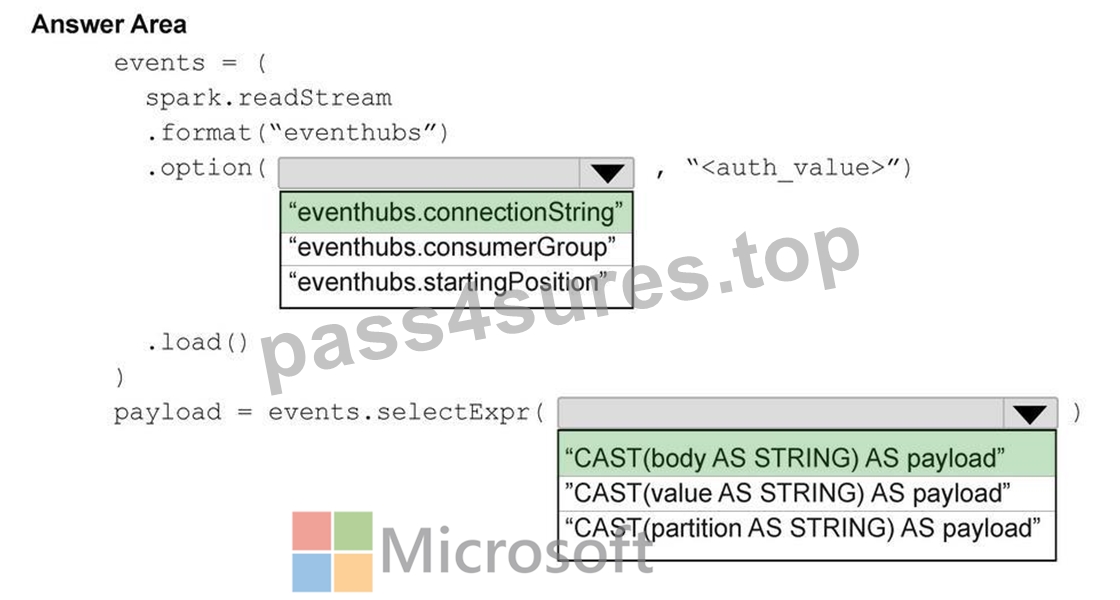
NEW QUESTION # 21
......
It has a lot of advantages. Giving yourself more time to prepare for the Microsoft DP-750 exam questions using it will allow you to obtain your DP-750 certification. It is one of the major reasons many people prefer buying Implementing Data Engineering Solutions Using Azure Databricks DP-750 Exam Dumps preparation material. It was designed by the best Microsoft Exam Questions who took the time to prepare it.
DP-750 Latest Torrent: https://www.pass4sures.top/Microsoft-Certified-Fabric-Data-Engineer-Associate/DP-750-testking-braindumps.html
What's more, part of that Pass4sures DP-750 dumps now are free: https://drive.google.com/open?id=1cyj4hVD2lbDxFQ3eGNUTzV-dvOmyTnsU