P.S. MogiExamがGoogle Driveで共有している無料かつ新しいDP-700ダンプ:https://drive.google.com/open?id=1ryDR6yug1g7AAfRqgQ-z76_YtGcx0juf
MogiExamのDP-700問題集はあなたを楽に試験の準備をやらせます。それに、もし最初で試験を受ける場合、試験のソフトウェアのバージョンを使用することができます。これは完全に実際の試験雰囲気とフォーマットをシミュレートするソフトウェアですから。このソフトで、あなたは事前に実際の試験を感じることができます。そうすれば、実際のDP-700試験を受けるときに緊張をすることはないです。ですから、心のリラックスした状態で試験に出る問題を対応することができ、あなたの正常なレベルをプレイすることもできます。
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Data Engineering Solutions Using Microsoft Fabric |
| Exam Number: | DP-700 |
| Exam Price: | Varies by region (approx. $165 USD) |
| Real Exam Qty: | 40-60 |
| Exam Duration: | 100-120 |
| Available Languages: | German, Korean, English, French, Simplified Chinese, Portuguese (Brazil), Spanish, Japanese |
| Passing Score: | 700/1000 |
| Certificate Validity Period: | 1 year (renewable) |
| Exam Format: | Multiple response, Multiple choice, Scenario-based questions, Case studies |
| Related Certifications: | Microsoft Certified: Fabric Analytics Engineer Associate Microsoft Certified: Azure Data Engineer Associate |
| Recommended Training: | Microsoft Fabric Documentation Microsoft Learn DP-700 Learning Path |
| Exam Registration: | Microsoft Learn Certification Exam Page Pearson VUE Microsoft Exams |
| Sample Questions: | Microsoft DP-700 Sample Questions |
| Exam Way: | Online proctored via Pearson VUE or in-person at authorized testing centers |
| Pre Condition: | No formal prerequisites, but recommended experience with Azure data services and basic data engineering concepts |
| Official Syllabus URL: | https://learn.microsoft.com/credentials/certifications/exams/dp-700/ |
他の人はあちこちでMicrosoft DP-700試験資料を探しているとき、あなたはすでに勉強中で、準備階段でライバルに先立ちます。また、我々MogiExamは量豊かのMicrosoft DP-700試験資料を提供しますし、ソフト版であなたにMicrosoft DP-700試験の最も現実的な環境をシミュレートさせます。勉強中で、何の質問があると、メールで我々はあなたのためにすぐ解決します。心配はありませんし、一心不乱に試験復習に取り組んでいます。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
質問 # 87
You have a Fabric workspace that contains an eventhouse and a KQL database named Database1. Database1 has the following:
A table named Table1
A table named Table2
An update policy named Policy1
Policy1 sends data from Table1 to Table2.
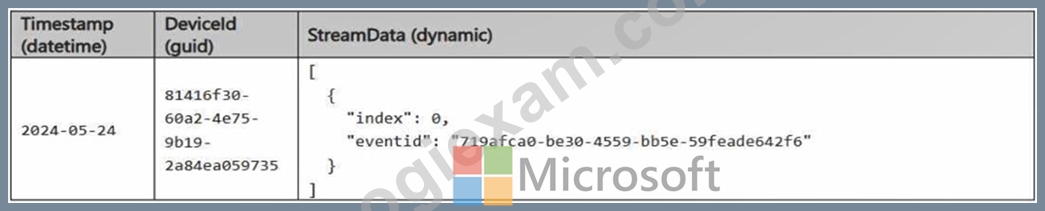
The following is a sample of the data in Table2.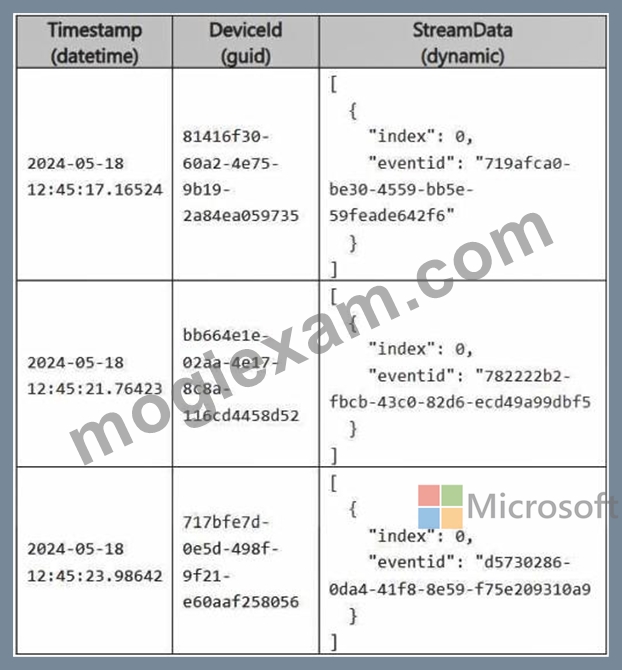
Recently, the following actions were performed on Table1:
An additional element named temperature was added to the StreamData column.
The data type of the Timestamp column was changed to date.
The data type of the DeviceId column was changed to string.
You plan to load additional records to Table2.
Which two records will load from Table1 to Table2? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
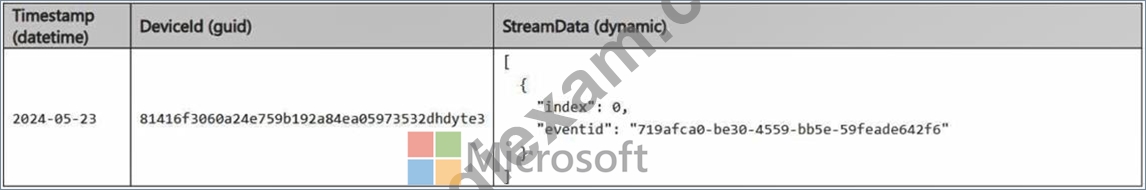
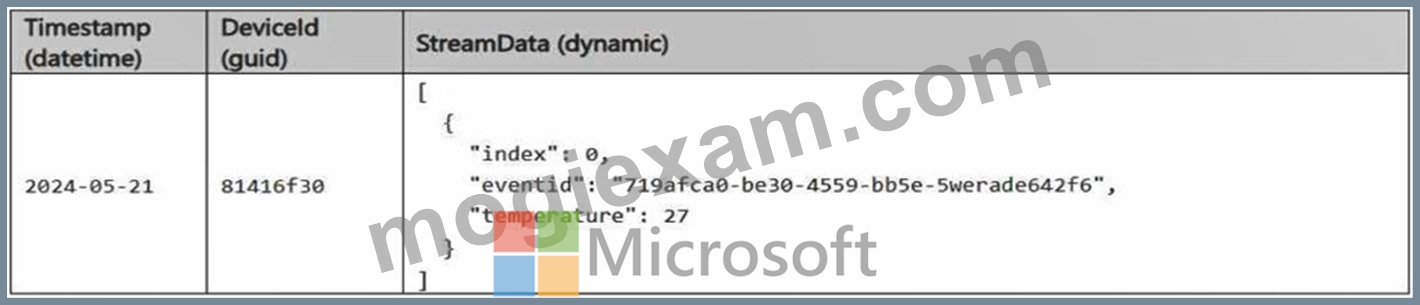
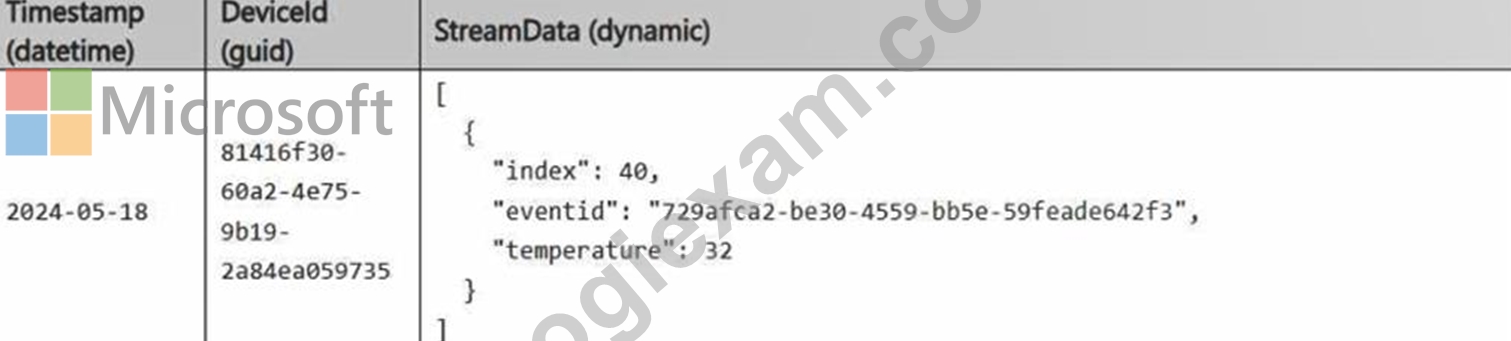
正解:B、D
解説:
Changes to Table1 Structure:
StreamData column: An additional temperature element was added.
Timestamp column: Data type changed from datetime to date.
DeviceId column: Data type changed from guid to string.
Impact of Changes:
Only records that comply with Table2's structure will load.
Records that deviate from Table2's column data types or structure will be rejected.
Record B:
Timestamp: Matches Table2 (datetime format).
DeviceId: Matches Table2 (guid format).
StreamData: Contains only the index and eventid, which matches Table2.
Accepted because it fully matches Table2's structure and data types.
Record D:
Timestamp: Matches Table2 (datetime format).
DeviceId: Matches Table2 (guid format).
StreamData: Matches Table2's structure.
Accepted because it fully matches Table2's structure and data types.
質問 # 88
You need to ensure that the data engineers are notified if any step in populating the lakehouses fails. The solution must meet the technical requirements and minimize development effort.
What should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.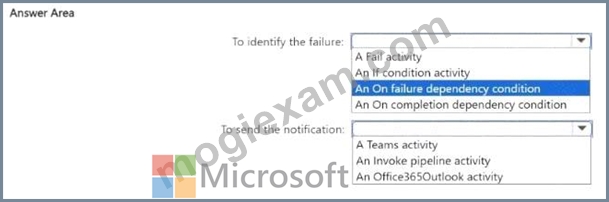
正解:
解説: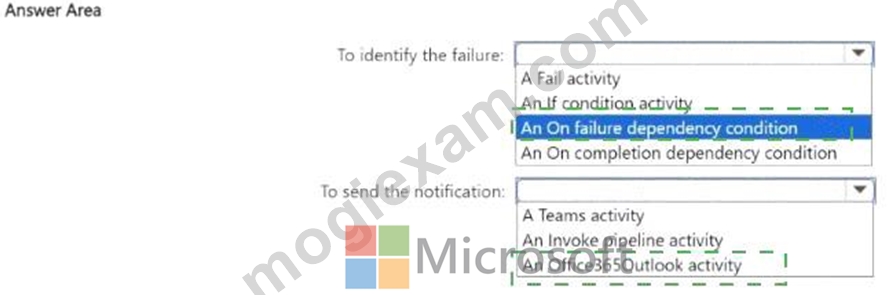
Explanation: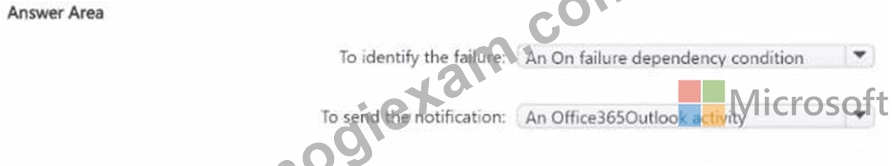
質問 # 89
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a KQL database that contains two tables named Stream and Reference. Stream contains streaming data in the following format.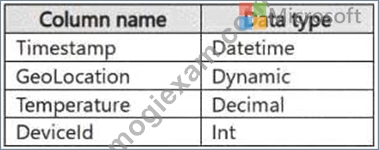
Reference contains reference data in the following format.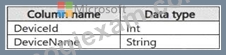
Both tables contain millions of rows.
You have the following KQL queryset.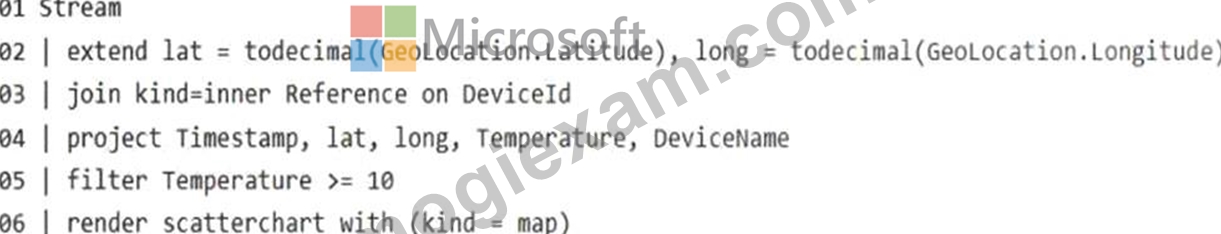
You need to reduce how long it takes to run the KQL queryset.
Solution: You change the join type to kind=outer.
Does this meet the goal?
正解:A
解説:
An outer join will include unmatched rows from both tables, increasing the dataset size and processing time.
It does not improve query performance.
質問 # 90
You have a Fabric workspace named Workspace1 that contains an Apache Spark job definition named Job1.
You have an Azure SQL database named Source1 that has public internet access disabled.
You need to ensure that Job1 can access the data in Source1.
What should you create?
正解:C
質問 # 91
You plan to process the following three datasets by using Fabric:
* Dataset1: This dataset will be added to Fabric and will have a unique primary key between the source and the destination. The unique primary key will be an integer and will start from 1 and have an increment of 1.
* Dataset2: This dataset contains semi-structured data that uses bulk data transfer. The dataset must be handled in one process between the source and the destination. The data transformation process will include the use of custom visuals to understand and work with the dataset in development mode.
* Dataset3. This dataset is in a takehouse. The data will be bulk loaded. The data transformation process will include row-based windowing functions during the loading process.
You need to identify which type of item to use for the datasets. The solution must minimize development effort and use built-in functionality, when possible. What should you identify for each dataset? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.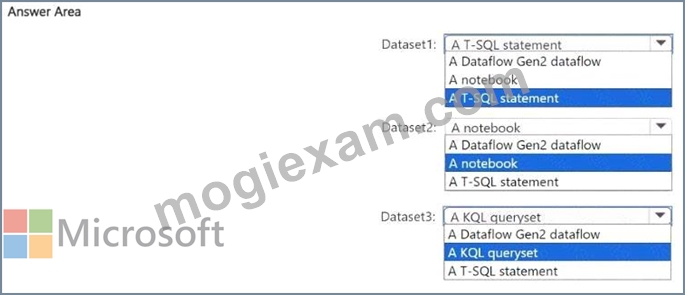
正解:
解説: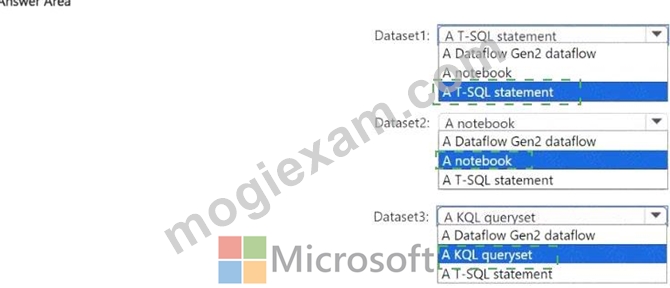
Explanation: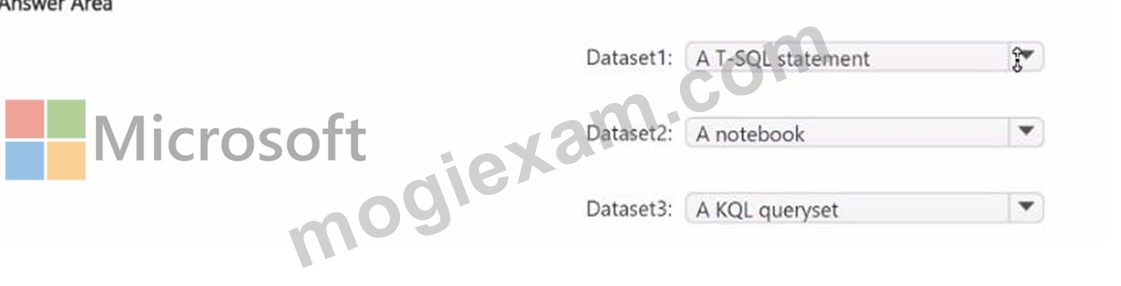
質問 # 92
......
DP-700関連試験: https://www.mogiexam.com/DP-700-exam.html
P.S. MogiExamがGoogle Driveで共有している無料かつ新しいDP-700ダンプ:https://drive.google.com/open?id=1ryDR6yug1g7AAfRqgQ-z76_YtGcx0juf