Study SPS-C01 Center - SPS-C01 Valid Dumps Sheet

2026 Latest TestInsides SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1-48bPTGqthd2YQmhuNpP_GBwzvoooF-y
Moreover, you do not need an active internet connection to utilize TestInsides desktop Snowflake Certified SnowPro Specialty - Snowpark practice exam software. It works without the internet after software installation on Windows computers. The TestInsides web-based Snowflake SPS-C01 Practice Test requires an active internet and it is compatible with all operating systems.
| Section | Weight | Objectives |
|---|
| Topic 1: Snowpark API for Python | 30% | - User-Defined Functions (UDFs) and Stored Procedures
- Reading and writing data
- Establishing connections and session management
- Working with Semi-structured data
- DataFrame creation and manipulation
|
| Topic 2: Performance Optimization and Best Practices | 20% | - Warehouse sizing for Snowpark
- Debugging and explain plans
- Caching strategies
- Query pushdown and optimization
- Minimizing data transfer
- Vectorized UDFs
|
| Topic 3: Data Transformations and DataFrame Operations | 35% | - Using built-in functions
- Persisting transformed data
- Complex data pipelines
- Window functions
- Filtering, Aggregating, and Joining DataFrames
|
| Topic 4: Snowpark Concepts | 15% | - Client-side vs. Server-side execution
- Transformations vs. Actions
- Stored procedures and conditional logic
- Snowpark DataFrames and query plans
- Snowpark architecture and core concepts
- Snowpark Sessions and connection management
|
>> Study SPS-C01 Center <<
Highly-Praised SPS-C01 Qualification Test Helps You Pass the Snowflake Certified SnowPro Specialty - Snowpark Exam - TestInsides
In your day-to-day life, things look like same all the time. Sometimes you feel the life is so tired, do the same things again and again every day. Doing the same things and living on the same life make you very bored. So hurry to prepare for SPS-C01 exam, we believe that our SPS-C01 exam braindumps will help you change your present life. It is possible for you to start your new and meaningful life in the near future, if you can pass the Snowflake exam and get the certification. So it is very important for you to prepare for the practice exam, you must pay more attention to the SPS-C01 Certification guide to help you.
Snowflake Certified SnowPro Specialty - Snowpark Sample Questions (Q128-Q133):
NEW QUESTION # 128
You have a Snowpark Python application that reads data from a Snowflake table, performs a complex transformation using a User- Defined Table Function (UDTF), and then writes the transformed data back to a new Snowflake table. The UDTF is defined as follows:
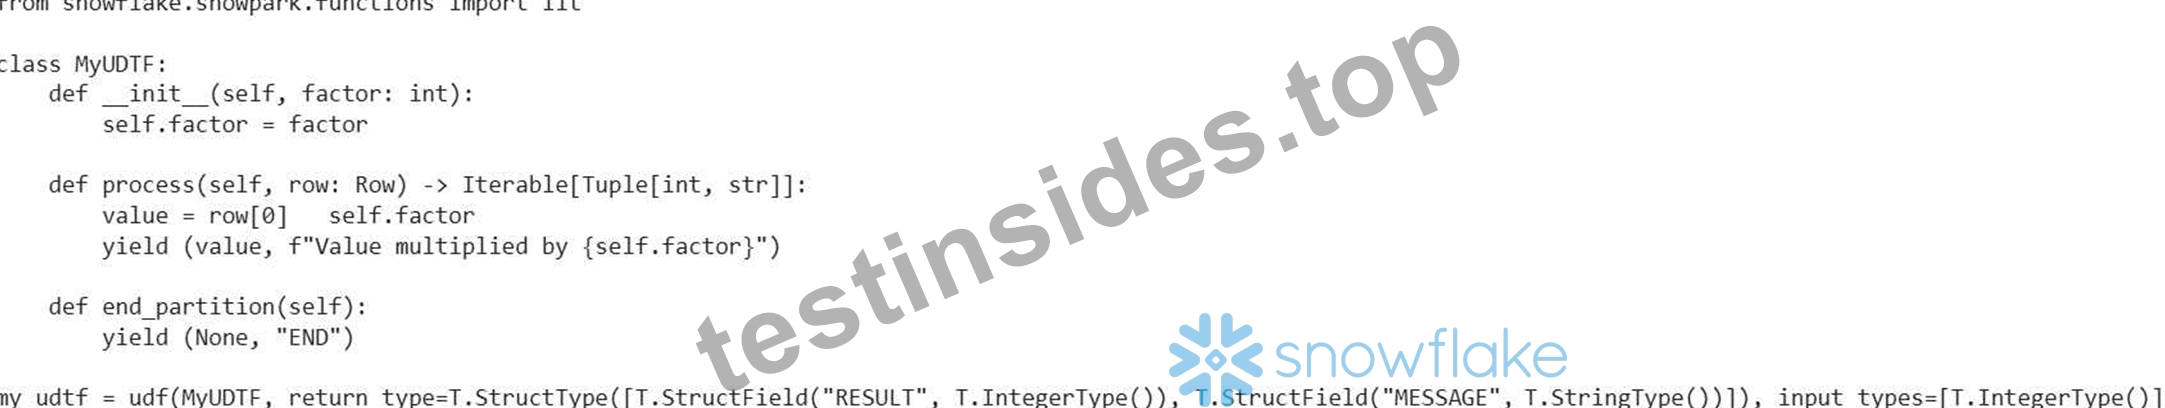
You need to optimize the performance of this application. Which of the following strategies would be MOST effective in reducing the execution time of the UDTF?
- A. Reduce the number of rows in the input table by applying a filter before calling the UDTF.
- B. Use a vectorized UDTF instead of a standard UDTF, processing data in batches. (Assume 'vectorized=True' is a valid parameter for 'udf .)
- C. Cache the input DataFrame before applying the UDTF using 'df.cache()'.
- D. Replace the UDTF with a standard User-Defined Function (UDF) as UDFs are inherently faster.
- E. Increase the warehouse size to the largest available option before running the Snowpark application.
Answer: B
Explanation:
Vectorized UDTFs process data in batches, which can significantly improve performance compared to processing each row individually. This is especially true for complex transformations. Increasing warehouse size (A) can help but might not be as efficient as vectorization. Reducing input data (B) is always a good practice, but vectorization provides a more direct performance boost to the UDTF execution. Standard UDFs (D) are not generally faster than UDTFs, especially when dealing with table transformations. Caching (E) can help if the DataFrame is reused multiple times, but it doesn't directly optimize the UDTF's performance.
NEW QUESTION # 129
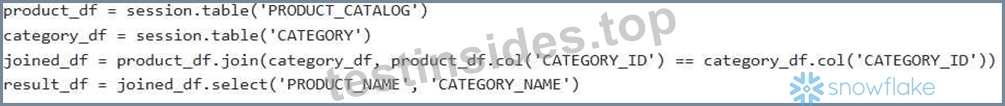
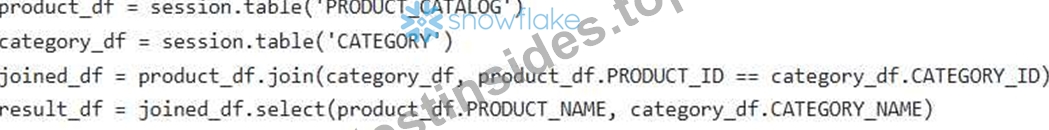
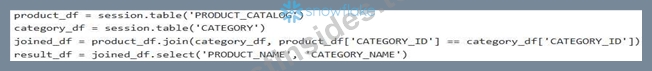
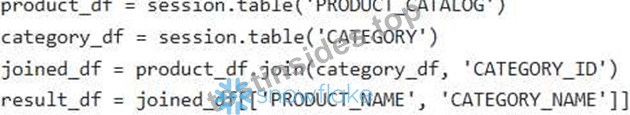
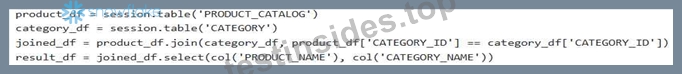
You have a Snowflake table 'PRODUCT CATALOG' with columns 'PRODUCT ID, 'PRODUCT NAME, and 'CATEGORY ID. You also have a table 'CATEGORY' with 'CATEGORY ID' and 'CATEGORY NAME. You need to create a Snowpark DataFrame that joins these two tables and includes only 'PRODUCT NAME and 'CATEGORY NAME. Assume a Snowpark Session object named 'session' is available. Which code snippet demonstrates creating the DataFrame using Snowpark's join functionality and column selection while using the 'table' method?
Answer: E
Explanation:
Option D correctly joins the tables using the 'join' method with a column expression specifying the join condition. It also correctly selects only the desired columns using and option A incorrectly uses 'PRODUCT_ID instead of for the join and needs 'col()' to reference columns. option B selects 'PRODUCT_NAME', 'CATEGORY_NAME' without using 'col(Y which will cause an error since the join brings duplicate column names from product_df and category_df. Option C uses Pythonic '[['PRODUCT_NAME', 'CATEGORY_NAME'I]' which only works on Pandas dataframes. option E attempts to use col() to reference the columns in the join condition which is incorrect as it is a column expression needs to use fully qualified table name for the same named column in two dataframes; moreover selection is missing col().
NEW QUESTION # 130
You're tasked with creating a Snowpark UDF to calculate the Haversine distance between two sets of latitude and longitude coordinates (point A and point B). Which of the following statements about deploying and using this UDF is/are TRUE?
- A. When defining the UDF with input types, the Python types must exactly match the corresponding Snowflake data types.
- B. The UDF can be written in Python, Java, or Scala. Using a Java UDF will likely offer best performance, especially when dealing with very large datasets. You'll need to stage the compiled JAR file on an internal stage that Snowpark can access.
- C. The UDF can only be called directly from within the Snowpark session and cannot be used in standard Snowflake SQL queries.
- D. The UDF, once defined, can be used inside of any DataFrame operation like 'select', 'filter' , and 'withColumn'
- E. The UDF can only be written in Python and must be deployed as an inline UDF within the Snowpark session.
Answer: C,D
NEW QUESTION # 131
You have a Snowpark DataFrame named 'transactions' containing transaction data'. You need to create a UDTF using Python to categorize transactions into 'High Value', 'Medium Value', and 'Low Value' based on the transaction amount and the customer's region. The categorization logic requires access to a dynamically updated lookup table stored in a Snowflake stage. Which approach would be MOST efficient and scalable, minimizing data transfer and maximizing Snowpark's vectorized operations?
- A. Create a vectorized UDF. Load the lookup table from the stage into the UDF's environment once during initialization. Then, process transactions in batches using pandas DataFrames within the UDF.
- B. Use a scalar UDF, reading the lookup table from the stage for each transaction. This ensures data consistency but may incur significant overhead for each row processed.
- C. Define a scalar UDF that queries the lookup table directly from Snowflake using a Snowflake connector. This avoids data transfer to the UDF but introduces external dependency and connection management overhead for each row.
- D. Use a UDTF with the parameter, reading the lookup table directly into the UDTF using a Snowpark DataFrame and joining it with each batch of the 'transactions DataFrame. Materialize the result to a temporary table.
- E. Create a vectorized UDTF that loads the lookup table into memory during the first call, and then caches it for subsequent calls. Implement a refresh mechanism using a Snowflake external function triggered by stage updates.
Answer: A
Explanation:
A vectorized UDF is the most efficient approach. It allows processing data in batches using pandas DataFrames, leveraging vectorized operations for faster execution. Loading the lookup table once during initialization and reusing it avoids repeated data transfer. While option E sounds appealing, caching mechanisms can get complex to manage for data recency. Snowflake stages are generally more suitable as temporary lookup tables rather than permanent caching solution as they're design for data loading operations.
NEW QUESTION # 132
You are designing a Snowpark application to process streaming data ingested into Snowflake using Snowpipe. The application needs to apply a complex set of transformations and aggregations to the incoming data in real-time. Which of the following approaches would be MOST suitable for this scenario, leveraging the strengths of Snowpark architecture?
- A. Use Snowpark to define a series of chained UDFs that perform the transformations and aggregations directly within the Snowpipe pipeline.
- B. Continuously query the incoming data from Snowpipe using a Snowpark DataFrame and perform the transformations and aggregations on the client-side in a loop.
- C. Create a Snowpark DataFrame that represents the incoming data and use the 'write_pandaS function to write the transformed data to a separate Snowflake table after each micro-batch.
- D. Define a Snowpark Stored Procedure ('sproc') that is triggered automatically by a Snowflake Task whenever new data arrives via Snowpipe. The stored procedure performs the transformations and aggregations and stores the results in a new table.
- E. Utilize Snowflake's Streams and Tasks feature and define views with complex SQL transformations that leverages Snowpipe.
Answer: D
Explanation:
Using a Snowpark Stored Procedure triggered by a Snowflake Task provides the best solution for real-time processing of streaming data from Snowpipe. The Task automates the execution of the stored procedure whenever new data is available, and the stored procedure leverages Snowpark's server-side capabilities to perform the transformations and aggregations efficiently within the Snowflake environment. Option A involves client-side processing, Option B isn't compatible with Snowpipe directly and chained UDFs may not optimal for complex transformations and aggregations. Option C involves constant writes and may have performance issues with large datasets. While option E could work, utilizing Snowpark stored procedures provides better flexibility and Python code integration for more complex logic.
NEW QUESTION # 133
......
If you visit our website TestInsides, then you will find that our Snowflake SPS-C01 practice questions are written in three different versions: PDF version, Soft version and APP version. All types of SPS-C01 Training Questions are priced favorably on your wishes. Obtaining our Snowflake SPS-C01 study guide in the palm of your hand, you can achieve a higher rate of success.
SPS-C01 Valid Dumps Sheet: https://www.testinsides.top/SPS-C01-dumps-review.html
- Free PDF Quiz Professional Snowflake - Study SPS-C01 Center 😲 Easily obtain free download of ➥ SPS-C01 🡄 by searching on ▶ www.easy4engine.com ◀ 🤳SPS-C01 Real Dumps Free
- 2026 100% Free SPS-C01 –Updated 100% Free Study Center | SPS-C01 Valid Dumps Sheet 🍻 Download ➥ SPS-C01 🡄 for free by simply entering ⮆ www.pdfvce.com ⮄ website ⌨SPS-C01 New Questions
- High Pass-Rate Study SPS-C01 Center - Accurate SPS-C01 Valid Dumps Sheet: Snowflake Certified SnowPro Specialty - Snowpark 🍭 Download ▷ SPS-C01 ◁ for free by simply entering { www.pass4test.com } website 🐛Examcollection SPS-C01 Dumps Torrent
- Quiz Authoritative Snowflake - Study SPS-C01 Center 🦊 Search for ☀ SPS-C01 ️☀️ on ➥ www.pdfvce.com 🡄 immediately to obtain a free download 🪔SPS-C01 Real Dumps Free
- SPS-C01 Latest Exam Notes 🏨 New SPS-C01 Test Guide 🧂 Real SPS-C01 Exam 🎱 Search for ➤ SPS-C01 ⮘ and easily obtain a free download on ➠ www.pdfdumps.com 🠰 🦚Test SPS-C01 Cram
- Latest SPS-C01 Practice Materials 📏 Valid Test SPS-C01 Fee 🌳 Test SPS-C01 Cram 📅 Search for ⮆ SPS-C01 ⮄ and download it for free immediately on ➽ www.pdfvce.com 🢪 🚵SPS-C01 Latest Exam Notes
- Download SPS-C01 Fee 🧬 Valid Test SPS-C01 Fee ☎ Examcollection SPS-C01 Dumps Torrent 🦹 Search for ➡ SPS-C01 ️⬅️ on “ www.prepawayexam.com ” immediately to obtain a free download ✊SPS-C01 Test Guide Online
- SPS-C01 Latest Exam Notes 🦎 Latest SPS-C01 Practice Materials 🏞 SPS-C01 Real Dumps Free 🧣 Search on 【 www.pdfvce.com 】 for ( SPS-C01 ) to obtain exam materials for free download 🤝Exam SPS-C01 Tips
- 2026 100% Free SPS-C01 –Updated 100% Free Study Center | SPS-C01 Valid Dumps Sheet 🚆 Copy URL ➥ www.validtorrent.com 🡄 open and search for ▷ SPS-C01 ◁ to download for free 👘Exam SPS-C01 Discount
- SPS-C01 Latest Exam Notes 🤓 Exam SPS-C01 Tips 🌐 Real SPS-C01 Exam 🍸 The page for free download of ✔ SPS-C01 ️✔️ on 【 www.pdfvce.com 】 will open immediately 🕴SPS-C01 Test Guide Online
- Exam SPS-C01 Passing Score 🔶 Exam SPS-C01 Passing Score 🛅 New SPS-C01 Test Guide 🕒 Search for 《 SPS-C01 》 and download exam materials for free through ☀ www.verifieddumps.com ️☀️ ☔SPS-C01 Latest Exam Notes
- jacobscott67888.blogspot.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, schoolido.lu, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026 Latest TestInsides SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1-48bPTGqthd2YQmhuNpP_GBwzvoooF-y