人々は異なる目標がありますが、我々はあなたにMicrosoftのAI-300試験に合格させるという同じ目標があります。この目標を達成するのは、あなたにとってIT分野での第一歩だけですが、我々のMicrosoftのAI-300ソフトを開発するすべての意義です。だから、我々は尽力して我々の問題集を多くしてXhs1991の専門かたちに研究させてあなたの合格する可能性を増大します。あなたの利用するMicrosoftのAI-300ソフトが最新版のを保証するために、一年間の無料更新を提供します。
| Section | Objectives |
|---|---|
| Topic 1: Plan and design AI solutions using Azure AI services | - Requirements gathering and solution architecture
|
| Topic 2: Implement secure and scalable AI systems | - Security and governance
|
| Topic 3: Operationalizing machine learning solutions | - ML lifecycle management
|
| Topic 4: Design and implement generative AI solutions | - Large language model integration
|
これは、今後のAI-300テストのために有効な試験準備資料を購入する良い方法です。 適切な選択により、半分の労力で2倍の結果が得られます。 適切な試験準備により、明確な方向性が示され、効率的な準備ができます。 AI-300試験の準備は正しい方向を示すだけでなく、実際の試験問題のほとんどをカバーできるため、試験の内容を事前に知ることができます。 Microsoft AI-300試験準備の質問と回答をマスターし、試験気分を積極的に調整することもできます。
質問 # 166
A team provisions an Azure Machine Learning environment by triggering pull requests.
Deployments must be automated, auditable, and require approval before running.
You need to select a deployment automation tool.
Which tool should you use?
正解:C
解説:
GitHub Actions is the best tool for this scenario.
Pull Request Integration: GitHub Actions is a native continuous integration and continuous delivery (CI/CD) platform built directly into GitHub. It can natively listen for repository events- such as triggering a workflow automatically when a pull request is opened, updated, or merged.
Required Approvals: It provides built-in governance through Environments. You can configure specific deployment environments (e.g., Production) to enforce required reviewers, ensuring a deployment cannot run until an authorized user manually approves it.
Auditable Logs: Every workflow execution, event trigger, and manual approval is tracked chronologically within GitHub. This provides a highly transparent, centralized audit trail for compliance requirements.
Reference:
https://learn.microsoft.com/en-us/azure/developer/github/github-actions
質問 # 167
Your ML pipeline contains independent feature engineering steps that currently execute sequentially, increasing overall runtime. You want to optimize execution without modifying logic.
What is the BEST solution?
正解:A
解説:
Parallel execution allows independent pipeline steps to run simultaneously, reducing total execution time without altering logic. This is more efficient than increasing compute resources, which may raise costs without guaranteeing proportional performance improvements.
質問 # 168
Drag and Drop Question
You complete the fine-tuning of a generative model in Microsoft Foundry. The fine-tuned model now appears as a new model variant in your development environment.
The deployment process must ensure that proper validation and control is maintained.
You need to promote the fine-tuned model from development to production.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.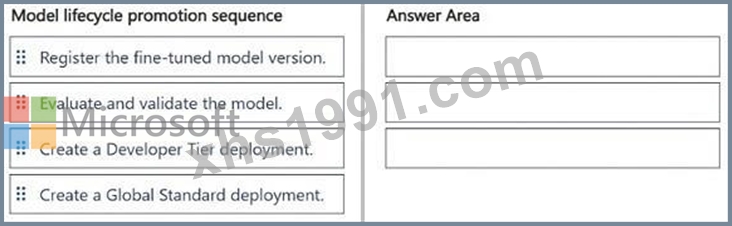
正解:
解説: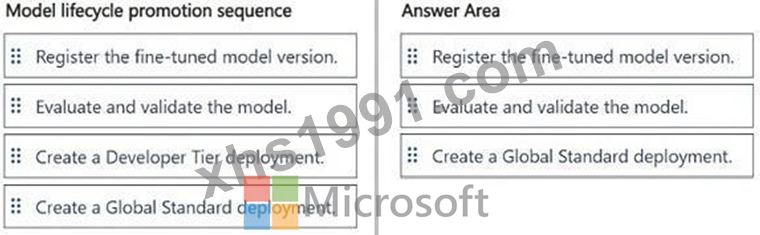
質問 # 169
You need to isolate training workloads while remaining cost-aware to address Fabrikam Inc.'s issues, constraints, and technical requirements.
What should you implement?
正解:C
解説:
Imagine a hospital analytics firm with data scientists who kick off dozens of training jobs throughout the week. During peak hours, five jobs compete for the same GPU cluster and fail or queue for hours. On quiet nights, that cluster sits completely idle, burning money. Managed compute targets with autoscaling solve both problems: the cluster scales out automatically when multiple jobs arrive simultaneously and scales back to zero when idle. Option A (single shared cluster) is exactly the resource-contention problem Fabrikam already has. Option B (fixed-size cluster) wastes money during off-peak hours. Option C (dedicated per-experiment clusters) eliminates contention but is prohibitively expensive for a cost-conscious healthcare firm.
Autoscaling managed compute is the cloud-native answer to variable workload demand.
Microsoft Learn Reference Topic: Azure Machine Learning compute targets - Configure autoscale for compute clusters
質問 # 170
Hotspot Question
You manage a Microsoft Foundry project.
You plan to build a RAG solution.
The solution must include two models:
- One for text output, named Model1. This model must resemble human
language and read naturally.
- One for creating embeddings, named Model2. This model must maximize
the retrieval of relevant results (high recall) while minimizing
irrelevant or incorrect matches (high precision).
You need to compare different models by using benchmarking metrics to select the appropriate models for Model1 and Model2.
Which benchmarking metric should you select for each model? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.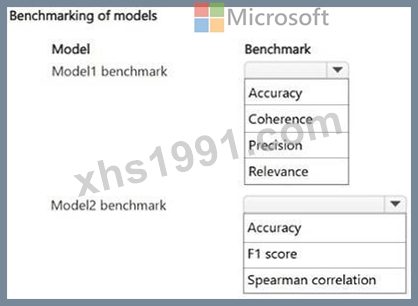
正解:
解説: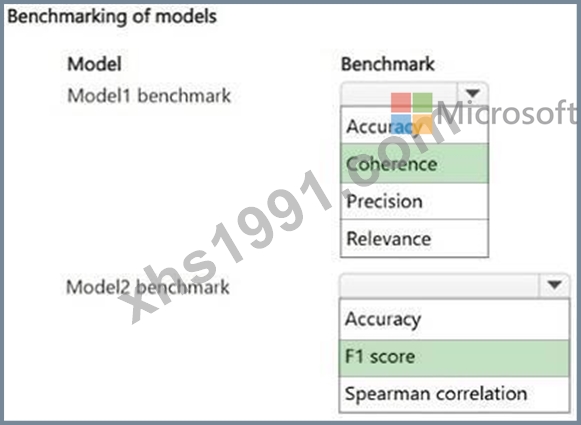
質問 # 171
......
Xhs1991必要な内容を収集してMicrosoft分析し、AI-300トレーニングクイズに記入することで、試験受験者の98%以上が楽かつ効率的に試験に合格しました。 Operationalizing Machine Learning and Generative AI Solutions試験に関連する学習したいすべてのメッセージは、AI-300練習エンジンで見つけることができます。 Operationalizing Machine Learning and Generative AI Solutions環境で行われた変更および次の試験での予測は、それらによって以前にコンパイルされます。
AI-300トレーニング: https://www.xhs1991.com/AI-300.html