P.S. Free & New DP-600 dumps are available on Google Drive shared by Prep4pass: https://drive.google.com/open?id=1kAC5XiJu8Adbl8WPSv_cwf1OM4jdNwG2
When we are in some kind of learning web site, often feel dazzling, because web page design is not reasonable, put too much information all rush, it will appear desultorily. Absorbing the lessons of the DP-600 test prep, will be all kinds of qualification examination classify layout, at the same time on the front page of the DP-600 test materials have clear test module classification, so clear page design greatly convenient for the users, can let users in a very short period of time to find what they want to study, and then targeted to study.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
The Prep4pass is one of the leading platforms that have been offering valid, updated, and real Channel Partner Program DP-600 exam dumps for many years. The Channel Partner Program Implementing Analytics Solutions Using Microsoft Fabric DP-600 Practice Test questions offered by the Prep4pass are designed and verified by experienced Implementing Analytics Solutions Using Microsoft Fabric DP-600 certification exam trainers.
NEW QUESTION # 52
You have a Fabric workspace named Workspace1 that contains a data flow named Dataflow1. Dataflow1 contains a query that returns the data shown in the following exhibit.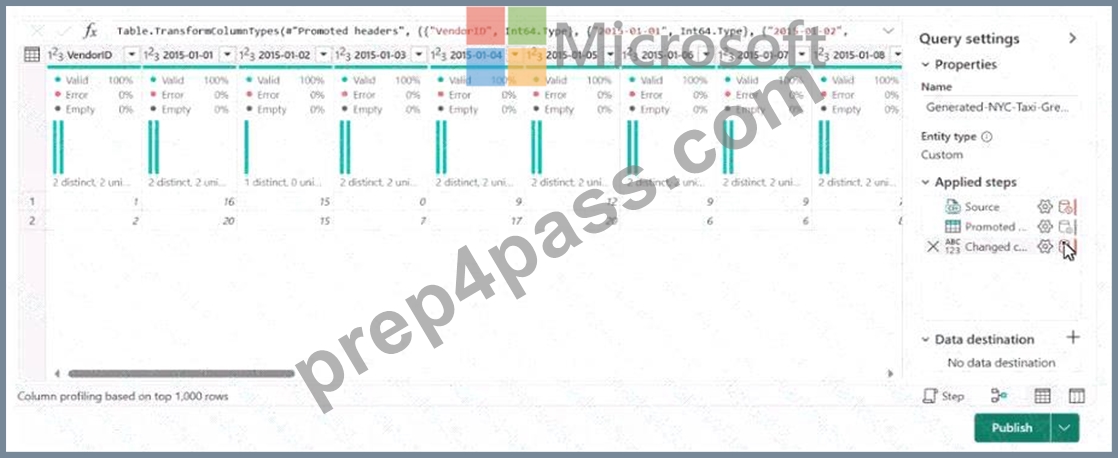
You need to transform the date columns into attribute-value pairs, where columns become rows.
You select the VendorlD column.
Which transformation should you select from the context menu of the VendorlD column?
Answer: B
Explanation:
The transformation you should select from the context menu of the VendorID column to transform the date columns into attribute-value pairs, where columns become rows, is Unpivot columns (B). This transformation will turn the selected columns into rows with two new columns, one for the attribute (the original column names) and one for the value (the data from the cells). References = Techniques for unpivoting columns are covered in the Power Query documentation, which explains how to use the transformation in data modeling.
NEW QUESTION # 53
You have a KQL database that contains a table named Readings.
You need to query Readings and return the results shown in the following table.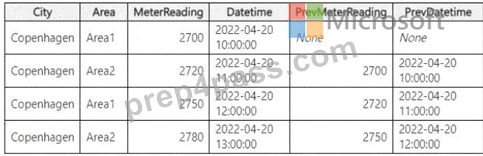
How should you complete the query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.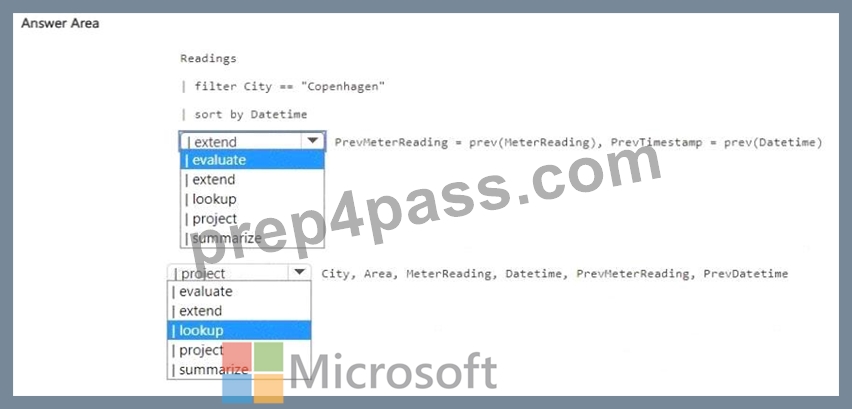
Answer:
Explanation: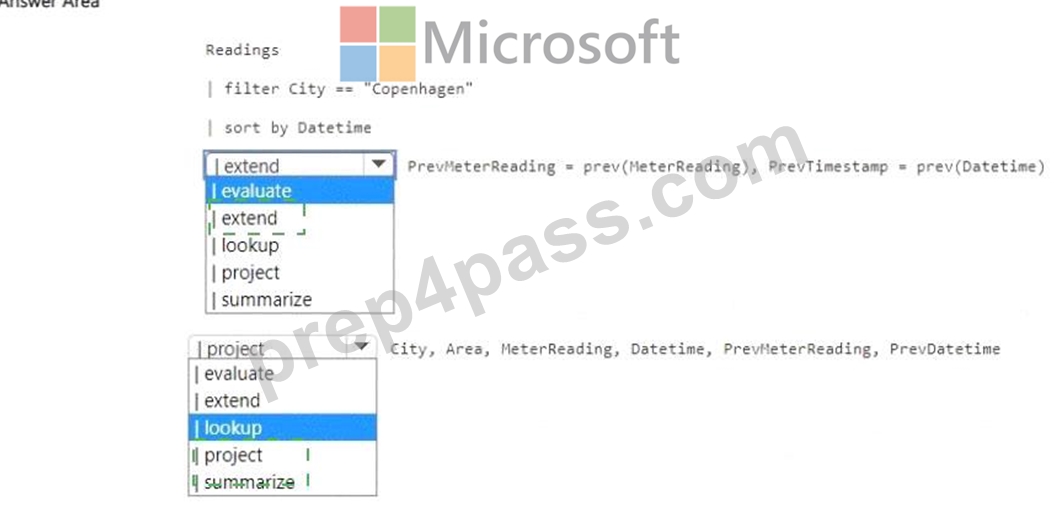
Explanation: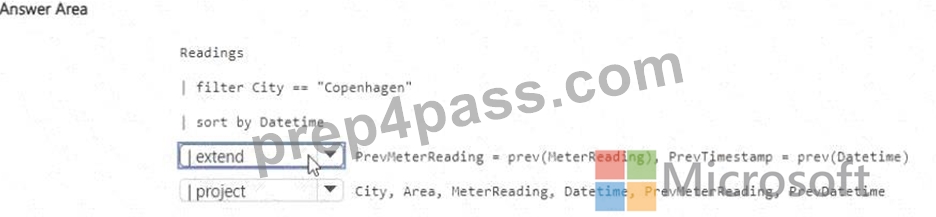
Comprehensive Detailed Explanation
We need to query a KQL database table named Readings to generate output that includes both the current reading and the previous reading values and datetime for each row.
Step 1: Understanding Requirements
The output table shows:
City, Area, MeterReading, Datetime
PrevMeterReading, PrevDatetime
The prev() function in KQL is used to access the value of a column from the previous row (based on order).
Step 2: Query Construction
We start with filtering:
Readings
| where City == " Copenhagen "
| sort by Datetime
To add columns that calculate the previous reading and previous datetime , we use extend :
| extend PrevMeterReading = prev(MeterReading), PrevDatetime = prev(Datetime) extend creates new columns.
prev() pulls the previous row's values.
Finally, we only want specific columns in the output. For this, we use project :
| project City, Area, MeterReading, Datetime, PrevMeterReading, PrevDatetime Step 3: Completed Query Readings
| where City == " Copenhagen "
| sort by Datetime
| extend PrevMeterReading = prev(MeterReading), PrevDatetime = prev(Datetime)
| project City, Area, MeterReading, Datetime, PrevMeterReading, PrevDatetime Why This is Correct extend adds calculated columns.
prev() gives access to the previous row.
project selects only the required columns.
This matches exactly the table shown in the question.
References
Kusto Query Language - extend operator
Kusto Query Language - project operator
prev() function in KQL
NEW QUESTION # 54
You have a Fabric warehouse that contains two tables named DimDate and Trips.
DimDate contains the following fields.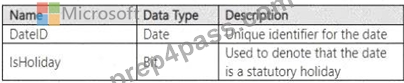
Trips contains the following fields.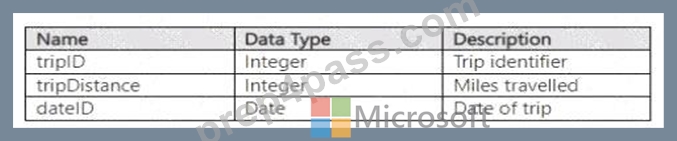
You need to compare the average miles per trip for statutory holidays versus non-statutory holidays.
How should you complete the T-SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.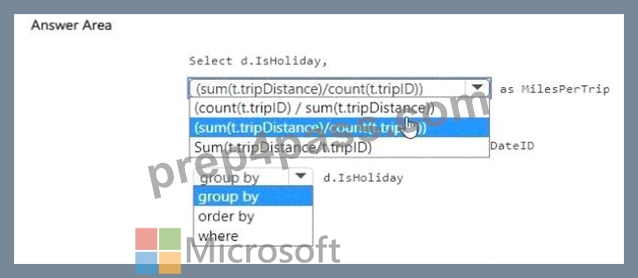
Answer:
Explanation: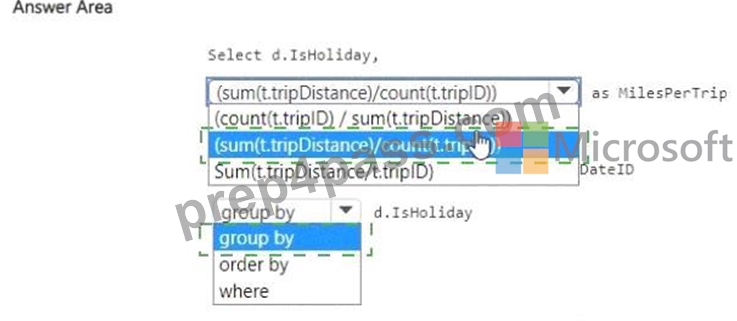
Explanation: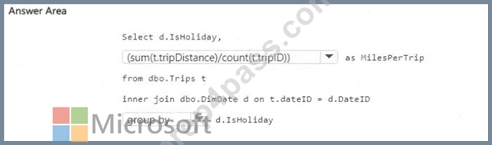
Comprehensive Detailed Explanation
Step 1: Requirement
We need to compare the average miles per trip for:
Statutory holidays (when IsHoliday = 1 )
Non-statutory holidays (when IsHoliday = 0 )
Step 2: Formula for average miles per trip
Average miles per trip = total miles ÷ number of trips
Total miles # SUM(t.tripDistance)
Number of trips # COUNT(t.tripID)
So the calculation is:
( SUM (t.tripDistance) / COUNT (t.tripID)) AS MilesPerTrip
Step 3: Grouping
We need a comparison by holiday status .
So we must group the results by:
GROUP BY d.IsHoliday
This ensures we get two rows: one for IsHoliday = 1 and one for IsHoliday = 0 .
Step 4: Final Query
SELECT
d.IsHoliday,
( SUM (t.tripDistance) / COUNT (t.tripID)) AS MilesPerTrip
FROM DimDate d
INNER JOIN Trips t ON d.DateID = t.DateID
GROUP BY d.IsHoliday;
Why This is Correct
The formula ensures average miles per trip .
Grouping ensures comparison between holidays vs non-holidays .
Efficient aggregation, minimal computation.
References
Aggregate functions in T-SQL
GROUP BY clause
NEW QUESTION # 55
Case Study 1 - Contoso
Overview
Contoso, Ltd. is a US-based health supplements company. Contoso has two divisions named Sales and Research. The Sales division contains two departments named Online Sales and Retail Sales. The Research division assigns internally developed product lines to individual teams of researchers and analysts.
Existing Environment
Identity Environment
Contoso has a Microsoft Entra tenant named contoso.com. The tenant contains two groups named ResearchReviewersGroup1 and ResearchReviewersGroup2.
Data Environment
Contoso has the following data environment:
- The Sales division uses a Microsoft Power BI Premium capacity.
- The semantic model of the Online Sales department includes a fact table named Orders that uses Import made. In the system of origin, the OrderID value represents the sequence in which orders are created.
- The Research department uses an on-premises, third-party data warehousing product.
- Fabric is enabled for contoso.com.
- An Azure Data Lake Storage Gen2 storage account named storage1 contains Research division data for a product line named Productline1. - The data is in the delta format.
- A Data Lake Storage Gen2 storage account named storage2 contains Research division data for a product line named Productline2. The data is in the CSV format.
Requirements
Planned Changes
Contoso plans to make the following changes:
- Enable support for Fabric in the Power BI Premium capacity used by the Sales division.
- Make all the data for the Sales division and the Research division available in Fabric.
- For the Research division, create two Fabric workspaces named Productline1ws and Productine2ws.
- In Productline1ws, create a lakehouse named Lakehouse1.
- In Lakehouse1, create a shortcut to storage1 named ResearchProduct.
Data Analytics Requirements
Contoso identifies the following data analytics requirements:
- All the workspaces for the Sales division and the Research division must support all Fabric experiences.
- The Research division workspaces must use a dedicated, on-demand capacity that has per- minute billing.
- The Research division workspaces must be grouped together logically to support OneLake data hub filtering based on the department name.
- For the Research division workspaces, the members of ResearchReviewersGroup1 must be able to read lakehouse and warehouse data and shortcuts by using SQL endpoints.
- For the Research division workspaces, the members of ResearchReviewersGroup2 must be able to read lakehouse data by using Lakehouse explorer.
- All the semantic models and reports for the Research division must use version control that supports branching.
Data Preparation Requirements
Contoso identifies the following data preparation requirements:
- The Research division data for Productline1 must be retrieved from Lakehouse1 by using Fabric notebooks.
- All the Research division data in the lakehouses must be presented as managed tables in Lakehouse explorer.
Semantic Model Requirements
Contoso identifies the following requirements for implementing and managing semantic models:
- The number of rows added to the Orders table during refreshes must be minimized.
- The semantic models in the Research division workspaces must use Direct Lake mode.
General Requirements
Contoso identifies the following high-level requirements that must be considered for all solutions:
- Follow the principle of least privilege when applicable.
- Minimize implementation and maintenance effort when possible.
You need to refresh the Orders table of the Online Sales department. The solution must meet the semantic model requirements.
What should you include in the solution?
Answer: A
Explanation:
We need to retrieve the maximum OrderID in the destination table to minimize the number of rows added during refresh. this would be an incremental load. can be done with data flows.
NEW QUESTION # 56
You have the following KQL query.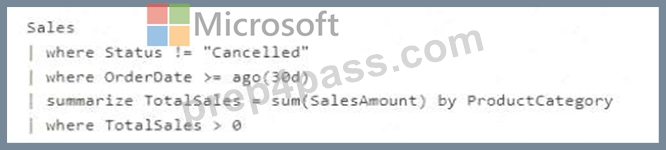
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.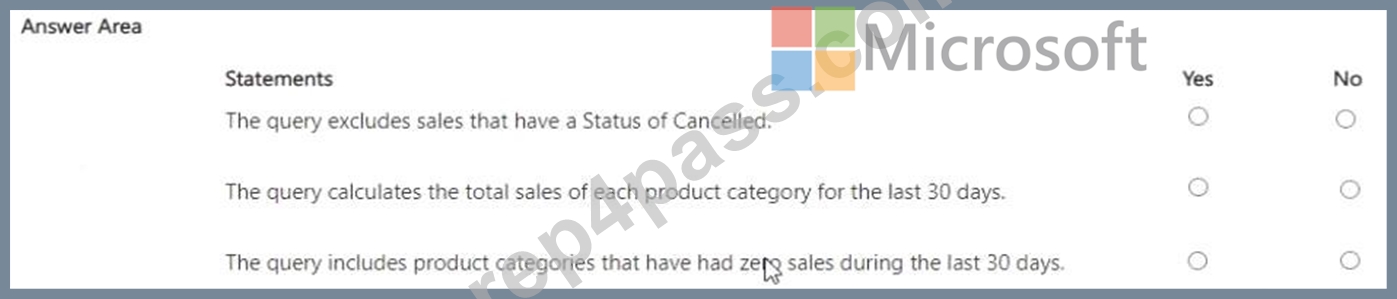
Answer:
Explanation: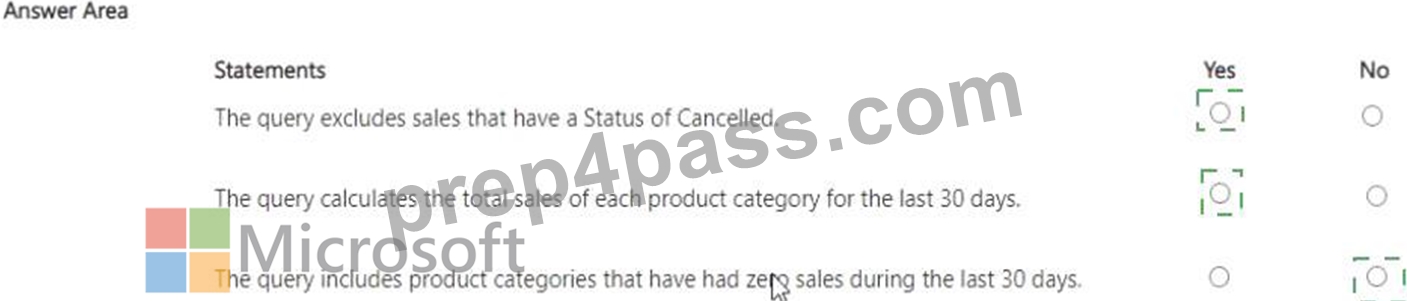
Explanation: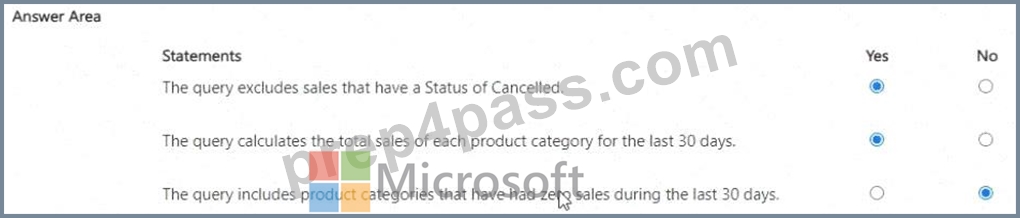
NEW QUESTION # 57
......
If you want to get a higher salary or a promotion on your position, you need to work harder! Purchase our DP-600 learning materials and stick with it. Then your strength will protect you. For as long as you study with our DP-600 exam questions, then you will find that the content of our DP-600 praparation braindumps is all the hot hit of the newest knowledage and keypoints of the subject, you will learn so much to master the skills which will help you solve your problems in your work. And besides, you can achieve the certification for sure with our DP-600 study guide.
DP-600 Reliable Test Preparation: https://www.prep4pass.com/DP-600_exam-braindumps.html
2026 Latest Prep4pass DP-600 PDF Dumps and DP-600 Exam Engine Free Share: https://drive.google.com/open?id=1kAC5XiJu8Adbl8WPSv_cwf1OM4jdNwG2