BTW, DOWNLOAD part of VCEEngine MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1Ahjmv6b9GaqcQny_S8X9c3894fk3gj45
If you visit our website VCEEngine, then you will find that our MLA-C01 practice questions are written in three different versions: PDF version, Soft version and APP version. All types of MLA-C01 training questions are priced favorably on your wishes. Obtaining our MLA-C01 Study Guide in the palm of your hand, you can achieve a higher rate of success. Besides, there are free demos of our MLA-C01 learning guide for your careful consideration to satisfy individual needs.
| Section | Weight | Objectives |
|---|---|---|
| Model Deployment and Inference | 20% | - SageMaker endpoints configuration - Model deployment strategies (real-time, batch) - Model versioning and rollback - Inference optimization (latency, throughput) - A/B testing and shadow mode deployment |
| Data Processing | 22% | - Data validation and quality assessment - Data ingestion and transformation - Data preprocessing and feature engineering - Data pipelining with AWS services ( Glue, Data Brew, etc.) - Handling imbalanced data |
| MLOps and Monitoring | 28% | - Model monitoring and drift detection - Cost optimization for ML workloads - Model lineage and reproducibility - Security and access management for ML - Incident response and remediation - CI/CD pipelines for ML |
| Model Development | 30% | - Algorithm selection and model architecture - Hyperparameter optimization - Training and validation strategies - Transfer learning and fine-tuning - Distributed training - ML frameworks (SageMaker, built-in algorithms) |
>> MLA-C01 Valid Study Guide <<
You can prepare for the AWS Certified Machine Learning Engineer - Associate exam without an internet connection using the offline version of the mock exam. Amazon MLA-C01 practice test not only gives you the opportunity to practice with real exam questions but also provides you with a self-assessment report highlighting your performance in an attempt. VCEEngine keeps an eye on changes in the Amazon AWS Certified Machine Learning Engineer - Associate exam syllabus and updates Amazon MLA-C01 Exam Dumps accordingly to make sure they are relevant to the latest exam topics. After making the payment for Amazon MLA-C01 dumps questions you’ll be able to get free updates for up to 365 days. Another thing you will get from using the MLA-C01 exam study material is free to support. If you encounter any problem while using the MLA-C01 prep material, you have nothing to worry about.
NEW QUESTION # 45
A company is using Amazon SageMaker and millions of files to train an ML model. Each file is several megabytes in size. The files are stored in an Amazon S3 bucket. The company needs to improve training performance.
Which solution will meet these requirements in the LEAST amount of time?
Answer: B
Explanation:
Amazon FSx for Lustre is designed for high-performance workloads like ML training. It provides fast, low- latency access to data by linking directly to the existing S3 bucket and caching frequently accessed files locally. This significantly improves training performance compared to directly accessing millions of files from S3. It requires minimal changes to the training job and avoids the overhead of transferring or restructuring data, making it the fastest and most efficient solution.
NEW QUESTION # 46
A company is building a web-based AI application by using Amazon SageMaker. The application will provide the following capabilities and features: ML experimentation, training, a central model registry, model deployment, and model monitoring.
The application must ensure secure and isolated use of training data during the ML lifecycle. The training data is stored in Amazon S3.
The company needs to run an on-demand workflow to monitor bias drift for models that are deployed to real- time endpoints from the application.
Which action will meet this requirement?
Answer: A
Explanation:
Monitoring bias drift in deployed machine learning models is crucial to ensure fairness and accuracy over time. Amazon SageMaker Clarify provides tools to detect bias in ML models, both during training and after deployment. To monitor bias drift for models deployed to real-time endpoints, an effective approach involves orchestrating SageMaker Clarify jobs using AWS Lambda functions.
Implementation Steps:
* Set Up Data Capture:
* Enable data capture on the SageMaker endpoint to record input data and model predictions. This captured data serves as the basis for bias analysis.
* Develop a Lambda Function:
* Create an AWS Lambda function configured to initiate a SageMaker Clarify job. This function will process the captured data to assess bias metrics.
* Schedule or Trigger the Lambda Function:
* Configure the Lambda function to run on-demand or at scheduled intervals using Amazon CloudWatch Events or EventBridge. This setup allows for regular bias monitoring as per the application's requirements.
* Analyze and Respond to Results:
* After each Clarify job completes, review the generated bias reports. If bias drift is detected, take appropriate actions, such as retraining the model or adjusting data preprocessing steps.
Advantages of This Approach:
* Automation: Utilizing AWS Lambda for orchestrating Clarify jobs enables automated and scalable bias monitoring without manual intervention.
* Cost-Effectiveness: AWS Lambda's serverless nature ensures that you only pay for the compute time consumed during the execution of the function, optimizing resource usage.
* Flexibility: The solution can be tailored to specific monitoring needs, allowing for adjustments in monitoring frequency and analysis parameters.
By implementing this solution, the company can effectively monitor bias drift in real-time, ensuring that the AI application maintains fairness and accuracy throughout its lifecycle.
References:
Bias drift for models in production - Amazon SageMaker
Schedule Bias Drift Monitoring Jobs - Amazon SageMaker
NEW QUESTION # 47
An ML engineer is using a training job to fine-tune a deep learning model in Amazon SageMaker Studio. The ML engineer previously used the same pre-trained model with a similar dataset. The ML engineer expects vanishing gradient, underutilized GPU, and overfitting problems.
The ML engineer needs to implement a solution to detect these issues and to react in predefined ways when the issues occur. The solution also must provide comprehensive real-time metrics during the training.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: A
Explanation:
SageMaker Debugger provides built-in rules to automatically detect issues like vanishing gradients, underutilized GPU, and overfitting during training jobs. It generates real-time metrics and allows users to define predefined actions that are triggered when specific issues occur. This solution minimizes operational overhead by leveraging the managed monitoring capabilities of SageMaker Debugger without requiring custom setups or extensive manual intervention.
NEW QUESTION # 48
Case Study
A company is building a web-based AI application by using Amazon SageMaker. The application will provide the following capabilities and features: ML experimentation, training, a central model registry, model deployment, and model monitoring.
The application must ensure secure and isolated use of training data during the ML lifecycle. The training data is stored in Amazon S3.
The company must implement a manual approval-based workflow to ensure that only approved models can be deployed to production endpoints.
Which solution will meet this requirement?
Answer: A
Explanation:
To implement a manual approval-based workflow ensuring that only approved models are deployed to production endpoints, Amazon SageMaker provides integrated tools such asSageMaker Pipelinesand the SageMaker Model Registry.
SageMaker Pipelinesis a robust service for building, automating, and managing end-to-end machine learning workflows. It facilitates the orchestration of various steps in the ML lifecycle, including data preprocessing, model training, evaluation, and deployment. By integrating with theSageMaker Model Registry, it enables seamless tracking and management of model versions and their approval statuses.
Implementation Steps:
* Define the Pipeline:
* Create a SageMaker Pipeline encompassing steps for data preprocessing, model training, evaluation, and registration of the model in the Model Registry.
* Incorporate aCondition Stepto assess model performance metrics. If the model meets predefined criteria, proceed to the next step; otherwise, halt the process.
* Register the Model:
* Utilize theRegisterModelstep to add the trained model to the Model Registry.
* Set the ModelApprovalStatus parameter to PendingManualApproval during registration. This status indicates that the model awaits manual review before deployment.
* Manual Approval Process:
* Notify the designated approver upon model registration. This can be achieved by integrating Amazon EventBridge to monitor registration events and trigger notifications via AWS Lambda functions.
* The approver reviews the model's performance and, if satisfactory, updates the model's status to Approved using the AWS SDK or through the SageMaker Studio interface.
* Deploy the Approved Model:
* Configure the pipeline to automatically deploy models with an Approved status to the production endpoint. This can be managed by adding deployment steps conditioned on the model's approval status.
Advantages of This Approach:
* Automated Workflow:SageMaker Pipelines streamline the ML workflow, reducing manual interventions and potential errors.
* Governance and Compliance:The manual approval step ensures that only thoroughly evaluated models are deployed, aligning with organizational standards.
* Scalability:The solution supports complex ML workflows, making it adaptable to various project requirements.
By implementing this solution, the company can establish a controlled and efficient process for deploying models, ensuring that only approved versions reach production environments.
References:
* Automate the machine learning model approval process with Amazon SageMaker Model Registry and Amazon SageMaker Pipelines
* Update the Approval Status of a Model - Amazon SageMaker
NEW QUESTION # 49
An ML engineer is working on an ML model to predict the prices of similarly sized homes. The model will base predictions on several features The ML engineer will use the following feature engineering techniques to estimate the prices of the homes:
* Feature splitting
* Logarithmic transformation
* One-hot encoding
* Standardized distribution
Select the correct feature engineering techniques for the following list of features. Each feature engineering technique should be selected one time or not at all (Select three.)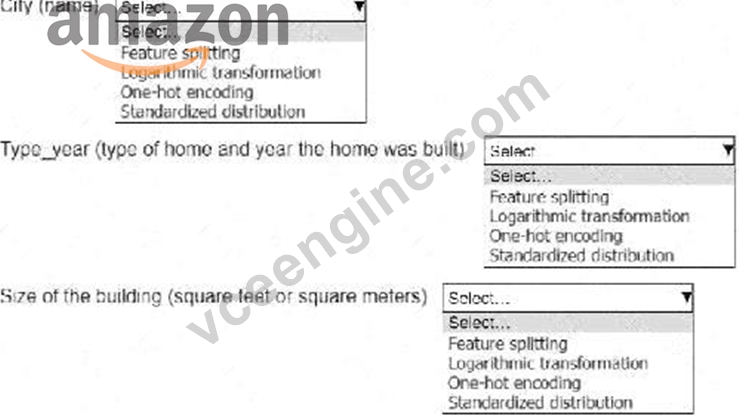
Answer:
Explanation: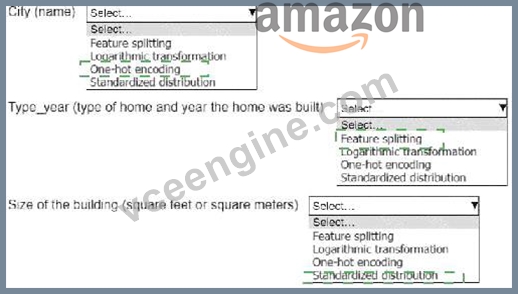
Explanation:
City (name): One-hot encoding
Type_year (type of home and year the home was built): Feature splitting Size of the building (square feet or square meters): Standardized distribution City (name): One-hot encoding Why? The " City " is a categorical feature (non-numeric), so one-hot encoding is used to transform it into a numeric format. This encoding creates binary columns for each unique category (e.g., cities like " New York " or " Los Angeles " ), which the model can interpret.
Type_year (type of home and year the home was built): Feature splitting Why? " Type_year " combines two pieces of information into one column, which could confuse the model.
Feature splitting separates this column into two distinct features: " Type of home " and " Year built, " enabling the model to process each feature independently.
Size of the building (square feet or square meters): Standardized distribution Why? Size is a continuous numerical variable, and standardization (scaling the feature to have a mean of 0 and a standard deviation of 1) ensures that the model treats it fairly compared to other features, avoiding bias from differences in feature scale.
By applying these feature engineering techniques, the ML engineer can ensure that the input data is correctly formatted and optimized for the model to make accurate predictions.
NEW QUESTION # 50
......
Compared with companies that offer a poor level of customer service, our MLA-C01 exam questions have over 98 percent of chance to help you achieve success. Up to now, we have had thousands of letters and various feedbacks from satisfied customers who are all faithful fans of our MLA-C01 Study Guide, and the number of them is keeping growing. So our MLA-C01 practice materials are the clear performance and manifestation of our sincerity. You really should have a try on our MLA-C01 exam dumps!
New MLA-C01 Exam Bootcamp: https://www.vceengine.com/MLA-C01-vce-test-engine.html
2026 Latest VCEEngine MLA-C01 PDF Dumps and MLA-C01 Exam Engine Free Share: https://drive.google.com/open?id=1Ahjmv6b9GaqcQny_S8X9c3894fk3gj45