BONUS!!! Download part of ExamsReviews SPS-C01 dumps for free: https://drive.google.com/open?id=141R9Ssi8hEuUd34S6khiMcp3kgbMMp8T
If you are interested in ExamsReviews's training program about Snowflake certification SPS-C01 exam, you can first on WWW.ExamsReviews.COM to free download part of the exercises and answers about Snowflake Certification SPS-C01 Exam as a free try. We will provide one year free update service for those customers who choose ExamsReviews's products.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark Concepts | 15% | - Transformations vs. Actions - Stored procedures and conditional logic - Snowpark architecture and core concepts - Snowpark Sessions and connection management - Client-side vs. Server-side execution - Snowpark DataFrames and query plans |
| Topic 2: Performance Optimization and Best Practices | 20% | - Minimizing data transfer - Vectorized UDFs - Warehouse sizing for Snowpark - Debugging and explain plans - Caching strategies - Query pushdown and optimization |
| Topic 3: Snowpark API for Python | 30% | - DataFrame creation and manipulation - Establishing connections and session management - Reading and writing data - Working with Semi-structured data - User-Defined Functions (UDFs) and Stored Procedures |
| Topic 4: Data Transformations and DataFrame Operations | 35% | - Persisting transformed data - Complex data pipelines - Window functions - Using built-in functions - Filtering, Aggregating, and Joining DataFrames |
Furthermore, after acquiring our Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 Exam Questions preparation material, you will receive free updates for 365 days. ExamsReviews provides up-to-date Snowflake Certified SnowPro Specialty - Snowpark exam questions, latest test dumps demo and latest test experience will make you success in your career. And price is affordable.
NEW QUESTION # 11
You have a Snowpark DataFrame 'customer df with a 'customer name' column. You need to create a new column 'initials' that contains the initials of each customer's name. For example, if 'customer name' is 'John Doe', 'initials' should be 'JD'. You must handle names with multiple words correctly. Which Snowpark SQL expression using the "col()' function is the most efficient and correct way to define the 'initials' column?





Answer: B
Explanation:
Option D is the most robust and efficient solution. It uses a regular expression to extract the first letter of each word in the name, handling multiple words correctly, and converting it to uppercase. Option A is incorrect because it only handles two-word names and relies on string concatenation, which can be less efficient than using the 'concat function. Option B is incorrect as 'array_accumulate' is not used in Snowpark to compute initials. Option C is incorrect as it is too basic and relies on two-word names only. Option E is incorrect as it extracts only the first two characters from the name.
NEW QUESTION # 12
Consider the following Snowpark code snippet that defines and registers a UDF: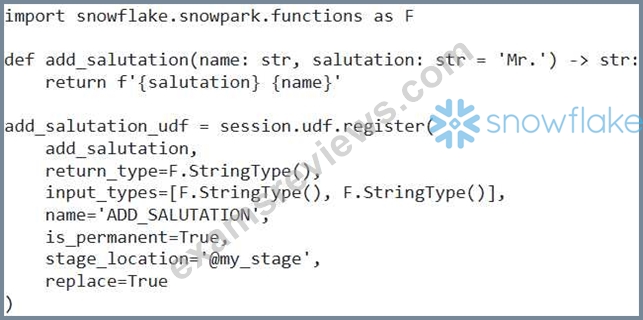
Which of the following statements about this code are TRUE?
Answer: B,C,E
Explanation:
The correct answers are C, D, and E. makes the UDF permanent. 'replace=True' overwrites any existing UDF with the same name. Python's default parameter value IS used in the SQL call if the salutation is omitted. 'input_typeS are not redundant, they are required and Python's type hints are not automatically used. Option A is incorrect because 'is_permanent' is set to true.
NEW QUESTION # 13
You have a Snowpark DataFrame containing sensor data'. You need to write this data to a Snowflake stage 'sensor_stage' , creating a new set of files every hour based on the 'timestamp' column (data type: Timestamp). You also want to ensure that the file names include the hour of the timestamp and are written in Avro format with Zstandard compression. The directory structure on the stage should reflect the hourly partitioning. Which of the following approaches offers the most efficient and scalable way to achieve this, while minimizing the number of files written per hour?
Answer: C
Explanation:
Option A is the most efficient and scalable approach. By creating a new 'hour' column and using 'partitionBy('hour')' , Snowpark will automatically handle the hourly partitioning and create the appropriate directory structure on the stage. The will create new directory if it doesn't exist and write data, 'format('avro')' ensures the data is written as Avro files, and 'option('compression', 'zstd')' enables Zstandard compression. Option B, using a stored procedure with iteration, is less efficient because it requires fetching the data multiple times and performing the filtering within the stored procedure. Option C, writing the file in Scala , requires manage more code and jar file, which is not optimal approach for Snowflake's data storage/processing mechanism. Option D is highly inefficient as it involves retrieving the entire DataFrame into the client's memory and writing each row separately, negating the benefits of Snowpark's distributed processing. Option E creates another object in snowfalke, so that can be avoided.
NEW QUESTION # 14
You are tasked with creating a Snowpark stored procedure to perform complex data transformations using a Pandas DataFrame. You want to optimize the performance of the stored procedure by leveraging Snowpark's distributed execution capabilities. Consider the following code snippet: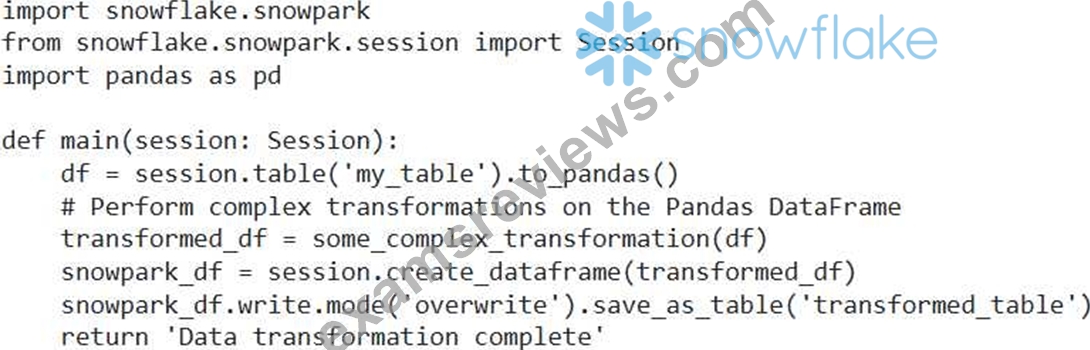
Which of the following changes to the above code will significantly improve the performance by utilizing Snowpark's distributed execution?
Answer: A
Explanation:
Option B provides the most significant performance improvement. Converting the Snowpark DataFrame to a Pandas DataFrame brings all the data to the client-side (where the stored procedure is running), negating the benefits of Snowpark's distributed processing. By performing the transformations directly on the Snowpark DataFrame using Snowpark's built-in functions, the transformations are pushed down to Snowflake's compute engine, allowing for distributed execution. Option A is incorrect as Pandas DataFrames do not leverage Snowpark's distributed processing. Option C 'session.write_pandas' is deprecated, and while it could write to the table, the computations will still happen client-side and not be distributed. Option D introduces complexity and might not be as efficient as Snowpark's native distributed execution, and it does not leverage Snowpark's optimized distributed processing within the Snowflake environment. Limiting the amount of data pulled into pandas is a helpful best practice to minimize data transfer (Option E), however, its not the most efficient. Therefore, the option that would make the largest improvement would be Option B.
NEW QUESTION # 15
A data science team wants to operationalize a Snowpark Python UDF that performs sentiment analysis on customer reviews. The UDF, 'analyze sentiment(review_text)', is currently defined within a Snowpark session. Which of the following approaches is the MOST efficient and scalable way to deploy this UDF for real-time scoring of incoming review data in a Snowflake table named 'CUSTOMER REVIEWS'?
Answer: B
Explanation:
Registering the UDF as a persistent UDF in Snowflake allows it to be called directly from SQL, leveraging Snowflake's query engine for optimal performance and scalability. Option A keeps the transformation entirely within Snowpark, which is a valid approach, but less scalable. Option C involves converting to a Pandas DataFrame, which moves data outside of Snowflake and negates its benefits. Option D creates a stored procedure that is correct but the question ask to perform in real time so it's not ideal. Option E is not the way to persist Snowpark with UDF.
NEW QUESTION # 16
......
Nowadays a lot of people start to attach importance to the demo of the study materials, because many people do not know whether the SPS-C01 study materials they want to buy are useful for them or not, so providing the demo of the study materials for all people is very important for all customers. A lot of can have a good chance to learn more about the SPS-C01 Study Materials that they hope to buy.
SPS-C01 Dumps: https://www.examsreviews.com/SPS-C01-pass4sure-exam-review.html
2026 Latest ExamsReviews SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=141R9Ssi8hEuUd34S6khiMcp3kgbMMp8T