Die Produkte von ExamFragen wird Ihnen nicht nur helfen, die Microsoft AI-300 Zertifizierungsprüfung erfolgreich zu bestehen, sondern auch Ihnen einen einjährigen kostenlosen Update-Service bieten. Wir werden den Kunden die neuesten von uns entwickelten Produkte in der ersten Zeit liefern, so dass Sie sich gut auf die Microsoft AI-300 Prüfung vorbereiten können. Falls Sie in der Microsoft AI-300 Prüfung durchfallen, zahlen wir Ihnen dann die gesammte Summe zurück.
| Section | Objectives |
|---|---|
| Topic 1: Design and implement a GenAIOps infrastructure | - Configure prompt orchestration, prompt flows, and agent frameworks - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Manage API keys, rate limits, and responsible AI guardrails - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search |
| Topic 2: Optimize generative AI systems and model performance | - Tune prompts, system messages, and grounding strategies - Implement cost management and scaling strategies for GenAI workloads - Optimize inference performance, caching, and throughput - Fine-tune and distill models for specific use cases |
| Topic 3: Design and implement an MLOps infrastructure | - Manage environments, data stores, and model registries - Set up Azure Machine Learning workspace and compute targets - Configure source control, CI/CD pipelines, and automation for ML workflows - Implement security, governance, and compliance for MLOps |
| Topic 4: Implement machine learning model lifecycle and operations | - Deploy models to real-time and batch endpoints - Train, register, and version models using Azure Machine Learning - Retrain, update, and manage model versions in production - Monitor model performance, data drift, and operational health |
| Topic 5: Implement generative AI quality assurance and observability | - Evaluate generative AI outputs for quality, safety, and grounding - Monitor latency, token usage, cost, and error rates - Implement logging, tracing, and telemetry for GenAI applications - Conduct red teaming, adversarial testing, and content filtering |
>> AI-300 Pruefungssimulationen <<
Nur kontinuierlich zu verbessern kann man immer an der führenden Stelle stehen. Und es ist auch unsere Firmenphilosophie. Deshalb prüfen wir regelmäßig nach, ob die Microsoft AI-300 Prüfung aktualisiert hat. Wenn sie aktualisiert hat, informieren wir unsere Kunden sofort darüber. Dadurch lassen Sie die neueste Informationen über Microsoft AI-300 Prüfung erfahren. Aller Kundendienst der Aktualisierung nach der Kauf der Microsoft AI-300 Software ist kostenlos innerhalb einem Jahr.
89. Frage
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You train and register an Azure Machine Learning model.
You plan to deploy the model to an online endpoint.
You need to ensure that applications will be able to use the authentication method with a non-expiring artifact to access the model.
Solution:
Create a managed online endpoint and set the value of its auto_mode parameter to key. Deploy the model to the inline endpoint.
Does the solution meet the goal?
Antwort: A
90. Frage
An Azure Machine Learning workspace processes sensitive training data.
The workspace must NOT be accessible from the public internet.
You need to restrict network access.
Which configuration should you implement?
Antwort: B
Begründung:
Azure Private Endpoints are network interfaces that connect your Azure ML workspace to your Virtual Network using a private IP address from the VNet ' s address space. Once a private endpoint is created and DNS is configured, all traffic to the workspace - including the Studio UI, REST API, and SDK calls - travels entirely over Microsoft ' s private backbone rather than the public internet. The workspace ' s public endpoint can then be completely disabled. Azure Firewall (option A) filters traffic at the network layer but still requires the workspace to have a public IP. Network Security Groups (option C) control traffic within VNets but cannot block the public endpoint of a PaaS service. Service endpoints (option D) keep traffic on the Azure backbone but the workspace still has a public-facing address. Private endpoints are the only option that fully removes the public network presence.
Microsoft Learn Reference Topic: Configure a private endpoint for Azure Machine Learning workspace
91. Frage
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You manage a Retrieval-Augmented Generation (RAG) application built on Microsoft Foundry.
The application retrieves documents from an indexed knowledge base and generates answers for internal users.
Recent feedback indicates that answers are fluent but sometimes include information that is not supported by the documents that were retrieved.
You need to evaluate whether a proposed change improves RAG answer quality by using supported and measurable techniques.
Solution: Measure token throughput and average response latency before and after applying the proposed change.
Does the solution meet the goal?
Antwort: A
Begründung:
Correct:
* Review user feedback comments collected after deployment to determine whether answers appear more accurate.
Relying solely on user feedback comments is not the proper immediate action for evaluating this specific issue but it is still the best choice.
Evaluate whether your proposed change improves the Retrieval-Augmented Generation (RAG) system by reducing hallucinations (unsupported information), you need to measure faithfulness and context relevance using automated, quantifiable metrics.
The proper course of action is to implement an LLM-as-a-Judge framework using an open-source evaluation library like Ragas or TruLens.
Recommended Evaluation Plan
Establish a baseline: Run your current RAG pipeline through a test dataset of 50-100 representative user queries.
Capture the outputs: Save the user query, the exact retrieved document snippets, and the generated response for every test.
Apply the change: Deploy your proposed modification (e.g., altered prompt, different temperature, or re-ranking algorithm).Run the evaluation: Pass the test dataset through the updated pipeline to generate a new set of responses.
Compare the metrics: Use the framework to score both sets of data and mathematically verify if the change reduced unsupported claims.
Incorrect:
* Compare embedding vector dimensions used by the retrieval pipeline before and after the change.
Comparing embedding vector dimensions is not a valid or effective method for measuring RAG answer quality. Vector dimensions (e.g., 1536 or 3072) are static architectural properties of your embedding model. They do not reflect factual accuracy, semantic grounding, or the rate of hallucinations in your text generation.
* Measure token throughput and average response latency before and after applying the proposed change.
Measuring token throughput and latency is not the correct action to solve this specific problem.
Reference:
https://www.getmaxim.ai/articles/how-to-evaluate-your-rag-system/
92. Frage
A company is creating an internal tool that summarizes long meeting transcripts and extracts action items.
The model must:
Process text inputs up to 200k tokens long.
Generate concise summaries in seconds.
Support interactive testing before integration into the app.
You need to select, deploy, and test a model that supports summarization with low latency.
How should you complete the configuration plan? To answer, select the appropriate options in the answer area . NOTE: Each correct selection is worth one point.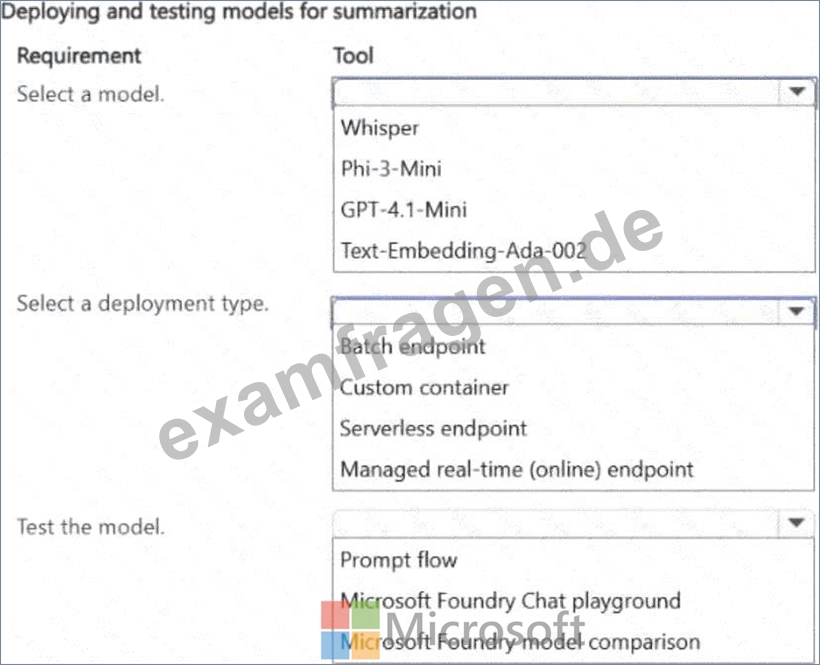
Antwort:
Begründung: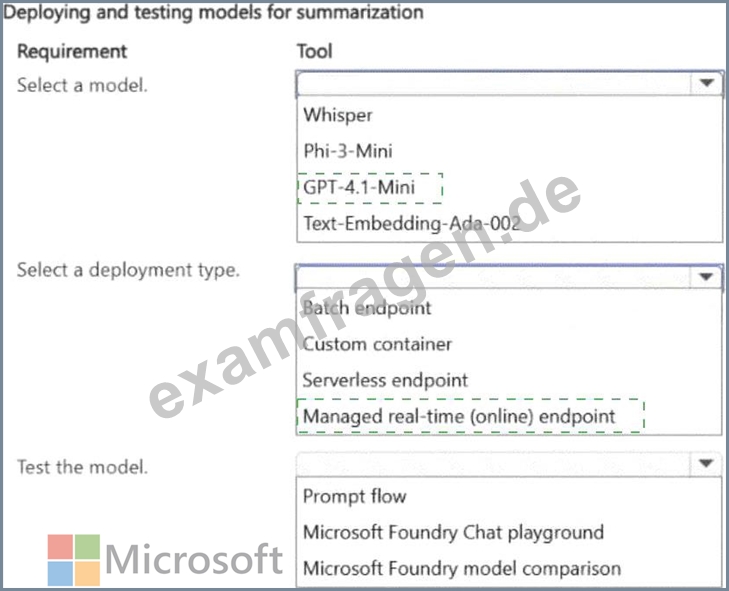
Explanation:
For a tool that must process text inputs up to 200k tokens long, generate concise summaries in seconds, and support interactive testing, the configuration must address three requirements. The large token context window points to GPT-4o, which supports up to 128k tokens and is among the largest-context Azure OpenAI models available in Foundry, making it suitable for long documents such as meeting transcripts. Low latency with the need to generate responses in seconds rules out batch deployment types; Data Zone Standard provides the best latency for single-tenant enterprise use cases with zone-level routing. Interactive testing before integration points directly to Microsoft Foundry ' s built-in Chat Playground or Prompt Playground, where you can paste transcripts, adjust system prompts, and evaluate outputs interactively before writing any application integration code.
Microsoft Learn Reference Topic: Deploy and test models in Microsoft Foundry - Model selection for long- context summarization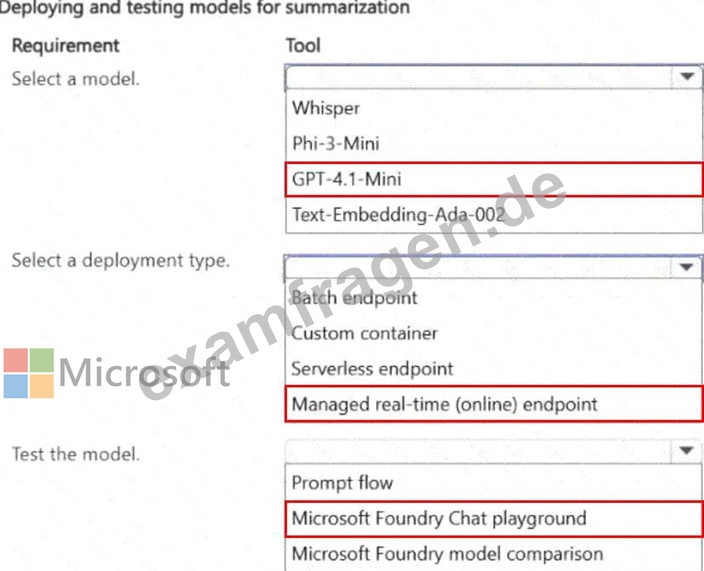
93. Frage
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You manage a Retrieval-Augmented Generation (RAG) application built on Microsoft Foundry.
The application retrieves documents from an indexed knowledge base and generates answers for internal users.
Recent feedback indicates that answers are fluent but sometimes include information that is not supported by the documents that were retrieved.
You need to evaluate whether a proposed change improves RAG answer quality by using supported and measurable techniques.
Solution: Compare embedding vector dimensions used by the retrieval pipeline before and after the change.
Does the solution meet the goal?
Antwort: A
Begründung:
Correct:
* Review user feedback comments collected after deployment to determine whether answers appear more accurate.
Relying solely on user feedback comments is not the proper immediate action for evaluating this specific issue but it is still the best choice.
Evaluate whether your proposed change improves the Retrieval-Augmented Generation (RAG) system by reducing hallucinations (unsupported information), you need to measure faithfulness and context relevance using automated, quantifiable metrics.
The proper course of action is to implement an LLM-as-a-Judge framework using an open-source evaluation library like Ragas or TruLens.
Recommended Evaluation Plan
Establish a baseline: Run your current RAG pipeline through a test dataset of 50-100 representative user queries.
Capture the outputs: Save the user query, the exact retrieved document snippets, and the generated response for every test.
Apply the change: Deploy your proposed modification (e.g., altered prompt, different temperature, or re-ranking algorithm).Run the evaluation: Pass the test dataset through the updated pipeline to generate a new set of responses.
Compare the metrics: Use the framework to score both sets of data and mathematically verify if the change reduced unsupported claims.
Incorrect:
* Compare embedding vector dimensions used by the retrieval pipeline before and after the change.
Comparing embedding vector dimensions is not a valid or effective method for measuring RAG answer quality. Vector dimensions (e.g., 1536 or 3072) are static architectural properties of your embedding model. They do not reflect factual accuracy, semantic grounding, or the rate of hallucinations in your text generation.
* Measure token throughput and average response latency before and after applying the proposed change.
Measuring token throughput and latency is not the correct action to solve this specific problem.
Reference:
https://www.getmaxim.ai/articles/how-to-evaluate-your-rag-system/
94. Frage
......
Sie können im Internet kostenlos die Software und Prüfungsfragen und Antworten zur Microsoft AI-300 Zertifizierungsprüfung als Probe herunterladen. ExamFragen wird Ihnen helfen, die Microsoft AI-300 Zertifizierungsprüfung zu bestehen. Wenn Sie unvorsichtigerweise in der Prüfung durchfallen, erstatten wir Ihnen Ihre an uns geleistene Zahlung.
AI-300 Zertifizierungsantworten: https://www.examfragen.de/AI-300-pruefung-fragen.html