BTW, DOWNLOAD part of TroytecDumps Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1Nxw-ePY5J8NgTfKkWCsRV8cwpYwyuyVi
Our Databricks-Generative-AI-Engineer-Associate learning materials were developed based on this market demand. More and more people are aware of the importance of obtaining a certificate. There are more and more users of Databricks-Generative-AI-Engineer-Associate practice guide. Our products can do so well, the most important thing is that the quality of Databricks-Generative-AI-Engineer-Associateexam questions is very good, and can be continuously improved according to market demand. And you can look at the data on our website, the hot hit of our Databricks-Generative-AI-Engineer-Associate training guide can prove how popular it is!
| Section | Weight | Objectives |
|---|---|---|
| Design Applications | 14% | - Design solution architecture - Select appropriate models, tools and approaches - Decompose complex requirements into tasks |
| Assembling and Deploying Apps | 22% | - Deploy models via Model Serving - Package and deploy applications - Manage application lifecycle |
| Data Preparation | 14% | - Manage data quality and format - Prepare and process data for LLM use - Implement data pipelines and transformations |
| Evaluation and Monitoring | 12% | - Monitor application behavior and outputs - Iterate and improve solutions - Evaluate model and application performance |
| Governance | 8% | - Ensure compliance and security - Apply Unity Catalog for data governance - Manage access and permissions |
| Application Development | 30% | - Develop LLM chains and workflows - Build RAG applications - Use Databricks Vector Search - Integrate with MLflow |
>> Test Databricks-Generative-AI-Engineer-Associate Dumps Free <<
TroytecDumps not only provides you with the best Databricks practice exam materials, but also with the most comprehensive service. If you buy our Databricks-Generative-AI-Engineer-Associate exam questions and answers, you can get the right of free update exam pdf one-year. And you can try the free demo of our braindumps before you decide to buy. You will pass Databricks-Generative-AI-Engineer-Associate Exam Tests with the help of our latest learning materials and top questions.
NEW QUESTION # 91
A Generative Al Engineer is tasked with developing an application that is based on an open source large language model (LLM). They need a foundation LLM with a large context window.
Which model fits this need?
Answer: C
Explanation:
* Problem Context: The engineer needs an open-source LLM with a large context window to develop an application.
* Explanation of Options:
* Option A: DistilBERT: While an efficient and smaller version of BERT, DistilBERT does not provide a particularly large context window.
* Option B: MPT-30B: This model, while large, is not specified as being particularly notable for its context window capabilities.
* Option C: Llama2-70B: Known for its large model size and extensive capabilities, including a large context window. It is also available as an open-source model, making it ideal for applications requiring extensive contextual understanding.
* Option D: DBRX: This is not a recognized standard model in the context of large language models with extensive context windows.
Thus,Option C(Llama2-70B) is the best fit as it meets the criteria of having a large context window and being available for open-source use, suitable for developing robust language understanding applications.
NEW QUESTION # 92
A company has a typical RAG-enabled, customer-facing chatbot on its website.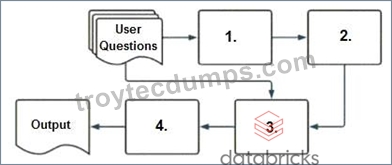
Select the correct sequence of components a user ' s questions will go through before the final output is returned. Use the diagram above for reference.
Answer: A
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user ' s question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1) : The first step involves the user ' s question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2) : The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3) : The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4) : Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable :
* B, C, D : These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence is embedding model, vector search, context-augmented prompt, response- generating LLM , which is option A.
NEW QUESTION # 93
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: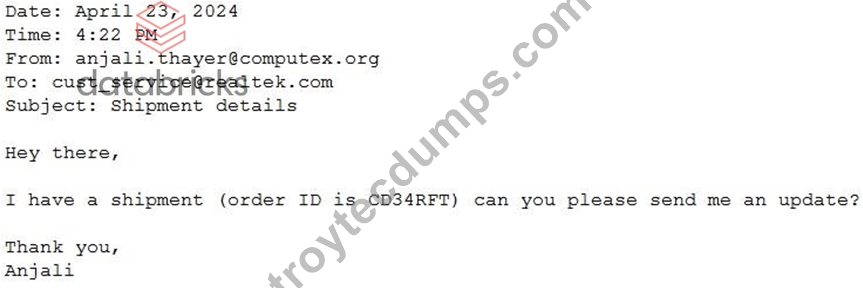
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Answer: B
Explanation:
* Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM's responses.
* Explanation of Options:
Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore, Option B is optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
NEW QUESTION # 94
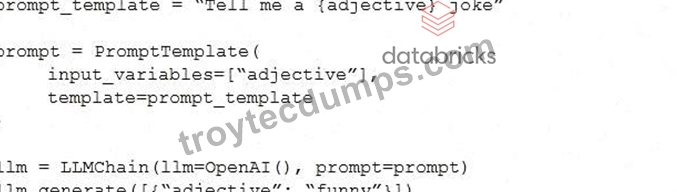
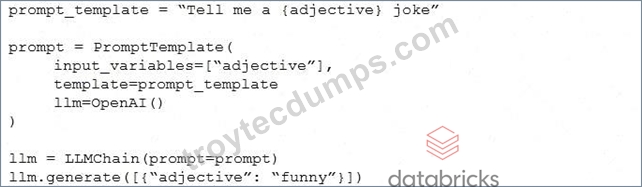
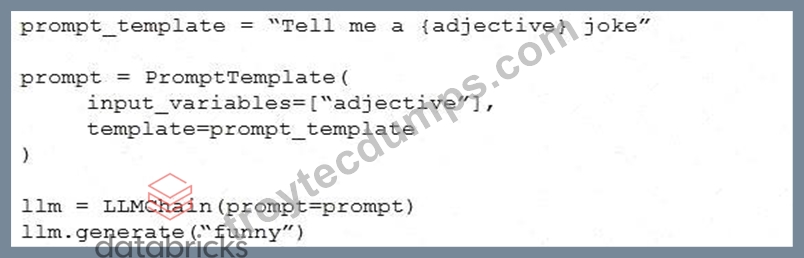
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.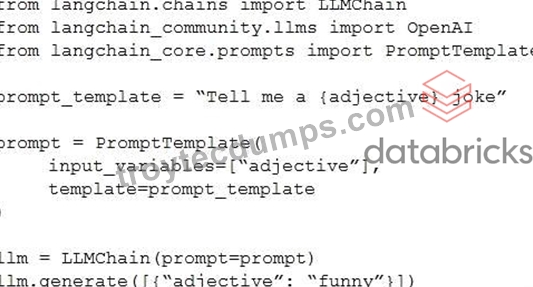
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
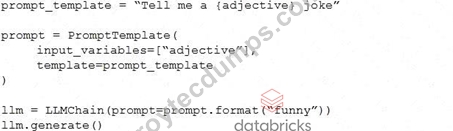
Answer: C
Explanation:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods:
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
* Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
* Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
* Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 95
A Generative Al Engineer is setting up a Databricks Vector Search that will lookup news articles by topic within 10 days of the date specified An example query might be "Tell me about monster truck news around January 5th 1992". They want to do this with the least amount of effort.
How can they set up their Vector Search index to support this use case?
Answer: B
Explanation:
The task is to set up a Databricks Vector Search index for news articles, supporting queries like "monster truck news around January 5th, 1992," with minimal effort. The index must filter by topic and a 10-day date range. Let's evaluate the options.
* Option A: Split articles by 10-day blocks and return the block closest to the query
* Pre-splitting articles into 10-day blocks requires significant preprocessing and index management (e.g., one index per block). It's effort-intensive and inflexible for dynamic date ranges.
* Databricks Reference:"Static partitioning increases setup complexity; metadata filtering is preferred"("Databricks Vector Search Documentation").
* Option B: Include metadata columns for article date and topic to support metadata filtering
* Adding date and topic as metadata in the Vector Search index allows dynamic filtering (e.g., date
± 5 days, topic = "monster truck") at query time. This leverages Databricks' built-in metadata filtering, minimizing setup effort.
* Databricks Reference:"Vector Search supports metadata filtering on columns like date or category for precise retrieval with minimal preprocessing"("Vector Search Guide," 2023).
* Option C: Pass the query directly to the vector search index and return the best articles
* Passing the full query (e.g., "Tell me about monster truck news around January 5th, 1992") to Vector Search relies solely on embeddings, ignoring structured filtering for date and topic. This risks inaccurate results without explicit range logic.
* Databricks Reference:"Pure vector similarity may not handle temporal or categorical constraints effectively"("Building LLM Applications with Databricks").
* Option D: Create separate indexes by topic and add a classifier model to appropriately pick the best index
* Separate indexes per topic plus a classifier model adds significant complexity (index creation, model training, maintenance), far exceeding "least effort." It's overkill for this use case.
* Databricks Reference:"Multiple indexes increase overhead; single-index with metadata is simpler"("Databricks Vector Search Documentation").
Conclusion: Option B is the simplest and most effective solution, using metadata filtering in a single Vector Search index to handle date ranges and topics, aligning with Databricks' emphasis on efficient, low-effort setups.
NEW QUESTION # 96
......
Passing the Databricks-Generative-AI-Engineer-Associate exam rests squarely on the knowledge of exam questions and exam skills. Our Databricks-Generative-AI-Engineer-Associate training quiz has bountiful content that can fulfill your aims at the same time. We know high efficient Databricks-Generative-AI-Engineer-Associate practice materials play crucial roles in your review. Our experts also collect with the newest contents of Databricks-Generative-AI-Engineer-Associate Study Guide and have been researching where the exam trend is heading and what it really want to examine you.
Databricks-Generative-AI-Engineer-Associate Exam Question: https://www.troytecdumps.com/Databricks-Generative-AI-Engineer-Associate-troytec-exam-dumps.html
P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by TroytecDumps: https://drive.google.com/open?id=1Nxw-ePY5J8NgTfKkWCsRV8cwpYwyuyVi