P.S.CertJukenがGoogle Driveで共有している無料の2026 Microsoft DP-100ダンプ:https://drive.google.com/open?id=13Jes_3saikw5lXDJaTLnS4Q5QtwIYimd
インターネットで信頼できる試験コレクション資料を検索して私たちを見つけた場合、実際には、DP-100認定試験に最適な製品が見つかりました。 DP-100試験の合格率が高いことで有名です。そのため、多くの古いお客様がDP-100試験に参加する前に私たちを信頼して直接選択しています。購入する前に、ダウンロード用の無料のPDFデモを提供して、製品の品質をより深く知ることができ、想像力に応えるだけでなく、DP-100学習ガイドを明確に購入できるようにします。
DP-100 認定試験は、Microsoft のデータと AI 認定トラックの一部であり、データサイエンティストがキャリアを進めるために重要なステップです。データの準備、モデルのトレーニングと展開、および機械学習アルゴリズムなど、さまざまなトピックをカバーしています。また、候補者は、Azure Machine Learning、Azure Databricks、および Azure SQL Database などの Azure サービスでの実務経験を持つ必要があります。
多くの人がDP-100試験を非常に重視する必要があります。また、試験に合格することは多くの人にとって簡単なことではないこともわかっています。そのため、多くの人にとって優れた学習方法は非常に重要です。さらに、適切な学習ツールも同様に重要です。DP-100リファレンスガイドは、リラックスした状態で試験に合格するのに役立ちます。弊社からDP-100認定試験ガイド資料をご紹介します。 DP-100学習教材は、DP-100試験に合格するのに非常に有用で役立つと考えています。
DP-100試験は、データサイエンスの概念を理解し、Azureサービスでの実践的な経験が必要な難しい認定試験です。しかし、この試験に合格することでデータサイエンス分野の専門家にとって多くのキャリアチャンスが開かれます。合格者は、Azure上でのデータサイエンスソリューションの設計と実装の専門知識を証明できるため、今日の求人市場で非常に求められるスキルとなります。
質問 # 138
Hotspot Question
You create an Azure Machine Learning workspace. You use the Azure Machine Learning Python SDK v2 to create a compute cluster.
The compute cluster must run a training script. Costs associated with running the training script must be minimized.
You need to complete the Python script to create the compute cluster.
How should you complete the script? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.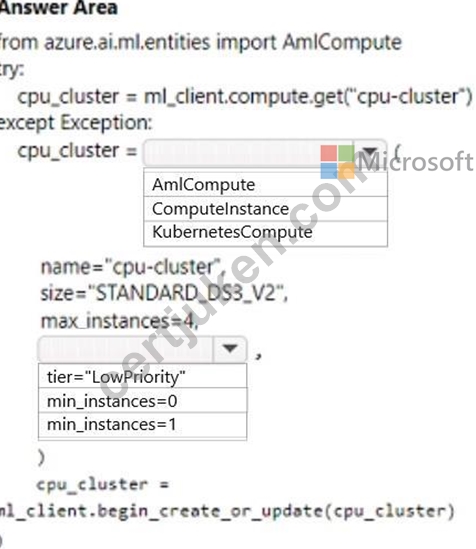
正解:
解説: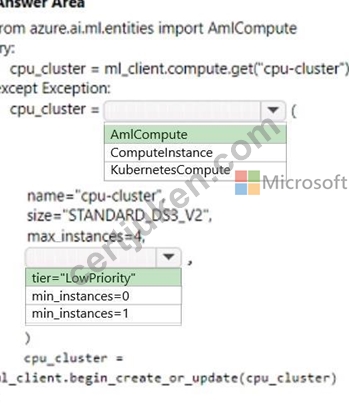
質問 # 139
You have a Python data frame named salesData in the following format: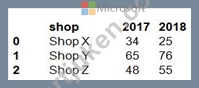
The data frame must be unpivoted to a long data format as follows: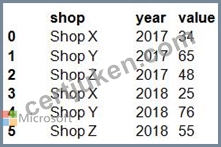
You need to use the pandas.melt() function in Python to perform the transformation.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.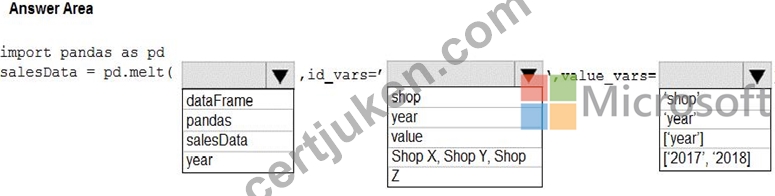
正解:
解説: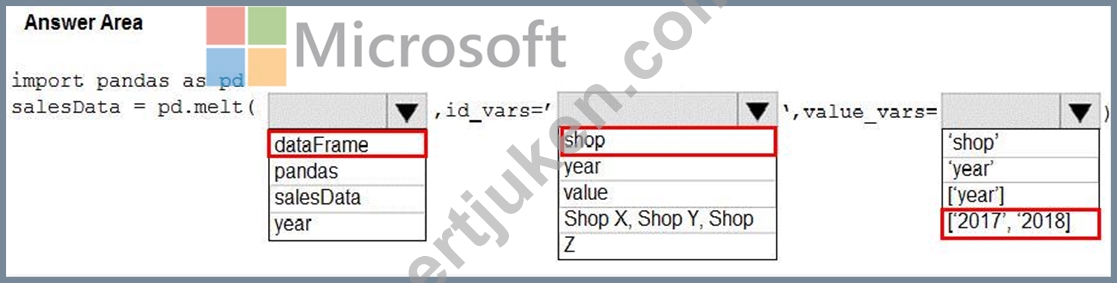
Explanation:
Box 1: dataFrame
Syntax: pandas.melt(frame, id_vars=None, value_vars=None, var_name=None, value_name='value', col_level=None)[source] Where frame is a DataFrame Box 2: shop Paramter id_vars id_vars : tuple, list, or ndarray, optional Column(s) to use as identifier variables.
Box 3: ['2017','2018']
value_vars : tuple, list, or ndarray, optional
Column(s) to unpivot. If not specified, uses all columns that are not set as id_vars.
Example:
df = pd.DataFrame({'A': {0: 'a', 1: 'b', 2: 'c'},
... 'B': {0: 1, 1: 3, 2: 5},
... 'C': {0: 2, 1: 4, 2: 6}})
pd.melt(df, id_vars=['A'], value_vars=['B', 'C'])
A variable value
0 a B 1
1 b B 3
2 c B 5
3 a C 2
4 b C 4
5 c C 6
References:
https://pandas.pydata.org/pandas-docs/stable/reference/api/pandas.melt.html
質問 # 140
You write code to retrieve an experiment that is run from your Azure Machine Learning workspace.
The run used the model interpretation support in Azure Machine Learning to generate and upload a model explanation.
Business managers in your organization want to see the importance of the features in the model.
You need to print out the model features and their relative importance in an output that looks similar to the following.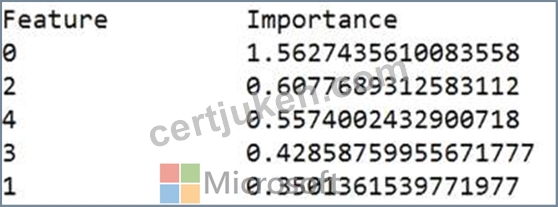
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.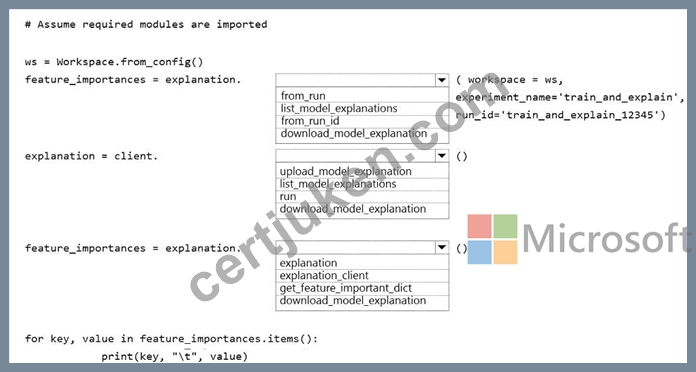
正解:
解説: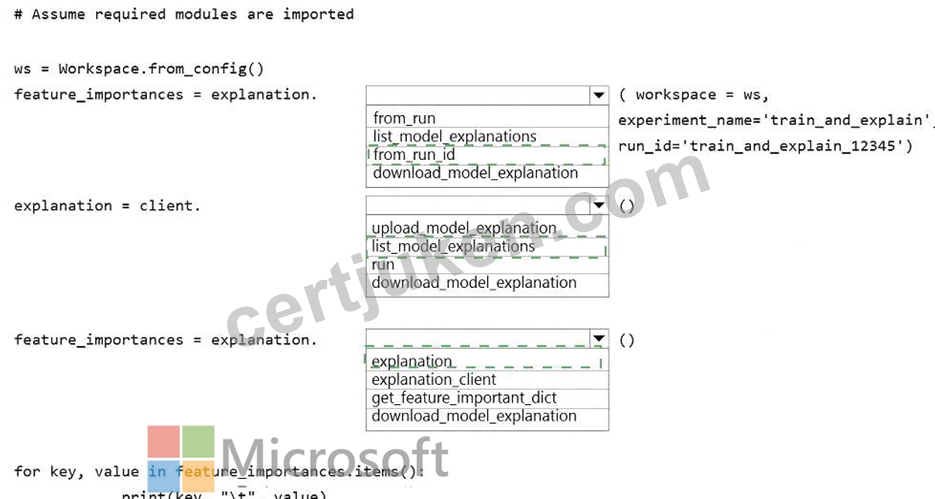
Explanation: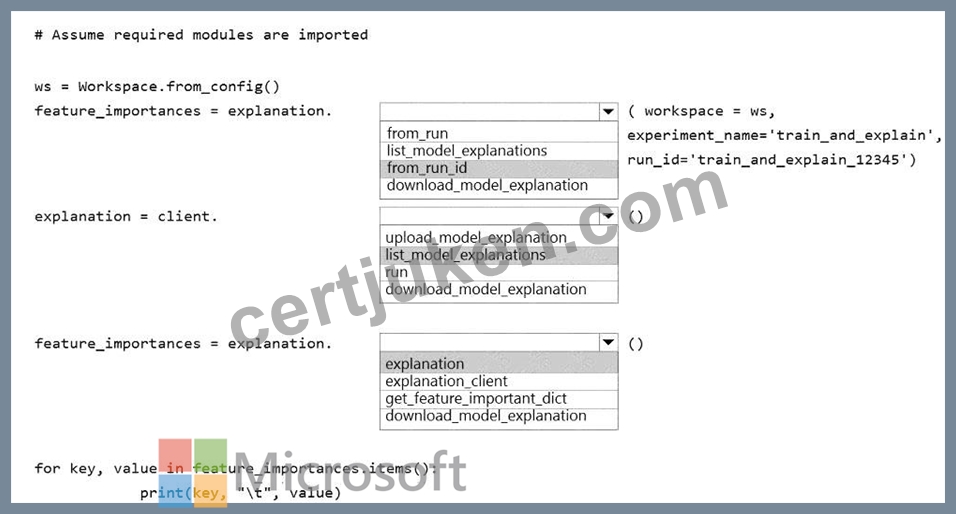
Box 1: from_run_id
from_run_id(workspace, experiment_name, run_id)
Create the client with factory method given a run ID.
Returns an instance of the ExplanationClient.
Parameters
Workspace Workspace An object that represents a workspace.
experiment_name str The name of an experiment.
run_id str A GUID that represents a run.
Box 2: list_model_explanations
list_model_explanations returns a dictionary of metadata for all model explanations available.
Returns
A dictionary of explanation metadata such as id, data type, explanation method, model type, and upload time, sorted by upload time Box 3: explanation Reference:
https://docs.microsoft.com/en-us/python/api/azureml-contrib-interpret/azureml.contrib.interpret.explanation.
explanation_client.explanationclient?view=azure-ml-py
質問 # 141
You manage an Azure Machine Learning workspace.
You must define the execution environments for your jobs and encapsulate the dependencies for your code.
You need to configure the environment from a Docker build context.
How should you complete the rode segment? To answer, select the appropriate option in the answer area.
NOTE: Each correct selection is worth one point.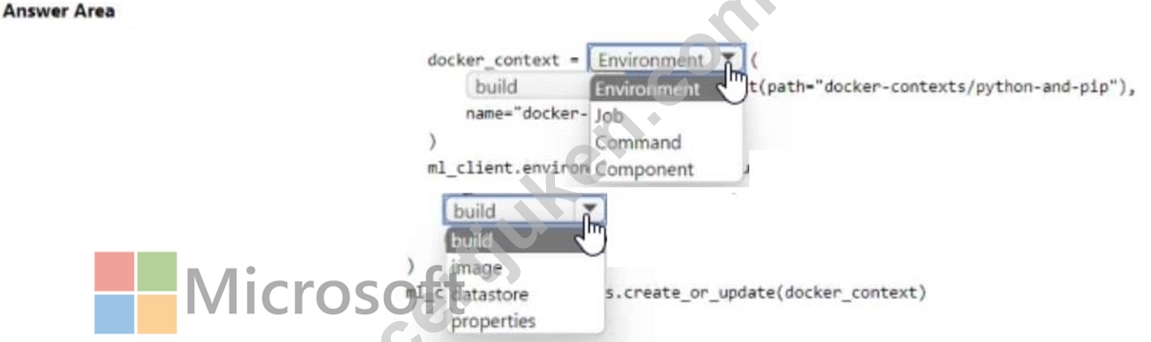
正解:
解説: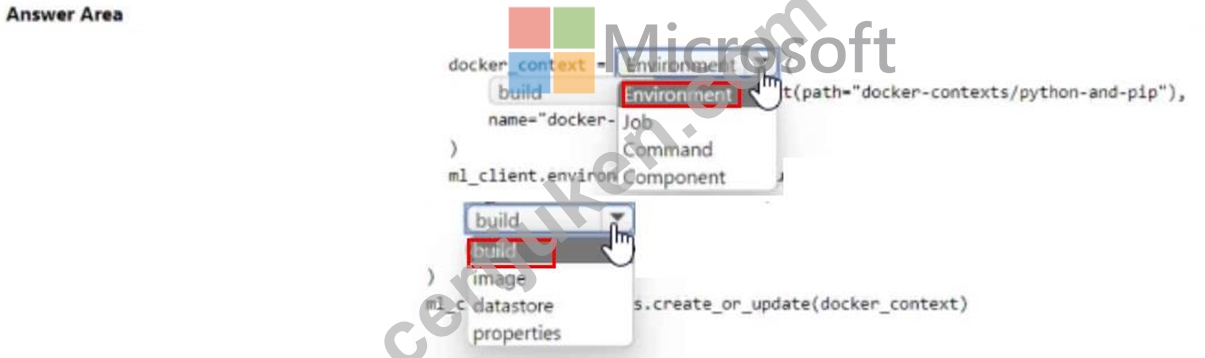
質問 # 142
You have a Python data frame named salesData in the following format:
The data frame must be unpivoted to a long data format as follows:
You need to use the pandas.melt() function in Python to perform the transformation.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
正解:
解説: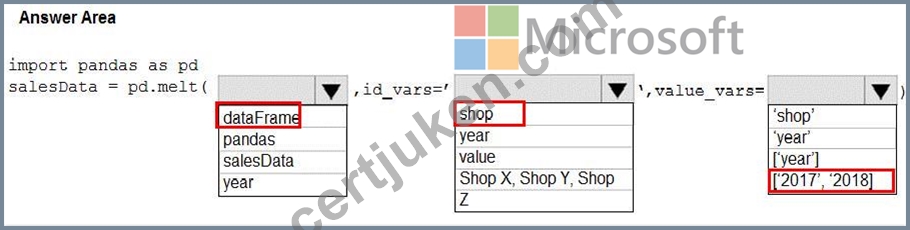
Reference:
https://pandas.pydata.org/pandas-docs/stable/reference/api/pandas.melt.html
質問 # 143
......
DP-100合格受験記: https://www.certjuken.com/DP-100-exam.html
2026年CertJukenの最新DP-100 PDFダンプおよびDP-100試験エンジンの無料共有:https://drive.google.com/open?id=13Jes_3saikw5lXDJaTLnS4Q5QtwIYimd