Außerdem sind jetzt einige Teile dieser ZertSoft Databricks-Generative-AI-Engineer-Associate Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=15DoybxFfqm4nUgklWQpAajbdcKRuPL9K
Es ist uns allen klar, dass das Hauptproblem in der IT-Branche ein Mangel an Qualität und Funktionalität ist. ZertSoft stellt Ihnen alle notwendigen Schulungsunterlagen zur Databricks Databricks-Generative-AI-Engineer-Associate Prüfung zur Verfügung. Ähnlich wie die reale Zertifizietungsprüfung verhelfen die Multiple-Choice-Fragen Ihnen zum Bestehen der Prüfung. Die Databricks Databricks-Generative-AI-Engineer-Associate Prüfung Schulungsunterlagen von ZertSoft sind überprüfte Prüfungsmaterialien. Alle diesen Fragen und Antworten zeigen unsere praktische Erfahrungen und Spezialisierung.
| Section | Weight | Objectives |
|---|---|---|
| Governance | 8% | - Manage permissions and logging - Apply safety filters and guidelines |
| Design Applications | 14% | - Design and architect applications - Select appropriate models - Define functional requirements |
| Evaluation and Monitoring | 12% | - Monitor deployed applications - Evaluate model quality and performance |
| Data Preparation | 14% | - Manage data quality and chunking - Prepare data for RAG applications |
| Application Development | 30% | - Integrate Databricks tools (LangChain, etc.) - Develop LLM chains - Implement prompt engineering |
| Assembling and Deploying Apps | 22% | - Use Vector Search - Package and deploy models - Build and deploy RAG pipelines |
>> Databricks-Generative-AI-Engineer-Associate Dumps <<
Wir können mit Stolz sagen, dass wir ZertSoft professionell ist! Denn die Bestehensquote der Prüflingen, die unsere Databricks Databricks-Generative-AI-Engineer-Associate Software benutzt haben, ist unglaublich hoch. Denn unsere Tech-Gruppe ist unglaublich kompetent. Der Kundendienst ist ein sehr wichtiger Standard für eine Firma. Um den hohen Standard zu entsprechen, bieten wir 24/7 online Kundendienst, einjähriger kostenloser Databricks Databricks-Generative-AI-Engineer-Associate Aktualisierungsdienst nach dem Kauf und die Erstattungspolitik beim Durchfall. Wenn Sie wirklich Databricks Databricks-Generative-AI-Engineer-Associate bestehen möchten, wählen Sie unsere Produkte!
47. Frage
A Generative AI Engineer at a legal firm is designing a RAG system to analyze historical legal cases. The system needs to process millions of court opinions and legal documents, already organized by time and topic, to track how interpretations of specific laws have evolved over time. All of these documents are in plain-text.
The engineer needs to choose a chunking method that would most effectively preserve continuity and the temporal nature of the cases. Which method do they choose?
Antwort: D
Begründung:
In the context of legal document analysis where the " evolution of interpretation " is the primary goal, preserving narrative continuity is paramount. Windowed summarization with overlapping chunks is the most effective method for this use case. Overlapping (e.g., 10-15% of the chunk size) ensures that sentences or concepts split at the boundary of one chunk are preserved in the next, preventing the loss of critical context that often occurs in legal jargon. Furthermore, windowed summarization allows the system to condense long- form court opinions into manageable parts while maintaining the chronological " thread " of the argument.
While sentence-level embeddings with metadata (D) are useful for filtering, they often lack the sufficient context required to understand the nuances of a legal ruling. A windowed approach provides the LLM with enough surrounding text to understand the " why " behind a legal evolution, rather than just the " when. "
48. Frage
After changing the response generating LLM in a RAG pipeline from GPT-4 to a model with a shorter context length that the company self-hosts, the Generative AI Engineer is getting the following error:
What TWO solutions should the Generative AI Engineer implement without changing the response generating model? (Choose two.)
Antwort: A,C
Begründung:
Problem Context: After switching to a model with a shorter context length, the error message indicating that the prompt token count has exceeded the limit suggests that the input to the model is too large.
Explanation of Options:
Option A: Use a smaller embedding model to generate - This wouldn't necessarily address the issue of prompt size exceeding the model's token limit.
Option B: Reduce the maximum output tokens of the new model - This option affects the output length, not the size of the input being too large.
Option C: Decrease the chunk size of embedded documents - This would help reduce the size of each document chunk fed into the model, ensuring that the input remains within the model's context length limitations.
Option D: Reduce the number of records retrieved from the vector database - By retrieving fewer records, the total input size to the model can be managed more effectively, keeping it within the allowable token limits.
Option E: Retrain the response generating model using ALiBi - Retraining the model is contrary to the stipulation not to change the response generating model.
Options C and D are the most effective solutions to manage the model's shorter context length without changing the model itself, by adjusting the input size both in terms of individual document size and total documents retrieved.
49. Frage
A Generative AI Engineer is deploying a customer-facing, fine-tuned LLM on their public website. Given the large investment the company put into fine-tuning this model, and the proprietary nature of the tuning data, they are concerned about model inversion attacks. Which of the following Databricks AI Security Framework (DASF) risk mitigation strategies are most relevant to this use case?
Antwort: B
Begründung:
Model inversion attacks occur when an attacker uses the model's outputs to reconstruct the sensitive training data used during the fine-tuning process. To mitigate this in a public-facing application, implementing AI Guardrails is the most relevant strategy. Guardrails act as a programmable "filter" between the LLM and the end-user. They can be configured to detect if a model's response contains patterns that look like proprietary training data or PII (Personally Identifiable Information). While ACLs (B) and ABAC (D) protect the model's infrastructure (who can invoke the API), they do not inspect the content of the output, which is where the inversion attack actually manifests. Databricks provides integrated guardrail capabilities (via Mosaic AI Gateway) specifically to enforce compliance and prevent the leakage of sensitive internal knowledge that may have been baked into the model weights during fine-tuning.
50. Frage
A Generative Al Engineer has built an LLM-based system that will automatically translate user text between two languages. They now want to benchmark multiple LLM's on this task and pick the best one. They have an evaluation set with known high quality translation examples. They want to evaluate each LLM using the evaluation set with a performant metric.
Which metric should they choose for this evaluation?
Antwort: D
Begründung:
The task is to benchmark LLMs for text translation using an evaluation set with known high-quality examples, requiring a performant metric. Let's evaluate the options.
Option A: ROUGE metric
ROUGE (Recall-Oriented Understudy for Gisting Evaluation) measures overlap between generated and reference texts, primarily for summarization. It's less suited for translation, where precision and word order matter more.
Databricks Reference: "ROUGE is commonly used for summarization, not translation evaluation" ("Generative AI Cookbook," 2023).
Option B: BLEU metric
BLEU (Bilingual Evaluation Understudy) evaluates translation quality by comparing n-gram overlap with reference translations, accounting for precision and brevity. It's widely used, performant, and appropriate for this task.
Databricks Reference: "BLEU is a standard metric for evaluating machine translation, balancing accuracy and efficiency" ("Building LLM Applications with Databricks").
Option C: NDCG metric
NDCG (Normalized Discounted Cumulative Gain) assesses ranking quality, not text generation. It's irrelevant for translation evaluation.
Databricks Reference: "NDCG is suited for ranking tasks, not generative output scoring" ("Databricks Generative AI Engineer Guide").
Option D: RECALL metric
Recall measures retrieved relevant items but doesn't evaluate translation quality (e.g., fluency, correctness). It's incomplete for this use case.
Databricks Reference: No specific extract, but recall alone lacks the granularity of BLEU for text generation tasks.
Conclusion: Option B (BLEU) is the best metric for translation evaluation, offering a performant and standard approach, as endorsed by Databricks' guidance on generative tasks.
51. Frage
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.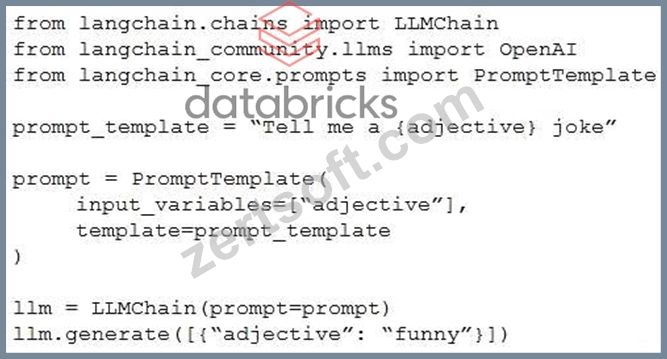
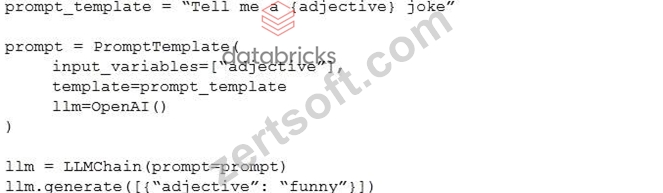
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?


Antwort: D
Begründung:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods:
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
* Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
* Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
* Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
52. Frage
......
Die Schulungsunterlagen zur Databricks Databricks-Generative-AI-Engineer-Associate Zertifizierungsprüfung sind preiswert, sie verfügen auch über hohe Genauigkeiten und große Reichweite. Nachdem Sie unsere Ausbildungsmaterialien zur Databricks Databricks-Generative-AI-Engineer-Associate Zertifizierungsprüfung gekauft haben, werden wir Ihnen einjähriger Aktualisierung kostenlos anbieten. Hier versprechen wir Ihnen, dass wir alle Ihre bezahlten Summe zurückgeben werden, wenn es irgend ein Qualitätsproblem gibt oder Sie die Databricks Databricks-Generative-AI-Engineer-Associate Zertifizierungsprüfung nicht bestehen, nachdem Sie unsere Schulungsunterlagen zur Databricks Databricks-Generative-AI-Engineer-Associate Prüfung gekauft haben.
Databricks-Generative-AI-Engineer-Associate Testfagen: https://www.zertsoft.com/Databricks-Generative-AI-Engineer-Associate-pruefungsfragen.html
P.S. Kostenlose und neue Databricks-Generative-AI-Engineer-Associate Prüfungsfragen sind auf Google Drive freigegeben von ZertSoft verfügbar: https://drive.google.com/open?id=15DoybxFfqm4nUgklWQpAajbdcKRuPL9K