P.S. Free & New Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by BraindumpsIT: https://drive.google.com/open?id=1WdGRaMq7B72Hkg8VjQjMYQlYedcO1Gwv
Almost every Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) test candidate nowadays is confused about the Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) study material. They don't know where to download updated Professional-Machine-Learning-Engineer questions that can help them prepare quickly for the Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) test. Some rely on outdated Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) questions and suffer from the loss of money and time.
| Section | Objectives |
|---|---|
| Scaling prototypes into ML models | - Training at scale (Distributed training, TPUs) - Hyperparameter tuning - Frameworks (TensorFlow, PyTorch, JAX, Scikit-learn) |
| Automating and orchestrating ML pipelines | - Vertex AI Pipelines (Kubeflow Pipelines) - CI/CD for ML systems - Triggering and scheduling pipelines |
| Collaborating within and across teams to manage data and models | - Data management and governance - Version control and reproducibility (e.g., DVC, MLOps) - Collaboration between Data Scientists, Data Engineers, and ML Engineers |
| Architecting low-code ML solutions | - AutoML capabilities and implementation - Leveraging pre-built ML models as a service (e.g., Vision AI, Speech-to-Text, Recommendations AI) - Implementing BigQuery ML for basic models |
| Monitoring ML solutions | - Model retraining strategies - Logging and alerting (Cloud Monitoring) - Performance monitoring and drift detection |
| Serving and scaling models | - Model optimization (Quantization, Distillation) - Hardware accelerators (GPU/TPU) in serving - Batch prediction - Online prediction (Vertex AI Prediction) |
>> Interactive Professional-Machine-Learning-Engineer EBook <<
Our company has always been following the trend of the Professional-Machine-Learning-Engineer Certification.The content of our Professional-Machine-Learning-Engineer practice materials is chosen so carefully that all the questions for the exam are contained. And our Professional-Machine-Learning-Engineer study materials have three formats which help you to read, test and study anytime, anywhere. This means with our products you can prepare for exams efficiently. If you desire a Google certification, our products are your best choice.
NEW QUESTION # 61
You are designing an architecture with a serverless ML system to enrich customer support tickets with informative metadata before they are routed to a support agent. You need a set of models to predict ticket priority, predict ticket resolution time, and perform sentiment analysis to help agents make strategic decisions when they process support requests. Tickets are not expected to have any domain-specific terms or jargon.
The proposed architecture has the following flow: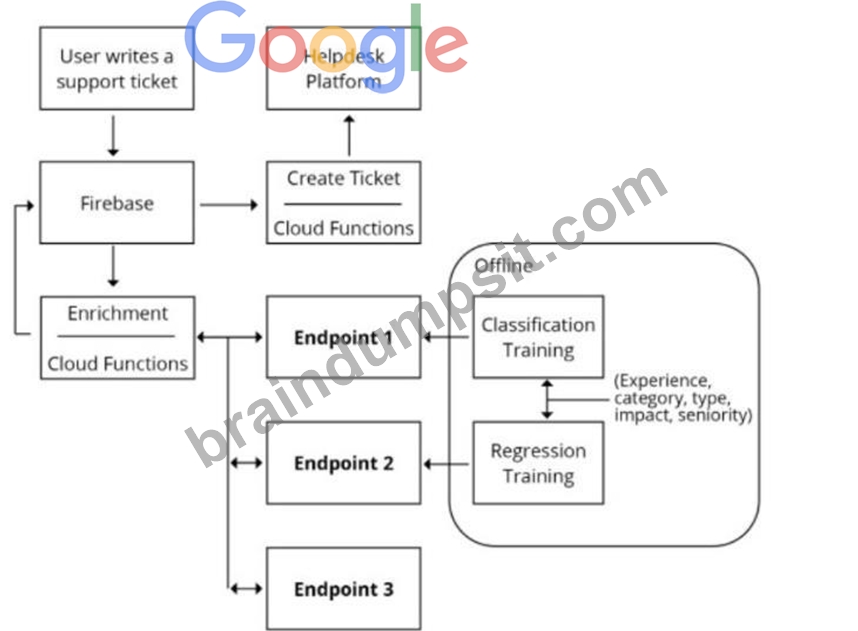
Which endpoints should the Enrichment Cloud Functions call?
Answer: B
Explanation:
Vertex AI is a unified platform for building and deploying ML models on Google Cloud. It supports both custom and AutoML models, and provides various tools and services for ML development, such as Vertex Pipelines, Vertex Vizier, Vertex Explainable AI, and Vertex Feature Store. Vertex AI can be used to create models for predicting ticket priority and resolution time, as these are domain-specific tasks that require custom training data and evaluation metrics. Cloud Natural Language API is a pre-trained service that provides natural language understanding capabilities, such as sentiment analysis, entity analysis, syntax analysis, and content classification. Cloud Natural Language API can be used to perform sentiment analysis on the support tickets, as this is a general task that does not require domain-specific knowledge or jargon. The other options are not suitable for the given architecture. AutoML Natural Language and AutoML Vision are services that allow users to create custom natural language and vision models using their own data and labels.
They are not needed for sentiment analysis, as Cloud Natural Language API already provides this functionality. Cloud Vision API is a pre-trained service that provides image analysis capabilities, such as object detection, face detection, text detection, and image labeling. It is not relevant for the support tickets, as they are not expected to have any images. References:
* Vertex AI documentation
* Cloud Natural Language API documentation
NEW QUESTION # 62
You are developing an ML pipeline using Vertex Al Pipelines. You want your pipeline to upload a new version of the XGBoost model to Vertex Al Model Registry and deploy it to Vertex Al End points for online inference. You want to use the simplest approach. What should you do?
Answer: C
Explanation:
According to the web search results, Vertex AI Pipelines is a serverless orchestrator for running ML pipelines, using either the KFP SDK or TFX1. Vertex AI Pipelines provides a set of prebuilt components that can be used to perform common ML tasks, such as training, evaluation, deployment, and more2. Vertex AI ModelUploadOp and ModelDeployOp are two such components that can be used to upload a new version of the XGBoost model to Vertex AI Model Registry and deploy it to Vertex AI Endpoints for online inference3. Therefore, option D is the best way to use the simplest approach for the given use case, as it only requires chaining two prebuilt components together. The other options are not relevant or optimal for this scenario. Reference:
Vertex AI Pipelines
Google Cloud Pipeline Components
Vertex AI ModelUploadOp and ModelDeployOp
Google Professional Machine Learning Certification Exam 2023
Latest Google Professional Machine Learning Engineer Actual Free Exam Questions
NEW QUESTION # 63
A Machine Learning Specialist is assigned a TensorFlow project using Amazon SageMaker for training, and needs to continue working for an extended period with no Wi-Fi access.
Which approach should the Specialist use to continue working?
Answer: A
Explanation:
Explanation
NEW QUESTION # 64
While performing exploratory data analysis on a dataset, you find that an important categorical feature has 5% null values. You want to minimize the bias that could result from the missing values. How should you handle the missing values?
Answer: C
Explanation:
This approach is often referred to as "imputing" missing values, and it is a common technique for dealing with missing data in categorical features. By using a placeholder category, you explicitly indicate that the value is missing, rather than assuming that the missing value is a particular category. This can help to minimize bias in downstream analyses, as it does not introduce any assumptions about the missing data that could bias your results.
NEW QUESTION # 65
You have trained a model by using data that was preprocessed in a batch Dataflow pipeline Your use case requires real-time inference. You want to ensure that the data preprocessing logic is applied consistently between training and serving. What should you do?
Answer: A
Explanation:
According to the official exam guide1, one of the skills assessed in the exam is to "design, build, and productionalize ML models to solve business challenges using Google Cloud technologies". Dataflow2 is a fully managed, fast, and easy-to-use service for running Apache Spark and Apache Hadoop clusters on Google Cloud. Dataflow supports both batch and streaming data processing pipelines. However, if your use case requires real-time inference, you need to ensure that the data preprocessing logic is applied consistently between training and serving. One way to achieve this is to refactor the transformation code in the batch data pipeline so that it can be used outside of the pipeline, and use the same code in the endpoint. This way, you can avoid data skew and drift issues that might arise from using different preprocessing methods for training and serving. Therefore, option B is the best way to ensure the data preprocessing logic is applied consistently between training and serving. The other options are not relevant or optimal for this scenario. Reference:
Professional ML Engineer Exam Guide
Dataflow
Google Professional Machine Learning Certification Exam 2023
Latest Google Professional Machine Learning Engineer Actual Free Exam Questions
NEW QUESTION # 66
......
In every area, timing counts importantly. With the advantage of high efficiency, our Professional-Machine-Learning-Engineer practice materials help you avoid wasting time on selecting the important and precise content from the broad information. In such a way, you can confirm that you get the convenience and fast. By studying with our Professional-Machine-Learning-Engineer Real Exam for 20 to 30 hours, we can claim that you can get ready to attend the Professional-Machine-Learning-Engineerexam.
Professional-Machine-Learning-Engineer Latest Exam Test: https://www.braindumpsit.com/Professional-Machine-Learning-Engineer_real-exam.html
DOWNLOAD the newest BraindumpsIT Professional-Machine-Learning-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1WdGRaMq7B72Hkg8VjQjMYQlYedcO1Gwv