最も早い時間で気楽にMicrosoftのDP-750認定試験に合格したいなら、CertJukenを選んだ方が良いです。あなたはCertJukenの学習教材を購入した後、私たちは一年間で無料更新サービスを提供することができます。あなたは最新のMicrosoftのDP-750試験トレーニング資料を手に入れることが保証します。もしうちの学習教材を購入した後、試験に不合格になる場合は、私たちが全額返金することを保証いたします。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Topic 2: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 3: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 4: Prepare and process data | 30-35% | - Ingest and transform data
|
DP-750試験の教材を使用すると、夢をより確実に保護できます。これは、教材の合格率が高いためです。 DP-750学習教材は、DP-750学習ガイドの品質が業界を確実にリードし、完璧なサービスシステムを確保するために最も専門的なチームを選択しました。 DP-750学習教材の焦点と真剣さは、99%の合格率を与えます。当社の製品を使用すると、最も重要な合格率など、必要なすべてを取得できます。私たちのDP-750の実際の試験は、あなたの夢の道で本当に良いヘルパーです。
質問 # 60
You have an Azure Databricks workspace that uses serverless compute.
You need to ingest data by using Lakeflow Jobs. New records must be processed as soon as they become available.
Which type of job trigger should you use for the ingestion?
正解:C
解説:
The correct answer is D - Continuous trigger.
A Continuous trigger keeps the job running as a perpetual loop. As soon as one micro-batch or iteration completes, the next begins. New records are picked up with the shortest possible latency - as close to real- time as a Lakeflow Jobs pipeline gets.
File Arrival (Option B) is event-driven but introduces per-file trigger overhead and is best suited for file-based ingestion rather than continuous streaming workloads. Scheduled (Option C) runs at fixed clock intervals - if new data arrives between runs, it waits until the next scheduled execution. Manual (Option A) requires a human to start each run.
The question specifies serverless compute, which pairs naturally with Continuous trigger because serverless handles cluster lifecycle automatically - the job stays active without managing a persistent cluster. 'New records must be processed as soon as they become available' is the exact use case the Continuous trigger is designed for.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/triggers
質問 # 61
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two catalogs named Catalog1 and Catalog2.
An external application uses a service principal named SP1 to connect to a SQL warehouse.
You need to ensure that SP1 can query the data in Catalog1 and Catalog2. The solution must follow the principle of least privilege.
Which permissions should you grant to SP1 for the catalogs?
正解:C
質問 # 62
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1. Table1 stores customer data.
You need to implement a data retention solution that meets the following requirements:
Deleted data must be retained for 30 days to support audits.
Deleted data that is older than 30 days must be removed permanently.
The solution must minimize administrative effort.
Which two properties should you configure? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
正解:B、C
解説:
The correct answers are B and D. Delta Lake's data retention behaviour is controlled by two distinct properties that work together:
delta.deletedFileRetentionDuration governs how long physically deleted data files are kept before VACUUM can remove them. Setting this to 30 days ensures deleted records remain on storage for the full audit window.
delta.logRetentionDuration controls how long the transaction log is retained. Time-travel queries (SELECT ...
VERSION AS OF or TIMESTAMP AS OF) rely on the log to reconstruct historical table states - without 30 days of log, you can't query 30-day-old snapshots even if the data files are still there.
Both properties need to be set to 30 days to fully honour the requirement. Option A (delta.timeUntilArchived) doesn't exist in Delta Lake. Option C (autoCompact) manages file sizing, not retention. Option E (enableDeletionVectors) speeds up deletes but has no bearing on how long data is kept.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/history#configure-data-retention
質問 # 63
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to ensure that data lineage is captured and can be reviewed for tables accessed by Databricks notebooks and jobs. The solution must minimize administrative effort.
Which compute configuration should you use to capture the data lineage and what should you use to review the data lineage? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.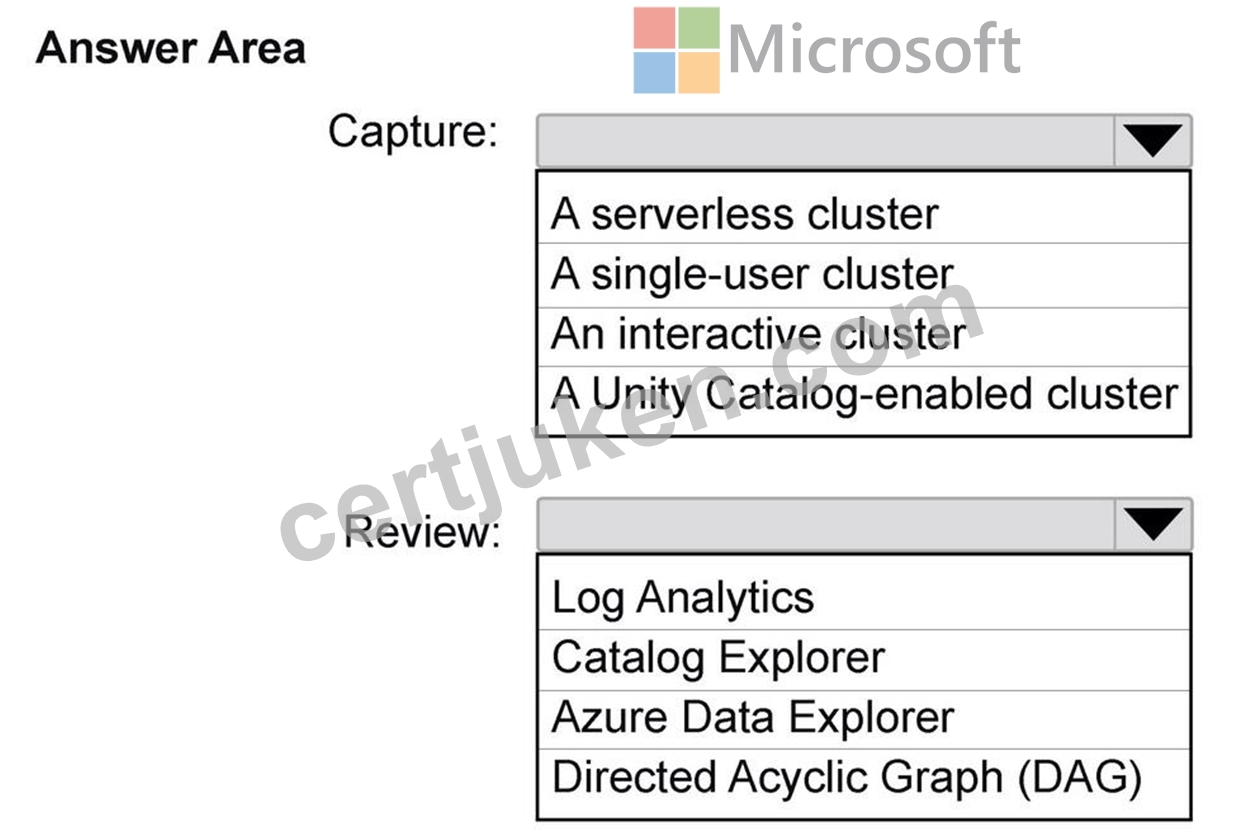
正解:
解説: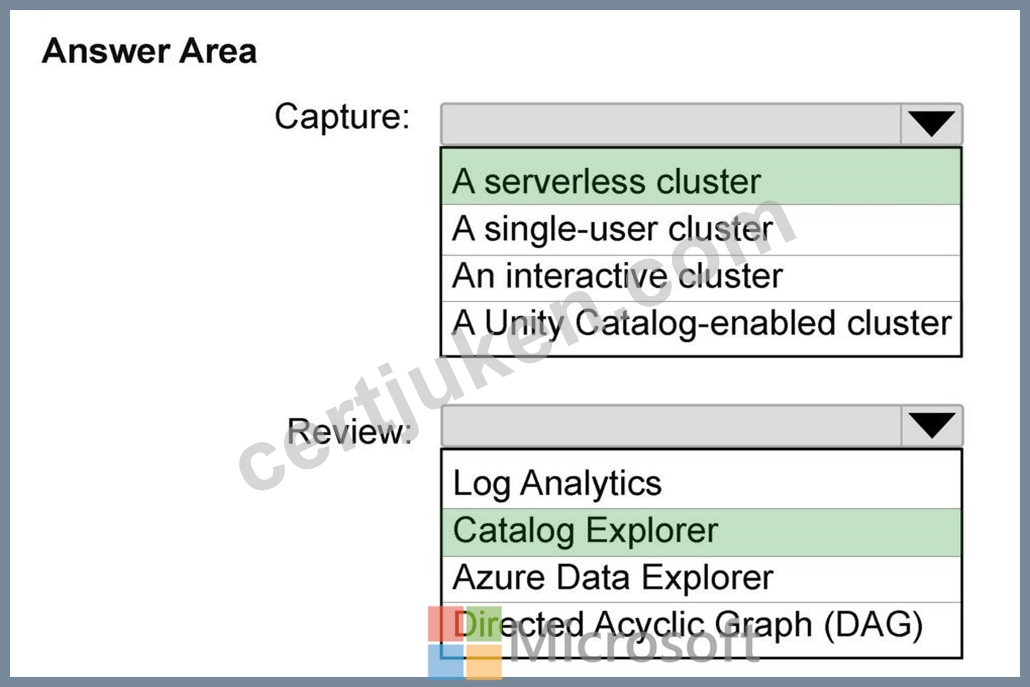
質問 # 64
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a complex job named Job1 that contains eight tasks. Job1 takes multiple hours to complete.
During the last job run, the final task fails due to a transient issue.
You need to retry the last task without rerunning tasks that have already completed.
What should you do?
正解:D
解説:
You can retry only the failed final task by using the Repair Run feature in Azure Databricks. This allows you to rerun failed or skipped tasks without restarting the successful ones, preserving your Unity Catalog data lineage and saving hours of compute time.
Reference:
https://www.databricks.com/blog/2022/05/06/save-time-and-money-on-data-and-ml-workflows- with-repair-and-rerun.html
質問 # 65
......
周りの多くの人は全部Microsoft DP-750資格認定試験にパースしまして、彼らはどのようにできましたか。今には、あなたにCertJukenを教えさせていただけませんか。我々社サイトのMicrosoft DP-750問題庫は最新かつ最完備な勉強資料を有して、あなたに高品質のサービスを提供するのはDP-750資格認定試験の成功にとって唯一の選択です。躊躇わなくて、CertJukenサイト情報を早く了解して、あなたに試験合格を助かってあげますようにお願いいたします。
DP-750学習体験談: https://www.certjuken.com/DP-750-exam.html