2026 Latest CertkingdomPDF SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1QCwT8et3R6eRy5YuSn7h5iOZh67c3UwT
Genius is 99% of sweat plus 1% of inspiration. You really don't need to think that you can succeed for nothing. If you still have a trace of enterprise, you really want to start working hard! Our SPS-C01 exam questions are the most effective helpers on your path. As the high pass rate of our SPS-C01 study braindumps is as 98% to 100%, you can pass the exam without any doubt. And with the SPS-C01 certification, you will lead a better life!
| Section | Objectives |
|---|---|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Data Engineering with Snowpark | - Pipeline development
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Testing, Debugging, and Deployment | - Production readiness
|
>> Reliable SPS-C01 Braindumps Files <<
Generally speaking, preparing for the SPS-C01 exam is a very hard and even some suffering process. Because time is limited, sometimes we have to spare time to do other things to review the exam content, which makes the preparation process full of pressure and anxiety. But from the point of view of customers, our SPS-C01 Study Materials will not let you suffer from this. As mentioned above, our SPS-C01 study materials have been carefully written, each topic is the essence of the content. Only should you spend about 20 - 30 hours to study SPS-C01 study materials carefully can you take the exam.
NEW QUESTION # 192
You are developing a Snowpark Python stored procedure for processing financial data'. The procedure uses the 'pandas' library for data manipulation and the 'scipy' library for statistical calculations. You want to optimize the execution of the stored procedure to leverage the available resources in your Snowflake environment. Which of the following strategies would be MOST effective in improving the performance of your stored procedure, considering the need to handle large datasets?
Answer: C
Explanation:
Option C is the most effective strategy for improving performance with large datasets. Snowpark's vectorized UDFs allow you to leverage Snowflake's distributed processing capabilities to perform calculations in parallel, avoiding the overhead of transferring data to Pandas. Option B would bring the entire dataset into memory on a single node which defeats the purpose of Snowflakes distributed computing. Option A might help but wouldn't fundamentally address the distribution issue. Option D is a brute-force approach and might help, but vectorized UDFs are more efficient. Option E could work but it requires complicated coding of partitioning logic.
NEW QUESTION # 193
Consider two Snowpark DataFrames, 'employees' and 'departments' , with the following schemas: 'employees': (employee_id: Integer Type, employee_name: StringType, department_id: Integer Type, salary: IntegerType) 'departments': (department_id: Integer Type, department_name: StringType, location: StringType) You want to find the highest salary within each department, along with the department name and location, and display the results in a Snowpark DataFrame. Which of the following Snowpark Python code snippets correctly achieves this?


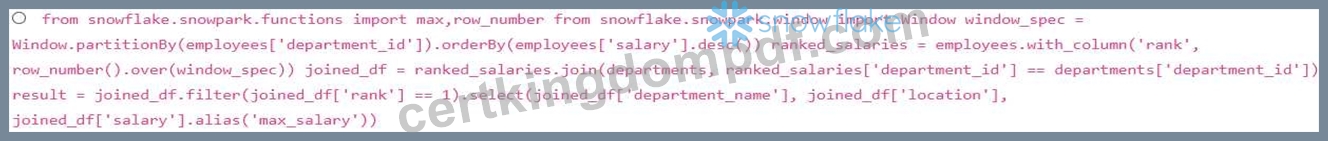


Answer: A
Explanation:
Option A correctly groups the 'employees' DataFrame by 'department_id' , calculates the maximum salary for each department using and then joins the resulting DataFrame with the 'departments' DataFrame on Finally, it selects the required columns: department name, location, and the calculated maximum salary. Option B is not correct as it calculates the rank of all salaries within each department but it does not aggregate on 'department_id'. Option C incorrectly attempts to group by columns from both tables before joining. Option D incorrectly uses the un-joined employees table where rank_salaries are from department_id. Option E will not work due to table names during select. It tries to use 'joined_df table for columns which doesn't have it.
NEW QUESTION # 194
You are tasked with optimizing a Snowpark application that performs complex data transformations on a large dataset (1 TB) stored in Snowflake. The application currently uses Snowpark DataFrames and is experiencing slow performance. You suspect the issue might be related to data transfer overhead between the Snowflake engine and the Python environment. Which of the following strategies would be MOST effective in minimizing this overhead and improving performance?
Answer: A,C,E
Explanation:
UDFs written in Python allow you to push the computation to the Snowflake engine, avoiding the need to transfer large amounts of data to the Python environment, improving performance by reducing data transfer overhead. Pre-filtering and aggregating reduces data before more complex transformations, also reducing data transfer. Vectorization through optimized Snowpark DataFrame methods also reduces data transfer and speeds computation in the Snowflake engine. Converting to Pandas DataFrames negates the benefit of Snowpark for large datasets. Increasing the virtual warehouse size only addresses processing power but does not minimize data transfer.
NEW QUESTION # 195
You are developing a Snowpark application that needs to train a machine learning model on a large dataset stored in Snowflake. You want to optimize the performance of your model training process. Which of the following strategies would be MOST effective in leveraging Snowpark's architecture to achieve this, considering both client-side and server-side capabilities?
Answer: B
Explanation:
Using a stored procedure ('sproc') allows the model training to occur entirely within the Snowflake environment, leveraging its scalable compute resources and eliminating the need to transfer large datasets to the client. This minimizes data transfer overhead and maximizes performance. Options A, D and E involve data transfer or execution outside the Snowflake environment which contradicts Snowpark's server-side processing advantages. Option C is a good preprocessing step, but doesn't train the model inside Snowflake.
NEW QUESTION # 196
You are developing a Snowpark application using Visual Studio Code and the Snowflake VS Code extension. You want to configure the extension to automatically detect and use a specific Anaconda environment for your Snowpark development. Assuming you have already created an Anaconda environment named 'snowpark_env', which configuration setting in the VS Code settings.json file would correctly specify the Python path for the Snowflake extension?
Answer: B
Explanation:
Option D is the correct configuration setting. The 'python.defaultlnterpreterPath' setting in VS Code's 'settings.json' file is used to specify the Python interpreter path that VS Code should use for all Python-related tasks, including running and debugging Snowpark applications. Options A and C are incorrect because the Snowflake extension uses standard VS Code Python settings. Option E is for SnowSQL and not directly related to Snowpark Python development within VS Code. The path needs to point to the python executable inside your conda enviornment.
NEW QUESTION # 197
......
We will try our best to solve your problems for you. I believe that you will be more inclined to choose a good service product, such as SPS-C01 learning question. After all, everyone wants to be treated warmly and kindly, and hope to learn in a more pleasant mood. The authoritative, efficient, and thoughtful service of SPS-C01 learning question will give you the best user experience, and you can also get what you want with our study materials. I hope our study materials can accompany you to pursue your dreams. If you can choose SPS-C01 test guide, we will be very happy. We look forward to meeting you.
Reliable SPS-C01 Mock Test: https://www.certkingdompdf.com/SPS-C01-latest-certkingdom-dumps.html
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by CertkingdomPDF: https://drive.google.com/open?id=1QCwT8et3R6eRy5YuSn7h5iOZh67c3UwT