What's more, part of that Braindumpsqa SPS-C01 dumps now are free: https://drive.google.com/open?id=1e5wCFDe4NxlSZa4_I9eIHx3yFi00arik
Our product boosts varied functions to be convenient for you to master the SPS-C01 training materials and get a good preparation for the exam and they include the self-learning function, the self-assessment function, the function to stimulate the exam and the timing function. We provide 24-hours online on SPS-C01 Guide prep customer service and the long-distance professional personnel assistance to for the client. If clients have any problems about our SPS-C01 study materials they can contact our customer service at any time.
| Section | Objectives |
|---|---|
| Data Engineering with Snowpark | - Pipeline development
|
| Testing, Debugging, and Deployment | - Production readiness
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
>> Valid SPS-C01 Test Pass4sure <<
The Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) study material of Braindumpsqa is available in three different and easy-to-access formats. The first one is printable and portable Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) PDF format. With the PDF version, you can access the collection of actual Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) questions with your smart devices like smartphones, tablets, and laptops.
NEW QUESTION # 167
You are developing a Snowpark application to process sales data. The application uses a UDF that calls an external Python library with a large memory footprint. After deploying the application, you observe that the Snowflake warehouse frequently runs out of memory, causing the application to fail. Which of the following strategies would be MOST effective in mitigating this issue, while minimizing cost and maintaining performance? Assume the data volume is relatively large and the UDF is computationally intensive.
Answer: D
Explanation:
Option B is the most effective and cost-efficient solution. Processing data in smaller batches using a generator pattern within the UDF will significantly reduce memory consumption without requiring a larger, more expensive warehouse. Option A is a brute-force approach that increases costs unnecessarily. Option C might help, but batching provides more reliable memory control. Option D involves significant code rewriting and might not guarantee a substantial memory reduction, especially if the Python library is inherently memory-intensive. Option E doesn't inherently solve the memory issue if the underlying UDF's memory usage remains high.
NEW QUESTION # 168
A data engineering team is building a Snowpark pipeline to process IoT sensor data'. They want to create a UDF that uses a 3rd-party Python library (not available in Snowflake's Anaconda channel) to analyze the sensor readings. The UDF needs to be efficiently deployed and managed within Snowflake. Which of the following approaches represents the MOST robust and scalable way to register and deploy this UDF using Snowpark?
Answer: B
Explanation:
Option B is the correct answer. It describes the best practice for deploying UDFs with external Python libraries in Snowflake. Creating a virtual environment, zipping it, uploading it to a stage, and referencing it during UDF registration ensures proper dependency management and avoids conflicts. Option A is problematic because embedding the library directly makes the UDF definition very large and unmanageable. Option C will not work if the required version isn't available. Option D is incorrect because functions.udf relies on packages available in the Snowflake Anaconda channel and doesn't manage custom packages. While Option E could work, its overly complex for this specific scenario compared to utilizing Snowpark virtual enviornment and stage management. Option B is more efficient and streamlined.
NEW QUESTION # 169
You are developing a Snowpark application that utilizes a DataFrame named 'transactions df containing transactional data. You need to apply a series of complex transformations, including window functions and joins with other DataFrames. To optimize performance and manage resources effectively, you want to control how Snowpark executes these operations within Snowflake. Which of the following actions or configurations would have the MOST significant impact on controlling the execution plan and resource utilization of your Snowpark application?
Answer: D
Explanation:
Option C, using to analyze the query plan and then manually optimizing the Snowpark code, would have the MOST significant impact. Understanding the query plan allows you to identify bottlenecks, skew issues, and inefficient operations. Based on the plan, you can rewrite your Snowpark code to guide Snowflake toward a more efficient execution strategy. Caching (A) can sometimes help, but it's not always beneficial and can consume resources unnecessarily if not used carefully. Enabling native execution (B) generally improves performance, but it doesn't give you direct control over the execution plan. Partitioning (D) can be helpful, but the optimal number of partitions depends on the data and the transformations being performed. Using imperative loops (E) generally defeats the purpose of using Snowpark's declarative DataFrame API, which is designed to leverage Snowflake's query optimizer and parallel processing capabilities. It will most likely be very ineficient. Therefore, analyzing the query plan is crucial for optimizing resource utilization and controlling execution.
NEW QUESTION # 170
You are developing a Snowpark Python UDF to perform sentiment analysis on product reviews. The UDF takes a text review (STRING) as input and returns a sentiment score (FLOAT). You want to operationalize this UDF, ensuring type safety and performance. Which of the following approaches is MOST recommended, considering both ease of use and explicit type declaration?

Answer: E
Explanation:
Using a combination of type hints and the registration API provides the best balance of readability and explicit type safety. The @udf decorator with 'return_type' and ensures that Snowflake understands the data types, while the Python type hints improve code readability and help catch type errors during development. Option A relies on inference, which can be less explicit and potentially lead to unexpected behavior. Option B lacks the readability of Python type hints. Option D is not a valid way to register a UDF. Casting the result (Option E) doesn't define the data type beforehand and is less efficient than defining during registration.
NEW QUESTION # 171
Consider the following Snowpark Python code snippet designed to create a DataFrame and then register a custom function (UDF):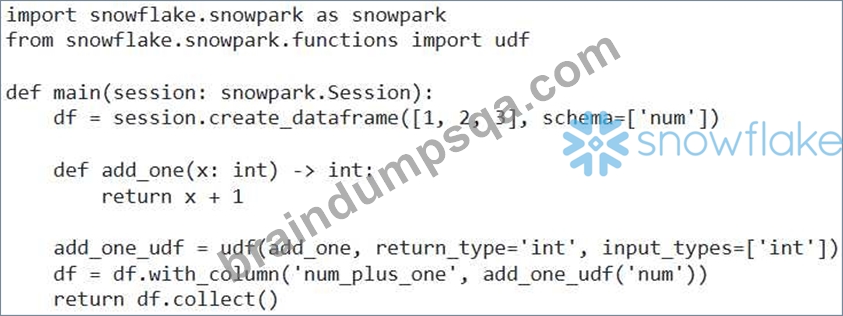
This code runs successfully. However, you need to deploy this as a stored procedure. What minimal changes are required to make this code runnable as a Snowpark Python stored procedure and callable from SQL?
Answer: D
Explanation:
When deploying as a stored procedure, 'return will cause an error since stored procedures cannot return Snowpark DataFrames directly to SQL. You need to return the DataFrame to pandas using 'return and remove 'return_type' and 'input_types' arguments of udf to allow inference.
NEW QUESTION # 172
......
Are you often regretful that you have purchased an inappropriate product? Unlike other platforms for selling test materials, in order to make you more aware of your needs, SPS-C01 study materials provide sample questions for you to download for free. You can use the sample questions to learn some of the topics about SPS-C01 study materials and familiarize yourself with the SPS-C01 software in advance. If you feel that the SPS-C01 study materials are satisfying to you, you can choose to purchase our complete question bank. After the payment, you will receive the email sent by the system within 5-10 minutes. Click on the login to start learning immediately with SPS-C01 study materials. No need to wait.
SPS-C01 Positive Feedback: https://www.braindumpsqa.com/SPS-C01_braindumps.html
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by Braindumpsqa: https://drive.google.com/open?id=1e5wCFDe4NxlSZa4_I9eIHx3yFi00arik