New Certified-Data-Engineer-Professional Exam Experience & Training Certified-Data-Engineer-Professional For Exam

As is known to us, the high pass rate is a reflection of the high quality of Certified-Data-Engineer-Professional study torrent. The more people passed their exam, the better the study materials are. There are more than 98 percent that passed their exam, and these people both used our Certified-Data-Engineer-Professional test torrent. There is no doubt that our Databricks Certified Data Engineer Professional guide torrent has a higher pass rate than other study materials. We deeply know that the high pass rate is so important for all people, so we have been trying our best to improve our pass rate all the time. Now our pass rate has reached 99 percent. If you choose our Certified-Data-Engineer-Professional study torrent as your study tool and learn it carefully, you will find that it will be very soon for you to get the Databricks Certified Data Engineer Professional certification in a short time. Do not hesitate and buy our Certified-Data-Engineer-Professional test torrent, it will be very helpful for you.
| Section | Objectives |
|---|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 3. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 4. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 5. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 6. Create pipeline components using control flow operators such as if/else and foreach
- 7. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 8. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDF
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Apply Change Data Feed to address streaming table limitations and improve latency
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Monitoring and Alerting | - Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Query Profile and Spark UI to monitor workloads
- Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
|
| Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Simplify data layout decisions and optimize query performance using liquid clustering
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Design and implement scalable data models using Delta Lake to manage large datasets
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Use row filters and column masks to protect sensitive table data
|
| Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Analyze errors and remediate failed job runs using job repairs and parameter overrides
|
>> New Certified-Data-Engineer-Professional Exam Experience <<
100% Pass 2026 Trustable Databricks New Certified-Data-Engineer-Professional Exam Experience
Computer brings more convenience, online access to information, published an article, watch movies, online remote virtual learning and other benefits. IT workers are becoming high-salary field in all over the world. NewPassLeader releases latest and valid Certified-Data-Engineer-Professional Exam preparations to help candidates clear exams certainly as Databricks certifications are outstanding and attractive. If you determine to take part in exams, our Certified-Data-Engineer-Professional exam preparations will be a good helper.
Databricks Certified Data Engineer Professional Sample Questions (Q39-Q44):
NEW QUESTION # 39
A data architect is implementing Delta Sharing as part of their data governance strategy to enable secure data collaboration with external partners and internal business units. The architect must establish a permission framework that allows designated data stewards to create shares for their respective domains while maintaining security boundaries and audit compliance. Which specific permissions and roles must be assigned to enable users to create, configure, and manage Delta Shares while maintaining proper security governance and access controls?
- A. Users need the MANAGE SHARES permission on the workspace
- B. Any user with USE_CATALOG privilege can create shares
- C. Users need to be metastore admins or have CREATE SHARE privilege for the metastore
- D. Only workspace admins can create and manage shares
Answer: C
Explanation:
Creating and managing Delta Shares requires elevated governance privileges at the metastore level. Assigning users as metastore admins or granting them the CREATE SHARE privilege allows designated data stewards to create and configure shares within defined security boundaries, while preserving centralized auditability and access control.
NEW QUESTION # 40
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalid latitude and longitude values in the activity_details table have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to add CHECK constraints to the Delta Lake table:
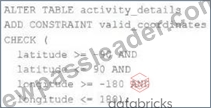
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
- A. The activity details table already exists; CHECK constraints can only be added during initial table creation.
- B. The current table schema does not contain the field valid coordinates; schema evolution will need to be enabled before altering the table to add a constraint.
- C. The activity details table already contains records that violate the constraints; all existing data must pass CHECK constraints in order to add them to an existing table.
- D. The activity details table already contains records; CHECK constraints can only be added prior to inserting values into a table.
- E. Because another team uses this table to support a frequently running application, two-phase locking is preventing the operation from committing.
Answer: C
Explanation:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and
180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation.
NEW QUESTION # 41
A data engineer is tasked with building a nightly batch ETL pipeline that processes very large volumes of raw JSON logs from a data lake into Delta tables for reporting. The data arrives in bulk once per day, and the pipeline takes several hours to complete. Cost efficiency is important, but performance and reliability of completing the pipeline are the highest priorities. Which type of Databricks cluster should the data engineer configure?
- A. An all-purpose cluster always kept running to ensure low-latency job startup times.
- B. A high-concurrency cluster designed for interactive SQL workloads.
- C. A lightweight single-node cluster with low worker node count to reduce costs.
- D. A job cluster configured to autoscale across multiple workers during the pipeline run.
Answer: D
Explanation:
Job clusters are optimized for automated production workloads. They start when a job is triggered and terminate automatically once the task completes. This ensures cost control while maintaining performance and reliability for batch ETL. Autoscaling allows Databricks to add or remove workers dynamically based on workload size, ensuring large data volumes are processed efficiently.
All-purpose clusters are intended for development or ad-hoc workloads, not scheduled ETL.
NEW QUESTION # 42
An upstream system is emitting change data capture (CDC) logs that are being written to a cloud object storage directory. Each record in the log indicates the change type (insert, update, or delete) and the values for each field after the change. The source table has a primary key identified by the field pk_id.
For analytical purposes, only the most recent value for each record needs to be recorded in the target Delta Lake table in the Lakehouse. The Databricks job to ingest these records occurs once per hour, but each individual record may have changed multiple times over the course of an hour.
Which solution meets these requirements?
- A. Use MERGE INTO to insert, update, or delete the most recent entry for each pk_id into a table, then propagate all changes throughout the system.
- B. Use Delta Lake's change data feed to automatically process CDC data from an external system, propagating all changes to all dependent tables in the Lakehouse.
- C. Deduplicate records in each batch by pk_id and overwrite the target table.
- D. Iterate through an ordered set of changes to the table, applying each in turn to create the current state of the table, (insert, update, delete), timestamp of change, and the values.
Answer: B
NEW QUESTION # 43
A data engineer is designing a Lakeflow Declarative Pipeline to process streaming order data.
The pipeline uses Auto Loader to ingest data and must enforce data quality by ensuring customer_id and amount are greater than zero. Invalid records should be dropped. Which Lakeflow Declarative Pipelines configurations implement this requirement using Python?
- A. @dlt.table
def silver_orders():
return (
dlt.read_stream("bronze_orders")
.expect("valid_customer", "customer_id IS NOT NULL")
.expect("valid_amount", "amount > 0")
) - B. @dlt.table
def silver_orders():
return (
dlt.read_stream("bronze_orders")
.expect_or_drop("valid_customer", "customer_id IS NOT NULL")
.expect_or_drop("valid_amount", "amount > 0")
) - C. @dlt.table
@dlt.expect("valid_customer", "customer_id IS NOT NULL")
@dlt.expect("valid_amount", "amount > 0")
def silver_orders():
return dlt.read_stream("bronze_orders") - D. @dlt.table
@dlt.expect_or_drop("valid_customer", "customer_id IS NOT NULL")
@dlt.expect_or_drop("valid_amount", "amount > 0")
def silver_orders():
return dlt.read_stream("bronze_orders")
Answer: B
Explanation:
Lakeflow Declarative Pipelines (LDP), formerly Delta Live Tables (DLT), supports enforcing data quality using expectations. Expectations can either:
Track violations (expect) -> records that do not meet conditions are flagged but still included in the pipeline.
Drop violations (expect_or_drop) -> records that do not meet conditions are excluded from downstream tables.
Fail pipeline on violations (expect_or_fail) -> records that fail conditions stop the pipeline.
In this scenario, the requirement explicitly states that invalid records (where customer_id is null or amount < 0) must be dropped. According to the official documentation, the correct method is .expect_or_drop("expectation_name", "SQL_predicate") applied on the streaming input.
Option A is correct: It uses .expect_or_drop directly within the transformation chain for both rules, ensuring records that fail are removed before writing to the silver table.
Option B incorrectly uses @dlt.expect decorators, which only track violations but do not drop invalid rows.
Option C uses .expect, which also only flags rows, not drop them.
Option D uses @dlt.expect_or_drop decorator syntax, which is not supported in Python API; expect_or_drop must be applied as a method on the DataFrame, not as a decorator.
Therefore, the correct solution is Option A, which ensures compliance by enforcing data quality and dropping invalid rows programmatically during ingestion.
NEW QUESTION # 44
......
Contending for the success fruit of Certified-Data-Engineer-Professional practice exam, many customers have been figuring out the effective ways to pass it. Due to the shortage of useful practice materials or being scanty for them, we listed these traits of our Certified-Data-Engineer-Professional practice materials. Actually, some practice materials are shooting the breeze about their effectiveness, but our Certified-Data-Engineer-Professional practice materials are real high quality Certified-Data-Engineer-Professional practice materials with passing rate up to 98 to 100 percent.
Training Certified-Data-Engineer-Professional For Exam: https://www.newpassleader.com/Databricks/Certified-Data-Engineer-Professional-exam-preparation-materials.html
- Updated New Certified-Data-Engineer-Professional Exam Experience, Ensure to pass the Certified-Data-Engineer-Professional Exam 🦼 Download ⏩ Certified-Data-Engineer-Professional ⏪ for free by simply entering ☀ www.practicevce.com ️☀️ website 🚔Certified-Data-Engineer-Professional Latest Exam Online
- Popular Certified-Data-Engineer-Professional Exams 🎼 Certification Certified-Data-Engineer-Professional Test Answers 📲 Dumps Certified-Data-Engineer-Professional Questions 🏜 The page for free download of 「 Certified-Data-Engineer-Professional 」 on ▛ www.pdfvce.com ▟ will open immediately 🥣Exam Certified-Data-Engineer-Professional Duration
- 2026 New Certified-Data-Engineer-Professional Exam Experience - Databricks Databricks Certified Data Engineer Professional - The Best Training Certified-Data-Engineer-Professional For Exam 🥠 Simply search for ✔ Certified-Data-Engineer-Professional ️✔️ for free download on ➽ www.vce4dumps.com 🢪 🆓Latest Certified-Data-Engineer-Professional Test Pdf
- Reliable Certified-Data-Engineer-Professional Test Dumps 🐔 Certified-Data-Engineer-Professional Valid Dumps Book 👛 Certified-Data-Engineer-Professional Valid Test Questions ⛅ ✔ www.pdfvce.com ️✔️ is best website to obtain ➠ Certified-Data-Engineer-Professional 🠰 for free download 🏃Popular Certified-Data-Engineer-Professional Exams
- High Pass-Rate New Certified-Data-Engineer-Professional Exam Experience Spend Your Little Time and Energy to Clear Certified-Data-Engineer-Professional exam easily 👏 Immediately open ⮆ www.torrentvce.com ⮄ and search for ➤ Certified-Data-Engineer-Professional ⮘ to obtain a free download 🐎Certified-Data-Engineer-Professional Valid Test Questions
- Free Certified-Data-Engineer-Professional Exam Dumps 🤵 Certification Certified-Data-Engineer-Professional Test Answers 〰 Certified-Data-Engineer-Professional Exam Certification Cost 🍈 Open website ⮆ www.pdfvce.com ⮄ and search for ➽ Certified-Data-Engineer-Professional 🢪 for free download ↕Certified-Data-Engineer-Professional Valid Test Questions
- {Enjoy 50% Discount} On Databricks Certified-Data-Engineer-Professional Questions With {Free 365-days Updates} 🦚 Enter [ www.pdfdumps.com ] and search for [ Certified-Data-Engineer-Professional ] to download for free 🔀Exam Certified-Data-Engineer-Professional Duration
- Certified-Data-Engineer-Professional Test Objectives Pdf ✉ Prep Certified-Data-Engineer-Professional Guide 🏋 Certified-Data-Engineer-Professional Test Objectives Pdf 🌇 ➠ www.pdfvce.com 🠰 is best website to obtain ✔ Certified-Data-Engineer-Professional ️✔️ for free download 🔘Test Certified-Data-Engineer-Professional Study Guide
- Certification Certified-Data-Engineer-Professional Test Answers 🦟 Free Certified-Data-Engineer-Professional Exam Dumps 🧮 Test Certified-Data-Engineer-Professional Study Guide 🥧 The page for free download of 《 Certified-Data-Engineer-Professional 》 on 【 www.practicevce.com 】 will open immediately 🅰Certified-Data-Engineer-Professional Reliable Braindumps Free
- Test Certified-Data-Engineer-Professional Study Guide 🥺 Certified-Data-Engineer-Professional Exam Outline 📘 Certified-Data-Engineer-Professional Actual Exam 🚪 Search for ⮆ Certified-Data-Engineer-Professional ⮄ and download it for free immediately on ✔ www.pdfvce.com ️✔️ 🛳Popular Certified-Data-Engineer-Professional Exams
- Certification Certified-Data-Engineer-Professional Test Answers ✨ Test Certified-Data-Engineer-Professional Study Guide 🐊 Certified-Data-Engineer-Professional Brain Dumps 🚁 Copy URL 【 www.pdfdumps.com 】 open and search for ⏩ Certified-Data-Engineer-Professional ⏪ to download for free 🐺Certified-Data-Engineer-Professional Brain Dumps
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes