100% Pass 2026 Databricks Databricks-Certified-Data-Analyst-Associate: Databricks Certified Data Analyst Associate Exam–The Best Dumps Cost

P.S. Free & New Databricks-Certified-Data-Analyst-Associate dumps are available on Google Drive shared by DumpsFree: https://drive.google.com/open?id=1NowCbuMLT2Gmy0NCVCS3ZjYose5A5Xjm
If you want to walk into the test center with confidence, you should prepare well for Databricks-Certified-Data-Analyst-Associate certification. While, where to get the accurate and valid Databricks study pdf is another question puzzling you. Now, Databricks-Certified-Data-Analyst-Associate sure pass exam will help you step ahead in the real exam and assist you get your Databricks-Certified-Data-Analyst-Associate Certification easily. Our Databricks-Certified-Data-Analyst-Associate test questions answers will provide the best valid and accurate knowledge for you and give you right reference. You will successfully pass your actual test with the help of our high quality and high hit-rate Databricks-Certified-Data-Analyst-Associate study torrent.
Databricks Databricks-Certified-Data-Analyst-Associate Exam Overview:
>> Dumps Databricks-Certified-Data-Analyst-Associate Cost <<
Latest Databricks-Certified-Data-Analyst-Associate Exam Forum, New Databricks-Certified-Data-Analyst-Associate Test Simulator
You can practice all the difficulties and hurdles which could be faced in an actual Databricks exam. It also assists you in boosting confidence and reducing problem-solving time. The Pass4future designs Databricks-Certified-Data-Analyst-Associate desktop-based practice software for desktops, so you can install it from a website and then use it without an internet connection. You only need an internet connection to verify the license of the products. No other plugins are required to employ it.
| Topic | Details |
|---|
| Topic 1 | - Data Visualization and Dashboarding: Sub-topics of this topic are about of describing how notifications are sent, how to configure and troubleshoot a basic alert, how to configure a refresh schedule, the pros and cons of sharing dashboards, how query parameters change the output, and how to change the colors of all of the visualizations. It also discusses customized data visualizations, visualization formatting, Query Based Dropdown List, and the method for sharing a dashboard.
|
| Topic 2 | - Databricks SQL: This topic discusses key and side audiences, users, Databricks SQL benefits, complementing a basic Databricks SQL query, schema browser, Databricks SQL dashboards, and the purpose of Databricks SQL endpoints
- warehouses. Furthermore, the delves into Serverless Databricks SQL endpoint
- warehouses, trade-off between cluster size and cost for Databricks SQL endpoints
- warehouses, and Partner Connect. Lastly it discusses small-file upload, connecting Databricks SQL to visualization tools, the medallion architecture, the gold layer, and the benefits of working with streaming data.
|
| Topic 3 | - Data Management: The topic describes Delta Lake as a tool for managing data files, Delta Lake manages table metadata, benefits of Delta Lake within the Lakehouse, tables on Databricks, a table owner’s responsibilities, and the persistence of data. It also identifies management of a table, usage of Data Explorer by a table owner, and organization-specific considerations of PII data. Lastly, the topic it explains how the LOCATION keyword changes, usage of Data Explorer to secure data.
|
| Topic 4 | - Analytics applications: It describes key moments of statistical distributions, data enhancement, and the blending of data between two source applications. Moroever, the topic also explains last-mile ETL, a scenario in which data blending would be beneficial, key statistical measures, descriptive statistics, and discrete and continuous statistics.
|
| Topic 5 | - SQL in the Lakehouse: It identifies a query that retrieves data from the database, the output of a SELECT query, a benefit of having ANSI SQL, access, and clean silver-level data. It also compares and contrasts MERGE INTO, INSERT TABLE, and COPY INTO. Lastly, this topic focuses on creating and applying UDFs in common scaling scenarios.
|
Databricks Certified Data Analyst Associate Exam Sample Questions (Q95-Q100):
NEW QUESTION # 95
Data engineers and data analysts are working together on a data pipeline. The data engineer is working on the raw, bronze, and silver layers of the pipeline using Python, and the data analyst is working on the gold layer of the pipeline using SQL. The raw source of the pipeline is a streaming input. They now want to migrate their pipeline to use Delta Live Tables.
Which of the following changes will need to be made to the pipeline when migrating to Delta Live Tables?
- A. The pipeline will need to be written entirely in Python.
- B. The pipeline will need to be written entirely in SQL.
- C. The pipeline will need to use a batch source in place of a streaming source.
- D. The pipeline can have different notebook sources in SQL and Python.
Answer: D
Explanation:
Option A is correct. Delta Live Tables, now documented under Lakeflow Declarative Pipelines, supports both Python and SQL source files in the same pipeline. The pipeline does not need to be rewritten entirely in one language, and it can still use streaming inputs. Official Databricks extract: "You can add Python and SQL source files to the same pipeline." The same documentation also shows examples for batch and streaming reads in Python and SQL.
NEW QUESTION # 96
A data engineer needs to use a Delta table as part of a data pipeline, but they do not know if they have the appropriate permissions.
In which of the following locations can the data engineer review their permissions on the table?
- A. Data Explorer
- B. Databricks Filesystem
- C. Repos
- D. Jobs
- E. Dashboards
Answer: A
Explanation:
Option E is correct. In the current Databricks UI, Data Explorer is known as Catalog Explorer. It is the location used to browse catalogs, schemas, tables, and views, review object metadata, and request or inspect access-related information. DBFS, Jobs, Dashboards, and Repos are not the table-permission review location.
Official Databricks extract: users can navigate the catalog tree, open an object's page, and request additional privileges from Catalog Explorer.
NEW QUESTION # 97
Consider the following two statements:
Statement 1:
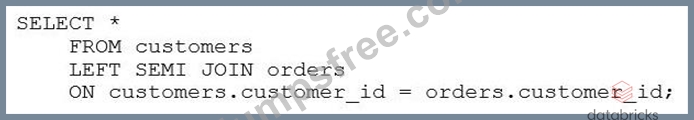
Statement 2:

Which of the following describes how the result sets will differ for each statement when they are run in Databricks SQL?
- A. Both statements will fail because Databricks SQL does not support those join types.
- B. There is no difference between the result sets for both statements.
- C. When the first statement is run, only rows from the customers table that have at least one match with the orders table on customer_id will be returned. When the second statement is run, only those rows in the customers table that do not have at least one match with the orders table on customer_id will be returned.
- D. The first statement will return all data from the customers table and matching data from the orders table. The second statement will return all data from the orders table and matching data from the customers table. Any missing data will be filled in with NULL.
- E. When the first statement is run, all rows from the customers table will be returned and only the customer_id from the orders table will be returned. When the second statement is run, only those rows in the customers table that do not have at least one match with the orders table on customer_id will be returned.
Answer: C
Explanation:
Based on the images you sent, the two statements are SQL queries for different types of joins between the customers and orders tables. A join is a way of combining the rows from two table references based on some criteria. The join type determines how the rows are matched and what kind of result set is returned. The first statement is a query for a LEFT SEMI JOIN, which returns only the rows from the left table reference (customers) that have a match with the right table reference (orders) on the join condition (customer_id). The second statement is a query for a LEFT ANTI JOIN, which returns only the rows from the left table reference (customers) that have no match with the right table reference (orders) on the join condition (customer_id). Therefore, the result sets for the two statements will differ in the following way:
The first statement will return a subset of the customers table that contains only the customers who have placed at least one order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT SEMI JOIN does not include any columns from the orders table.
The second statement will return a subset of the customers table that contains only the customers who have not placed any order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have no orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT ANTI JOIN does not include any columns from the orders table.
The other options are not correct because:
A) The first statement will not return all data from the customers table, as it will exclude the customers who have no orders. The second statement will not return all data from the orders table, as it will exclude the orders that have a matching customer. Neither statement will fill in any missing data with NULL, as they do not return any columns from the other table.
C) There is a difference between the result sets for both statements, as explained above. The LEFT SEMI JOIN and the LEFT ANTI JOIN are not equivalent operations and will produce different outputs.
D) Both statements will not fail, as Databricks SQL does support those join types. Databricks SQL supports various join types, including INNER, LEFT OUTER, RIGHT OUTER, FULL OUTER, LEFT SEMI, LEFT ANTI, and CROSS. You can also use NATURAL, USING, or LATERAL keywords to specify different join criteria.
E) The first statement will not return only the customer_id from the orders table, as it will return all columns from the customers table. The second statement is correct, but it is not the only difference between the result sets.
NEW QUESTION # 98
In which of the following situations should a data analyst use higher-order functions?
- A. When custom logic needs to be applied at scale to array data objects
- B. When built-in functions need to run through the Catalyst Optimizer
- C. When custom logic needs to be converted to Python-native code
- D. When built-in functions are taking too long to perform tasks
- E. When custom logic needs to be applied to simple, unnested data
Answer: A
Explanation:
Higher-order functions are a simple extension to SQL to manipulate nested data such as arrays. A higher- order function takes an array, implements how the array is processed, and what the result of the computation will be. It delegates to a lambda function how to process each item in the array. This allows you to define functions that manipulate arrays in SQL, without having to unpack and repack them, use UDFs, or rely on limited built-in functions. Higher-order functions provide a performance benefit over user defined functions. References: Higher-order functions | Databricks on AWS, Working with Nested Data Using Higher Order Functions in SQL on Databricks | Databricks Blog, Higher-order functions - Azure Databricks | Microsoft Learn, Optimization recommendations on Databricks | Databricks on AWS
NEW QUESTION # 99
A data analyst wants the following output:
customer_name number_of_orders
John Doe 388
Zhang San 234
Which statement will produce this output?
- A. SELECT customer_name, count(order_id) AS number_of_orders
FROM customers
JOIN orders
ON customers.customer_id = orders.customer_id
GROUP BY customer_name; - B. SELECT customer_name, count(order_id) number_of_orders
FROM customers
JOIN orders
ON customers.customer_id = orders.customer_id USE customer_name; - C. SELECT customerjiame, count(order_id)
FROM customers
JOIN orders
ON customers.customer_id = orders.customer_id GROUP BY customerjiame; - D. SELECT customerjiame, (order_id) number_of_orders
FROM customers
JOIN orders
ON customers.customer_id = orders.customer_id;
Answer: A
NEW QUESTION # 100
......
Latest Databricks-Certified-Data-Analyst-Associate Exam Forum: https://www.dumpsfree.com/Databricks-Certified-Data-Analyst-Associate-valid-exam.html
- Free PDF Quiz High-quality Databricks - Databricks-Certified-Data-Analyst-Associate - Dumps Databricks Certified Data Analyst Associate Exam Cost 🥐 Enter ⏩ www.prepawaypdf.com ⏪ and search for ⮆ Databricks-Certified-Data-Analyst-Associate ⮄ to download for free 🏏Databricks-Certified-Data-Analyst-Associate Reliable Exam Sims
- Vce Databricks-Certified-Data-Analyst-Associate Free 🚋 Databricks-Certified-Data-Analyst-Associate Dump Torrent 🗨 Latest Databricks-Certified-Data-Analyst-Associate Exam Cost 🚞 Open ▛ www.pdfvce.com ▟ enter ☀ Databricks-Certified-Data-Analyst-Associate ️☀️ and obtain a free download 🔝Databricks-Certified-Data-Analyst-Associate Dump Torrent
- Valid Databricks-Certified-Data-Analyst-Associate Test Blueprint 😨 Vce Databricks-Certified-Data-Analyst-Associate Free 🌮 Databricks-Certified-Data-Analyst-Associate Valid Exam Syllabus 💄 Easily obtain free download of ⇛ Databricks-Certified-Data-Analyst-Associate ⇚ by searching on ▷ www.easy4engine.com ◁ 🦛Valid Databricks-Certified-Data-Analyst-Associate Test Blueprint
- 2026 Databricks-Certified-Data-Analyst-Associate – 100% Free Dumps Cost | Pass-Sure Latest Databricks-Certified-Data-Analyst-Associate Exam Forum 🎪 Search on ➡ www.pdfvce.com ️⬅️ for 《 Databricks-Certified-Data-Analyst-Associate 》 to obtain exam materials for free download 🍣Databricks-Certified-Data-Analyst-Associate New Exam Braindumps
- Verified Dumps Databricks-Certified-Data-Analyst-Associate Cost - Guaranteed Databricks Databricks-Certified-Data-Analyst-Associate Exam Success with Trustable Latest Databricks-Certified-Data-Analyst-Associate Exam Forum 🚦 Immediately open “ www.prepawaypdf.com ” and search for ➽ Databricks-Certified-Data-Analyst-Associate 🢪 to obtain a free download 🔜Valid Databricks-Certified-Data-Analyst-Associate Test Blueprint
- Databricks-Certified-Data-Analyst-Associate New Exam Braindumps 🎈 New Databricks-Certified-Data-Analyst-Associate Exam Test 🐺 New Databricks-Certified-Data-Analyst-Associate Braindumps 🚐 Immediately open ➤ www.pdfvce.com ⮘ and search for ▷ Databricks-Certified-Data-Analyst-Associate ◁ to obtain a free download 🤴New Databricks-Certified-Data-Analyst-Associate Exam Pattern
- Free PDF Quiz Databricks - Databricks-Certified-Data-Analyst-Associate - Databricks Certified Data Analyst Associate Exam Useful Dumps Cost 🍐 Copy URL [ www.practicevce.com ] open and search for ▶ Databricks-Certified-Data-Analyst-Associate ◀ to download for free 🍭Databricks-Certified-Data-Analyst-Associate Valid Exam Camp Pdf
- Databricks-Certified-Data-Analyst-Associate Reliable Exam Preparation 💑 Latest Databricks-Certified-Data-Analyst-Associate Exam Forum 👄 New Databricks-Certified-Data-Analyst-Associate Exam Test 📷 Immediately open ▷ www.pdfvce.com ◁ and search for ▛ Databricks-Certified-Data-Analyst-Associate ▟ to obtain a free download 🌆Databricks-Certified-Data-Analyst-Associate Pass Exam
- Databricks-Certified-Data-Analyst-Associate Dump Torrent 🕸 Databricks-Certified-Data-Analyst-Associate Pass Exam 🔝 New Databricks-Certified-Data-Analyst-Associate Braindumps 🎀 Open ⏩ www.practicevce.com ⏪ and search for “ Databricks-Certified-Data-Analyst-Associate ” to download exam materials for free 🐺Latest Databricks-Certified-Data-Analyst-Associate Exam Cost
- Verified Dumps Databricks-Certified-Data-Analyst-Associate Cost - Guaranteed Databricks Databricks-Certified-Data-Analyst-Associate Exam Success with Trustable Latest Databricks-Certified-Data-Analyst-Associate Exam Forum 🕸 Download ▷ Databricks-Certified-Data-Analyst-Associate ◁ for free by simply entering ➤ www.pdfvce.com ⮘ website 👡Databricks-Certified-Data-Analyst-Associate Reliable Exam Sims
- Databricks-Certified-Data-Analyst-Associate Pass Exam 🌇 Latest Databricks-Certified-Data-Analyst-Associate Exam Forum 🤝 Vce Databricks-Certified-Data-Analyst-Associate Free 🔢 Search for ⏩ Databricks-Certified-Data-Analyst-Associate ⏪ and download it for free immediately on ➤ www.prep4away.com ⮘ 🎲New Databricks-Certified-Data-Analyst-Associate Braindumps
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, vrcmods.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
DOWNLOAD the newest DumpsFree Databricks-Certified-Data-Analyst-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1NowCbuMLT2Gmy0NCVCS3ZjYose5A5Xjm