Certified-Data-Engineer-Professional資訊 - Certified-Data-Engineer-Professional考試心得

KaoGuTi的專家團隊利用他們的經驗和知識終於研究出了關於Databricks Certified-Data-Engineer-Professional 認證考試的培訓資料。我們的Databricks Certified-Data-Engineer-Professional 認證考試培訓資料很受客戶歡迎,這是KaoGuTi的專家團隊勤勞勞動的結果。他們研究出來的模擬測試題及答案有很高的品質,和真實的考試題目有95%的相似性,是很值得你依賴的。如果你使用了KaoGuTi的培訓工具,你可以100%通過你的第一次參加的Databricks Certified-Data-Engineer-Professional認證考試。
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 2. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 3. Compare streaming tables and materialized views
- 4. Configure environments, dependencies, memory, and retry behavior
- 5. Use control flow operators in pipeline components
- 6. Use APPLY CHANGES APIs for change data capture
- 7. Develop unit and integration tests for data processing code
- 8. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
|
| Topic 2: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Ingest data from message buses and cloud storage
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Topic 3: Monitoring and Alerting | - Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
- Monitoring
- 1. Use system tables for resource, cost, audit, and workload monitoring
- 2. Use Query Profiler and Spark UI to monitor workloads
- 3. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 4. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
|
| Topic 4: Cost & Performance Optimisation | - Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Understand deletion vectors and liquid clustering
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
|
| Topic 5: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 6: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
|
| Topic 7: Data Modelling | - Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Optimize data layout using Liquid Clustering
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Topic 8: Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Use ACLs to secure workspace objects and enforce least privilege
- 2. Use row filters and column masks for sensitive data
- 3. Apply anonymization and pseudonymization techniques
|
| Topic 9: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
|
| Topic 10: Data Sharing and Federation | - Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure Databricks-to-Databricks Sharing
- 3. Configure sharing with external platforms using the open sharing protocol
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
>> Certified-Data-Engineer-Professional資訊 <<
已驗證的Certified-Data-Engineer-Professional資訊和資格考試領導者和可靠的Certified-Data-Engineer-Professional:Databricks Certified Data Engineer Professional
由于IT行業的競爭力近年來有所增加,如果您需要提升自己的職業發展道路,Databricks Certified-Data-Engineer-Professional認證就成為基本的選擇條件之一。而通過Certified-Data-Engineer-Professional考試被視為獲得此認證最關鍵的方法,該認證不斷可以增加您的就業機會,還為您提供了無數新的可能。所有考生都知道我們的Databricks Certified-Data-Engineer-Professional考古題產品可以幫助您快速掌握考試知識點,無需參加其它的培訓課程,就可以保證您高分通過Certified-Data-Engineer-Professional考試。
最新的 Databricks Certification Certified-Data-Engineer-Professional 免費考試真題 (Q48-Q53):
問題 #48
A healthcare analytics team is implementing a dimensional model in Delta Lake for patient care analysis. They have a date dimension table and are evaluating design options to ensure it supports a wide range of time-based analyses. Which design approach for the date dimension will support efficient time-based querying and aggregation?
- A. Create separate dimension tables for different calendar systems (fiscal, academic, etc.)
- B. Store only the date value and calculate all time attributes in queries.
- C. Pre-calculate attributes like fiscal_period, quarter, month_name, day_of_week, and holiday.
- D. Store the date as string in ISO format (YYYY-MM-DD) for readability.
答案:C
解題說明:
Pre-calculating commonly used time attributes in the date dimension enables efficient filtering, grouping, and aggregation without requiring repeated computations at query time. This design supports a wide range of time-based analyses and improves query performance and usability in dimensional models.
問題 #49
A data engineer is implementing Unity Catalog governance for a multi-team environment. Data scientists need interactive clusters for basic data exploration tasks, while automated ETL jobs require dedicated processing. How should the data engineer configure cluster isolation policies to enforce least privilege and ensure Unity Catalog compliance?
- A. Configure all clusters with NO ISOLATION_SHARED access mode since Unity Catalog works with any cluster configuration.
- B. Allow all users to create any cluster type and rely on manual configuration to enable Unity Catalog access modes.
- C. Use only DEDICATED access mode for both interactive workloads and automated jobs to maximize security isolation.
- D. Create compute policies with STANDARD access mode for interactive workloads and DEDICATED access mode for automated jobs.
答案:D
解題說明:
Unity Catalog enforces governance and data isolation through cluster access modes and compute policies. According to Databricks documentation, "Interactive clusters that multiple users share should use Standard access mode, while automated jobs and production pipelines should use Dedicated access mode for stricter isolation." Standard access mode allows multiple users to share the same compute resources but still respects Unity Catalog permissions. Dedicated access mode isolates the job run's execution environment, ensuring that data access is limited to the job's identity. Configuring these modes within compute policies enforces least privilege and ensures all compute complies with Unity Catalog security standards. Options A and C are incorrect because using only Dedicated clusters reduces resource efficiency, while "No isolation" clusters are not Unity Catalog compliant.
問題 #50
A data engineering team is implementing an append-only data pipeline using Delta Lake, and wants to ensure that data is never modified or deleted once written. Which Delta Lake feature should the data engineer enable to prevent modifications to existing data?
- A. Delta APPEND_ONLY
- B. Delta OPTIMIZE
- C. Delta VACUUM
- D. Delta Time Travel
答案:A
解題說明:
Enabling the append-only table property enforces that data can only be inserted into the Delta table. Updates and deletes are blocked, ensuring that once data is written it is never modified or removed, which is essential for strict append-only pipeline guarantees.
問題 #51
Review the following error traceback:
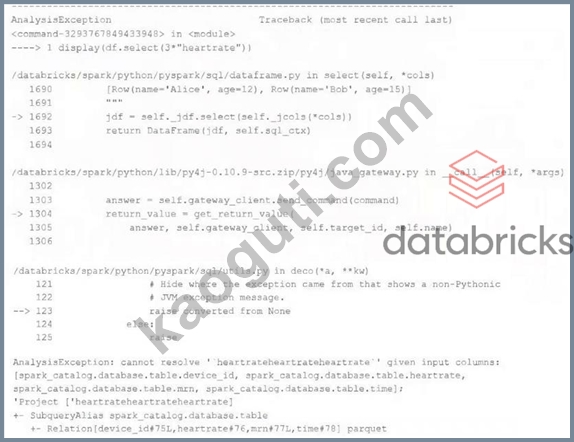
Which statement describes the error being raised?
- A. There is a syntax error because the heartrate column is not correctly identified as a column.
- B. The code executed was PvSoark but was executed in a Scala notebook.
- C. There is no column in the table named heartrateheartrateheartrate
- D. There is a type error because a DataFrame object cannot be multiplied.
- E. There is a type error because a column object cannot be multiplied.
答案:C
解題說明:
https://sparkbyexamples.com/spark/spark-cannot-resolve-given-input-columns/
問題 #52
A data engineer needs to create an application that will collect information about the latest job run including the repair history. How should the data engineer format the request?
- A. Call/api/2.1/jobs/runs/get with the run_id and include_history parameters
- B. Call/api/2.1/jobs/runs/list with the job_id and include_history parameters
- C. Call/api/2.1/jobs/runs/list with the run_id and include_history parameters
- D. Call/api/2.1/jobs/runs/get with the job_id and include_history parameters
答案:B
解題說明:
To retrieve information about the latest job runs along with their repair history, you use the jobs/runs/list endpoint with the job_id and include_history=true. This endpoint returns a list of runs for a specific job, including details about retries and repair attempts, which is not available via runs/get that retrieves a single run by run_id.
問題 #53
......
我們KaoGuTi是一個優秀的IT認證資訊來源,在KaoGuTi裏,你可以找到為你認證考試的學習技巧以及學習材料,我們KaoGuTi Databricks的Certified-Data-Engineer-Professional考試培訓資料是由經驗豐富和擁有長期學生經驗和他們的要求的IT專業人士研究出來的培訓資料,內容精確性和邏輯性特別強,遇到KaoGuTi,你將遇到最好的培訓資料,放心使用我們的KaoGuTi Databricks的Certified-Data-Engineer-Professional考試培訓資料,有了它你就已經做好了充分的準備來迎接這個認證考試。
Certified-Data-Engineer-Professional考試心得: https://www.kaoguti.com/Certified-Data-Engineer-Professional_exam-pdf.html
- Certified-Data-Engineer-Professional題庫資訊 🤼 Certified-Data-Engineer-Professional證照指南 🥘 Certified-Data-Engineer-Professional熱門認證 🍬 立即在▷ www.pdfexamdumps.com ◁上搜尋⇛ Certified-Data-Engineer-Professional ⇚並免費下載最新Certified-Data-Engineer-Professional考題
- Certified-Data-Engineer-Professional考試題庫 🥬 Certified-Data-Engineer-Professional題庫資訊 🌕 Certified-Data-Engineer-Professional認證題庫 📴 在⮆ www.newdumpspdf.com ⮄網站下載免費➥ Certified-Data-Engineer-Professional 🡄題庫收集Certified-Data-Engineer-Professional考試證照
- 最有效的Certified-Data-Engineer-Professional資訊-最新考試題庫幫助妳壹次性通過考試Certified-Data-Engineer-Professional:Databricks Certified Data Engineer Professional ⛹ 《 www.newdumpspdf.com 》上的免費下載⮆ Certified-Data-Engineer-Professional ⮄頁面立即打開Certified-Data-Engineer-Professional認證題庫
- Certified-Data-Engineer-Professional題庫資料 👿 最新Certified-Data-Engineer-Professional考題 🍬 Certified-Data-Engineer-Professional考題套裝 🎷 ▶ www.newdumpspdf.com ◀上的免費下載▛ Certified-Data-Engineer-Professional ▟頁面立即打開Certified-Data-Engineer-Professional題庫分享
- Certified-Data-Engineer-Professional認證考試的新考古題匯總 📠 ➽ www.vcesoft.com 🢪提供免費▛ Certified-Data-Engineer-Professional ▟問題收集Certified-Data-Engineer-Professional權威認證
- Certified-Data-Engineer-Professional證照指南 🐳 Certified-Data-Engineer-Professional權威認證 🪀 Certified-Data-Engineer-Professional考試證照 📄 到( www.newdumpspdf.com )搜尋☀ Certified-Data-Engineer-Professional ️☀️以獲取免費下載考試資料Certified-Data-Engineer-Professional證照指南
- 高通過率的Databricks Certified-Data-Engineer-Professional資訊&Trustable tw.fast2test.com - 資格考試中的領先提供商 🛑 在➡ tw.fast2test.com ️⬅️搜索最新的( Certified-Data-Engineer-Professional )題庫Certified-Data-Engineer-Professional認證指南
- 最新Certified-Data-Engineer-Professional考古題 🥾 Certified-Data-Engineer-Professional考試題庫 👉 Certified-Data-Engineer-Professional認證題庫 ❇ 透過☀ www.newdumpspdf.com ️☀️輕鬆獲取{ Certified-Data-Engineer-Professional }免費下載Certified-Data-Engineer-Professional證照資訊
- Certified-Data-Engineer-Professional PDF題庫 🧘 Certified-Data-Engineer-Professional熱門認證 🚐 Certified-Data-Engineer-Professional考試題庫 🌎 立即打開⇛ www.vcesoft.com ⇚並搜索➡ Certified-Data-Engineer-Professional ️⬅️以獲取免費下載Certified-Data-Engineer-Professional考試證照
- Certified-Data-Engineer-Professional熱門認證 💑 Certified-Data-Engineer-Professional考試證照 💝 Certified-Data-Engineer-Professional權威認證 🥣 ➡ www.newdumpspdf.com ️⬅️最新“ Certified-Data-Engineer-Professional ”問題集合Certified-Data-Engineer-Professional學習筆記
- Certified-Data-Engineer-Professional題庫分享 🛰 Certified-Data-Engineer-Professional題庫分享 ✏ Certified-Data-Engineer-Professional證照資訊 🏎 ▶ www.vcesoft.com ◀提供免費[ Certified-Data-Engineer-Professional ]問題收集Certified-Data-Engineer-Professional認證題庫
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes