What's more, part of that ITCertMagic SPS-C01 dumps now are free: https://drive.google.com/open?id=14hQR5S57nIcJqEb5v3nD2V3qrUN_SqiO
The most important is that you just only need to spend 20 to 30 hours on practicing SPS-C01 exam questions before you take the exam, therefore you can arrange your time to balance learning and other things. Of course, you care more about your test pass rate. We offer you more than 99% pass guarantee if you are willing to use our SPS-C01 test guide and follow our plan of learning. If you fail to pass the exam with our Snowflake Certified SnowPro Specialty - Snowpark torrent prep, you will get a full refund. However, if you want to continue studying our course, you can still enjoy comprehensive services through SPS-C01 Torrent prep. We will update relevant learning materials in time .And we guarantee that you can enjoy a discount of more than one year.
| Section | Weight | Objectives |
|---|---|---|
| Snowpark API for Python | 30% | - User-Defined Functions (UDFs) and Stored Procedures - Establishing connections and session management - DataFrame creation and manipulation - Working with Semi-structured data - Reading and writing data |
| Data Transformations and DataFrame Operations | 35% | - Complex data pipelines - Window functions - Using built-in functions - Persisting transformed data - Filtering, Aggregating, and Joining DataFrames |
| Performance Optimization and Best Practices | 20% | - Query pushdown and optimization - Minimizing data transfer - Vectorized UDFs - Caching strategies - Warehouse sizing for Snowpark - Debugging and explain plans |
| Snowpark Concepts | 15% | - Snowpark DataFrames and query plans - Client-side vs. Server-side execution - Snowpark architecture and core concepts - Transformations vs. Actions - Snowpark Sessions and connection management - Stored procedures and conditional logic |
>> Snowflake SPS-C01 Valid Test Preparation <<
We can assist you with learning by simplified information by our SPS-C01 learning guide. At the same time, our specialists will update SPS-C01 learning materials daily and continue to improve the materials. Therefore, you can use our SPS-C01 exam questions faster and more efficiently, which means that you can save a lot of time to do more meaningful and valuable things. When you are learning our SPS-C01 Learning Materials, you can find confidence in the process of learning materials and feel happy in learning. After about 20-30 hours, you can get your Snowflake certificate.
NEW QUESTION # 233
A data engineering team is developing a Snowpark stored procedure in Python to perform anomaly detection on time-series data stored in a Snowflake table named 'sensor_readingS. The stored procedure needs to efficiently process large volumes of data and return only the rows identified as anomalies. Which of the following approaches would provide the most performant and scalable solution for operationalizing this stored procedure?
Answer: D
Explanation:
Option B is the most performant and scalable. It leverages Snowpark's distributed processing to perform the anomaly detection calculations directly on the Snowflake data, avoiding the overhead of transferring large datasets to Pandas DataFrames or using inefficient Python loops. Using a SQL Query inside the stored procedure would work but not as efficient as Snowpark dataframes that are lazy executed. Transferring data into a pandas dataframe is also inefficient as it reduces Snowflake's ability to perform the computation inside Snowflake's distributed framework. Lastly a Scala UDF would still require data transfer between Snowpark and Scala, which makes it ineffecient.
NEW QUESTION # 234
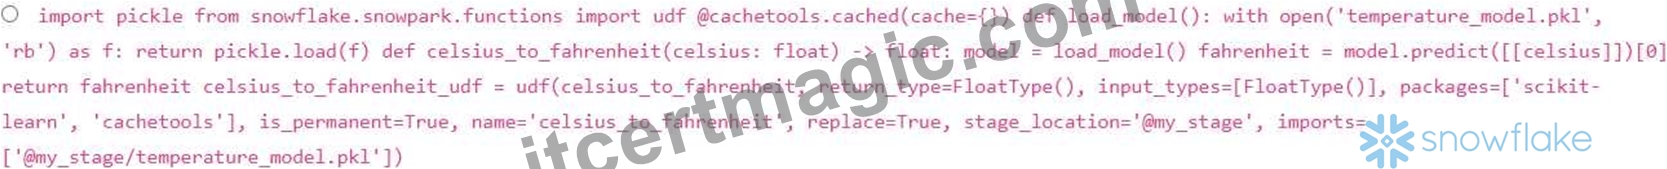
You are developing a Snowpark application to process sensor data'. You need to define a UDF that converts temperature readings from Celsius to Fahrenheit. However, the conversion formula is computationally intensive and requires access to a pre-trained machine learning model stored as a resource in a stage. Given the following considerations, what is the most efficient and correct way to define this UDF? The model file is named 'temperature_model.pkl'.



Answer: C
Explanation:
Option C is the most efficient and correct way. It correctly uses the 'imports' parameter in the @sf.UDF decorator to specify the location of the model file in the stage. This ensures that the model file is available to the UDF at runtime. Options A and B attempts to open the file without properly importing, and would fail. Option D includes caching, which is good for frequently called functions with the same input, but the primary issue lies in correctly importing the model from the stage. Using caching is also possible, but it is not required. Option C is the most direct and correct approach to fulfilling the prompt's requirements. The other options will result in errors or are less efficient.
NEW QUESTION # 235
You are developing a Snowpark application to process sales data. The application uses a UDF that calls an external Python library with a large memory footprint. After deploying the application, you observe that the Snowflake warehouse frequently runs out of memory, causing the application to fail. Which of the following strategies would be MOST effective in mitigating this issue, while minimizing cost and maintaining performance? Assume the data volume is relatively large and the UDF is computationally intensive.
Answer: C
Explanation:
Option B is the most effective and cost-efficient solution. Processing data in smaller batches using a generator pattern within the UDF will significantly reduce memory consumption without requiring a larger, more expensive warehouse. Option A is a brute-force approach that increases costs unnecessarily. Option C might help, but batching provides more reliable memory control. Option D involves significant code rewriting and might not guarantee a substantial memory reduction, especially if the Python library is inherently memory-intensive. Option E doesn't inherently solve the memory issue if the underlying UDF's memory usage remains high.
NEW QUESTION # 236
You have a Snowpark application that reads data from a large Snowflake table and performs several transformations. During testing, you observe that the application's performance is inconsistent, with some runs taking significantly longer than others, even with the same input data'. You suspect that data locality might be a contributing factor. What steps can you take within your Snowpark application to investigate and potentially improve data locality and performance consistency?
Answer: C,D,E
Explanation:
'DataFrame.repartition(V allows you to redistribute data based on a chosen key, improving locality for operations that depend on that key. Snowflake's automatic clustering physically organizes data on disk, improving read performance. Combining with repartition()' ensures that frequently accessed, well-partitioned data is readily available in memory close to the processing nodes, boosting performance. Disabling the cache makes the application's performance worse. The warehouse size, if not large enough, can also lead to data spilling to disk, decreasing the performance.
NEW QUESTION # 237
You have a Snowpark Python application that reads data from a Snowflake table, performs several transformations, and then writes the results back to a new Snowflake table. The transformations involve complex calculations and aggregations. During testing, you observe that the application is consuming a significant amount of credits. Which of the following optimization strategies would be MOST effective in reducing the credit consumption of your Snowpark application?
Answer: B,E
Explanation:
Converting Python UDFs to Java UDTFs can significantly improve performance and reduce credit consumption because Java UDTFs execute within the Snowflake engine. Minimizing data transfer by pushing down transformations and using stored procedures reduces the amount of data processed and transferred, thus reducing credit consumption. Disabling auto-scaling might reduce peak credit consumption but could also increase overall execution time and potentially increase costs if the warehouse is under-sized. Caching can help in some cases but introduces memory management complexities. Snowflake automatically handles index management and query optimization; explicitly specifying hints is generally not necessary and using cache might not be suitable for large datasets.
NEW QUESTION # 238
......
Only if you download our software and practice no more than 30 hours will you attend your test confidently. Because our SPS-C01 exam torrent can simulate limited-timed examination and online error correcting, it just takes less time and energy for you to prepare the SPS-C01 exam than other study materials. It is very economical that you just spend 20 or 30 hours then you have the SPS-C01 certificate in your hand, which is typically beneficial for your career in the future. Therefore, purchasing the SPS-C01 guide torrent is the best and wisest choice for you to prepare your test.
SPS-C01 Latest Braindumps Sheet: https://www.itcertmagic.com/Snowflake/real-SPS-C01-exam-prep-dumps.html
2026 Latest ITCertMagic SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=14hQR5S57nIcJqEb5v3nD2V3qrUN_SqiO