Databricks-Certified-Professional-Data-Engineer Exam Course - Databricks-Certified-Professional-Data-Engineer Valid Mock Test

BTW, DOWNLOAD part of ExamsLabs Databricks-Certified-Professional-Data-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1ONtgrg4F6cwX9ErWr4KVxsmpPQiWJoyx
The selection of proper training material is a promising method to pass Databricks Databricks-Certified-Professional-Data-Engineer exam. No quality, no success. ExamsLabs Databricks Databricks-Certified-Professional-Data-Engineer questions and answers consist of perfect exam simulations, real test questions and accurate test answers. Our ExamsLabs Databricks Databricks-Certified-Professional-Data-Engineer test provides high-quality products and improves after-sales service. If you spend a lot of time catching up, the way you choose is wrong. What is more serious is that you may fail. Please trust our ExamsLabs Databricks Databricks-Certified-Professional-Data-Engineer braindump. By selecting it, 100% guarantee to pass the exam.
| Section | Weight | Objectives |
|---|
| Delta Lake | 20-25% | - Delta Lake operations
- 1. Delta Live Tables
- 2. Merge, update, delete operations
- 3. Schema evolution and enforcement
- Delta Lake fundamentals
- 1. Time travel and data versioning
- 2. Optimize and Z-order
- 3. ACID transactions
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Task dependencies and orchestration
- 2. Monitoring and alerting
- 3. Jobs and job scheduling
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Data governance fundamentals
- 2. Bronze, silver, gold data layers
- 3. Differences between data lake, data warehouse, and lakehouse
|
| Data Ingestion | 15-20% | - Batch ingestion methods
- 1. DBR autoloader
- 2. Spark APIs for ingestion
- 3. Integration with external systems
- Streaming ingestion
- 1. Structured streaming fundamentals
- 2. Kafka integration
|
| Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
- 1. DataFrame operations and transformations
- 2. Spark SQL queries and functions
- 3. Window functions
- Python and SQL for data engineering
- 1. Spark APIs in Python
- 2. Built-in and user-defined functions
- 3. Performance optimization techniques
|
>> Databricks-Certified-Professional-Data-Engineer Exam Course <<
Get ExamsLabs Databricks Databricks-Certified-Professional-Data-Engineer Real Questions Today with Free Updates for 365 Days
Facing the incoming Databricks-Certified-Professional-Data-Engineer exam, you may feel stained and anxious, suspicious whether you could pass the exam smoothly and successfully. Actually, you must not impoverish your ambition. Our suggestions are never boggle at difficulties. It is your right time to make your mark. Preparation of exam without effective materials is just like a soldier without gun. You will be feeling be counteracted the effect of tension for our Databricks-Certified-Professional-Data-Engineer practice dumps can relieve you of the anxious feelings.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q213-Q218):
NEW QUESTION # 213
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings.
The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
- A. Tungsten encoding used by Databricks is optimized for storing string data: newly-added native support for querying JSON strings means that string types are always most efficient.
- B. Because Delta Lake uses Parquet for data storage, Dremel encoding information for nesting can be directly referenced by the Delta transaction log.
- C. Schema inference and evolution on Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
- D. By default Delta Lake collects statistics on the first 32 columns in a table; these statistics are leveraged for data skipping when executing selective queries.
Answer: D
Explanation:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. These statistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.References: Databricks documentation on Delta Lake optimization techniques, including data skipping and statistics collection (https://docs.databricks.com/delta/optimizations/index.html).
NEW QUESTION # 214
Which statement describes the default execution mode for Databricks Auto Loader?
- A. Webhook trigger Databricks job to run anytime new data arrives in a source directory; new data automatically merged into target tables using rules inferred from the data.
- B. New files are identified by listing the input directory; new files are incrementally and idempotently loaded into the target Delta Lake table.
- C. New files are identified by listing the input directory; the target table is materialized by directory querying all valid files in the source directory.
- D. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; new files are incrementally and impotently into the target Delta Lake table.
Answer: B
Explanation:
Databricks Auto Loader simplifies and automates the process of loading data into Delta Lake. The default execution mode of the Auto Loader identifies new files by listing the input directory. It incrementally and idempotently loads these new files into the target Delta Lake table. This approach ensures that files are not missed and are processed exactly once, avoiding data duplication. The other options describe different mechanisms or integrations that are not part of the default behavior of the Auto Loader.
References:
* Databricks Auto Loader Documentation: Auto Loader Guide
* Delta Lake and Auto Loader: Delta Lake Integration
NEW QUESTION # 215
John Smith is a newly joined team member in the Marketing team who currently has access read access to sales tables but does not have access to delete rows from the table, which of the following commands help you accomplish this?
- A. GRANT DELETE TO TABLE table_name ON john.smith@marketing.com
- B. GRANT USAGE ON TABLE table_name TO john.smith@marketing.com
- C. GRANT MODIFY TO TABLE table_name ON john.smith@marketing.com
- D. GRANT DELETE ON TABLE table_name TO john.smith@marketing.com
- E. GRANT MODIFY ON TABLE table_name TO john.smith@marketing.com
Answer: E
Explanation:
Explanation
The answer is GRANT MODIFY ON TABLE table_name TO john.smith@marketing.com , please note INSERT, UPDATE, and DELETE are combined into one role called MODIFY.
Below are the list of privileges that can be granted to a user or a group, SELECT: gives read access to an object.
CREATE: gives the ability to create an object (for example, a table in a schema).
MODIFY: gives the ability to add, delete, and modify data to or from an object.
USAGE: does not give any abilities, but is an additional requirement to perform any action on a schema object.
READ_METADATA: gives the ability to view an object and its metadata.
CREATE_NAMED_FUNCTION: gives the ability to create a named UDF in an existing catalog or schema.
MODIFY_CLASSPATH: gives the ability to add files to the Spark classpath.
ALL PRIVILEGES: gives all privileges (is translated into all the above privileges
NEW QUESTION # 216
A table named user_ltv is being used to create a view that will be used by data analysis on various teams.
Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
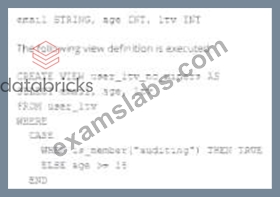
An analyze who is not a member of the auditing group executing the following query:
Which result will be returned by this query?
- A. All columns will be displayed normally for those records that have an age greater than 17; records not meeting this condition will be omitted.
- B. All records from all columns will be displayed with the values in user_ltv.
- C. All age values less than 18 will be returned as null values all other columns will be returned with the values in user_ltv.
- D. All columns will be displayed normally for those records that have an age greater than 18; records not meeting this condition will be omitted.
Answer: D
Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 217
You currently working with the marketing team to setup a dashboard for ad campaign analysis, since the team is not sure how often the dashboard should be refreshed they have decided to do a manual refresh on an as needed basis. Which of the following steps can be taken to reduce the overall cost of the compute when the team is not using the compute?
*Please note that Databricks recently change the name of SQL Endpoint to SQL Warehouses.
- A. They can turn on the Auto Stop feature for the SQL endpoint(SQL Warehouse).
- B. They can turn on the Serverless feature for the SQL endpoint(SQL Warehouse).
- C. They can decrease the maximum bound of the SQL endpoint(SQL Warehouse) scaling range.
- D. They can decrease the cluster size of the SQL endpoint(SQL Warehouse).
- E. They can turn on the Serverless feature for the SQL endpoint(SQL Warehouse) and change the Spot Instance Policy from "Reliability Optimized" to "Cost optimized"
Answer: A
Explanation:
Explanation
The answer is, They can turn on the Auto Stop feature for the SQL endpoint(SQL Warehouse).
Use auto stop to automatically terminate the cluster when you are not using it.
NEW QUESTION # 218
......
If you want to sharpen your skills, and get the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) certification done within the target period, it is important to get the best Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam questions. You must try the ExamsLabs Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) practice exam that will help you get the Databricks Databricks-Certified-Professional-Data-Engineer Certification. ExamsLabs hires the top industry experts to draft the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam dumps and help the candidates to clear their Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam easily. ExamsLabs plays a vital role in their journey to get the Databricks-Certified-Professional-Data-Engineer certification.
Databricks-Certified-Professional-Data-Engineer Valid Mock Test: https://www.examslabs.com/Databricks/Databricks-Certification/best-Databricks-Certified-Professional-Data-Engineer-exam-dumps.html
- Certification Databricks-Certified-Professional-Data-Engineer Exam 🐨 Databricks-Certified-Professional-Data-Engineer Practice Tests 🔻 Test Databricks-Certified-Professional-Data-Engineer Centres 🚘 Go to website ▶ www.practicevce.com ◀ open and search for “ Databricks-Certified-Professional-Data-Engineer ” to download for free 🎽Databricks-Certified-Professional-Data-Engineer Valid Exam Prep
- Databricks-Certified-Professional-Data-Engineer Mock Test 🍐 Test Databricks-Certified-Professional-Data-Engineer Sample Online 🕺 Databricks-Certified-Professional-Data-Engineer Reliable Study Notes 📬 Search for ( Databricks-Certified-Professional-Data-Engineer ) on ➤ www.pdfvce.com ⮘ immediately to obtain a free download 🍬Test Databricks-Certified-Professional-Data-Engineer Centres
- Unparalleled Databricks-Certified-Professional-Data-Engineer Exam Course - Guaranteed Databricks Databricks-Certified-Professional-Data-Engineer Exam Success with Efficient Databricks-Certified-Professional-Data-Engineer Valid Mock Test 💦 Open ➽ www.testkingpass.com 🢪 enter [ Databricks-Certified-Professional-Data-Engineer ] and obtain a free download ↕Pdf Demo Databricks-Certified-Professional-Data-Engineer Download
- New Release Databricks Databricks-Certified-Professional-Data-Engineer Dumps To Get Excellent Marks In Exam 2026 🐁 Download ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ for free by simply entering ⮆ www.pdfvce.com ⮄ website 🦨Test Databricks-Certified-Professional-Data-Engineer Quiz
- Quiz 2026 Databricks-Certified-Professional-Data-Engineer: Accurate Databricks Certified Professional Data Engineer Exam Exam Course 🔫 Copy URL 《 www.troytecdumps.com 》 open and search for { Databricks-Certified-Professional-Data-Engineer } to download for free 🍝Databricks-Certified-Professional-Data-Engineer Practice Tests
- Databricks-Certified-Professional-Data-Engineer Valid Exam Prep 🍿 Practice Databricks-Certified-Professional-Data-Engineer Test Engine 🧷 Test Databricks-Certified-Professional-Data-Engineer Centres 🧁 Easily obtain free download of 「 Databricks-Certified-Professional-Data-Engineer 」 by searching on 《 www.pdfvce.com 》 🚇Test Databricks-Certified-Professional-Data-Engineer Quiz
- Databricks-Certified-Professional-Data-Engineer Certification Questions 👣 Databricks-Certified-Professional-Data-Engineer Book Pdf 🏐 Databricks-Certified-Professional-Data-Engineer Book Pdf 💫 Go to website ⇛ www.exam4labs.com ⇚ open and search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ to download for free 😍Databricks-Certified-Professional-Data-Engineer Examcollection Vce
- Unparalleled Databricks-Certified-Professional-Data-Engineer Exam Course - Guaranteed Databricks Databricks-Certified-Professional-Data-Engineer Exam Success with Efficient Databricks-Certified-Professional-Data-Engineer Valid Mock Test 🔋 Download ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ for free by simply entering ➠ www.pdfvce.com 🠰 website 🚌Databricks-Certified-Professional-Data-Engineer Valid Exam Prep
- Databricks-Certified-Professional-Data-Engineer Mock Test 🏆 Download Databricks-Certified-Professional-Data-Engineer Demo 🪂 New Databricks-Certified-Professional-Data-Engineer Test Registration 🦙 Copy URL 《 www.exam4labs.com 》 open and search for ( Databricks-Certified-Professional-Data-Engineer ) to download for free 🕡Valid Databricks-Certified-Professional-Data-Engineer Exam Prep
- Download Databricks-Certified-Professional-Data-Engineer Demo 🧐 New Databricks-Certified-Professional-Data-Engineer Test Registration 🍆 Valid Databricks-Certified-Professional-Data-Engineer Exam Prep 🧧 Simply search for 「 Databricks-Certified-Professional-Data-Engineer 」 for free download on ⏩ www.pdfvce.com ⏪ 🖼Databricks-Certified-Professional-Data-Engineer Valid Exam Prep
- Databricks-Certified-Professional-Data-Engineer Exam Demo 🌄 Practice Databricks-Certified-Professional-Data-Engineer Test Engine 🟨 Databricks-Certified-Professional-Data-Engineer Demo Test 🥒 Copy URL ☀ www.prepawayexam.com ️☀️ open and search for ➽ Databricks-Certified-Professional-Data-Engineer 🢪 to download for free 🏭Databricks-Certified-Professional-Data-Engineer Examcollection Vce
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, telegra.ph, www.stes.tyc.edu.tw, Disposable vapes
BONUS!!! Download part of ExamsLabs Databricks-Certified-Professional-Data-Engineer dumps for free: https://drive.google.com/open?id=1ONtgrg4F6cwX9ErWr4KVxsmpPQiWJoyx