
P.S. Kostenlose und neue MLA-C01 Prüfungsfragen sind auf Google Drive freigegeben von ITZert verfügbar: https://drive.google.com/open?id=1j2V8xZT4uXKsyqZfCDQ3VsrFYlK2jup_
Wenn Sie sorgen darum, dass die Vorbereitungszeit für Amazon MLA-C01 nicht genug ist oder wie die autoritative Prüfungsunterlagen finden können, dann können Sie ganz beruhigt sein. Wir ITZert bieten Ihnen die neuesten Prüfungsunterlagen der Amazon MLA-C01, die Ihnen helfen können, innerhalb einer kurzen Zeit auf die Amazon MLA-C01 Prüfung vorbereitet zu sein. Wir besitzen die autoritativen Prüfungsunterlagen sowie erfahrens und verantwortungsvolles Team. Das Ziel aller Bemühungen von uns ist, dass Sie die Amazon MLA-C01 Prüfung unbelastet bestehen.
| Section | Weight | Objectives |
|---|---|---|
| Data Preparation for Machine Learning (ML) | 28% | - Data preprocessing and transformation
|
| ML Solution Monitoring, Maintenance, and Security | 24% | - Monitoring and observability
|
| ML Model Development | 26% | - Model tuning and evaluation
|
| Deployment and Orchestration of ML Workflows | 22% | - ML pipeline orchestration
|
>> Amazon MLA-C01 Examengine <<
Wir können mit Stolz sagen, dass wir ITZert professionell ist! Denn die Bestehensquote der Prüflingen, die unsere Amazon MLA-C01 Software benutzt haben, ist unglaublich hoch. Denn unsere Tech-Gruppe ist unglaublich kompetent. Der Kundendienst ist ein sehr wichtiger Standard für eine Firma. Um den hohen Standard zu entsprechen, bieten wir 24/7 online Kundendienst, einjähriger kostenloser Amazon MLA-C01 Aktualisierungsdienst nach dem Kauf und die Erstattungspolitik beim Durchfall. Wenn Sie wirklich Amazon MLA-C01 bestehen möchten, wählen Sie unsere Produkte!
221. Frage
A company has significantly increased the amount of data stored as .csv files in an Amazon S3 bucket. Data transformation scripts and queries are now taking much longer than before.
An ML engineer must implement a solution to optimize the data for query performance with the LEAST operational overhead.
Which solution will meet this requirement?
Antwort: A
Begründung:
AWS strongly recommends converting large CSV datasets into columnar formats such as Apache Parquet to improve query performance. Parquet reduces I/O by reading only the required columns and applies compression, which significantly speeds up analytics workloads.
AWS Glue ETL jobs provide a fully managed, serverless way to perform this conversion with minimal operational overhead. Once converted, the Parquet files can be queried efficiently by services such as Amazon Athena, Redshift Spectrum, and SageMaker processing jobs.
Splitting CSV files does not address inefficient storage format. Dropping columns risks data loss. Amazon EMR introduces infrastructure management overhead and is unnecessary for a straightforward format conversion.
AWS documentation clearly identifies CSV-to-Parquet conversion using Glue ETL as a best practice for scalable analytics.
Therefore, Option C is the correct answer.
222. Frage
A financial company receives a high volume of real-time market data streams from an external provider. The streams consist of thousands of JSON records every second.
The company needs to implement a scalable solution on AWS to identify anomalous data points.
Which solution will meet these requirements with the LEAST operational overhead?
Antwort: C
Begründung:
The key requirements are real-time processing, high throughput, and minimal operational overhead. Amazon Kinesis Data Streams is designed for ingesting thousands of events per second with low latency.
For anomaly detection on streaming data, Amazon Managed Service for Apache Flink provides a built-in Random Cut Forest (RCF) function. RCF is an unsupervised anomaly detection algorithm that works well on numerical streaming data and does not require labeled training data.
This fully managed combination eliminates the need to deploy or maintain SageMaker endpoints, EC2 instances, or custom ML pipelines. Options B and C introduce unnecessary infrastructure and model management overhead. Option D is batch-oriented and unsuitable for real-time anomaly detection.
Therefore, using Kinesis Data Streams with Flink's built-in Random Cut Forest is the most scalable and low- overhead solution.
223. Frage
An ML engineer needs to implement a solution to host a trained ML model. The rate of requests to the model will be inconsistent throughout the day.
The ML engineer needs a scalable solution that minimizes costs when the model is not in use.
The solution also must maintain the model's capacity to respond to requests during times of peak usage.
Which solution will meet these requirements?
Antwort: D
224. Frage
A company needs to update the model definition of an existing Amazon SageMaker Al endpoint.
Select and order the correct steps from the following list to update the model definition settings with the LEAST interruption of inferences. Select each step one time or not at all. (Select and order THREE.)
* Create a new endpoint configuration that uses the new model definition.
* Create a new model definition with updated settings by using the CreateModel action in the SageMaker AI API.
* Delete the endpoint that needs to be updated and recreate the endpoint with the new endpoint configuration.
* Delete the IAM role and permissions for the ExecutionRoleArn parameter.
* Update the endpoint with the new endpoint configuration.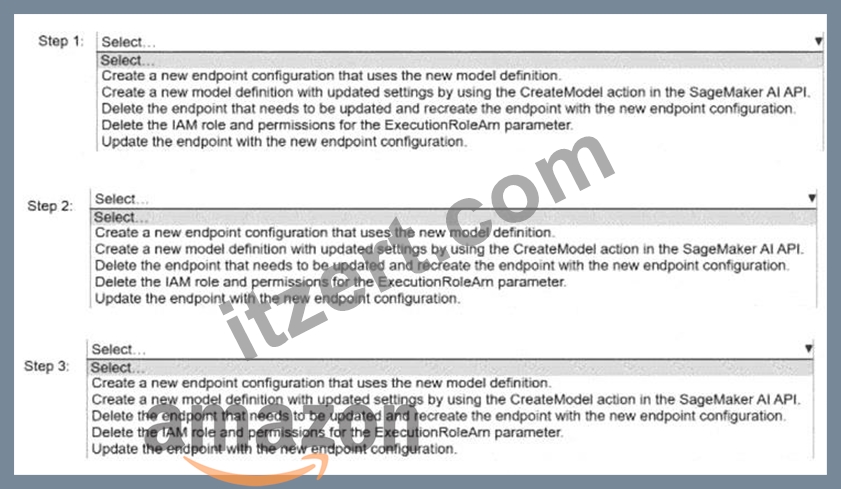
Antwort:
Begründung: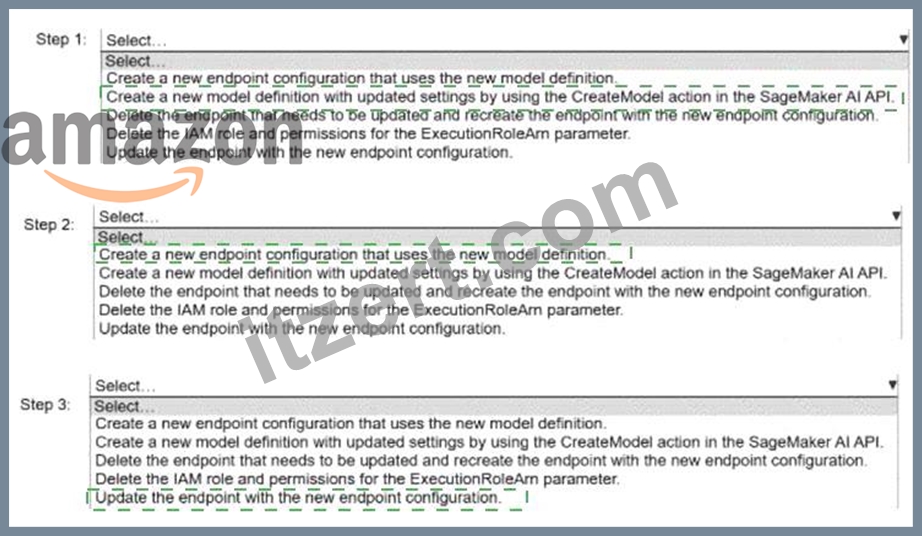
Explanation:
Step 1: Create a new model definition with updated settings by using the CreateModel action in the SageMaker AI API.
Step 2: Create a new endpoint configuration that uses the new model definition.
Step 3: Update the endpoint with the new endpoint configuration.
Do not delete and recreate the endpoint. That causes unnecessary inference interruption. SageMaker endpoint updates are designed to use a new EndpointConfig; AWS explicitly states that to update an endpoint, you must create a new endpoint configuration, then call UpdateEndpoint on the existing endpoint. During the update, SageMaker changes the endpoint to Updating and then back to InService.
225. Frage
An ML engineer is developing a classification model. The ML engineer needs to use custom libraries in processing jobs, training jobs, and pipelines in Amazon SageMaker AI.
Which solution will provide this functionality with the LEAST implementation effort?
Antwort: B
Begründung:
AWS documentation strongly recommends using custom Docker containers when ML workloads require consistent access to custom dependencies across processing jobs, training jobs, and pipelines.
By building a single Docker image that contains all required libraries and hosting it in Amazon ECR, the ML engineer ensures that every SageMaker job uses the same runtime environment. This approach eliminates the need for repetitive installation steps and avoids environment drift.
Manually installing libraries in managed containers is error-prone and not reusable across jobs. Notebook instances are not designed to host production jobs and pipelines. Running code externally breaks the SageMaker workflow and increases operational complexity.
Using a custom container is a one-time setup that provides maximum reuse with minimal ongoing effort, making it the least implementation effort option in the long run.
Therefore, Option B is the correct and AWS-recommended answer.
226. Frage
......
Die Fragen zur Amazon MLA-C01 Zertifizierungsprüfung von ITZert sind die gründlichste, die genaueste und die neueste Praxistest. Sie werden Selbstbewusstsein finden, die Schwierigkeiten beim ersten Versuch zu überwinden. Die Amazon MLA-C01 Zertifizierungsprüfung wird von allen Ländern akzeptiert. Alle Länder werden sie gleich behandeln. Das Amazon MLA-C01 Zertifikat wird Ihnen nicht nur helfen, Ihre Fachkenntnisse und Fähigkeiten zu verbessern, sondern auch mehrere berufliche Chancen zu erhalten.
MLA-C01 Testengine: https://www.itzert.com/MLA-C01_valid-braindumps.html
2026 Die neuesten ITZert MLA-C01 PDF-Versionen Prüfungsfragen und MLA-C01 Fragen und Antworten sind kostenlos verfügbar: https://drive.google.com/open?id=1j2V8xZT4uXKsyqZfCDQ3VsrFYlK2jup_