What's more, part of that TestKingFree DY0-001 dumps now are free: https://drive.google.com/open?id=1KuixtrjaNAdMBlanWvUeUAiNiShCalt6
For added reassurance, we also provide you with up to 1 year of free CompTIA Dumps updates and a free demo version of the actual product so that you can verify its validity before purchasing. The key to passing the CompTIA DY0-001 exam on the first try is vigorous DY0-001 practice. And that's exactly what you'll get when you prepare from our CompTIA DataAI Certification Exam (DY0-001) practice material. Each format of our DY0-001 study material excels in its own way and serves to improve your skills and gives you an inside-out understanding of each exam topic.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Modeling, Analysis, and Outcomes | 24% | - Model Lifecycle
|
| Topic 2: Machine Learning | 24% | - Supervised & Tree-based Learning
|
| Topic 3: Mathematics and Statistics | 17% | - Applied Mathematics
|
| Topic 4: Specialized Applications of Data Science | 13% | - Specialized Domains
|
| Topic 5: Operations and Processes | 22% | - Business & Data Lifecycle
|
>> Latest DY0-001 Exam Format <<
It Contains a pool of real CompTIA DY0-001 exam questions. This CompTIA DataAI Certification Exam (DY0-001) practice test is compatible with every windows-based system. One downloaded does not require an active internet connection to operate. You can self-evaluate your mistakes after each DY0-001 Practice Exam attempt and work on the weak points that require more attention.
NEW QUESTION # 42
A team is building a spam detection system. The team wants a probability-based identification method without complex, in-depth training from the historical data set. Which of the following methods would best serve this purpose?
Answer: D
Explanation:
# Naive Bayes is a probabilistic classification algorithm based on Bayes' theorem. It is lightweight, fast, and effective for text-based classification problems like spam detection. It also performs well with small or simple training sets.
Why the other options are incorrect:
* A: Logistic regression is also probabilistic but requires more feature preprocessing.
* B: Random forest is accurate but computationally heavier.
* D: Linear regression is for continuous targets - not suitable for classification.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.1:"Naive Bayes classifiers are ideal for spam detection and similar applications due to their efficiency and probabilistic nature."
* Text Classification Techniques, Chapter 4:"Naive Bayes requires minimal training and works well with high-dimensional, sparse data such as email content."
NEW QUESTION # 43
A data analyst wants to save a newly analyzed data set to a local storage option. The data set must meet the following requirements:
* Be minimal in size
* Have the ability to be ingested quickly
* Have the associated schema, including data types, stored with it
Which of the following file types is the best to use?
Answer: B
Explanation:
Given the requirements:
* Minimized file size
* Fast ingestion
* Schema preservation (including data types)
The most appropriate format is:
# Parquet - It is a columnar storage file format developed for efficient data processing. Parquet files are compressed, support schema embedding, and enable fast columnar reads, making them ideal for analytical workloads and big data environments.
Why the other options are incorrect:
* A. JSON: Text-heavy and lacks native support for data types/schema.
* C. XML: Verbose and has poor performance in storage and ingestion speed.
* D. CSV: Flat structure, doesn't store data types or schema, and can be large in size.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 6.2 (Data Storage Formats):"Parquet is a preferred format for data analysis as it provides efficient compression and encoding with embedded schema information, making it ideal for minimal storage and fast ingestion."
* Apache Parquet Documentation:"Parquet is designed for efficient data storage and retrieval. It includes schema support and works best for analytics use cases." Parquet is a columnar storage format that automatically includes schema (data types), uses efficient compression to minimize file size, and enables very fast reads for analytic workloads.
NEW QUESTION # 44
A movie production company would like to find the actors appearing in its top movies using data from the tables below. The resulting data must show all movies in Table 1, enriched with actors listed in Table 2.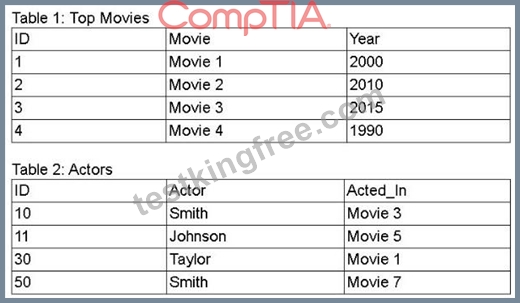
Which of the following query operations achieves the desired data set?
Answer: C
Explanation:
# A LEFT JOIN ensures all rows from Table 1 (Top Movies) are preserved, even if there's no matching actor data in Table 2. This matches the requirement to show all movies, enriched with actor information when available.
Why the other options are incorrect:
* A: INNER JOIN would exclude movies without matching actor entries.
* B: UNION combines distinct rows - not appropriate for matching columns between two tables.
* C: INTERSECT shows only common movies - excludes unmatched top movies.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 5.2:"LEFT JOINs are used when all records from one table (primary) must be retained, even if there are no matching rows in the secondary table."
-
NEW QUESTION # 45
Which of the following environmental changes is most likely to resolve a memory constraint error when running a complex model using distributed computing?
Answer: A
Explanation:
Increasing the number of nodes in your cluster directly expands the total available memory across the distributed system, alleviating memory‐constraint errors without changing your code or deployment paradigm. Containerization or edge deployments don't inherently provide more memory, and migrating to the cloud alone doesn't guarantee additional nodes unless you explicitly scale out.
NEW QUESTION # 46
Which of the following techniques enables automation and iteration of code releases?
Answer: B
Explanation:
# CI/CD (Continuous Integration / Continuous Deployment) is a DevOps methodology that automates the building, testing, and deployment of code. It allows teams to iteratively release updates and improvements in a reliable and scalable manner.
Why the other options are incorrect:
* A: Virtualization provides environment emulation but doesn't manage code releases.
* B: Markdown is a documentation tool - unrelated to deployment automation.
* C: Code isolation refers to modular programming, not automation pipelines.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 5.3:"CI/CD pipelines streamline model deployment through automation, allowing continuous integration and delivery of updates."
* DevOps for Data Science, Chapter 4:"CI/CD supports fast and reliable code iterations by automatically testing and deploying to production environments."
-
NEW QUESTION # 47
......
If you are nervous on your DY0-001 exam for you always have the problem on the time-schedule or feeling lack of confidence on the condition that you go to the real exam room. Our Software version of DY0-001 study materials will be your best assistant. With the advantage of simulating the real exam environment, you can get a wonderful study experience with our DY0-001 Exam Prep as well as gain the best pass percentage.
DY0-001 Exam Training: https://www.testkingfree.com/CompTIA/DY0-001-practice-exam-dumps.html
BONUS!!! Download part of TestKingFree DY0-001 dumps for free: https://drive.google.com/open?id=1KuixtrjaNAdMBlanWvUeUAiNiShCalt6