Latest Customized Databricks-Machine-Learning-Professional Lab Simulation - Win Your Databricks Certificate with Top Score

BONUS!!! Download part of Braindumpsqa Databricks-Machine-Learning-Professional dumps for free: https://drive.google.com/open?id=16FwdM2z8aB1Gfwj-2dnr8jhtGq0mKgtB
If you cannot fully believe our Databricks-Machine-Learning-Professional exam prep, you can refer to the real comments from our customers on our official website before making a decision. There are some real feelings after they have bought our study materials. Almost all of our customers have highly praised our Databricks-Machine-Learning-Professional exam guide because they have successfully obtained the certificate. Generally, they are very satisfied with our Databricks-Machine-Learning-Professional Exam Torrent. Also, some people will write good review guidance for reference. Maybe it is useful for your preparation of the Databricks-Machine-Learning-Professional exam. In addition, you also can think carefully which kind of study materials suit you best. If someone leaves their phone number or email address in the comments area, you can contact them directly to get some useful suggestions.
| Topic | Details |
|---|
| Topic 1 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 2 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| Topic 3 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Topic 4 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| Topic 5 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Topic 6 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| Topic 7 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 8 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
| Topic 9 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Topic 10 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
>> Customized Databricks-Machine-Learning-Professional Lab Simulation <<
Exam Databricks Databricks-Machine-Learning-Professional Review - Databricks-Machine-Learning-Professional Valid Test Tips
After you pay for our Databricks-Machine-Learning-Professional exam material online, you will get the link to download it in only 5 to 10 minutes. You don't have to wait a long time to start your preparation for the Databricks-Machine-Learning-Professional exam. The only thing you must make sure is that you have left your right E-mail address when you purchase our Databricks-Machine-Learning-Professional Study Guide. Moreover, you don't need to worry about safety in buying our Databricks-Machine-Learning-Professional exam materials. We have considered all the details for you. You can just buy and download right now!
Databricks Certified Machine Learning Professional Sample Questions (Q28-Q33):
NEW QUESTION # 28
A data scientist set up a machine learning pipeline to automatically log a data visualization with each run. They now want to view the visualizations in Databricks.
Which of the following locations in Databricks will show these data visualizations?
- A. The MLflow Model Registry Model paqe
- B. Logged data visualizations cannot be viewed in Databricks
- C. The Artifacts section of the MLflow Run page
- D. The Figures section of the MLflow Run page
- E. The Artifacts section of the MLflow Experiment page
Answer: D
NEW QUESTION # 29
How can you save a trained Spark ML PipelineModel?
- A. pipeline.persist()
- B. pipeline.save()
- C. pipelineModel.write().save()
- D. pipeline.store()
Answer: C
Explanation:
Example:
pipelineModel.write().overwrite().save("/model")
NEW QUESTION # 30
A machine learning engineer has developed a model and registered it using the FeatureStoreClient fs. The model has model URI model_uri. The engineer now needs to perform batch inference on the training set logged with the model, but a few of the feature values in the column spend have since been updated and arc present in the customer-level Spark DataFrame spark_df. The customer_id column is the primary key of spark_df and the training set used when training and logging the model. Which code block can be used to compute predictions for the training set while overwriting its old spend values with the new spend values from spark_df?
- A. df = fs.get_updated_feature(spark_df, model=uri)
fs.score_batch(model_uri, df) - B. df = fs.get_updated_features(spark_df)
fs.score_batch(model_uri, df) - C. fs.score_batch(model_uri, spark_df)
- D. fs.score_model(model_uri, spark_df)
Answer: B
Explanation:
To perform batch inference while incorporating updated feature values (like spend) from a DataFrame (spark_df), the correct approach is to use fs.get_updated_features(spark_df) to refresh the relevant features based on the primary key (customer_id), then score the model using fs.score_batch(...). This ensures predictions are made with the latest data.
NEW QUESTION # 31
A Machine Learning Engineer is building an application that requires low latency data lookups in response to a user's question following a RAG based search. They want to ensure their users can receive as recent data as possible for urgent requests, so data should not be more than a few minutes late. The underlying data is a large table that may contain hundreds of gigabytes of data. Which data serving approach will suit their use case?
- A. A fast database hosted in MLflow model serving
- B. Online tables with snapshot sync mode
- C. Online tables with triggered mode and a time series key
- D. Online tables with continuous sync mode
Answer: D
Explanation:
Online tables with continuous sync mode are designed for low-latency serving while keeping data fresh within minutes. Continuous sync incrementally propagates updates from the large underlying table to the online store, ensuring near-real-time availability for RAG-based lookups without requiring full refreshes, which is ideal for urgent, freshness-sensitive queries on large datasets.
NEW QUESTION # 32
A data scientist has run the following line of code to create a Feature Store table:
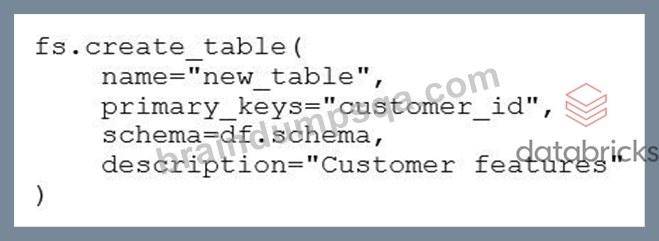
Which statement correctly describes the data in the Feature Store table new_table?
- A. The data in new_table is the values in column customer_id from df
- B. There is no data in new_table
- C. The data in new_table is the customer-related features from df
- D. The data in new_table is exactly the same as the data in df
Answer: B
Explanation:
The fs.create_table() command defines metadata for a Feature Store table, such as its name, primary key, schema, and description - but it does not insert any data into the table. This command simply registers an empty table structure based on the provided schema (df.schema).
To populate the table with data, a separate fs.write_table() or equivalent write operation must be executed afterward.
NEW QUESTION # 33
......
Braindumpsqa's experienced expert team has developed effective training program a for Databricks certification Databricks-Machine-Learning-Professional exam, which is very fit for candidates. Braindumpsqa provide you the high quality product, which can let you do simulation test before the real Databricks Certification Databricks-Machine-Learning-Professional Exam. So you can take a best preparation for the exam.
Exam Databricks-Machine-Learning-Professional Review: https://www.braindumpsqa.com/Databricks-Machine-Learning-Professional_braindumps.html
- Databricks-Machine-Learning-Professional Latest Exam Questions 👄 Databricks-Machine-Learning-Professional Intereactive Testing Engine ☃ Valid Test Databricks-Machine-Learning-Professional Tips 👸 Search for [ Databricks-Machine-Learning-Professional ] on ➡ www.vce4dumps.com ️⬅️ immediately to obtain a free download 🦏Practice Databricks-Machine-Learning-Professional Exams Free
- 2026 Realistic Databricks Customized Databricks-Machine-Learning-Professional Lab Simulation Pass Guaranteed Quiz 🐷 Open ▷ www.pdfvce.com ◁ enter ✔ Databricks-Machine-Learning-Professional ️✔️ and obtain a free download 🕊Braindumps Databricks-Machine-Learning-Professional Pdf
- Databricks Databricks-Machine-Learning-Professional Desktop - Practice Test Software By www.examcollectionpass.com 📀 Immediately open 《 www.examcollectionpass.com 》 and search for ▶ Databricks-Machine-Learning-Professional ◀ to obtain a free download 💍Databricks-Machine-Learning-Professional Test Certification Cost
- 2026 Professional Customized Databricks-Machine-Learning-Professional Lab Simulation Help You Pass Databricks-Machine-Learning-Professional Easily 💏 Open ⏩ www.pdfvce.com ⏪ enter ▛ Databricks-Machine-Learning-Professional ▟ and obtain a free download ✒Valid Test Databricks-Machine-Learning-Professional Tips
- Databricks-Machine-Learning-Professional Intereactive Testing Engine ✈ Valid Study Databricks-Machine-Learning-Professional Questions 🦡 Valid Test Databricks-Machine-Learning-Professional Tips 📟 Download [ Databricks-Machine-Learning-Professional ] for free by simply searching on ⇛ www.prep4away.com ⇚ 🧈Valid Databricks-Machine-Learning-Professional Exam Prep
- Databricks - Efficient Customized Databricks-Machine-Learning-Professional Lab Simulation 💱 Search for “ Databricks-Machine-Learning-Professional ” and obtain a free download on ( www.pdfvce.com ) 🍋Test Databricks-Machine-Learning-Professional Assessment
- Databricks-Machine-Learning-Professional Test Certification Cost 🔀 Exam Databricks-Machine-Learning-Professional PDF 😜 Braindumps Databricks-Machine-Learning-Professional Pdf 👱 Search for ▷ Databricks-Machine-Learning-Professional ◁ and download it for free on ➠ www.vceengine.com 🠰 website 🦕Databricks-Machine-Learning-Professional Exam Answers
- Databricks-Machine-Learning-Professional Training Materials - Databricks-Machine-Learning-Professional Certification Training - Databricks-Machine-Learning-Professional Exam Questions 🦪 Search for ▛ Databricks-Machine-Learning-Professional ▟ and obtain a free download on “ www.pdfvce.com ” 🌴Latest Databricks-Machine-Learning-Professional Exam Book
- Pass Guaranteed 2026 Valid Databricks Databricks-Machine-Learning-Professional: Customized Databricks Certified Machine Learning Professional Lab Simulation 🎩 Search for ⏩ Databricks-Machine-Learning-Professional ⏪ on ⮆ www.pass4test.com ⮄ immediately to obtain a free download 🏏Databricks-Machine-Learning-Professional Test Certification Cost
- Free PDF Quiz Databricks - Databricks-Machine-Learning-Professional Fantastic Customized Lab Simulation 🗳 Search for ▶ Databricks-Machine-Learning-Professional ◀ and download it for free on ⏩ www.pdfvce.com ⏪ website 🙅Guaranteed Databricks-Machine-Learning-Professional Questions Answers
- Databricks-Machine-Learning-Professional Training Materials - Databricks-Machine-Learning-Professional Certification Training - Databricks-Machine-Learning-Professional Exam Questions 🧎 Download ⮆ Databricks-Machine-Learning-Professional ⮄ for free by simply entering [ www.prepawayexam.com ] website 😪Guaranteed Databricks-Machine-Learning-Professional Questions Answers
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, wanderlog.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
What's more, part of that Braindumpsqa Databricks-Machine-Learning-Professional dumps now are free: https://drive.google.com/open?id=16FwdM2z8aB1Gfwj-2dnr8jhtGq0mKgtB