2026年Japancertの最新XSIAM-Engineer PDFダンプおよびXSIAM-Engineer試験エンジンの無料共有:https://drive.google.com/open?id=1180F7n5LOBMrtrlP-n9qVTH8OquOteiY
あなたは無料でXSIAM-Engineer復習教材をダウンロードしたいですか?もちろん、回答ははいです。だから、あなたはコンピューターでPalo Alto Networksのウエブサイトを訪問してください。そうすれば、あなたは簡単にXSIAM-Engineer復習教材のデモを無料でダウンロードできます。そして、あなたはXSIAM-Engineer復習教材の三種類のデモをダウンロードできます。
| Section | Weight | Objectives |
|---|---|---|
| Detection Engineering and Content | 25% | - Detection Rules
|
| Planning and Installation | 25% | - Installation and Initial Setup
|
| Integration and Data Onboarding | 25% | - Authentication and Connectivity
|
| Automation, Response and Troubleshooting | 25% | - Automation Workflows
|
Japancert試験に合格できる人は、短時間で高給を獲得できます。 試験に勝つことに決めた場合は、XSIAM-Engineer試験トレントを試す必要があります。そうすると、試験に簡単に合格できることがわかります。Palo Alto Networks 学習教材としてXSIAM-Engineer準備トレントを使用する場合、試験の確認と準備に必要な時間と労力はほとんど必要ありません。 ですから、XSIAM-Engineer学習準備を購入する価値があります。 XSIAM-Engineerトレーニングガイドの無料デモを提供して、購入前にXSIAM-Engineer試験問題を十分に理解できるようにします。
質問 # 108
A critical zero-day vulnerability (e.g., a new remote code execution in a widely used library) is announced, and Palo Alto Networks releases an emergency XSIAM agent update. The security team needs to push this update to 100,000 endpoints as quickly as possible, ensuring minimal disruption. What is the most effective and least disruptive method for deploying this critical agent update at scale, leveraging XSIAM's capabilities?
正解:E
解説:
Option C is the most effective and least disruptive method for deploying critical agent updates at scale using Cortex XSIAM. The XSIAM console provides robust agent version management. By simply updating the 'Agent Versions' policy assigned to specific agent groups, the XSIAM cloud instructs the agents to fetch and install the new version. The agents' built-in update mechanism is designed for efficiency and usually performs the update silently in the background, often without requiring a reboot unless specific kernel components or critical drivers are updated. This method leverages the intelligence of the XSIAM platform for rapid, controlled, and minimally disruptive large-scale deployments. Options A and B are manual, slower, and often force reboots. Option D is not scalable. Option E is unacceptable for a critical zero-day vulnerability.
質問 # 109
Consider an XSIAM environment where the XDR Collectors are deployed as Docker containers orchestrated by Kubernetes. A new XDR Collector image version (2.5.0) has been released, and you need to perform a controlled update across your cluster. Your current deployment uses a Helm chart. Which of the following kubectl commands, when used in conjunction with a modified Helm chart value for the image tag, would facilitate a rolling update with zero downtime, assuming the Helm chart is correctly configured for rolling updates?





正解:C
解説:
When managing applications deployed via Helm, the standard and most effective way to perform updates, especially rolling updates, is through 'helm upgrade'. By modifying the 'image.tag' value in the Helm chart (either directly in 'values.yamr or via '-set' as shown), Helm will intelligently detect the change and perform a rolling update on the Kubernetes deployment, ensuring zero downtime if the deployment strategy is set to 'RollingUpdate' (which is the default for most Helm charts). Options A, B, D, and E are either less appropriate for a Helm-managed application, cause downtime, or are not the primary mechanism for an image update through Helm.
質問 # 110
An XSIAM engineer is reviewing an existing indicator rule designed to detect suspicious login attempts from rare geographic locations. The current rule triggers on any login event where the 'city' field is not within a predefined list of allowed cities for the organization. This has led to a high volume of false positives due to legitimate travel by employees. To optimize this rule, which of the following actions should the engineer take?
正解:A
解説:
Option C is the most effective optimization strategy. Instead of simply flagging any login from a rare location, correlating it with other suspicious behaviors (concurrent logins, failed attempts, sensitive app access) significantly increases the fidelity of the alert, reducing false positives while still catching genuine threats. Option A disables valuable context. Option B increases analyst fatigue. Option D is not scalable or maintainable for a large organization with frequent travel. Option E is irrelevant as geographic data is usually derived from IP addresses, regardless of endpoint or network log source.
質問 # 111
A company is automating Cortex XSIAM agent deployment using Ansible. The challenge is to install the agent and ensure it's registered with the correct agent group dynamically, without hardcoding group names into the playbook, as new groups are frequently created. The XSIAM API documentation provides endpoints for retrieving agent group information. Which of the following Ansible playbook snippets best demonstrates the concept of dynamic agent group assignment using the XSIAM API during installation?
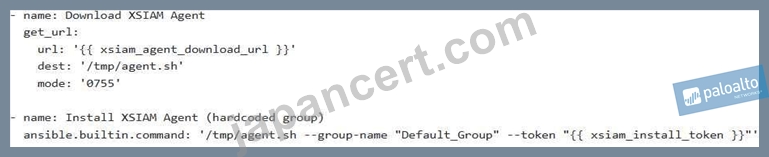
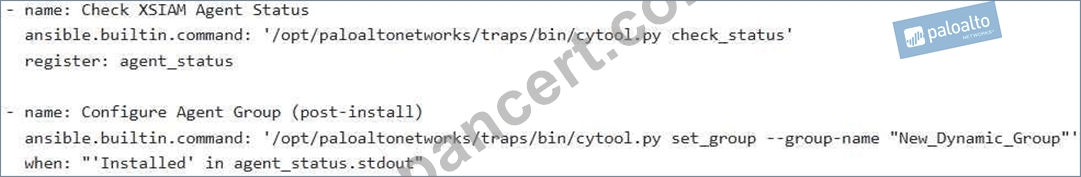
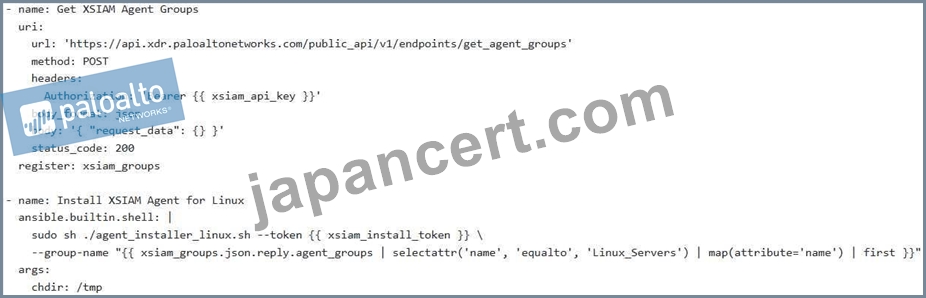
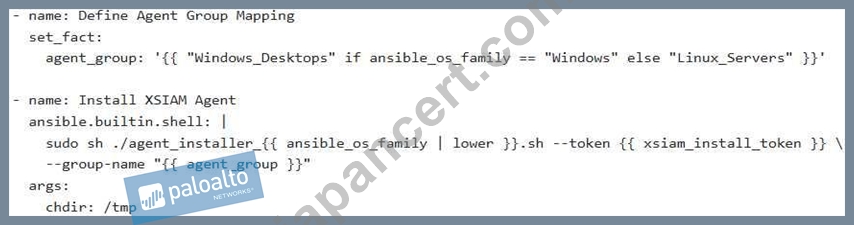
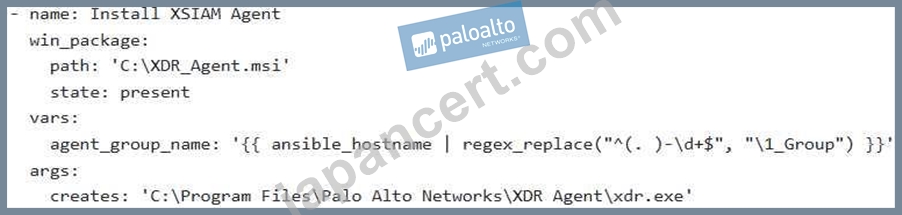
正解:C
解説:
Option B correctly demonstrates the concept of dynamic agent group assignment using the XSIAM API. It first uses the 'uri' module to make an API call to , authenticating with a bearer token. This API call retrieves all existing agent groups from the XSIAM console. The subsequent installation step then uses Jinja2 templating Cxsiam_groups.json.reply.agent_groups I selectattr('name', 'equalto', 'Linux_Servers') I map(attribute='name') I first') to dynamically select the name of the 'Linux_Servers' group from the API response and pass it to the agent installer. This is a robust method for ensuring agents are assigned to correct groups, even if group IDs or exact names change, as long as a lookup logic (like matching by a known name 'Linux_Servers') is maintained. Option A uses a regex for group naming, which is not dynamic in relation to XSIAM console groups. Option C hardcodes the group. Option D is a post-installation change, not during initial deployment, and doesn't dynamically fetch groups. Option E uses conditional logic but still relies on hardcoded group names within the playbook, not fetching them dynamically from the XSIAM API.
質問 # 112
A large-scale XSIAM deployment is experiencing significant delays (hours) in log visibility from geographically dispersed Palo Alto Networks NGFWs, despite network connectivity being verified and NGFWs showing active log forwarding. The and metrics on the XSIAM Collectors indicate high activity, but is significantly lower. This suggests a bottleneck. Which of the following is the most effective immediate action to identify the specific bottleneck within the XSIAM data ingestion pipeline?
正解:D
解説:
When lags significantly behind and is high, it points to a bottleneck within the collector's processing pipeline (parsing, normalization, enrichment) rather than just network ingress or data lake writes. Option B is the most effective immediate troubleshooting step because it directs the engineer to internal collector logs, which provide granular insights into where processing is stalling or failing. Options A and E are scaling solutions. Option C is a diagnostic step but disruptive. Option D focuses on data lake, which is downstream from the observed bottleneck.
質問 # 113
......
我々Japancertは一番行き届いたアフタサービスを提供します。Palo Alto Networks XSIAM-Engineer試験問題集を購買してから、一年間の無料更新を楽しみにしています。あなたにPalo Alto Networks XSIAM-Engineer試験に関する最新かつ最完備の資料を勉強させ、試験に合格させることだと信じます。もしあなたはXSIAM-Engineer試験に合格しなかったら、全額返金のことを承諾します。
XSIAM-Engineer過去問: https://www.japancert.com/XSIAM-Engineer.html
無料でクラウドストレージから最新のJapancert XSIAM-Engineer PDFダンプをダウンロードする:https://drive.google.com/open?id=1180F7n5LOBMrtrlP-n9qVTH8OquOteiY