ZertPruefung bieten Ihnen eine klare und ausgezeichnete Wahl und hilft Ihnen, Ihre Sorgen zu reduzieren. Möchten Sie einen frühen Erfolg? Möchten Sie Microsoft DP-750 Zertifikat schnell zu erhalten? Beeilen Sie sich, Microsoft DP-750 Prüfungsunterlagen von ZertPruefung in Ihren Einkaufswagen hinzuzufügen. ZertPruefung gibt Ihnen eine gute Anleitung, um sicherzustellen, dass Sie die Microsoft DP-750 Prüfung bestehen können. Mit ZertPruefung können Sie ganz schnell das gewünschte Zertifikat bekommen.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
>> DP-750 Trainingsunterlagen <<
Vorm Kauf der Dumps zur DP-750 Zertifizierungsprüfung von ZertPruefung können Sie unsere Demo kostenlos als Probe herunterladen.
12. Frage
What ensures failure recovery in Databricks Structured Streaming?
Antwort: B
Begründung:
Checkpointing stores streaming state and progress, allowing recovery after failures without data loss or duplication. Auto scaling adjusts compute resources but does not ensure reliability.
Partition pruning improves query performance. Broadcast joins optimize joins but are unrelated to recovery.
13. Frage
Hotspot Question
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out-of-memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.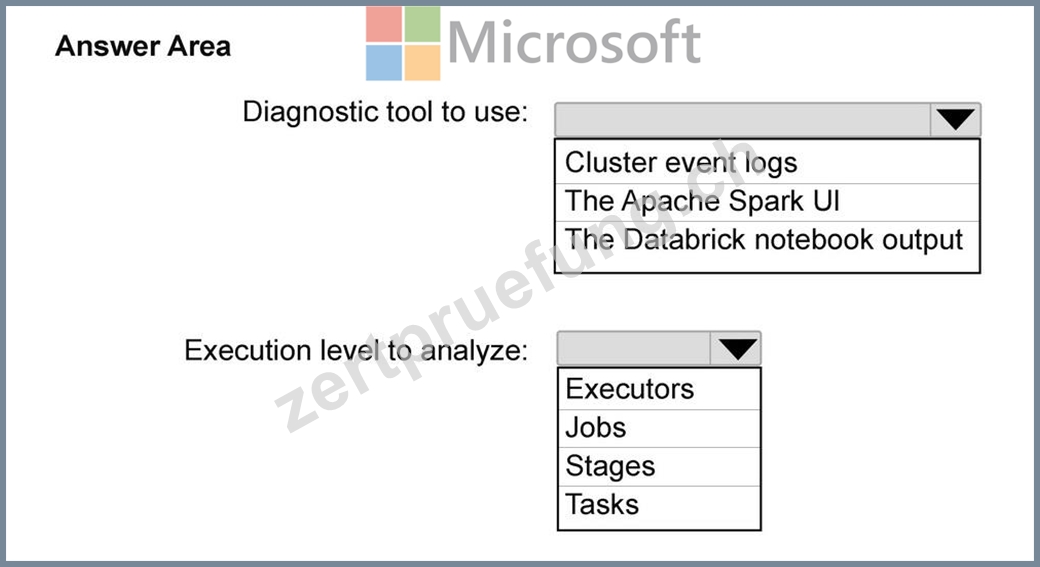
Antwort:
Begründung: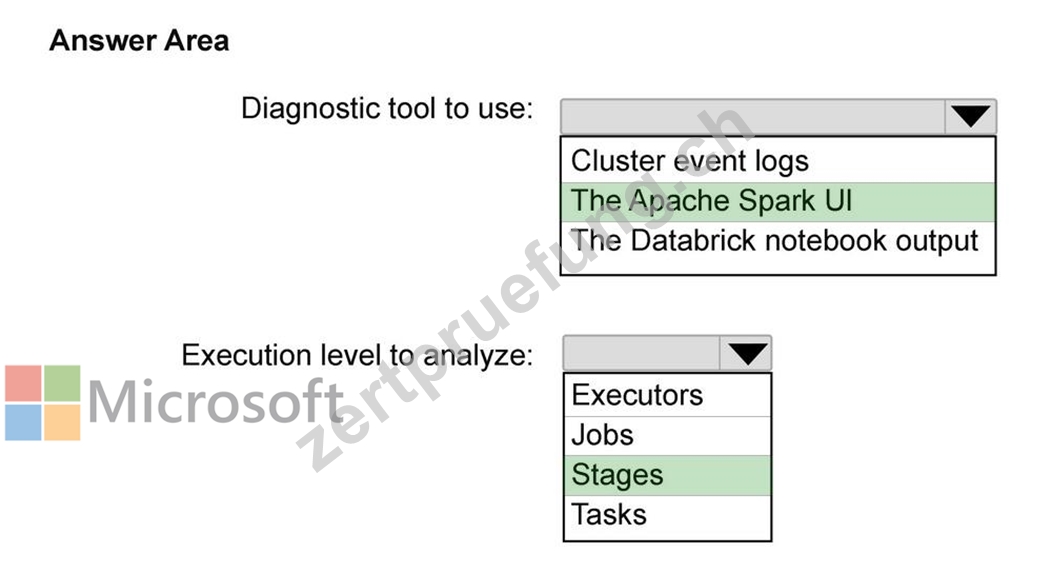
14. Frage
You have an Azure Databricks workspace.
You have an Apache Spark Structured Streaming job named Job! that processes data continuously and fails periodically due to transient errors You need to ensure that Job! meets the following requirements
* Resumes processing from the point that Job1 failed
* Minimizes how long it takes to restart Job!
* Minimizes the costs to restart Job!
What should you do?
Antwort: C
Begründung:
The correct answer is B - implement checkpointing.
A checkpoint is a durable record of the streaming job's progress written to ADLS Gen2 or DBFS after each successfully committed micro-batch. When the job restarts after a transient failure, it reads the checkpoint to find the last committed offset and resumes from that exact point - no data is reprocessed, no data is lost.
This satisfies all three requirements directly: checkpointing enables resumption from the failure point (not from the beginning), restart is fast because there's no replay overhead, and costs are minimised because no compute is wasted reprocessing records already handled.
Option A (decrease retry interval) makes the job retry sooner but doesn't control where it resumes from.
Option C (alert and manual restart) adds human latency and doesn't prevent reprocessing without a checkpoint. Option D (increase minimum nodes) reduces the likelihood of resource-related failures but increases cost and doesn't address the recovery behaviour itself.
Reference: https://learn.microsoft.com/en-us/azure/databricks/structured-streaming/query-recovery
15. Frage
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 runs every hour.
Occasionally, Job1 takes longer than one hour to complete.
You need to configure the job scheduling behavior to meet the following requirements:
* Overlapping runs must be prevented to avoid data corruption.
* Scheduled runs must not be discarded when another run is already active.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.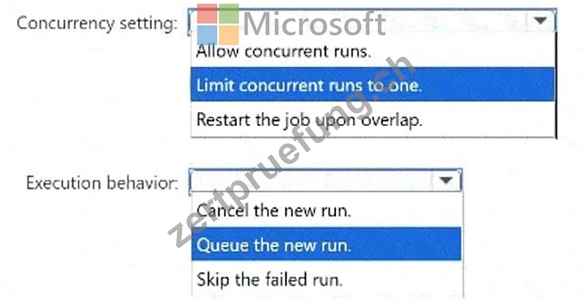
Antwort:
Begründung: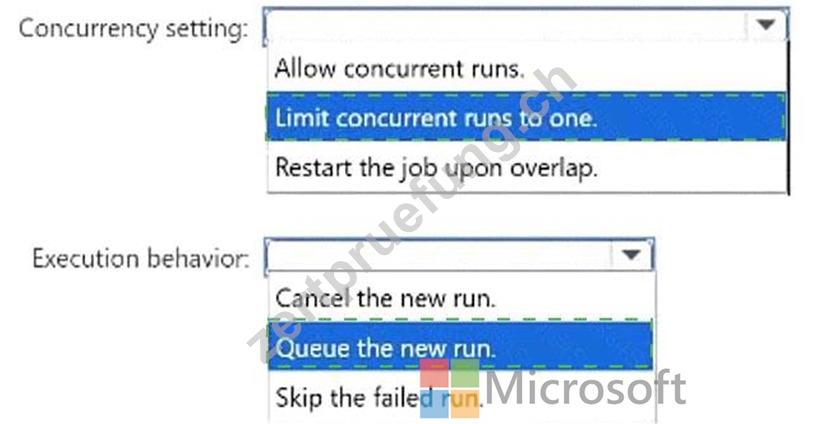
Explanation:
Concurrency setting: Limit concurrent runs to one.
Execution behavior: Queue the new run.
Limiting concurrent runs to one ensures that only one instance of Job1 can execute at a time. This prevents two hourly runs from simultaneously modifying the same tables, files, checkpoints, or downstream systems, thereby reducing the risk of duplicate processing and data corruption. When a scheduled trigger occurs while an earlier execution is still active, queueing the new run preserves that execution and starts it after the active run finishes. Allowing concurrent runs would violate the non-overlap requirement. Restarting the job during an overlap could interrupt partially completed work. Canceling the new run or skipping it would avoid simultaneous execution, but the scheduled processing interval could be lost. Single-run concurrency combined with queueing therefore serializes the executions without discarding scheduled work.
16. Frage
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table! is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table!
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
Antwort: C
Begründung:
The correct answer is C - Enable schema evolution.
When new columns are added to the source data, a pipeline without schema evolution treats the unexpected columns as a schema mismatch and fails the write. Schema evolution, when enabled in an SDP pipeline, automatically adds those new columns to the target Delta table on the next pipeline run. The pipeline continues without intervention, and no historical data is lost.
Option A (disable schema enforcement) is the wrong lever - it removes all schema validation, which could allow corrupt or mistyped data into Table1. Schema evolution is a targeted, safer response.
Option B (row filters to exclude records with new columns) would silently discard valid records just because they carry extra fields - that's data loss. Option D (separate table per schema version) creates an explosion of tables as schemas evolve and makes downstream analytics significantly more complex. Schema evolution is the clean, built-in solution.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/schema-evolution
17. Frage
......
Die Chance sind für die Menschen, die gut vorbereitet sind. Wenn Sie vor dem Einstieg des Berufslebens schon die Zertifizierung der Microsoft DP-750 erwerbt haben, sind Sie gut bereit für die Jobsuche. Die Microsoft DP-750 zu bestehen ist tatsächlich nicht leicht. Trotzdem haben schon zahlreiche Leute mit Hilfe der Microsoft DP-750 Prüfungsunterlagen, die von uns ZertPruefung angeboten werden, die Prüfung erfolgreich bestanden. Möchten Sie einer von ihnen zu werden? Dann lassen Sie unsere Produkte Ihnen helfen!
DP-750 Prüfungsfrage: https://www.zertpruefung.ch/DP-750_exam.html