DP-750인증시험은Microsoft인증시험중의 하나입니다.그리고 또한 비중이 아주 큰 인증시험입니다. 그리고Microsoft DP-750인증시험 패스는 진짜 어렵다고 합니다. 우리ExamPassdump에서는 여러분이DP-750인증시험을 편리하게 응시하도록 전문적이 연구팀에서 만들어낸 최고의DP-750덤프를 제공합니다, ExamPassdump와 만남으로 여러분은 아주 간편하게 어려운 시험을 패스하실 수 있습니다,
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Ingest and transform data
|
| Topic 2: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 3: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 4: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
DP-750인증시험은Microsoft사의 인중시험입니다.Microsoft인증사의 시험을 패스한다면 it업계에서의 대우는 달라집니다. 때문에 점점 많은 분들이Microsoft인증DP-750시험을 응시합니다.하지만 실질적으로DP-750시험을 패스하시는 분들은 너무 적습니다.전분적인 지식을 터득하면서 완벽한 준비하고 응시하기에는 너무 많은 시간이 필요합니다.하지만 우리ExamPassdump는 이러한 여러분의 시간을 절약해드립니다.
질문 # 16
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.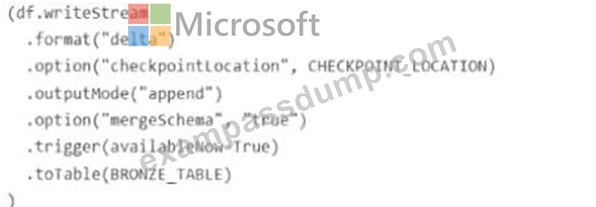
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.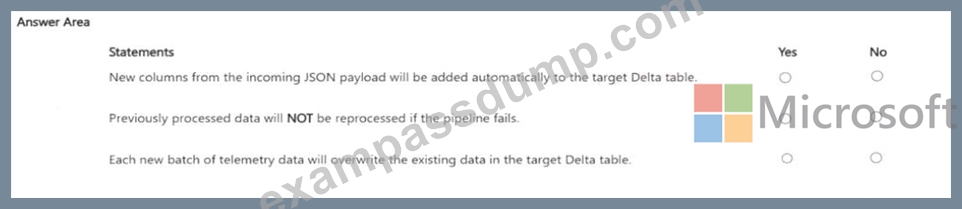
정답:
설명: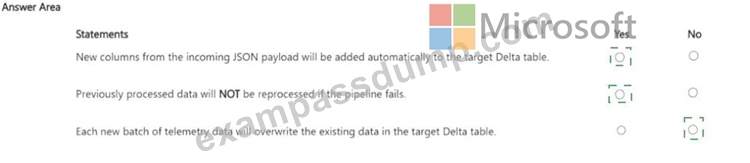
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: ' overwrite ' replaces existing data; ' append ' adds to it.
Always check whether the code uses the correct Delta format (.format( ' delta ' )), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
질문 # 17
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.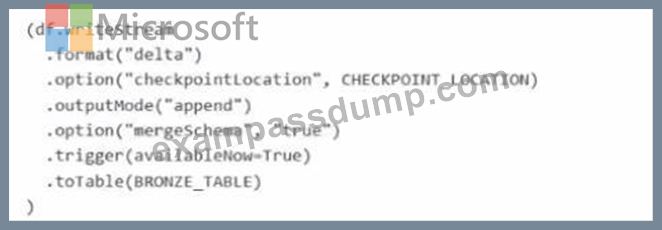
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
정답:
설명:
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: 'overwrite' replaces existing data; 'append' adds to it.
Always check whether the code uses the correct Delta format (.format('delta')), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
질문 # 18
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a foreign catalog in Catalog Explorer.
Does this meet the goal?
정답:B
설명:
The correct answer is A - Yes.
A foreign catalog created through Lakehouse Federation in Catalog Explorer is the correct solution for all three requirements. Here's why it works:
The schemas and tables of DB1 can be queried in Databricks - Lakehouse Federation pushes the query down to the external SQL Server and returns results, so analysts write normal SQL in Databricks.
They appear alongside other Unity Catalog objects - the foreign catalog sits in the same three-tier hierarchy as native catalogs, schemas, and tables, visible in Catalog Explorer alongside all other Unity Catalog assets.
The data is NOT copied into Databricks-managed storage - foreign catalogs query data in place at the source; nothing is replicated or materialised in Databricks storage.
This is exactly the scenario Lakehouse Federation was built for.
Reference: https://learn.microsoft.com/en-us/azure/databricks/query-federation/lakehouse-federation
질문 # 19
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1 You need to meet the following requirements:
* Records that violate rule! must NOT be written to Table1. but the pipeline must continue processing valid records.
* Data engineers must be able to review expectation metrics by using minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.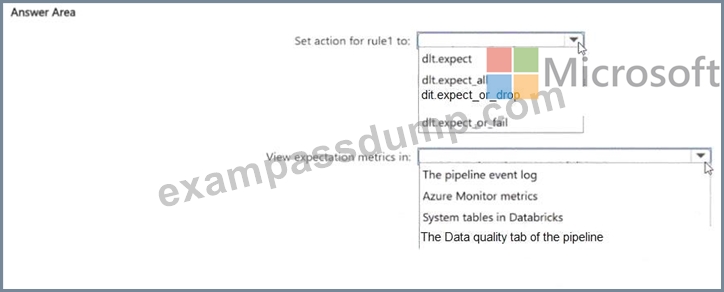
정답:
설명: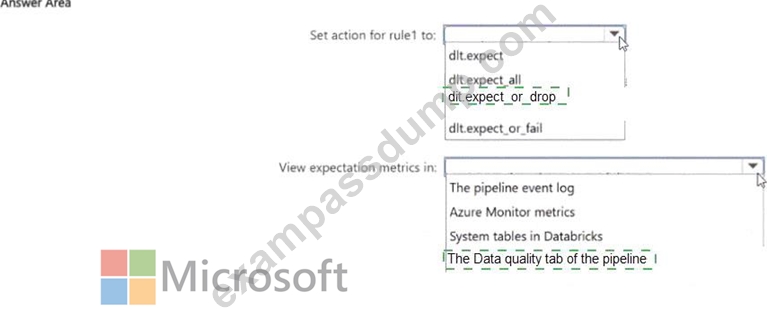
Explanation:
Two things are needed here:
For the rule enforcement: use @dlt.expect_or_drop. This drops any record that violates rule1 before it reaches Table1, while the pipeline continues processing all valid records. The table only ever receives clean data.
For reviewing metrics: the Lakeflow SDP Pipeline UI is the right tool - zero development effort required.
The pipeline graph shows expectation pass/fail counts directly on each table node, and the event log provides a detailed per-batch breakdown of how many records were dropped and why. Data engineers can inspect this at any time without writing additional monitoring queries or connecting external dashboards.
This combination is one of the strongest arguments for SDP over hand-coded Structured Streaming:
expectation observability is built in, not bolted on.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
질문 # 20
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1.
Table1 stores customer profile data.
Business users must analyze how customer profile records change over time. They must also be able to query earlier versions of the table.
You need to implement a solution that:
* Maintains persistent historical versions of customer profile records for long-term analysis.
* Allows users to query earlier versions of the Delta table.
* Minimizes maintenance effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.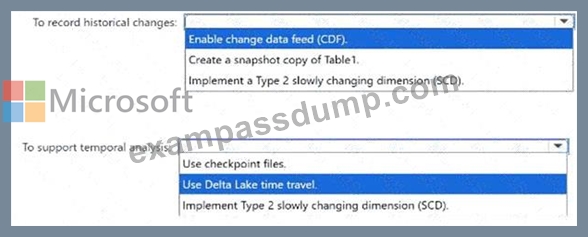
정답:
설명:
Explanation:
To record historical changes: Implement a Type 2 slowly changing dimension (SCD).
To support temporal analysis: Use Delta Lake time travel.
A Type 2 slowly changing dimension preserves customer-profile history by inserting a new record whenever a tracked attribute changes instead of overwriting the existing record. Effective dates, expiration dates, version values, or current-record indicators can identify which version applied during a particular period. This provides persistent business history for long-term analysis. Delta Lake time travel supports temporal analysis of the physical table by allowing users to query an earlier version with VERSION AS OF or TIMESTAMP AS OF. Time travel is useful for auditing and reproducing previous results, but its availability depends on retained Delta log entries and data files. Therefore, it should not replace a Type 2 SCD for permanent customer history. Together, the two features satisfy the historical-record and earlier-version requirements.
질문 # 21
......
Microsoft인증 DP-750시험은 중요한 IT인증자격증을 취득하는 필수시험과목입니다Microsoft인증 DP-750시험을 통과해야만 자격증 취득이 가능합니다.자격증을 많이 취득하면 자신의 경쟁율을 높여 다른능력자에 의해 대체되는 일은 면할수 있습니다.ExamPassdump에서는Microsoft 인증DP-750시험대비덤프를 출시하여 여러분이 IT업계에서 더 높은 자리에 오르도록 도움드립니다. 편한 덤프공부로 멋진 IT전문가의 꿈을 이루세요.
DP-750최신 업데이트버전 시험자료: https://www.exampassdump.com/DP-750_valid-braindumps.html