시험대비Databricks-Certified-Data-Analyst-Associate최고품질덤프문제보기덤프문제

ExamPassdump Databricks-Certified-Data-Analyst-Associate 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1Usuw4Nb317rUXntni-vvz7iVmP2jHa8I
현재 경쟁울이 심한IT시대에,Databricks Databricks-Certified-Data-Analyst-Associate자격증 취득만으로 이 경쟁이 심한 사회에서 자신만의위치를 보장할수 있고 더욱이는 한층업된 삶을 누릴수 있을수도 있습니다. 우리ExamPassdump 에서 여러분은Databricks Databricks-Certified-Data-Analyst-Associate관련 학습지도서를 얻을 수 있습니다. 우리ExamPassdump는 IT업계엘리트 한 강사들이 퍼펙트한Databricks Databricks-Certified-Data-Analyst-Associate문제집을 만들어서 제공합니다. 우리가 제공하는Databricks Databricks-Certified-Data-Analyst-Associate문제와 답으로 여러분은 한번에 성공적으로 시험을 패스 하실수 있습니다. 중요한것 저희 문제집을 선택함으로 여러분의 시간도 절약해드리고 무엇보다도 많은 근심없이 심플하게 시험을 패스하여 좋다는 점입니다.
Databricks Databricks-Certified-Data-Analyst-Associate 시험요강:
| 주제 | 소개 |
|---|
| 주제 1 | - Data Management: The topic describes Delta Lake as a tool for managing data files, Delta Lake manages table metadata, benefits of Delta Lake within the Lakehouse, tables on Databricks, a table owner’s responsibilities, and the persistence of data. It also identifies management of a table, usage of Data Explorer by a table owner, and organization-specific considerations of PII data. Lastly, the topic it explains how the LOCATION keyword changes, usage of Data Explorer to secure data.
|
| 주제 2 | - SQL in the Lakehouse: It identifies a query that retrieves data from the database, the output of a SELECT query, a benefit of having ANSI SQL, access, and clean silver-level data. It also compares and contrasts MERGE INTO, INSERT TABLE, and COPY INTO. Lastly, this topic focuses on creating and applying UDFs in common scaling scenarios.
|
| 주제 3 | - Analytics applications: It describes key moments of statistical distributions, data enhancement, and the blending of data between two source applications. Moroever, the topic also explains last-mile ETL, a scenario in which data blending would be beneficial, key statistical measures, descriptive statistics, and discrete and continuous statistics.
|
| 주제 4 | - Databricks SQL: This topic discusses key and side audiences, users, Databricks SQL benefits, complementing a basic Databricks SQL query, schema browser, Databricks SQL dashboards, and the purpose of Databricks SQL endpoints
- warehouses. Furthermore, the delves into Serverless Databricks SQL endpoint
- warehouses, trade-off between cluster size and cost for Databricks SQL endpoints
- warehouses, and Partner Connect. Lastly it discusses small-file upload, connecting Databricks SQL to visualization tools, the medallion architecture, the gold layer, and the benefits of working with streaming data.
|
| 주제 5 | - Data Visualization and Dashboarding: Sub-topics of this topic are about of describing how notifications are sent, how to configure and troubleshoot a basic alert, how to configure a refresh schedule, the pros and cons of sharing dashboards, how query parameters change the output, and how to change the colors of all of the visualizations. It also discusses customized data visualizations, visualization formatting, Query Based Dropdown List, and the method for sharing a dashboard.
|
>> Databricks-Certified-Data-Analyst-Associate최고품질 덤프문제보기 <<
높은 적중율을 자랑하는 Databricks-Certified-Data-Analyst-Associate최고품질 덤프문제보기 덤프는 Databricks Certified Data Analyst Associate Exam 100%시험패스 보장
많은 분들이 고난의도인 Databricks관련인증시험을 응시하고 싶어 하는데 이런 시험은 많은 전문적인 관련지식이 필요합니다. 시험은 당연히 완전히 전문적인 Databricks-Certified-Data-Analyst-Associate관련지식을 터득하자만이 패스할 가능성이 높습니다. 하지만 지금은 많은 방법들로 여러분의 부족한 면을 보충해드릴 수 있으며 또 힘든 Databricks시험도 패스하실 수 있습니다. 혹은 여러분은 전문적인 Databricks Certified Data Analyst Associate Exam관련지식을 터득하자들보다 더 간단히 더 빨리 시험을 패스하실 수 있습니다.
최신 Data Analyst Databricks-Certified-Data-Analyst-Associate 무료샘플문제 (Q10-Q15):
질문 # 10
A data analyst has created a user-defined function using the following line of code:
CREATE FUNCTION price(spend DOUBLE, units DOUBLE)
RETURNS DOUBLE
RETURN spend / units;
Which of the following code blocks can be used to apply this function to the customer_spend and customer_units columns of the table customer_summary to create column customer_price?
- A. SELECT PRICE customer_spend, customer_units AS customer_price FROM customer_summary
- B. SELECT function(price(customer_spend, customer_units)) AS customer_price FROM customer_summary
- C. SELECT double(price(customer_spend, customer_units)) AS customer_price FROM customer_summary
- D. SELECT price(customer_spend, customer_units) AS customer_price FROM customer_summary
- E. SELECT price FROM customer_summary
정답:D
설명:
A user-defined function (UDF) is a function defined by a user, allowing custom logic to be reused in the user environment1. To apply a UDF to a table, the syntax is SELECT udf_name(column_name) AS alias FROM table_name2. Therefore, option E is the correct way to use the UDF price to create a new column customer_price based on the existing columns customer_spend and customer_units from the table customer_summary. Reference:
What are user-defined functions (UDFs)?
User-defined scalar functions - SQL
V
질문 # 11
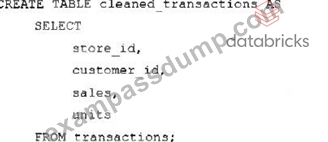
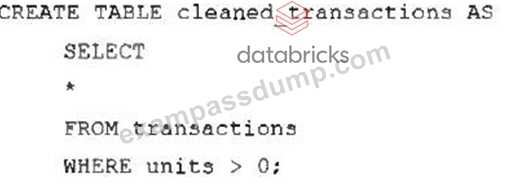
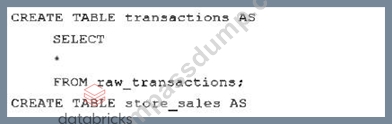
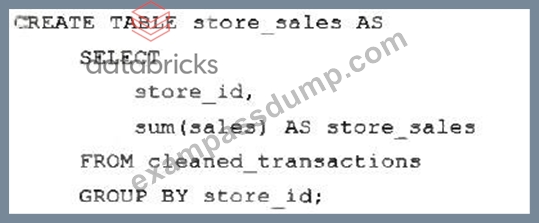
A data analyst is working in an organization that utilizes a multi-hop, medallion architecture. They have been tasked with creating a new Gold table from an existing Silver table.
Which query is performing a hop from a Silver table to a Gold table?
정답:D
설명:
Option C is the correct answer because it creates a new aggregated table, store_sales, from the existing cleaned
/refined table cleaned_transactions. In a medallion architecture, a table such as cleaned_transactions represents a Silver-layer table because it contains cleaned or validated transaction-level data. The query then creates store_sales by grouping by store_id and calculating SUM(sales), which is an aggregation suitable for analytics and reporting. That is exactly the Silver-to-Gold hop.
Option A creates cleaned_transactions from transactions, so it is moving toward a cleaned Silver table, not creating a Gold table. Option B creates transactions from raw_transactions, which is closer to a raw-to-Bronze or Bronze preparation step. Option D filters rows from transactions into cleaned_transactions, which is also a cleaning/validation step associated with Silver, not Gold.
Exact extract from official Databricks documentation: Databricks describes medallion architecture as improving data through "Bronze # Silver # Gold layer tables." The same official page identifies Silver as
"Data cleaning and validation" and Gold as "Dimensional modeling and aggregation." Databricks also states that the Gold layer "consists of aggregated data tailored for analytics and reporting."
질문 # 12
Which of the following should data analysts consider when working with personally identifiable information (PII) data?
- A. Organization-specific best practices for Pll data
- B. All of these considerations
- C. Legal requirements for the area in which the data was collected
- D. None of these considerations
- E. Legal requirements for the area in which the analysis is being performed
정답:B
설명:
Data analysts should consider all of these factors when working with PII data, as they may affect the data security, privacy, compliance, and quality. PII data is any information that can be used to identify a specific individual, such as name, address, phone number, email, social security number, etc. PII data may be subject to different legal and ethical obligations depending on the context and location of the data collection and analysis. For example, some countries or regions may have stricter data protection laws than others, such as the General Data Protection Regulation (GDPR) in the European Union. Data analysts should also follow the organization-specific best practices for PII data, such as encryption, anonymization, masking, access control, auditing, etc. These best practices can help prevent data breaches, unauthorized access, misuse, or loss of PII data. References:
* How to Use Databricks to Encrypt and Protect PII Data
* Automating Sensitive Data (PII/PHI) Detection
* Databricks Certified Data Analyst Associate
질문 # 13
A data analyst has two data sources that are providing similar but complementary information. The analyst wants to combine these sources of data into a single, comprehensive dataset for ongoing use for their team in a variety of different projects.
Which term is used to describe this type of work?
- A. Data testing
- B. Last-mile ETL
- C. Ad-hoc improvements
- D. Data blending
정답:D
설명:
Option D is correct. The scenario describes combining multiple complementary data sources into one comprehensive dataset. That is data blending. Last-mile ETL is usually project-specific final transformation near the end of an analytics workflow, while this question emphasizes combining two source datasets for broader ongoing team use. The current official Databricks exam guide describes the same kind of capability as creating unified datasets by joining data from multiple sources. That aligns with the concept of data blending. Reference: Databricks Certified Data Analyst Associate Exam Guide.
질문 # 14
A data analyst has a managed table table_name in database database_name. They would now like to remove the table from the database and all of the data files associated with the table. The rest of the tables in the database must continue to exist.
Which of the following commands can the analyst use to complete the task without producing an error?
- A. DELETE TABLE table_name FROM database_name;
- B. DROP TABLE database_name.table_name;
- C. DROP TABLE table_name FROM database_name;
- D. DROP DATABASE database_name;
- E. DELETE TABLE database_name.table_name;
정답:B
설명:
The DROP TABLE command removes a table from the metastore and deletes the associated data files. The syntax for this command is DROP TABLE [IF EXISTS] [database_name.]table_name;. The optional IF EXISTS clause prevents an error if the table does not exist. The optional database_name. prefix specifies the database where the table resides. If not specified, the current database is used. Therefore, the correct command to remove the table table_name from the database database_name and all of the data files associated with it is DROP TABLE database_name.table_name;. The other commands are either invalid syntax or would produce undesired results. Reference: Databricks - DROP TABLE
질문 # 15
......
Databricks Databricks-Certified-Data-Analyst-Associate인증시험은 현재IT업계에서 아주 인기 있는 시험입니다.많은 IT인사들이 관연 자격증을 취득하려고 노력하고 있습니다.Databricks Databricks-Certified-Data-Analyst-Associate인증시험에 대한 열기는 식지 않습니다.Databricks Databricks-Certified-Data-Analyst-Associate자격증은 여러분의 사회생활에 많은 도움이 될 것이며 연봉상승 등 생활보장에 업그레이드 될 것입니다.
Databricks-Certified-Data-Analyst-Associate최신버전 덤프공부자료: https://www.exampassdump.com/Databricks-Certified-Data-Analyst-Associate_valid-braindumps.html
- Databricks-Certified-Data-Analyst-Associate인증덤프 샘플 다운로드 🎶 Databricks-Certified-Data-Analyst-Associate시험문제 💬 Databricks-Certified-Data-Analyst-Associate시험대비 공부하기 🚼 무료 다운로드를 위해➡ Databricks-Certified-Data-Analyst-Associate ️⬅️를 검색하려면➠ www.pass4test.net 🠰을(를) 입력하십시오Databricks-Certified-Data-Analyst-Associate유효한 인증덤프
- 시험패스에 유효한 Databricks-Certified-Data-Analyst-Associate최고품질 덤프문제보기 덤프데모 다운 🥖 검색만 하면➤ www.itdumpskr.com ⮘에서✔ Databricks-Certified-Data-Analyst-Associate ️✔️무료 다운로드Databricks-Certified-Data-Analyst-Associate시험대비 공부하기
- 시험준비에 가장 좋은 Databricks-Certified-Data-Analyst-Associate최고품질 덤프문제보기 최신 덤프공부자료 🧩 검색만 하면{ www.dumptop.com }에서⇛ Databricks-Certified-Data-Analyst-Associate ⇚무료 다운로드Databricks-Certified-Data-Analyst-Associate덤프샘플문제 체험
- Databricks-Certified-Data-Analyst-Associate최고품질 인증시험 기출문제 ⏬ Databricks-Certified-Data-Analyst-Associate덤프샘플문제 체험 📋 Databricks-Certified-Data-Analyst-Associate최신버전덤프 🖋 ➠ www.itdumpskr.com 🠰을(를) 열고▷ Databricks-Certified-Data-Analyst-Associate ◁를 검색하여 시험 자료를 무료로 다운로드하십시오Databricks-Certified-Data-Analyst-Associate덤프샘플문제 체험
- Databricks-Certified-Data-Analyst-Associate덤프샘플문제 체험 ⚔ Databricks-Certified-Data-Analyst-Associate최고품질 예상문제모음 🤨 Databricks-Certified-Data-Analyst-Associate최고품질 예상문제모음 🗓 무료로 쉽게 다운로드하려면☀ www.pass4test.net ️☀️에서▷ Databricks-Certified-Data-Analyst-Associate ◁를 검색하세요Databricks-Certified-Data-Analyst-Associate최고품질 인증시험 기출문제
- Databricks-Certified-Data-Analyst-Associate덤프샘플문제 체험 💈 Databricks-Certified-Data-Analyst-Associate인증시험대비 공부자료 🚄 Databricks-Certified-Data-Analyst-Associate시험대비 공부하기 ↔ ⮆ www.itdumpskr.com ⮄웹사이트를 열고《 Databricks-Certified-Data-Analyst-Associate 》를 검색하여 무료 다운로드Databricks-Certified-Data-Analyst-Associate유효한 인증덤프
- Databricks-Certified-Data-Analyst-Associate인증시험 덤프문제 🛫 Databricks-Certified-Data-Analyst-Associate최고품질 예상문제모음 🚺 Databricks-Certified-Data-Analyst-Associate최신버전 시험덤프 🤜 ▷ www.passtip.net ◁을 통해 쉽게⏩ Databricks-Certified-Data-Analyst-Associate ⏪무료 다운로드 받기Databricks-Certified-Data-Analyst-Associate인증덤프공부자료
- Databricks-Certified-Data-Analyst-Associate최고품질 덤프문제보기 완벽한 시험덤프 데모문제 다운 😒 시험 자료를 무료로 다운로드하려면▷ www.itdumpskr.com ◁을 통해「 Databricks-Certified-Data-Analyst-Associate 」를 검색하십시오Databricks-Certified-Data-Analyst-Associate시험문제
- Databricks-Certified-Data-Analyst-Associate시험대비 공부하기 😜 Databricks-Certified-Data-Analyst-Associate인증덤프 샘플 다운로드 💟 Databricks-Certified-Data-Analyst-Associate완벽한 시험공부자료 ✌ 검색만 하면( www.pass4test.net )에서⮆ Databricks-Certified-Data-Analyst-Associate ⮄무료 다운로드Databricks-Certified-Data-Analyst-Associate최신버전 덤프공부자료
- 시험패스에 유효한 Databricks-Certified-Data-Analyst-Associate최고품질 덤프문제보기 덤프데모 다운 🧶 【 www.itdumpskr.com 】에서《 Databricks-Certified-Data-Analyst-Associate 》를 검색하고 무료로 다운로드하세요Databricks-Certified-Data-Analyst-Associate시험대비 최신 공부자료
- 시험준비에 가장 좋은 Databricks-Certified-Data-Analyst-Associate최고품질 덤프문제보기 최신 덤프공부자료 😀 무료로 쉽게 다운로드하려면{ www.itdumpskr.com }에서➽ Databricks-Certified-Data-Analyst-Associate 🢪를 검색하세요Databricks-Certified-Data-Analyst-Associate시험대비 최신 공부자료
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, learn.csisafety.com.au, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
2026 ExamPassdump 최신 Databricks-Certified-Data-Analyst-Associate PDF 버전 시험 문제집과 Databricks-Certified-Data-Analyst-Associate 시험 문제 및 답변 무료 공유: https://drive.google.com/open?id=1Usuw4Nb317rUXntni-vvz7iVmP2jHa8I