MLA-C01 Pass Guaranteed | MLA-C01 Exam Voucher

2026 Latest Pass4training MLA-C01 PDF Dumps and MLA-C01 Exam Engine Free Share: https://drive.google.com/open?id=1Q4RhjGzU_kvZSsQkOLoiyt2cu8ZjcWii
Our company has been putting emphasis on the development and improvement of MLA-C01 test prep over ten year without archaic content at all. So we are bravely breaking the stereotype of similar content materials of the exam, but add what the exam truly tests into our MLA-C01 exam guide. So we have adamant attitude to offer help rather than perfunctory attitude. All MLA-C01 Test Prep is made without levity and the passing rate has up to 98 to 100 percent now. We esteem your variant choices so all these versions of MLA-C01 exam guides are made for your individual preference and inclination.
| Topic | Details |
|---|
| Topic 1 | - Data Preparation for Machine Learning (ML): This section of the exam measures skills of Forensic Data Analysts and covers collecting, storing, and preparing data for machine learning. It focuses on understanding different data formats, ingestion methods, and AWS tools used to process and transform data. Candidates are expected to clean and engineer features, ensure data integrity, and address biases or compliance issues, which are crucial for preparing high-quality datasets in fraud analysis contexts.
|
| Topic 2 | - Deployment and Orchestration of ML Workflows: This section of the exam measures skills of Forensic Data Analysts and focuses on deploying machine learning models into production environments. It covers choosing the right infrastructure, managing containers, automating scaling, and orchestrating workflows through CI
- CD pipelines. Candidates must be able to build and script environments that support consistent deployment and efficient retraining cycles in real-world fraud detection systems.
|
| Topic 3 | - ML Solution Monitoring, Maintenance, and Security: This section of the exam measures skills of Fraud Examiners and assesses the ability to monitor machine learning models, manage infrastructure costs, and apply security best practices. It includes setting up model performance tracking, detecting drift, and using AWS tools for logging and alerts. Candidates are also tested on configuring access controls, auditing environments, and maintaining compliance in sensitive data environments like financial fraud detection.
|
| Topic 4 | - ML Model Development: This section of the exam measures skills of Fraud Examiners and covers choosing and training machine learning models to solve business problems such as fraud detection. It includes selecting algorithms, using built-in or custom models, tuning parameters, and evaluating performance with standard metrics. The domain emphasizes refining models to avoid overfitting and maintaining version control to support ongoing investigations and audit trails.
|
>> MLA-C01 Pass Guaranteed <<
Trusted MLA-C01 Pass Guaranteed & Realistic MLA-C01 Exam Voucher & Valid Amazon AWS Certified Machine Learning Engineer - Associate
You can prepare for the AWS Certified Machine Learning Engineer - Associate exam without an internet connection using the offline version of the mock exam. Amazon MLA-C01 practice test not only gives you the opportunity to practice with real exam questions but also provides you with a self-assessment report highlighting your performance in an attempt. Pass4training keeps an eye on changes in the Amazon AWS Certified Machine Learning Engineer - Associate exam syllabus and updates Amazon MLA-C01 Exam Dumps accordingly to make sure they are relevant to the latest exam topics. After making the payment for Amazon MLA-C01 dumps questions you’ll be able to get free updates for up to 365 days. Another thing you will get from using the MLA-C01 exam study material is free to support. If you encounter any problem while using the MLA-C01 prep material, you have nothing to worry about.
Amazon AWS Certified Machine Learning Engineer - Associate Sample Questions (Q11-Q16):
NEW QUESTION # 11
An ML engineer is developing a classification model. The ML engineer needs to use custom libraries in processing jobs, training jobs, and pipelines in Amazon SageMaker AI.
Which solution will provide this functionality with the LEAST implementation effort?
- A. Build a custom Docker container that includes the required libraries. Host the container in Amazon Elastic Container Registry (Amazon ECR). Use the ECR image in the SageMaker AI jobs and pipelines.
- B. Run code externally on Amazon EC2 and import results into SageMaker AI.
- C. Manually install the libraries in the SageMaker AI containers.
- D. Use a SageMaker AI notebook instance and install libraries at startup.
Answer: A
Explanation:
AWS documentation strongly recommends using custom Docker containers when ML workloads require consistent access to custom dependencies across processing jobs, training jobs, and pipelines.
By building a single Docker image that contains all required libraries and hosting it in Amazon ECR, the ML engineer ensures that every SageMaker job uses the same runtime environment. This approach eliminates the need for repetitive installation steps and avoids environment drift.
Manually installing libraries in managed containers is error-prone and not reusable across jobs. Notebook instances are not designed to host production jobs and pipelines. Running code externally breaks the SageMaker workflow and increases operational complexity.
Using a custom container is a one-time setup that provides maximum reuse with minimal ongoing effort, making it the least implementation effort option in the long run.
Therefore, Option B is the correct and AWS-recommended answer.
NEW QUESTION # 12
A hospital wants to predict patient outcomes for the coming year An ML engineer must improve several existing ML models that currently perform poorly.
Select the correct regularization method from the following list to improve each model Select each regularization method one time, more than one time, or not at all. (Select THREE.)
* L1 regularization
* L2 regularization
* Early stopping
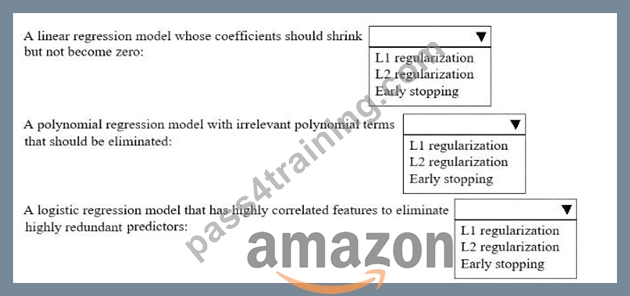
Answer:
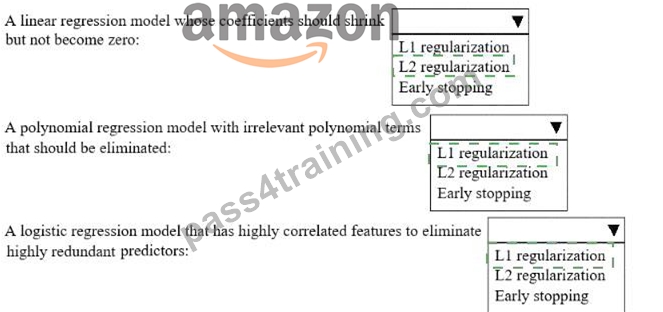
Explanation:
Explanation:
Linear regression model whose coefficients should shrink but not become zero answer: L2 regularization AWS says L2 produces smaller overall weight values and is the right fit when coefficients should be reduced without being forced to zero.
Polynomial regression model with irrelevant polynomial terms that should be eliminated answer: L1 regularization AWS says L1 reduces the number of features used by pushing small weights to zero , which matches elimination of irrelevant terms.
Logistic regression model that has highly correlated features to eliminate highly redundant predictors L1 regularization This is the nuanced one. AWS says L2 stabilizes weights when there is high correlation between features , but because the question explicitly says eliminate highly redundant predictors , L1 is the better match since it creates sparsity and removes predictors by zeroing coefficients.
NEW QUESTION # 13
Case Study
A company is building a web-based AI application by using Amazon SageMaker. The application will provide the following capabilities and features: ML experimentation, training, a central model registry, model deployment, and model monitoring.
The application must ensure secure and isolated use of training data during the ML lifecycle. The training data is stored in Amazon S3.
The company is experimenting with consecutive training jobs.
How can the company MINIMIZE infrastructure startup times for these jobs?
- A. Use SageMaker Training Compiler.
- B. Use SageMaker managed warm pools.
- C. Use Managed Spot Training.
- D. Use the SageMaker distributed data parallelism (SMDDP) library.
Answer: B
NEW QUESTION # 14
A company has an existing Amazon SageMaker AI model (v1) on a production endpoint. The company develops a new model version (v2) and needs to test v2 in production before substituting v2 for v1.
The company needs to minimize the risk of v2 generating incorrect output in production and must prevent any disruption of production traffic during the change.
Which solution will meet these requirements?
- A. Deploy v2 to a new endpoint. Turn on data capture for the production endpoint. Send 100% of the input data to v2.
- B. Create a second production variant for v2. Assign 10% of the traffic to v2 and 90% to v1. Collect all output of v2 in Amazon S3. If v2 performs as expected, switch all traffic to v2.
- C. Create a second production variant for v2. Assign 1% of the traffic to v2 and 99% to v1. Collect all output of v2 in Amazon S3. If v2 performs as expected, switch all traffic to v2.
- D. Deploy v2 into a shadow variant that samples 100% of the inference requests. Collect all output in Amazon S3. If v2 performs as expected, promote v2 to production.
Answer: D
Explanation:
AWS recommends SageMaker shadow testing as the safest way to validate a new model version using real production traffic without impacting production responses. A shadow variant receives a copy of inference requests but does not return predictions to end users. This completely eliminates the risk of exposing incorrect predictions.
Options A and B are canary deployments. While useful, they still allow v2 to return responses to real users, which violates the requirement to prevent disruption. Option C sends 100% of traffic to v2 externally and is risky.
Shadow variants are explicitly designed to minimize risk while using real data, making them the AWS best practice for pre-production validation.
Therefore, Option D is correct.
NEW QUESTION # 15
A company deployed an ML model that uses the XGBoost algorithm to predict product failures.
The model is hosted on an Amazon SageMaker endpoint and is trained on normal operating data.
An AWS Lambda function provides the predictions to the company's application.
An ML engineer must implement a solution that uses incoming live data to detect decreased model accuracy over time.
Which solution will meet these requirements?
- A. Modify the Lambda function to calculate model drift by using real-time inference data and model predictions. Program the Lambda function to send alerts.
- B. Schedule a monitoring job in SageMaker Debugger. Use the job to detect drift by analyzing the live data against a baseline of the training data statistics and constraints.
- C. Schedule a monitoring job in SageMaker Model Monitor. Use the job to detect drift by analyzing the live data against a baseline of the training data statistics and constraints.
- D. Use Amazon CloudWatch to create a dashboard that monitors real-time inference data and model predictions. Use the dashboard to detect drift.
Answer: C
NEW QUESTION # 16
......
The Amazon MLA-C01 certification exam is one of the hottest and career-oriented AWS Certified Machine Learning Engineer - Associate (MLA-C01) exams. With the AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam you can validate your skills and upgrade your knowledge level. By doing this you can learn new in-demand skills and gain multiple career opportunities. To do this you just need to enroll in the Amazon MLA-C01 Certification Exam and put all your efforts to pass this important Amazon MLA-C01 Exam Questions.
MLA-C01 Exam Voucher: https://www.pass4training.com/MLA-C01-pass-exam-training.html
- Pass Guaranteed 2026 Efficient Amazon MLA-C01 Pass Guaranteed ⬇ Open “ www.prep4away.com ” and search for ▷ MLA-C01 ◁ to download exam materials for free 😗MLA-C01 Exam Fee
- Valid MLA-C01 Test Guide 📼 MLA-C01 Exams Torrent ☯ MLA-C01 Exams Torrent 🍧 Simply search for ▷ MLA-C01 ◁ for free download on ➽ www.pdfvce.com 🢪 😋Valid MLA-C01 Test Guide
- 100% Pass 2026 Amazon High-quality MLA-C01 Pass Guaranteed 🔐 The page for free download of 「 MLA-C01 」 on ➡ www.dumpsquestion.com ️⬅️ will open immediately 😷Latest MLA-C01 Mock Test
- MLA-C01 Real Braindumps 😨 MLA-C01 Frequent Updates 🍼 MLA-C01 Frequent Updates 🔅 Download ☀ MLA-C01 ️☀️ for free by simply entering ▛ www.pdfvce.com ▟ website 🏢Valid MLA-C01 Test Review
- Certification MLA-C01 Dumps 🤺 MLA-C01 Dump Torrent 🧇 MLA-C01 Pass4sure Study Materials 🏍 Download “ MLA-C01 ” for free by simply searching on { www.testkingpass.com } 🚛New MLA-C01 Test Simulator
- Valid MLA-C01 Test Review 🛣 Relevant MLA-C01 Exam Dumps 🔝 MLA-C01 Frequent Updates ❎ Search for ▶ MLA-C01 ◀ and download it for free immediately on ➥ www.pdfvce.com 🡄 🦆Valid MLA-C01 Test Review
- Valid MLA-C01 Test Duration 🔥 MLA-C01 Exam Fee 🎒 MLA-C01 Exam Pattern 🙌 Immediately open “ www.practicevce.com ” and search for ☀ MLA-C01 ️☀️ to obtain a free download 👪New MLA-C01 Test Simulator
- Free PDF Quiz 2026 Amazon MLA-C01 High Hit-Rate Pass Guaranteed ✌ Search for ( MLA-C01 ) and download it for free immediately on 「 www.pdfvce.com 」 ⏰Well MLA-C01 Prep
- MLA-C01 Pass Guaranteed | High Pass-Rate AWS Certified Machine Learning Engineer - Associate 100% Free Exam Voucher 💭 Open website 《 www.pdfdumps.com 》 and search for ➥ MLA-C01 🡄 for free download 💍Certification MLA-C01 Dumps
- Amazon - MLA-C01 - AWS Certified Machine Learning Engineer - Associate –High Pass-Rate Pass Guaranteed 👦 The page for free download of ➡ MLA-C01 ️⬅️ on ⇛ www.pdfvce.com ⇚ will open immediately 🧾MLA-C01 Exam Collection Pdf
- Certification MLA-C01 Dumps 🆑 MLA-C01 Pass4sure Study Materials ⏩ Passing MLA-C01 Score 😦 Search for ➽ MLA-C01 🢪 and download it for free on ➤ www.troytecdumps.com ⮘ website 🌲MLA-C01 Frequent Updates
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free & New MLA-C01 dumps are available on Google Drive shared by Pass4training: https://drive.google.com/open?id=1Q4RhjGzU_kvZSsQkOLoiyt2cu8ZjcWii