P.S. NewDumps在Google Drive上分享了免費的、最新的Databricks-Certified-Data-Engineer-Professional考試題庫:https://drive.google.com/open?id=1RlDwyWCuX90hXA8pRCjxPhd1edCGcDHQ
手上能拿到一些實用的認證證書,無疑為自己的就業開拓了一番新的領土和創造了一些機會。Databricks-Certified-Data-Engineer-Professional 是全球最大的網絡設備公司 Databricks 公司的認可的初級技術認證,在整個 Databricks 認證體系中處于售前規劃方向的基礎證書,有了Databricks-Certified-Data-Engineer-Professional 認證你的平均年薪將不低于10萬人民幣。雖然獲取 Databricks-Certified-Data-Engineer-Professional 認證需要投入額外的時間與金錢,但事實證明IT認證的投入產出是值得的,對於未來的職業發展非常有利。
| Section | Objectives |
|---|---|
| Delta Lake and Data Management | - Delta Lake transactions and ACID properties - Time travel and versioning - Schema evolution and enforcement |
| Data Modeling and Transformation | - Dimensional modeling concepts - Performance optimization techniques - Spark SQL transformations |
| Databricks Lakehouse Platform Architecture | - Medallion architecture (Bronze, Silver, Gold) - Data governance concepts (Unity Catalog basics) - Workspace and cluster architecture |
| Production Pipelines and Orchestration | - Job scheduling and monitoring - Error handling and recovery strategies - Databricks Workflows |
| Data Ingestion and Processing | - Batch and streaming ingestion with Auto Loader - ETL pipeline design patterns - Structured Streaming fundamentals |
>> Databricks-Certified-Data-Engineer-Professional題庫下載 <<
各行各業的人們都在為了將來能做出點什麼成績而努力。在IT行業工作的你肯定也在努力提高自己的技能吧。那麼,你已經取得了現在最受歡迎的Databricks的Databricks-Certified-Data-Engineer-Professional認定考試的資格了嗎?對於Databricks-Certified-Data-Engineer-Professional考試,你瞭解多少呢?如果你想通過這個考試但是掌握的相關知識不足,你應該怎麼辦呢?不用著急,NewDumps可以給你提供幫助。
問題 #206
A production workload incrementally applies updates from an external Change Data Capture feed to a Delta Lake table as an always-on Structured Stream job. When data was initially migrated for this table, OPTIMIZE was executed and most data files were resized to 1 GB. Auto Optimize and Auto Compaction were both turned on for the streaming production job. Recent review of data files shows that most data files are under 64 MB, although each partition in the table contains at least 1 GB of data and the total table size is over 10 TB.
Which of the following likely explains these smaller file sizes?
答案:C
解題說明:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from This is the correct answer because Databricks has a feature called Auto Optimize, which automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones and sorting data within each file by a specified column. However, Auto Optimize also considers the trade- off between file size and merge performance, and may choose a smaller target file size to reduce the duration of merge operations, especially for streaming workloads that frequently update existing records. Therefore, it is possible that Auto Optimize has autotuned to a smaller target file size based on the characteristics of the streaming production job.
問題 #207
A streaming video analytics team ingests billions of events daily into a Unity Catalog-managed Delta table video_events. Analysts run ad-hoc point-lookup queries on columns like user_id, campaign_id, and region. The team manually runs OPTIMIZE video_events ZORDER BY (user_id, campaign_id, region), but still sees poor performance on recent data and dislikes the operational overhead. The team wants a hands-off way to keep hot columns co-located as query patterns evolve. Which Delta capability should the team leverage on video_events?
答案:D
解題說明:
According to Databricks Delta Lake optimization documentation, Liquid Clustering is a next- generation file organization capability that automatically manages file co-location without requiring explicit partitioning or manual Z-ORDERing. When combined with Predictive Optimization, Databricks automatically maintains clustering across frequently filtered or queried columns, adapting dynamically as query workloads evolve.
This approach eliminates the need for manual maintenance (such as periodic OPTIMIZE or Z- ORDER commands) while improving query performance on large tables--particularly for high- ingest streaming workloads.
Delta caching (B) only improves performance for cached queries and does not address file layout issues, and (D) handles file size optimization but not clustering. Thus, C is the most efficient, modern, and low-maintenance solution recommended by Databricks.
問題 #208
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from user. They then modify their code to the following (leaving all other variables unchanged).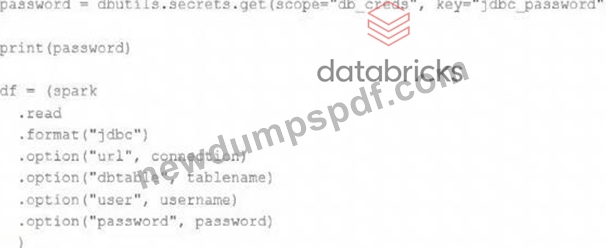
Which statement describes what will happen when the above code is executed?
答案:D
解題說明:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks.
問題 #209
Which statement regarding spark configuration on the Databricks platform is true?
答案:A
解題說明:
When Spark configuration properties are set for an interactive cluster using the Clusters UI in Databricks, those configurations are applied at the cluster level. This means that all notebooks attached to that cluster will inherit and be affected by these configurations. This approach ensures consistency across all executions within that cluster, as the Spark configuration properties dictate aspects such as memory allocation, number of executors, and other vital execution parameters. This centralized configuration management helps maintain standardized execution environments across different notebooks, aiding in debugging and performance optimization.
問題 #210
A data engineer is attempting to execute the following PySpark code:
df = spark.read.table("sales")
result = df.groupBy("region").agg(sum("revenue"))
However, upon inspecting the execution plan and profiling the Spark job, they observe excessive data shuffling during the aggregation phase.
Which technique should be applied to reduce shuffling during the groupBy aggregation operation?
答案:B
解題說明:
Repartitioning the DataFrame by the grouping key ensures that records with the same region are colocated in the same partitions before the aggregation runs. This significantly reduces the amount of data shuffled during the groupBy operation, leading to more efficient execution.
問題 #211
......
NewDumps不僅可靠性強,而且服務也很好。如果你選擇了NewDumps但是Databricks-Certified-Data-Engineer-Professional考試沒有成功,我們會100%全額退款給您。NewDumps還會為你提供一年的免費更新服務。
Databricks-Certified-Data-Engineer-Professional測試引擎: https://www.newdumpspdf.com/Databricks-Certified-Data-Engineer-Professional-exam-new-dumps.html
P.S. NewDumps在Google Drive上分享了免費的、最新的Databricks-Certified-Data-Engineer-Professional考試題庫:https://drive.google.com/open?id=1RlDwyWCuX90hXA8pRCjxPhd1edCGcDHQ