我々社はAnthropic CCAR-P問題集をリリースされる以来、たくさんの好評を博しました。試験に合格したお客様は「CCAR-P問題集のオンライン版を利用して、模擬試験を繰り返して受けました。無事試験に合格しました。JPTestKingから大変助かりました。」と感謝します。あなたの支持こそ我々は最も高品質のAnthropic CCAR-P問題集を開発して努力します。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Evaluation, Testing & Optimization | 16% | - Implement iterative improvement pipelines - Test accuracy, reliability, latency, and cost - Optimize performance, prompting, and model selection - Define evaluation metrics and success criteria |
| Topic 2: Claude Models, Prompting & Context Engineering | 13% | - Mitigate prompt injection, leaks, and jailbreak risks - Apply context engineering and context management techniques - Design system prompts, templates, and guardrails - Select appropriate Claude models based on trade-offs |
| Topic 3: Integration | 19% | - Design authentication, authorization, and observability - Integrate with data pipelines and RAG systems - Integrate Claude with enterprise systems, APIs, and tools - Implement Model Context Protocol (MCP) integrations |
| Topic 4: Governance, Safety & Risk Management | 14% | - Implement guardrails and safety controls - Address ethical AI considerations and bias mitigation - Ensure regulatory compliance (GDPR, HIPAA, etc.) - Manage data privacy and security compliance |
| Topic 5: Developer Productivity & Operational Enablement | 7% | - Improve developer workflows with AI-assisted tooling - Support debugging, monitoring, and operational resolution - Configure Claude tools and environments for teams |
| Topic 6: Solution Design & Architecture | 17% | - Design multi-agent systems and orchestration strategies - Translate business problems into Claude-based AI solutions - Select architectural patterns: workflow, agentic, augmented LLM - Design end-to-end architectures and feedback loops - Align solutions to business value pillars |
| Topic 7: Stakeholder Communication & Lifecycle Management | 14% | - Document architectures and support full lifecycle phases - Manage stakeholder feedback and expectation alignment - Conduct structured discovery and requirement gathering - Communicate architectural decisions and trade-offs |
JPTestKing最高のCCAR-Pテストトレントを提供する世界的なリーダーとして、私たちは大多数の消費者に包括的なサービスを提供し、統合サービスの構築に努めています。 さらに、CCAR-P認定トレーニングアプリケーションのほか、インタラクティブな共有およびアフターサービスでブレークスルーを達成しました。 実際問題として、当社Anthropicはすべてのクライアントの適切なソリューションの問題を考慮しています。 ヘルプが必要な場合は、CCAR-Pガイドトレントに関するClaude Certified Architect - Professional問題に対処するための即時サポートを提供し、CCAR-P試験の合格を支援します。
質問 # 120
You are classifying chunking strategies by the corpus type each is best suited to.
For each chunking strategy, select the appropriate corpus type: "Long Structured Documents,"
"Heterogeneous Short Records," or "Code or Hierarchical Specifications."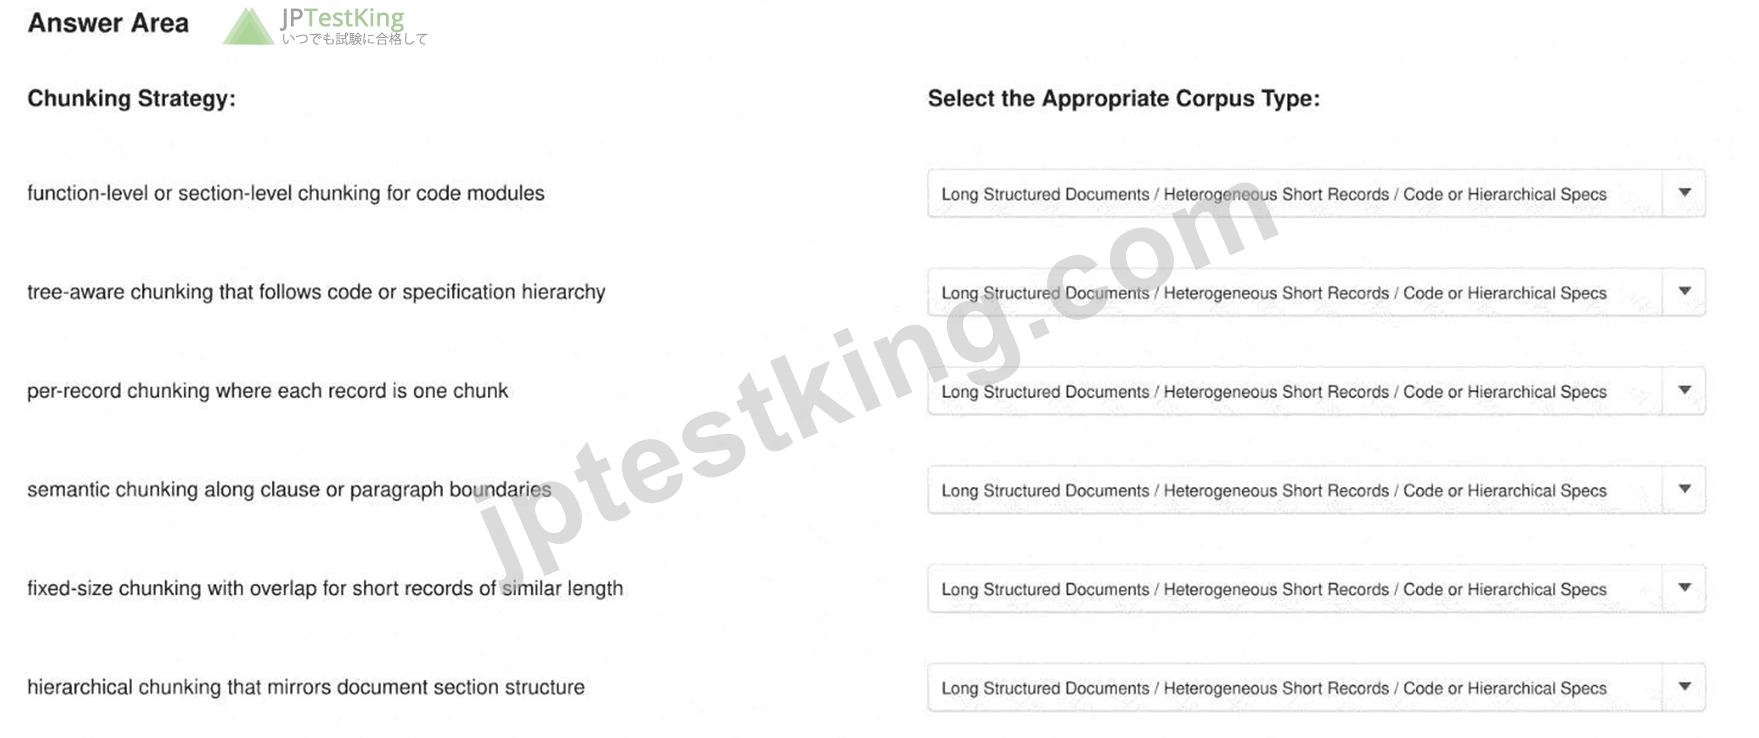
正解:
解説: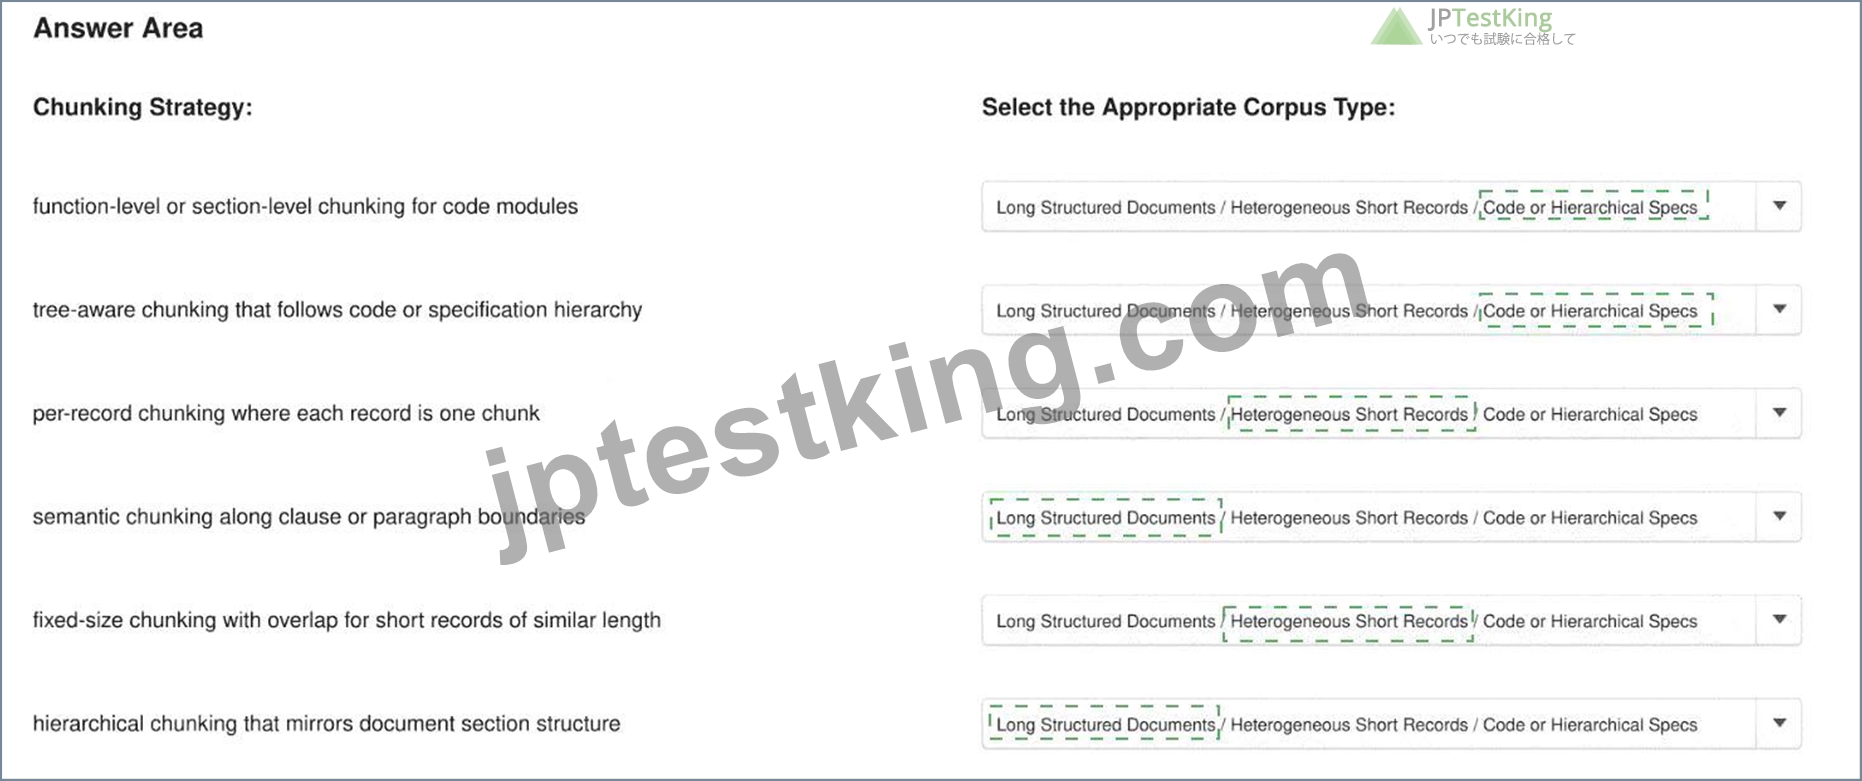
Explanation:
* Function-level or section-level chunking for code modules - Code or Hierarchical Specifications
* Tree-aware chunking that follows code or specification hierarchy - Code or Hierarchical Specifications
* Per-record chunking where each record is one chunk - Heterogeneous Short Records
* Semantic chunking along clause or paragraph boundaries - Long Structured Documents
* Fixed-size chunking with overlap for short records of similar length - Heterogeneous Short Records
* Hierarchical chunking that mirrors document section structure - Long Structured Documents Chunking must preserve the structural unit that carries meaning in the source corpus. Code and hierarchical specifications are best divided at function, module, class, or tree boundaries because arbitrary token cuts can separate definitions from their implementation or parent context. Heterogeneous short-record collections should generally preserve each record as an independent chunk. Fixed-size overlapping chunks are also effective when records have broadly similar lengths and lack meaningful internal hierarchy. Long structured documents benefit from semantic boundaries such as clauses and paragraphs, while hierarchical chunking preserves relationships among sections, subsections, and parent headings. Anthropic notes that chunk size, boundaries, and overlap materially affect retrieval performance; therefore, one universal chunking method is inappropriate. Anthropic Contextual Retrieval
質問 # 121
You must present an architectural recommendation to deploy a Claude-based contract review assistant to a steering committee that includes the CFO, the general counsel, and the CIO. Each stakeholder cares about different aspects of the decision.
How should you structure the recommendation document?
正解:A
解説:
A steering committee needs an answer-first recommendation that states the proposed architectural decision, the business outcome it supports, and the approval or action required. After establishing that common decision frame, the document should address each stakeholder's concerns separately.
The CFO requires implementation and operating costs, expected savings, consumption assumptions, financial exposure, and cost-control mechanisms. General counsel needs evidence concerning confidentiality, privilege, data handling, human legal review, explainability, retention, and regulatory risk. The CIO needs integration architecture, security boundaries, availability, scalability, operational ownership, technical dependencies, and lifecycle support.
Option A begins at an implementation depth unsuitable for the entire committee. Option B overweights the CFO's concerns and delays the rationale required by the other decision-makers. Option C ignores audience- specific responsibilities and forces every stakeholder to extract relevant information from an undifferentiated narrative.
The recommended structure is: decision and executive rationale, expected outcomes, accepted trade-offs, stakeholder-specific impact sections, major risks and controls, implementation implications, success metrics, and the requested governance decision. Technical appendices can preserve component-level detail without overwhelming the principal recommendation.
Study Guide references/topics: Executive communication; stakeholder differentiation; decision-first structure; financial, legal, and technology concerns; architectural recommendations.
質問 # 122
You are integrating AI-assisted tooling into the team's documentation workflow. The team wants generated documentation that stays grounded in the actual code.
Which integration approach best fits this requirement?
正解:A
解説:
Documentation remains grounded only when the generating agent can inspect the authoritative implementation. A purpose-built subagent should receive scoped filesystem and code-search capabilities, identify the relevant modules, interfaces, configuration files, tests, and call sites, and generate documentation from that evidence. This approach minimizes reliance on training-data recall, which cannot represent the repository's current private code or recent changes.
Subagents are useful because repository exploration occurs in their own context, allowing them to return focused findings or proposed edits without filling the main conversation with every file read. Their tool access should follow least privilege: read access to required paths, narrowly controlled write access, and explicit exclusions for secrets or unrelated repositories.
Generated documentation should enter the team's established change-control process as a patch, branch, or pull request. Normal review, automated checks, link validation, example execution, and human approval provide accountability and prevent unverified material from being published. Direct publication bypasses these safeguards, while disabling repository tools makes factual grounding impossible.
Study Guide references/topics: [Claude Code custom subagents](https://docs.anthropic.com/en/docs/claude- code/sub-agents); [codebase exploration workflows] (https://docs.anthropic.com/en/docs/claude-code
/common-workflows); source-grounded generation; least-privilege tools; human review and lifecycle controls.
質問 # 123
A revenue projection assistant has missed its monthly cost target by 38 percent. Profiling shows three contributors: a 6,000-token policy preamble repeated on every call (45 percent of cost), retrieval of historical sales chunks averaging 3,000 tokens per call (30 percent), and inference on a flagship-tier model (25 percent).
Stakeholders require that projection accuracy remain unchanged.
Which two optimizations should you sequence first to reduce cost without affecting accuracy? (Select two.) Each correct answer presents part of the solution.
正解:C、E
解説:
The required sequence must reduce repeated computation without changing the information or model capability used to generate projections. Prompt caching the static 6,000-token policy preamble directly addresses the largest cost contributor while preserving the complete instruction set. Anthropic states that cache reads cost substantially less than uncached input tokens, making repeated, stable prompt prefixes an ideal caching target. Prompt Caching Caching frequently reused historical-sales chunks applies the same principle to the retrieval layer. When identical, version-controlled chunks are repeatedly fetched and supplied to the model, caching their retrieval or reusable representation eliminates redundant work while maintaining the same evidence available to the projection process. The cache must use appropriate invalidation or source-version keys so updated sales data cannot be replaced by stale content.
Options A and B modify the information supplied to Claude. Fewer sales chunks could remove relevant historical evidence, while truncating policy instructions could alter constraints or projection behavior. Option D introduces a model-capability change and therefore cannot guarantee unchanged accuracy without a comparative evaluation. Those interventions may be considered later, but only after representative regression testing establishes equivalence.
Study Guide references/topics: Cost profiling; prompt caching; retrieval caching; cache invalidation; accuracy- preserving optimization; model and context trade-offs.
質問 # 124
You are a solution architect evaluating candidate use cases for a Claude-based program.
For each scenario, select Yes if Claude is appropriate as the primary solution at the architectural level.
Otherwise, select No.
正解:
解説: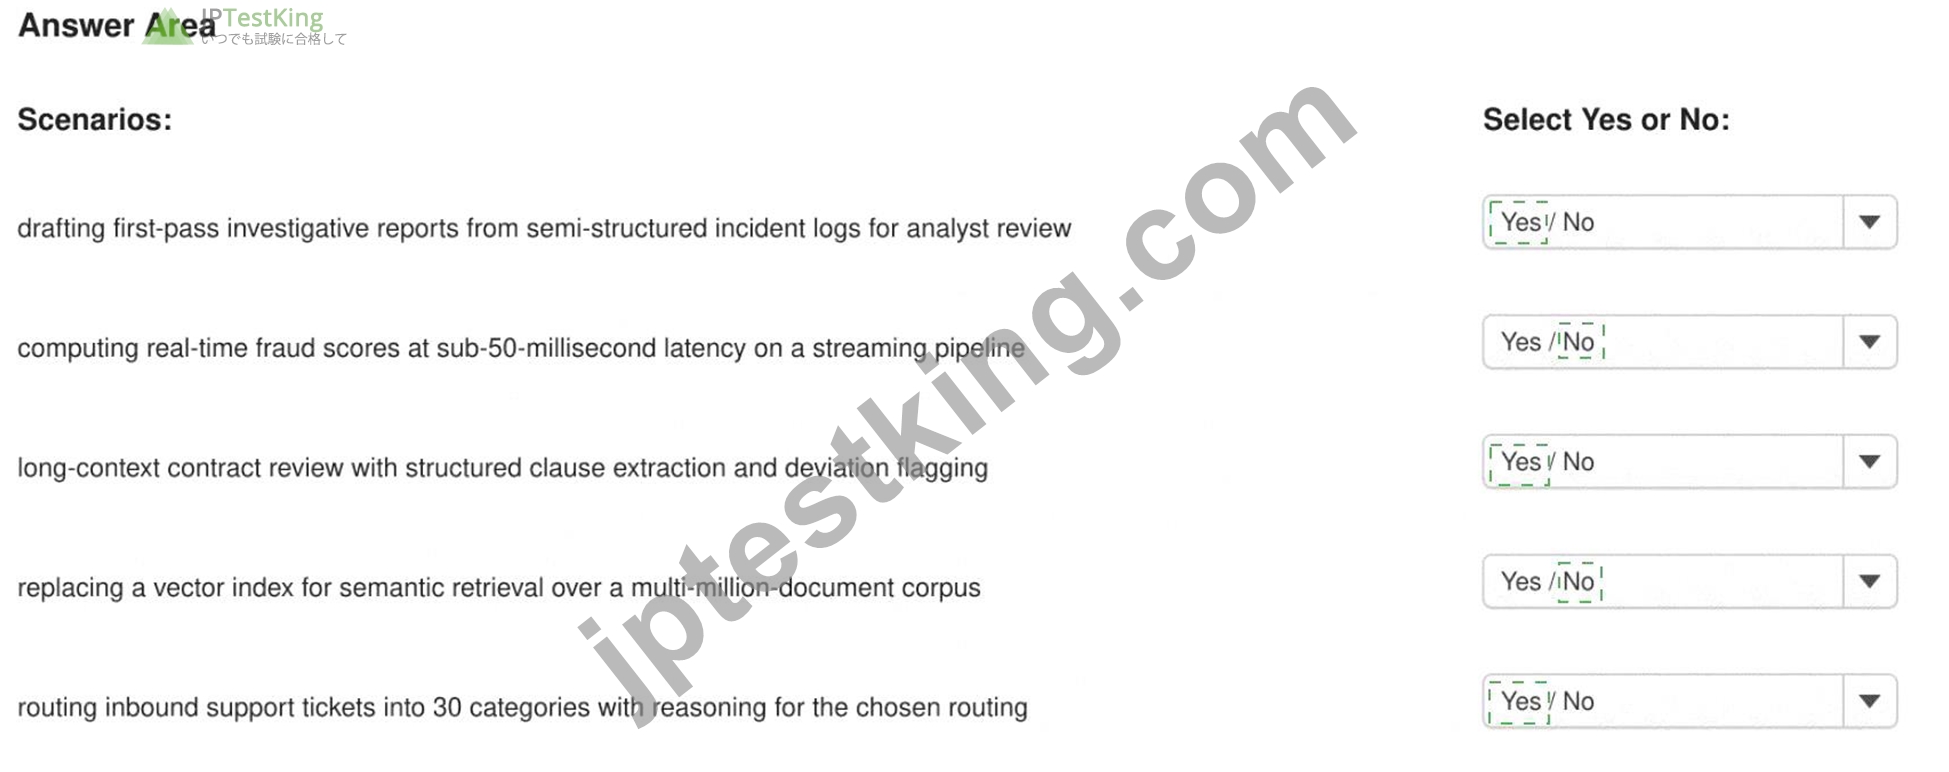
Explanation:
Drafting first-pass investigative reports from semi-structured incident logs for analyst review - Yes Computing real-time fraud scores at sub-50-millisecond latency on a streaming pipeline - No Long-context contract review with structured clause extraction and deviation flagging - Yes Replacing a vector index for semantic retrieval over a multi-million-document corpus - No Routing inbound support tickets into 30 categories with reasoning for the selected route - Yes Claude is well suited to language-intensive analysis, summarization, extraction, classification, and drafting.
Investigative-report drafting, contract analysis, and support-ticket routing all require interpretation of unstructured or semi-structured language and can incorporate human review. A sub-50-millisecond fraud- scoring path requires deterministic, specialized real-time processing and should not place LLM inference on the critical path. Claude also does not replace the retrieval index used to search millions of documents; it consumes the results produced by that infrastructure. The correct architectural decision separates tasks requiring semantic language reasoning from deterministic computation and information-retrieval infrastructure. Model selection and evaluation must then confirm that the chosen Claude model satisfies quality, latency, and cost requirements.
質問 # 125
......
JPTestKing を選択して100%のCCAR-P合格率を確保することができて、もしCCAR-P試験に失敗したら、JPTestKingが全額で返金いたします。
CCAR-Pテストサンプル問題: https://www.jptestking.com/CCAR-P-exam.html