P.S. Free 2026 Databricks Databricks-Certified-Professional-Data-Engineer dumps are available on Google Drive shared by Prep4King: https://drive.google.com/open?id=11qEFOFLRiFDWv659KBg_btolOzLObJSK
We want to provide our customers with different versions of Databricks-Certified-Professional-Data-Engineer test guides to suit their needs in order to learn more efficiently. Our Databricks-Certified-Professional-Data-Engineer qualification test can help you make full use of the time and resources to absorb knowledge and information. If you are accustomed to using the printed version of the material, we have a PDF version of the Databricks-Certified-Professional-Data-Engineer study tool for you to download and print, so that you can view the learning materials as long as you have free time. If you choose to study online, we have an assessment system that will make an assessment based on your learning of the Databricks-Certified-Professional-Data-Engineer qualification test to help you identify weaknesses so that you can understand your own defects of knowledge and develop a dedicated learning plan. Moreover our Databricks-Certified-Professional-Data-Engineer test guides provide customers with supplement service-mock test, which can totally inspire them to study hard and check for defects during their learning process. Our commitment is not frank, as long as you choose our Databricks-Certified-Professional-Data-Engineer study tool you will truly appreciate the benefits of our products.
| Section | Objectives |
|---|---|
| Topic 1: Data Ingestion and Transformation | - Handle batch and streaming data pipelines - Ingest data using Apache Spark and Databricks - Transform and clean datasets using Spark SQL and DataFrame APIs |
| Topic 2: Security, Governance, Monitoring, and Optimization | - Implement Unity Catalog governance and access control - Cost optimization and performance tuning - Monitor and optimize Spark workloads |
| Topic 3: Production Pipelines and Orchestration | - Automate ETL pipelines and scheduling - Build and manage workflows using Databricks Jobs - Pipeline reliability and fault tolerance |
| Topic 4: Data Modeling and Storage | - Delta Lake table design and optimization - Schema evolution and data partitioning strategies - Design scalable data lakehouse architectures |
>> Databricks-Certified-Professional-Data-Engineer Authorized Certification <<
At the time when people are hesitating about that which kind of Databricks-Certified-Professional-Data-Engineer study material should be chosen in order to prepare for the important exam I would like to recommend the Databricks-Certified-Professional-Data-Engineer training materials compiled by our company for you to complete the task. We have put substantial amount of money and effort into upgrading the quality of our Databricks-Certified-Professional-Data-Engineer Preparation material. There are so many advantages of our Databricks-Certified-Professional-Data-Engineer actual exam, such as free demo available, multiple choices, and practice test available to name but a few.
NEW QUESTION # 162
A data engineer, while designing a Pandas UDF to process financial time-series data with complex calculations that require maintaining state across rows within each stock symbol group, must ensure the function is efficient and scalable. Which approach will solve the problem with minimum overhead while preserving data integrity?
Answer: B
Explanation:
applyInPandas is the documented grouped Pandas API for processing each group as a pandas DataFrame.
Spark passes all columns for each group together, which allows per-group state to be maintained naturally inside the function. By contrast, scalar Pandas UDFs are batch-oriented Series-to-Series operations, not group- state processing tools. ( Apache Spark ) This is why option C is the intended best answer among the listed choices. Option A adds unnecessary external persistence overhead, option B relies on unsupported global executor state, and option D misuses grouped aggregation semantics for row-by-row stateful logic. Spark also documents applyInPandas specifically as a grouped operation, while scalar Pandas UDFs process row batches and concatenate results rather than preserving grouped state semantics. ( Apache Spark )
======
NEW QUESTION # 163
A nightly job ingests data into a Delta Lake table using the following code: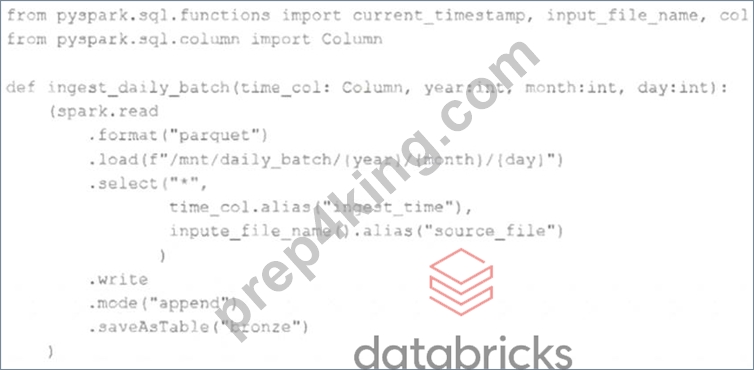
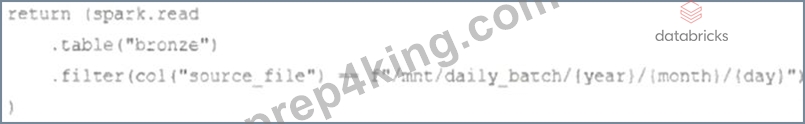
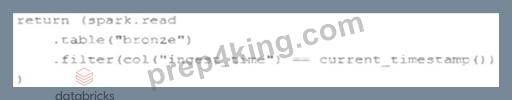
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
Answer: B
Explanation:
https://docs.databricks.com/en/delta/delta-change-data-feed.html
NEW QUESTION # 164
You are asked to set up an alert to notify in an email every time a KPI indicater increases beyond a threshold value, team also asked you to include the actual value in the alert email notification.
Answer: E
Explanation:
Explanation
Alerts support custom template supports using variables to customize the default message, set up the query to compare the KPI current value to the threshold and use the variable QUE-RY_RESULT_VALUE to display the value in the email notification.
here is a simple alert, that uses variables in the custom template to present these values in the email notification message, when the alert is fired these variables get replaced with actual values.
Alert with custom template
Graphical user interface, application Description automatically generated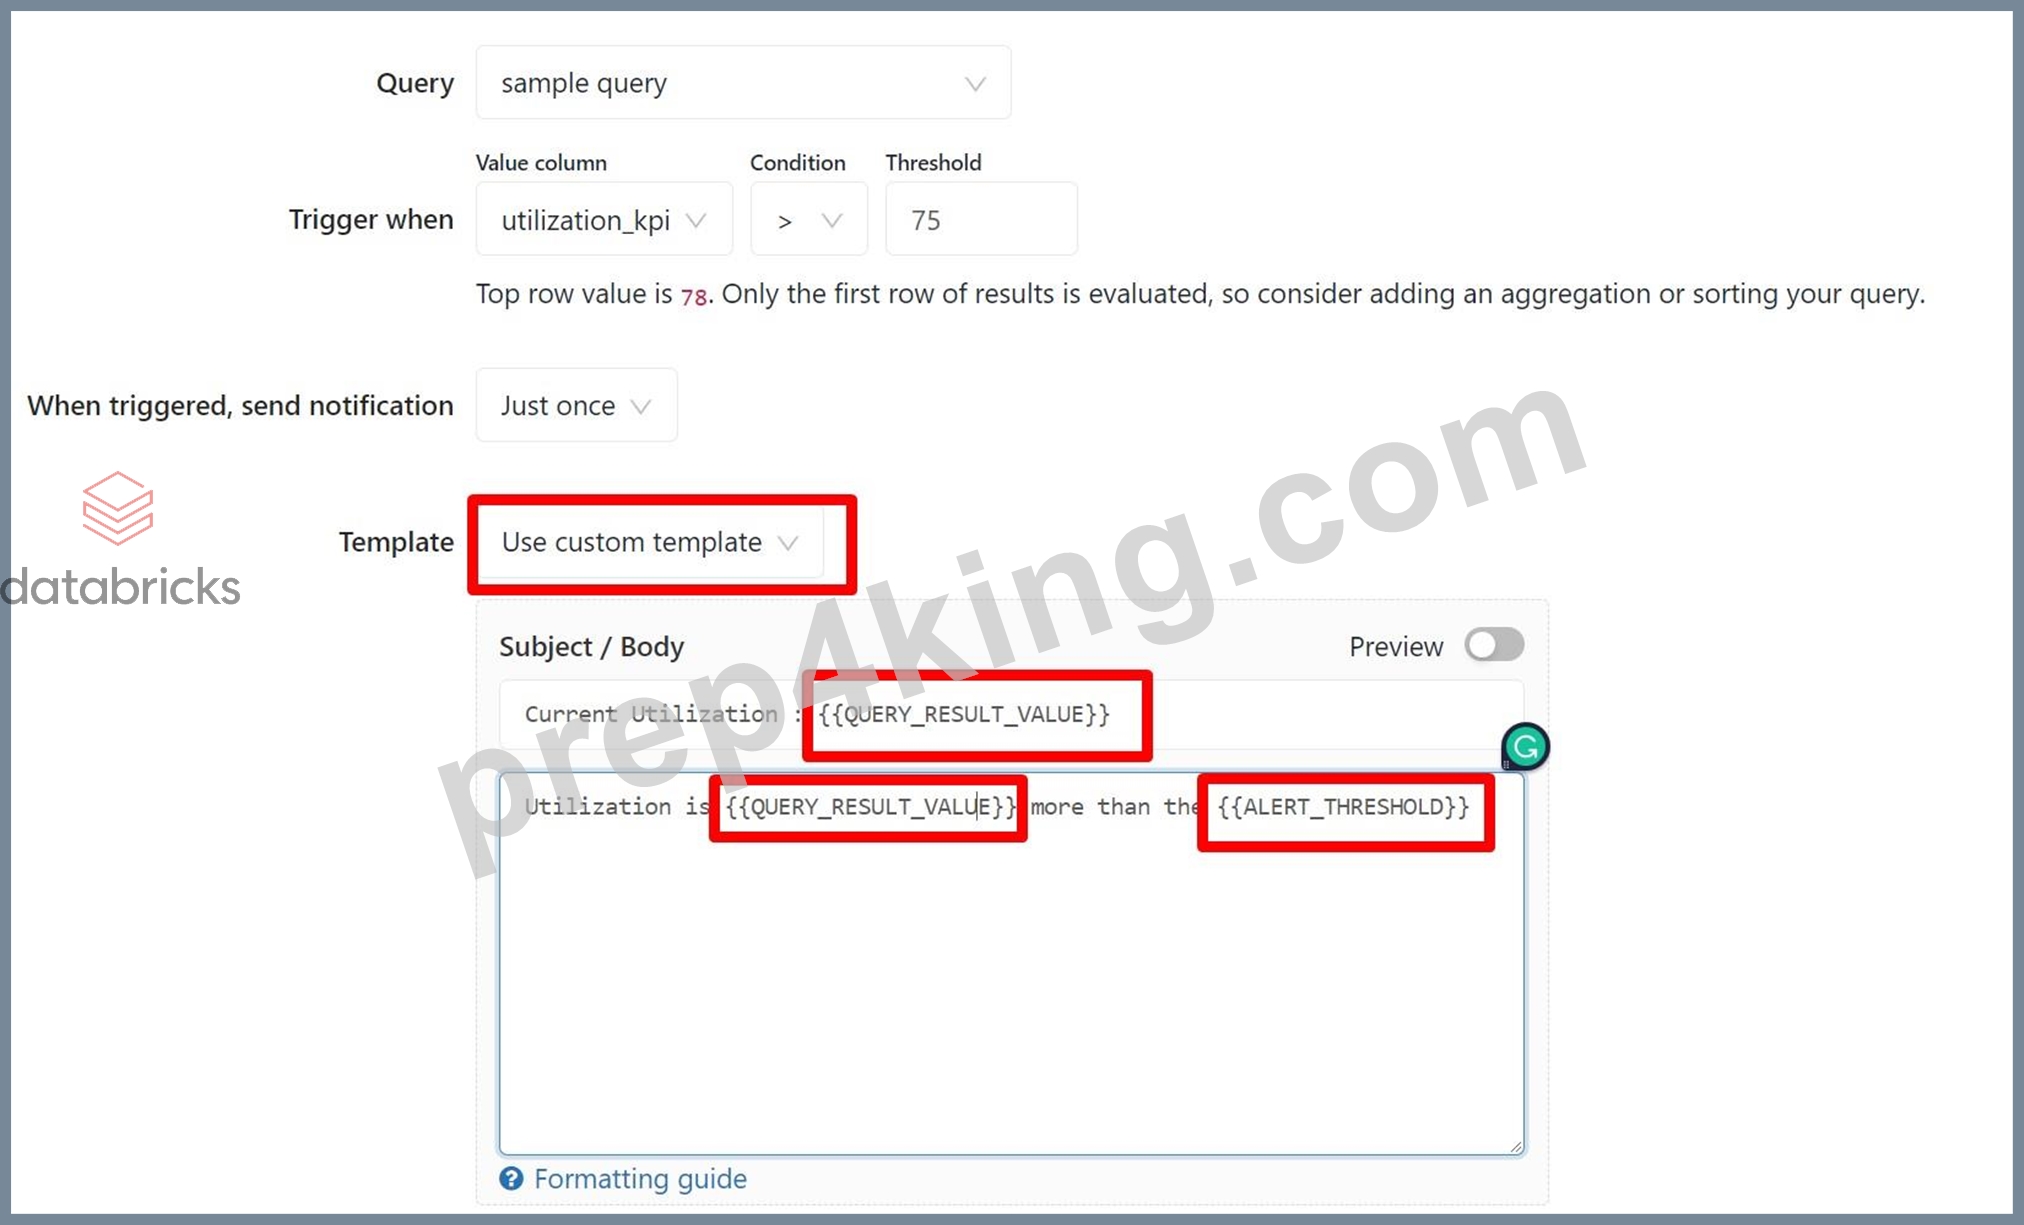
When you enable preview you can see how the alert looks when you substitute the variables.
Graphical user interface, text, application, email Description automatically generated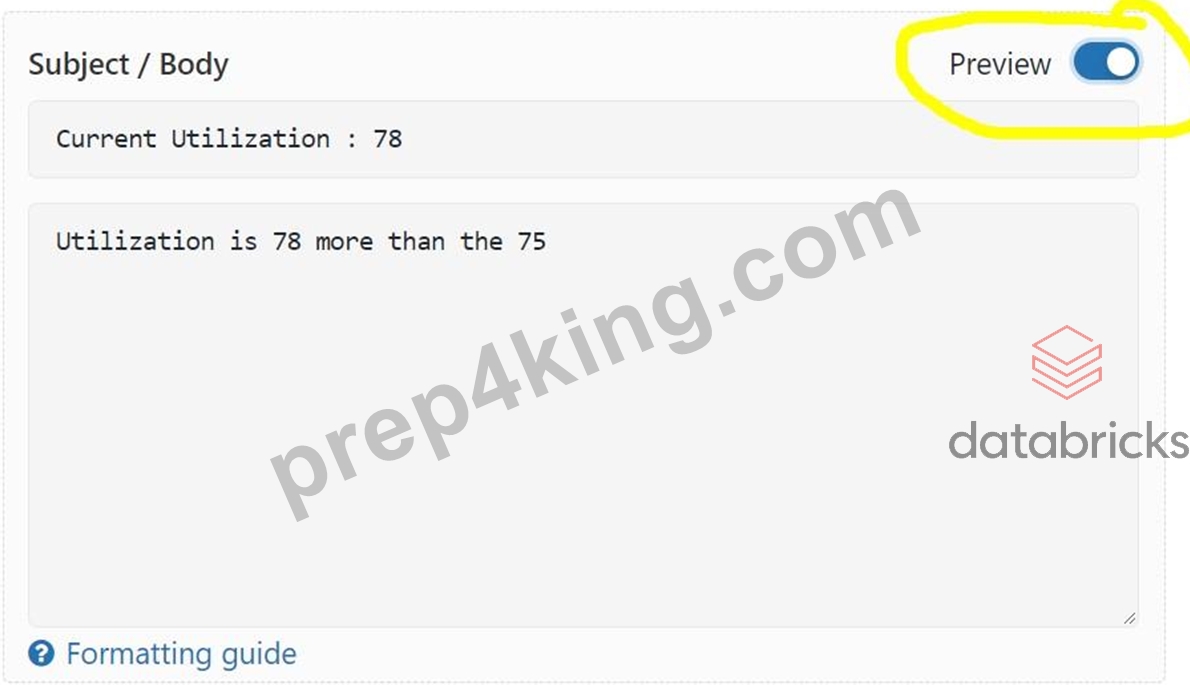
Below are additional template variables available to you with the custom template.
Alerts | Databricks on AWS
Graphical user interface, text, application, email Description automatically generated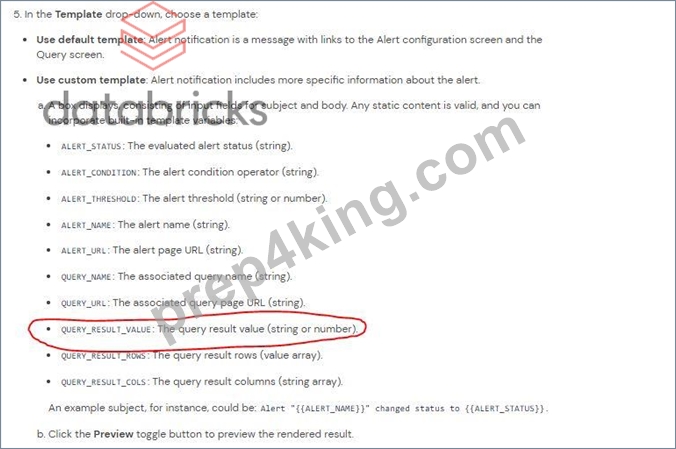
NEW QUESTION # 165
An hourly batch job is configured to ingest data files from a cloud object storage container where each batch represent all records produced by the source system in a given hour. The batch job to process these records into the Lakehouse is sufficiently delayed to ensure no late-arriving data is missed. The user_id field represents a unique key for the data, which has the following schema:
user_id BIGINT, username STRING, user_utc STRING, user_region STRING, last_login BIGINT, auto_pay BOOLEAN, last_updated BIGINT New records are all ingested into a table named account_history which maintains a full record of all data in the same schema as the source. The next table in the system is named account_current and is implemented as a Type 1 table representing the most recent value for each unique user_id.
Assuming there are millions of user accounts and tens of thousands of records processed hourly, which implementation can be used to efficiently update the described account_current table as part of each hourly batch job?
Answer: A
Explanation:
most recent value for each username.
Explanation:
This is the correct answer because it efficiently updates the account current table with only the most recent value for each user id. The code filters records in account history using the last updated field and the most recent hour processed, which means it will only process the latest batch of data. It also filters by the max last login by user id, which means it will only keep the most recent record for each user id within that batch. Then, it writes a merge statement to update or insert the most recent value for each user id into account current, which means it will perform an upsert operation based on the user id column. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Upsert into a table using merge" section.
NEW QUESTION # 166
A Structured Streaming job deployed to production has been resulting in higher than expected cloud storage costs. At present, during normal execution, each micro-batch of data is processed in less than 3 seconds; at least 12 times per minute, a micro-batch is processed that contains 0 records. The streaming write was configured using the default trigger settings. The production job is currently scheduled alongside many other Databricks jobs in a workspace with instance pools provisioned to reduce start-up time for jobs with batch execution. Holding all other variables constant and assuming records need to be processed in less than 10 minutes, which adjustment will meet the requirement?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "If no trigger is specified, the default processing-time trigger runs micro-batches as fast as possible." Exact extract: "Trigger once processes all available data once and then stops." Exact extract: "Job clusters are created for a job run and terminate when the job completes." The default "as fast as possible" trigger creates many empty micro-batches which repeatedly list/query cloud storage, inflating storage/metadata API costs. Switching to trigger(once=True) and scheduling the job to run every 10 minutes processes all available data in one batch, then stops. This both meets the <10-minute freshness requirement and minimizes compute (cluster can shut down between runs) and storage API calls (one batch per run instead of continual empty batches).
Reference:
NEW QUESTION # 167
......
Among all substantial practice materials with similar themes, our Databricks-Certified-Professional-Data-Engineer practice materials win a majority of credibility for promising customers who are willing to make progress in this line. With excellent quality at attractive price, our Databricks-Certified-Professional-Data-Engineer practice materials get high demand of orders in this fierce market with passing rate up to 98 to 100 percent all these years. We shall highly appreciate your acceptance of our Databricks-Certified-Professional-Data-Engineer practice materials and your decision will lead you to bright future with highly useful certificates. We have handled professional Databricks-Certified-Professional-Data-Engineer practice materials for over ten years. Our experts have many years’ experience in this particular line of business, together with meticulous and professional attitude towards jobs.
Databricks-Certified-Professional-Data-Engineer Pdf Braindumps: https://www.prep4king.com/Databricks-Certified-Professional-Data-Engineer-exam-prep-material.html
What's more, part of that Prep4King Databricks-Certified-Professional-Data-Engineer dumps now are free: https://drive.google.com/open?id=11qEFOFLRiFDWv659KBg_btolOzLObJSK