P.S. Free & New DP-100 dumps are available on Google Drive shared by Exam-Killer: https://drive.google.com/open?id=1jdlpFvoOVXmAsUq2CcwFrE20GXJMdQK6
Our product boosts three versions which include PDF version, PC version and APP online version. The Designing and Implementing a Data Science Solution on Azure test guide is highly efficient and the forms of the answers and questions are the same. Different version boosts their own feature and using method, and the client can choose the most convenient method. For example, PDF format of DP-100 guide torrent is printable and boosts instant access to download. You can learn at any time, and you can update the DP-100 Exam Questions freely in any day of one year. It provides free PDF demo. You can learn the APP online version of DP-100 guide torrent in your computer, cellphone, laptop or other set. Every version has their advantages so you can choose the most suitable method of Designing and Implementing a Data Science Solution on Azure test guide to prepare the exam. Believe us that we can bring you the service of high quality and make you satisfied.
Microsoft DP-100 Certification Exam is an excellent way for data science professionals to validate their expertise in designing and implementing data science solutions on Microsoft Azure. DP-100 exam is recognized globally and is highly regarded by employers in the field of data science. Designing and Implementing a Data Science Solution on Azure certification is a testament to the candidate's knowledge and expertise in the field of data science and can open up new career opportunities.
The best way to start the preparation process is to visit the official website of the certification exam. The official site is the most reliable source for the right information regarding the test. It is recommended that you download a detailed list of the exam objectives from the webpage and thoroughly study it before attempting the actual test.
>> Latest DP-100 Dumps Free <<
The secret of success is constancy to purpose. If your purpose is passing exams and getting a certification. DP-100 exam cram PDF will be the right shortcut for your exam. You shouldn't miss any possible chance or method to achieve your goal, especially our DP-100 Exam Cram Pdf always has 100% passing rate. Mostly choice is greater than effort. Well-pointed preparation for your test will help you save a lot of time. Microsoft DP-100 exam cram PDF will be great helper for your coming exam definitely.
Microsoft DP-100 Exam is a great way for data scientists to validate their skills and knowledge in Azure data science solutions. Passing DP-100 exam shows that the candidate has the necessary skills to design, implement, and deploy data science solutions on Azure. Moreover, this certification can be a valuable asset for individuals who want to advance their career in the data science field, as it demonstrates their proficiency in various areas related to data science.
NEW QUESTION # 243
You design a project for interactive data mangling with Apache Spark in an Azure Machine Learning workspace. The data pipeline must provide the following solution:
* Ingest and process a vast amount of data from various sources and linked services, such as databases and APIs
* Visualize the results in Microsoft Power Bl.
* Include a possibility to quickly identify and address issues by observing only a small amount of data using the fewest resources.
You need to select a computation option for project activities.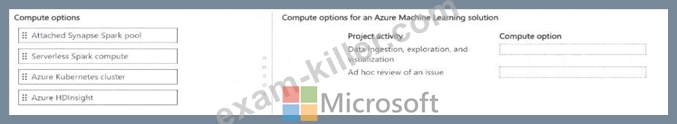
Answer:
Explanation: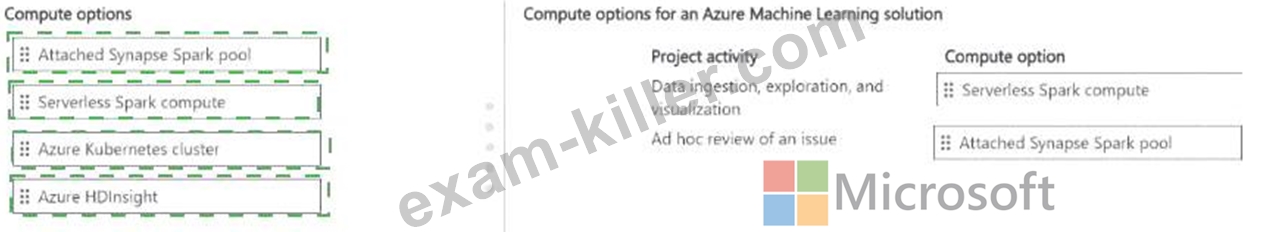
Explanation: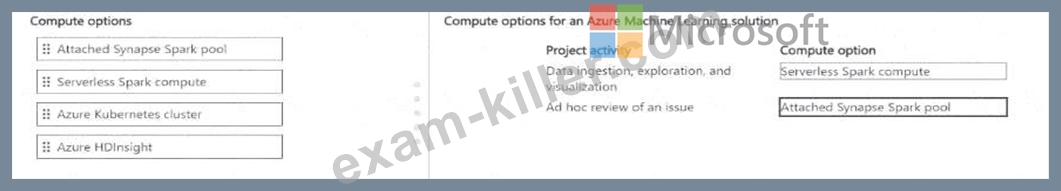
NEW QUESTION # 244
You create an Azure Machine Learning workspace and an Azure Synapse Analytics workspace with a Spark pool. The workspaces are contained within the same Azure subscription.
You must manage the Synapse Spark pool from the Azure Machine Learning workspace.
You need to attach the Synapse Spark pool in Azure Machine Learning by usinq the Python SDK v2.
Which three actions should you perform in sequence? To answer move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.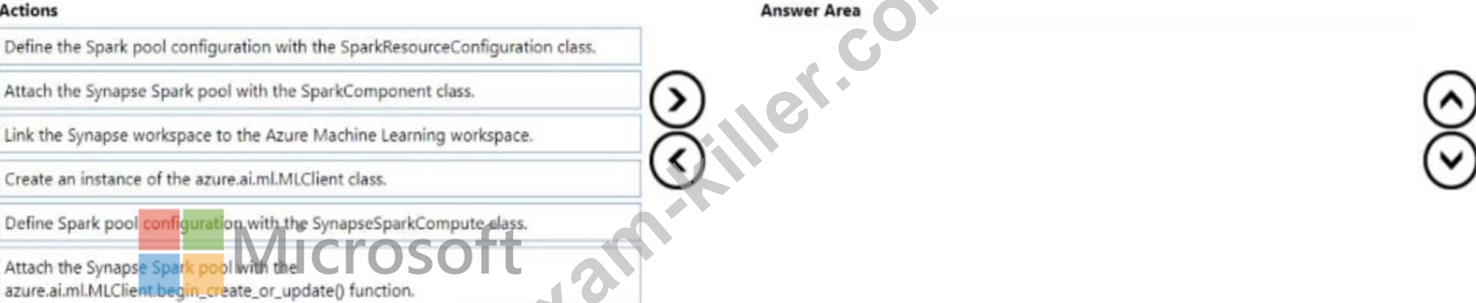
Answer:
Explanation: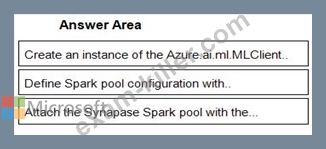
1 - Create an instance of the Azure.ai.ml.MLClient..
2 - Define Spark pool configuration with..
3 - Attach the Synapase Spark pool with the...
NEW QUESTION # 245
You create an Azure Machine Learning workspace. You train an MLflow-formatted regression model by using tabular structured data.
You must use a Responsible Al dashboard to assess the model.
You need to use the Azure Machine Learning studio Ul to generate the Responsible A dashboard.
What should you do first?
Answer: A
Explanation:
Topic 2, Case Study 1
Overview
You are a data scientist in a company that provides data science for professional sporting events. Models will be global and local market data to meet the following business goals:
*Understand sentiment of mobile device users at sporting events based on audio from crowd reactions.
*Access a user's tendency to respond to an advertisement.
*Customize styles of ads served on mobile devices.
*Use video to detect penalty events.
Current environment
Requirements
* Media used for penalty event detection will be provided by consumer devices. Media may include images and videos captured during the sporting event and snared using social media. The images and videos will have varying sizes and formats.
* The data available for model building comprises of seven years of sporting event media. The sporting event media includes: recorded videos, transcripts of radio commentary, and logs from related social media feeds feeds captured during the sporting events.
*Crowd sentiment will include audio recordings submitted by event attendees in both mono and stereo Formats.
Advertisements
* Ad response models must be trained at the beginning of each event and applied during the sporting event.
* Market segmentation nxxlels must optimize for similar ad resporr.r history.
* Sampling must guarantee mutual and collective exclusivity local and global segmentation models that share the same features.
* Local market segmentation models will be applied before determining a user's propensity to respond to an advertisement.
* Data scientists must be able to detect model degradation and decay.
* Ad response models must support non linear boundaries features.
* The ad propensity model uses a cut threshold is 0.45 and retrains occur if weighted Kappa deviates from 0.1
+/-5%.
* The ad propensity model uses cost factors shown in the following diagram: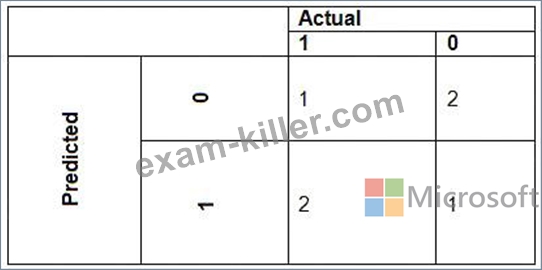
The ad propensity model uses proposed cost factors shown in the following diagram: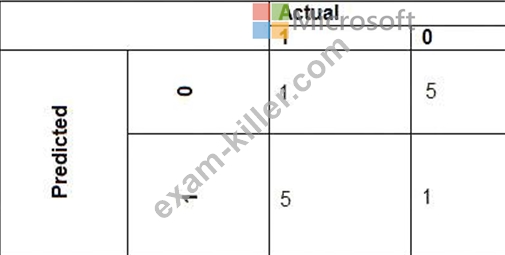
Performance curves of current and proposed cost factor scenarios are shown in the following diagram: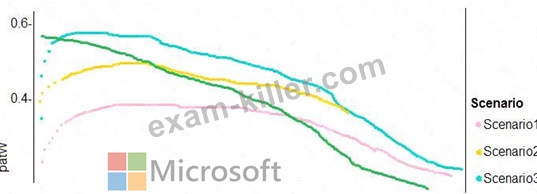
Penalty detection and sentiment
Findings
*Data scientists must build an intelligent solution by using multiple machine learning models for penalty event detection.
*Data scientists must build notebooks in a local environment using automatic feature engineering and model building in machine learning pipelines.
*Notebooks must be deployed to retrain by using Spark instances with dynamic worker allocation
*Notebooks must execute with the same code on new Spark instances to recode only the source of the data.
*Global penalty detection models must be trained by using dynamic runtime graph computation during training.
*Local penalty detection models must be written by using BrainScript.
* Experiments for local crowd sentiment models must combine local penalty detection data.
* Crowd sentiment models must identify known sounds such as cheers and known catch phrases. Individual crowd sentiment models will detect similar sounds.
* All shared features for local models are continuous variables.
* Shared features must use double precision. Subsequent layers must have aggregate running mean and standard deviation metrics Available.
segments
During the initial weeks in production, the following was observed:
*Ad response rates declined.
*Drops were not consistent across ad styles.
*The distribution of features across training and production data are not consistent.
Analysis shows that of the 100 numeric features on user location and behavior, the 47 features that come from location sources are being used as raw features. A suggested experiment to remedy the bias and variance issue is to engineer 10 linearly uncorrected features.
Penalty detection and sentiment
*Initial data discovery shows a wide range of densities of target states in training data used for crowd sentiment models.
*All penalty detection models show inference phases using a Stochastic Gradient Descent (SGD) are running too stow.
*Audio samples show that the length of a catch phrase varies between 25%-47%, depending on region.
*The performance of the global penalty detection models show lower variance but higher bias when comparing training and validation sets. Before implementing any feature changes, you must confirm the bias and variance using all training and validation cases.
NEW QUESTION # 246
You have a binary classifier that predicts positive cases of diabetes within two separate age groups.
The classifier exhibits a high degree of disparity between the age groups.
You need to modify the output of the classifier to maximize its degree of fairness across the age groups and meet the following requirements:
* Eliminate the need to retrain the model on which the classifier is based.
* Minimize the disparity between true positive rates and false positive rates across age groups.
Which algorithm and panty constraint should you use? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.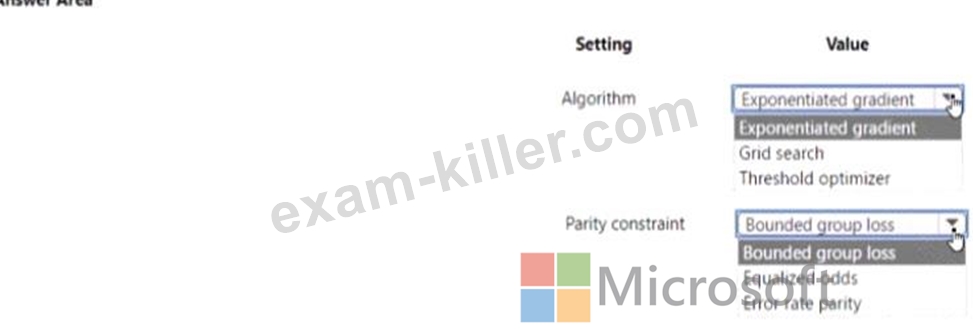
Answer:
Explanation: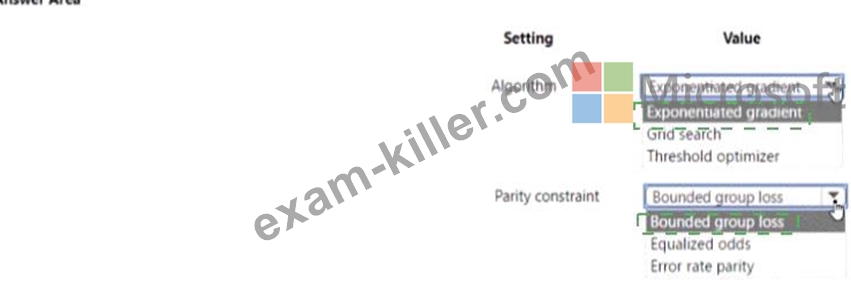
Explanation: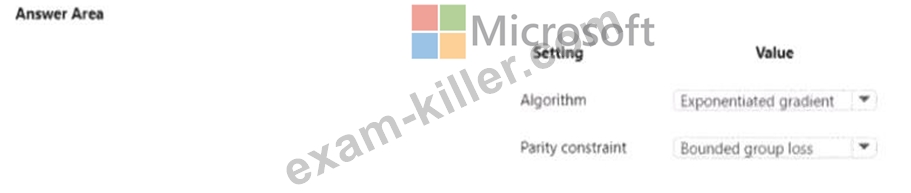
NEW QUESTION # 247
You manage an Azure Machine Learning workspace named workspace1 with a compute instance named compute1. You connect to compute! by using a terminal window from wofkspace1. You create a file named
"requirements.txt" containing Python dependencies to include Jupyler.
You need to add a new Jupyter kernel to compute1.
Which four commands should you use? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.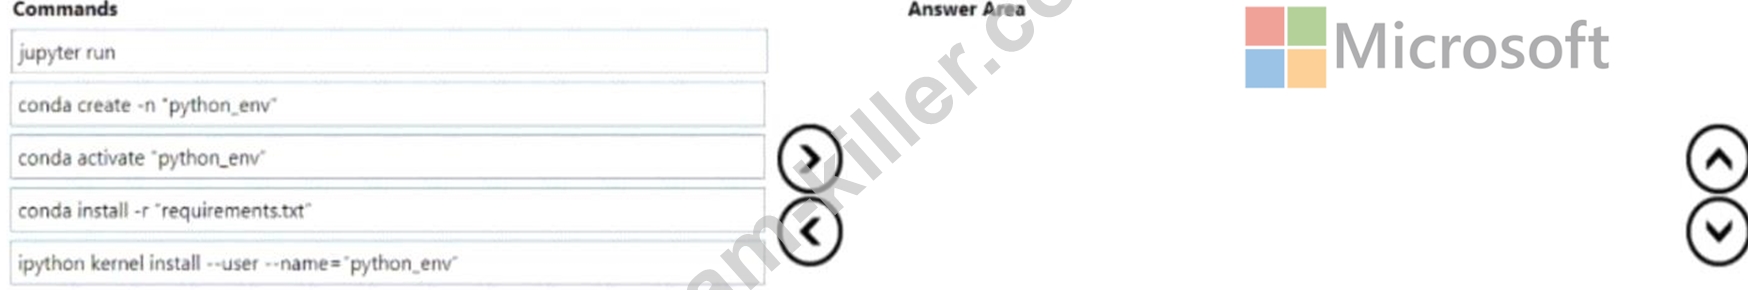
Answer:
Explanation: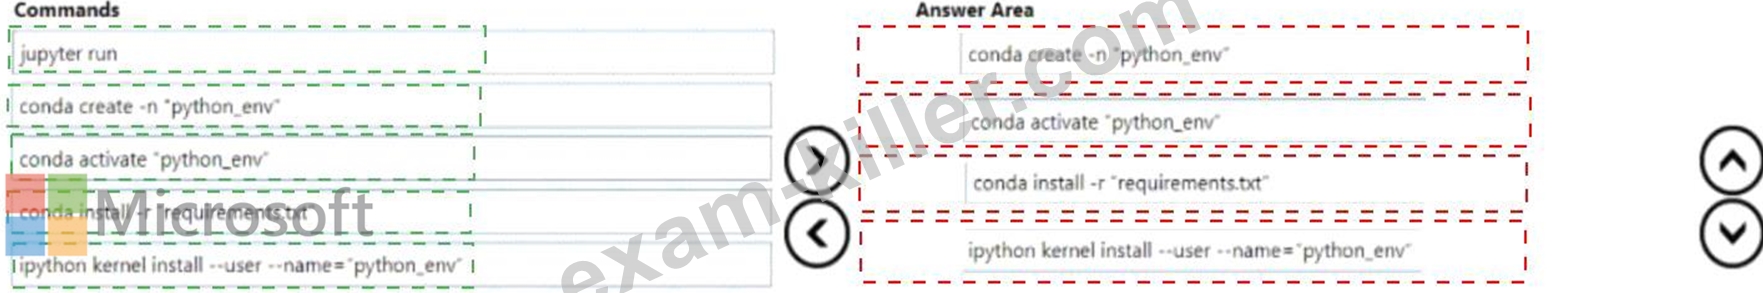
Explanation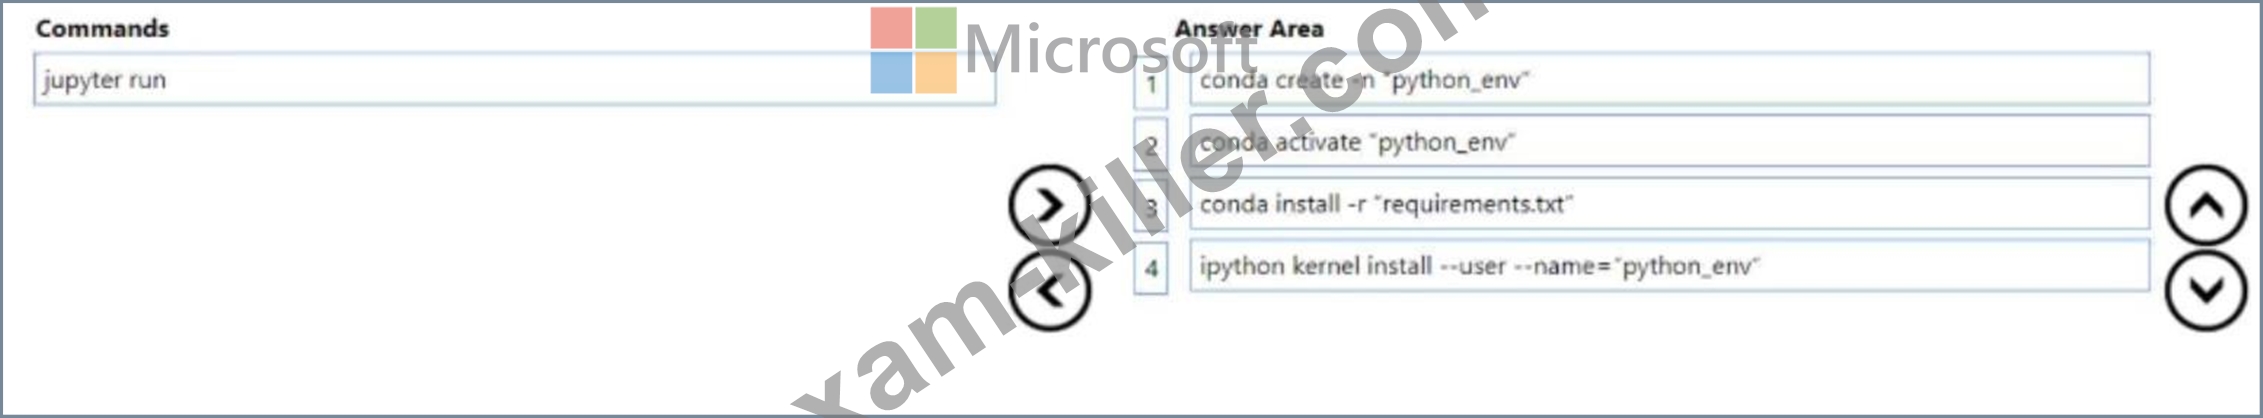
NEW QUESTION # 248
......
DP-100 Relevant Exam Dumps: https://www.exam-killer.com/DP-100-valid-questions.html
DOWNLOAD the newest Exam-Killer DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1jdlpFvoOVXmAsUq2CcwFrE20GXJMdQK6