2026 Latest VCEPrep NCM-MCI-6.10 PDF Dumps and NCM-MCI-6.10 Exam Engine Free Share: https://drive.google.com/open?id=1jk9yLNsygtTr8a6eGlUFS12sJCgSeBon
Candidates who participate in the Nutanix practice exam should first choose our latest braindumps pdf. It will help you pass test with 100% guaranteed. Besides, our NCM-MCI-6.10 exam prep can help you fit the atmosphere of actual test in advance, which enable you to improve your ability with minimum time spent on NCM-MCI-6.10 Dumps PDF and maximum knowledge gained.
| Section | Objectives |
|---|---|
| Topic 1: Deploy and Upgrade Nutanix Environments | - Cluster installation and configuration - Foundation processes - Software and firmware upgrades |
| Topic 2: Troubleshoot and Resolve Complex Issues | - Log analysis and diagnostics - Failure recovery procedures - Cluster health management |
| Topic 3: Configure and Manage Nutanix Networking | - Advanced networking scenarios - AHV networking configuration - Network segmentation and microsegmentation |
| Topic 4: Manage and Configure Nutanix Virtual Infrastructure | - AHV cluster configuration - Resource scheduling and optimization - VM management and operations |
| Topic 5: Implement and Manage Security and Compliance | - Access control and authentication - Compliance frameworks - Security hardening |
| Topic 6: Manage and Optimize Nutanix Storage | - Storage container and VDisk management - Storage optimization and efficiency - Data protection and disaster recovery |
| Topic 7: Analyze and Remediate Performance Issues | - Performance monitoring and metrics - Troubleshooting network performance - Troubleshooting storage performance |
>> NCM-MCI-6.10 Exam Topics Pdf <<
VCEPrep's experts have simplified the complex concepts and have added examples, simulations and graphs to explain whatever could be difficult for you to understand. Therefore even the average exam candidates can grasp all study questions without any difficulty. Additionally, the NCM-MCI-6.10 Exam takers can benefit themselves by using our testing engine and get numerous real exam like practice questions and answers. They will help them revising the entire syllabus within no time.
NEW QUESTION # 17
An administrator needs to configure a new write-intensive MS-SQL VM on Cluster 1.
VM specifications:
* vCPU: 12
* vRAM: 128GB
* Storage: 100 GB OS, 750 GB Data
Create the VM and any objects needed in the current environment to meet requirements, maximizing performance for the production environment. Include NEWSQL in the name of any new objects.
Production environment:
* 4 nodes
* Each node has two 8-core CPUs
* Each node has 1024 GB RAM
* Storage: 4 × 7.16 TB SSD Disks and 8 × 8 TB HDD disks
Make sure the VM is configured for maximum performance for the production environment.
Note: Network configuration is not required at this time. Do not power on the VM.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to create the high-performance SQL VM on Cluster 1.
This task requires two phases: first, creating a new all-flash storage container, and second, creating the VM with a specific vNUMA and disk controller configuration for maximum performance.
1. Access Cluster 1 Prism Element
* From the main Prism Central dashboard, navigate to Hardware > Clusters.
* Find Cluster 1 in the list and click its name. This will open the specific Prism Element login page for that cluster.
* Log in to Cluster 1's Prism Element interface.
2. Create the All-Flash Storage Container
To maximize performance for a "write-intensive" workload on a hybrid cluster, the data and log disks must be placed on an all-flash container.
* In the Cluster 1 PE interface, click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Storage.
* Click the + Storage Container button.
* Fill in the basic details:
* Name: NEWSQL_Flash_Container
* Click Advanced Settings.
* Scroll down to the Storage Tier section.
* Select the SSD radio button. This pins all data in this container to the SSD tier, ensuring all-flash performance.
* Click Save.
3. Create and Configure the VM
Now, create the VM, applying vNUMA and multi-SCSI controller best practices.
* From the main PE dashboard, navigate to the VM view.
* Click the + Create VM button.
* Enter the compute details. This configuration is critical for vNUMA performance, as it tells the VM's guest OS about the underlying physical NUMA topology (2 CPUs with 8 cores each).
* Name: NEWSQL_VM
* vCPUs: 12
* Number of Sockets: 2
* Cores per vCPU: 6 (This creates a 2-socket, 6-core VM, totaling 12 vCPUs)
* Memory: 128 GB
* Scroll down to the Disks section and add the OS disk:
* Click + Add New Disk.
* Storage Container: Select the default (hybrid) container.
* Size: 100 GB
* Bus: SCSI
* Device Index: 0 (This will be scsi.0)
* Click Add.
* Add the Data disk (on its own controller for parallel processing):
* Click + Add New Disk.
* Storage Container: Select NEWSQL_Flash_Container.
* Size: 750 GB
* Bus: SCSI
* Device Index: 1 (This creates a new controller, scsi.1)
* Click Add.
* Add a Log disk (on its own controller, a best practice for "write-intensive" SQL):
* Click + Add New Disk.
* Storage Container: Select NEWSQL_Flash_Container.
* Size: 100 GB (A common size for a log disk)
* Bus: SCSI
* Device Index: 2 (This creates a third controller, scsi.2)
* Click Add.
* Review the configuration: You should now have three disks attached, each on a separate controller (scsi.
0, scsi.1, scsi.2). This provides the maximum I/O performance.
* Ensure the Power on VM after creation box is unchecked.
* Click Save.
Topic 1, Performance Based Questions Set 1
Environment
You have been provisioned a dedicated environment for your assessment which includes the following:
Initial Steps
* When you first log into Prism Central or Prism Element you may see the EULA screen. Accept the EULA with any name and then disable Pulse.
* To access Prism Element, the pass-through from Prism Central
(Infrastructure\Hardware\Clusters\cluster-x\Launch Prism Element) works better than directly using the external IP:9440.
Workstation
* Windows Server 2019
* All software/tools/etc to perform the required tasks
* Nutanix Documentation and whitepapers can be found in Desktop\Files\Documentation and Desktop\Files\Documentation 6.10
* Note that the Workstation is the system you are currently logged into
* Windows Server 2019
* All software/tools/etc to perform the required tasks
* Nutanix Documentation and whitepapers can be found in Desktop\Files\Documentation and Desktop\Files\Documentation 6.10
* Note that the Workstation is the system you are currently logged into Nutanix Cluster
* There are two clusters provided, connected to one Prism Central. The connection information for the relevant cluster will be displayed to the right of the question. Please make sure you are working on the correct cluster for each item. Please ignore any licensing violations.
Important Notes
* If the text is too small and hard to read, or you cannot see all of the GUI, you can increase/decrease the zoom of the browser with CTRL + and CTRL - (the plus and minus keys).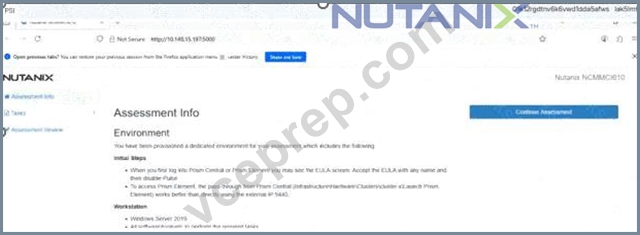
Prism Central Web Console
* admin / ykZUCJMER7V*
* nutanix / UJ2xE!DEXGY
Cluster 1
* CVM external IP: 34.53.118.63
* CVM DR IP: 172.30.0.6
* admin / 9Fw0B!3QH4X)
* nutanix / GNP*FE2504XWZ
* root / KR*6HY0z5E8
Cluster 2
* CVM external IP: 34.82.155.5
* CVM DR IP: 172.30.0.4
* admin / 5*K30fA76X
* nutanix / N*3F%1ME!Z7T9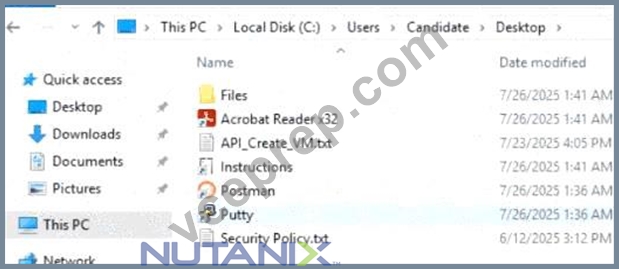
NEW QUESTION # 18
The Database team is reporting performance degradation for a business-critical application on Saturdays.
The team is requesting monitoring of processor, memory and storage utilization for the cluster for the application: SQL01, SQL02.
The report should contain views for the following:
* At the cluster level, only for the Cluster 1: The maximum percentage of CPU used
* At the VM level, including any future VM with the prefix SQL: The maximum time taken, maximum percentage of time a VM waits to use the physical CPU, out of the total CPU The report should run on Sundays at 12:00 AM for the previous 7 days. The report should show when completed.
Create a report named SQL_Batch_Saturday that meets these requirements.
Generate an instance of the report named SQL_Batch_Saturday as a CSV and save the file.
Note: You must name the report SQL_Batch_Saturday to receive any credit. Any other name will not be accepted. SMTP is not configured.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to create and run the report, performed entirely within Prism Central.
1. Create the Analysis Session
First, we will build the charts and entities for the report using the Analysis tool.
* From the Prism Central main menu, navigate to Operations > Analysis.
* Click the + New Session button.
* Add the required entities:
* In the "Entities" search box, type Cluster 1 and select Cluster: Cluster 1.
* In the "Entities" search box, type SQL01 and select VM: SQL01.
* In the "Entities" search box, type SQL02 and select VM: SQL02.
* Click Add Charts > New Chart to add the Cluster CPU chart:
* Title: Cluster 1 Max CPU Usage
* Entity Type: Cluster
* Metric: Cluster CPU Usage %
* Aggregation: Select Maximum.
* Click Add.
* Click Add Charts > New Chart to add the VM CPU Ready Time chart:
* Title: VM Max CPU Ready Time
* Entity Type: VM
* Metric: CPU Ready Time %
* Aggregation: Select Maximum.
* Click Add.
2. Save and Configure the Report
Now, save the session as a report and configure it to dynamically include all VMs with the SQL prefix.
* Click the Save as Report icon (the bookmark icon in the upper right).
* Name the report SQL_Batch_Saturday and click Save.
* Navigate to Operations > Reports.
* Find the SQL_Batch_Saturday report you just created and click its name to open the report editor.
* In the Entities tile, click the Edit (pencil) icon.
* By default, it will list "Cluster 1", "SQL01", and "SQL02".
* Change the VM selection:
* Select the radio button for All VMs prefixed with.
* In the text box, enter SQL.
* Ensure "Cluster 1" is still listed under "Clusters".
* Click Save.
3. Schedule the Report
* While still in the report editor for SQL_Batch_Saturday, click the Schedule button.
* Configure the schedule:
* Recurrence: Weekly
* Repeat on: Sunday
* Start Time: 12:00 AM
* Time Range: Previous 7 Days
* Configure the notification (as SMTP is not available):
* Expand the Notification Settings section.
* Check the box for Notify when ready (this enables the bell icon notification).
* Ensure "Email Report" is not checked.
* Click Save.
4. Generate and Save the CSV Instance
Finally, run the report now and download the CSV as requested.
* Navigate back to the main Operations > Reports list.
* Select the checkbox next to SQL_Batch_Saturday.
* Click the Actions dropdown and select Run Now.
* In the dialog, confirm the time range (e.g., "Last 7 Days") and click Run.
* Click the Report Instances tab.
* Wait for the report instance "SQL_Batch_Saturday" to finish running (the status will change from
"Running" to Succeeded).
* Once it has succeeded, click the Download (arrow) icon for that instance.
* Select the CSV format.
* Save the file to the desktop.
NEW QUESTION # 19
Task 13
An administrator found a CentOS VM, Cent_Down, on the cluster with a corrupted network stack. To correct the issue, the VM will need to be restored from a previous snapshot to become reachable on the network again.
VM credentials:
Username: root
Password: nutanix/4u
Restore the VM and ensure it is reachable on the network by pinging 172.31.0.1 from the VM.
Power off the VM before proceeding.
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To restore the VM and ensure it is reachable on the network, you can follow these steps:
Log in to the Web Console of the cluster where the VM is running.
Click on Virtual Machines on the left menu and find Cent_Down from the list. Click on the power icon to power off the VM.
Click on the snapshot icon next to the power icon to open the Snapshot Management window.
Select a snapshot from the list that was taken before the network stack was corrupted. You can use the date and time information to choose a suitable snapshot.
Click on Restore VM and confirm the action in the dialog box. Wait for the restore process to complete.
Click on the power icon again to power on the VM.
Log in to the VM using SSH or console with the username and password provided.
Run the command ping 172.31.0.1 to verify that the VM is reachable on the network. You should see a reply from the destination IP address.
Go to VMS from the prism central gui
Select the VMand go to More -> Guest Shutdown
Go to Snapshots tab and revert to latest snapshot available
power on vm and verify if ping is working
NEW QUESTION # 20
An administrator is experiencing an unidentified issue which is causing inode exhaustion on CVMs in Cluster
1. The time between receiving alerts and exhaustion is too short; the administrator needs to lower the alert thresholds to allow more time to clean up inodes until the issue has been identified and resolution implemented.
From Prism Element, modify the appropriate alert policy setting critical threshold for Cluster 1 to 60% and warning threshold to 45%. Ensure the check runs every minute and is not resolved without administrator action.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to modify the alert policy from the Prism Element (PE) interface for Cluster 1.
1. Access Cluster 1 Prism Element
* From the main Prism Central dashboard, navigate to Hardware > Clusters.
* Find Cluster 1 in the list and click its name. This will open the specific Prism Element login page for that cluster.
* Log in to Cluster 1's Prism Element interface.
2. Modify the Alert Policy
* In the Cluster 1 PE interface, click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Alert Policies.
* In the search bar, type inode to find the correct policy.
* Select the checkbox for the policy named cvm_inode_usage_high.
* Click the Update button.
* In the "Update Alert Policy" dialog, configure the following settings:
* Warning Threshold (%): Change the value to 45.
* Critical Threshold (%): Change the value to 60.
* Check Interval (Secs): Change the value to 60 (to run the check every minute).
* Auto Resolve: Uncheck this box (to ensure the alert is not resolved without administrator action).
* Click Save.
NEW QUESTION # 21
Task 2
Part1
An administrator logs into Prism Element and sees an alert stating the following:
Cluster services down on Controller VM (35.197.75.196)
Correct this issue in the least disruptive manner.
Part2
In a separate request, the security team has noticed a newly created cluster is reporting.
CVM [35.197.75.196] is using the default password.
They have provided some new security requirements for cluster level security.
Security requirements:
Update the default password for the root user on the node to match the admin user password: Note: 192.168.x.
x is not available. To access a node use the Host IP (172.30.0.x) from a CVM or the supplied external IP address.
Update the default password for the nutanix user on the CVM to match the admin user password.
Resolve the alert that is being reported.
Output the cluster-wide configuration of the SCMA policy to Desktop\Files\output.txt before changes are made.
Enable the Advance intrusion Detection Environment (AIDE) to run on a weekly basis for the cluster.
Enable high-strength password policies for the cluster.
Ensure CVMs require SSH keys for login instead of passwords. (SSH keys are located in the Desktop\Files\SSH folder).
Ensure the clusters meets these requirements. Do not reboot any cluster components.
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To correct the issue of cluster services down on Controller VM (35.197.75.196) in the least disruptive manner, you need to do the following steps:
Log in to Prism Element using the admin user credentials.
Go to the Alerts page and click on the alert to see more details.
You will see which cluster services are down on the Controller VM. For example, it could be cassandra, curator, stargate, etc.
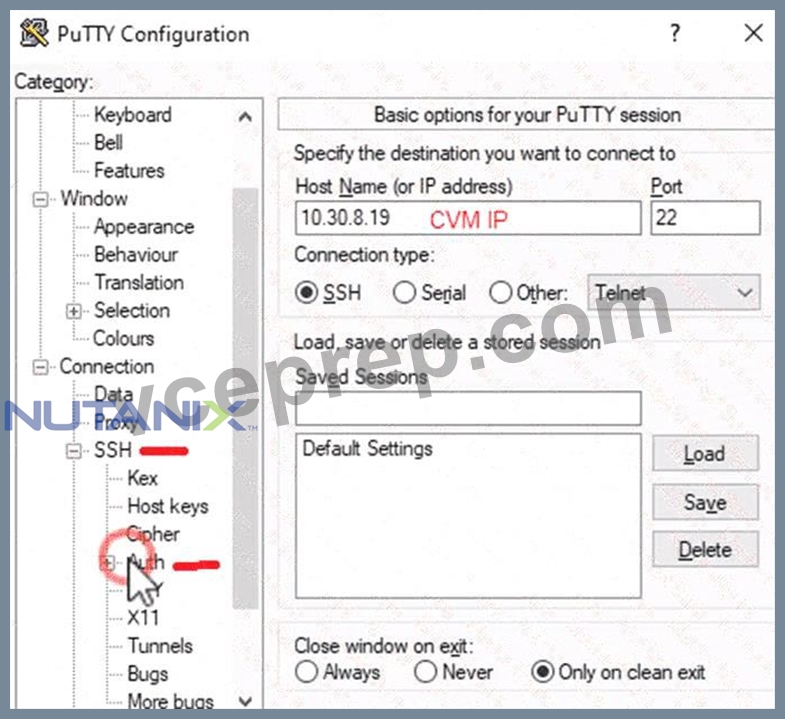
To start the cluster services, you need to SSH to the Controller VM using the nutanix user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the Controller VM. You will need the IP address and the password of the nutanix user, which you can find in Desktop\Files\SSH\nutanix.
txt.
Once you are logged in to the Controller VM, run the command:
cluster status | grep -v UP
This will show you which services are down on the Controller VM.
To start the cluster services, run the command:
cluster start
This will start all the cluster services on the Controller VM.
To verify that the cluster services are running, run the command:
cluster status | grep -v UP
This should show no output, indicating that all services are up.
To clear the alert, go back to Prism Element and click on Resolve in the Alerts page.
To meet the security requirements for cluster level security, you need to do the following steps:
To update the default password for the root user on the node to match the admin user password, you need to SSH to the node using the root user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the node. You will need the IP address and the password of the root user, which you can find in Desktop\Files\SSH\root.txt.
Once you are logged in to the node, run the command:
passwd
This will prompt you to enter a new password for the root user. Enter the same password as the admin user, which you can find in Desktop\Files\SSH\admin.txt.
To update the default password for the nutanix user on the CVM to match the admin user password, you need to SSH to the CVM using the nutanix user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the CVM. You will need the IP address and the password of the nutanix user, which you can find in Desktop\Files\SSH\nutanix.txt.
Once you are logged in to the CVM, run the command:
passwd
This will prompt you to enter a new password for the nutanix user. Enter the same password as the admin user, which you can find in Desktop\Files\SSH\admin.txt.
To resolve the alert that is being reported, go back to Prism Element and click on Resolve in the Alerts page.
To output the cluster-wide configuration of SCMA policy to Desktop\Files\output.txt before changes are made, you need to log in to Prism Element using the admin user credentials.
Go to Security > SCMA Policy and click on View Policy Details. This will show you the current settings of SCMA policy for each entity type.
Copy and paste these settings into a new text file named Desktop\Files\output.txt.
To enable AIDE (Advanced Intrusion Detection Environment) to run on a weekly basis for the cluster, you need to log in to Prism Element using the admin user credentials.
Go to Security > AIDE Configuration and click on Enable AIDE. This will enable AIDE to monitor file system changes on all CVMs and nodes in the cluster.
Select Weekly as the frequency of AIDE scans and click Save.
To enable high-strength password policies for the cluster, you need to log in to Prism Element using the admin user credentials.
Go to Security > Password Policy and click on Edit Policy. This will allow you to modify the password policy settings for each entity type.
For each entity type (Admin User, Console User, CVM User, and Host User), select High Strength as the password policy level and click Save.
To ensure CVMs require SSH keys for login instead of passwords, you need to log in to Prism Element using the admin user credentials.
Go to Security > Cluster Lockdown and click on Configure Lockdown. This will allow you to manage SSH access settings for the cluster.
Uncheck Enable Remote Login with Password. This will disable password-based SSH access to the cluster.
Click New Public Key and enter a name for the key and paste the public key value from Desktop\Files\SSH\id_rsa.pub. This will add a public key for key-based SSH access to the cluster.
Click Save and Apply Lockdown. This will apply the changes and ensure CVMs require SSH keys for login instead of passwords.
Part1
Enter CVM ssh and execute:
cluster status | grep -v UP
cluster start
If there are issues starting some services, check the following:
Check if the node is in maintenance mode by running the ncli host ls command on the CVM. Verify if the parameter Under Maintenance Mode is set to False for the node where the services are down. If the parameter Under Maintenance Mode is set to True, remove the node from maintenance mode by running the following command:
nutanix@cvm$ ncli host edit id=<host id> enable-maintenance-mode=false
You can determine the host ID by using ncli host ls.
See the troubleshooting topics related to failed cluster services in the Advanced Administration Guide available from the Nutanix Portal's Software Documentation page. (Use the filters to search for the guide for your AOS version). These topics have information about common and AOS-specific logs, such as Stargate, Cassandra, and other modules.
Check for any latest FATALs for the service that is down. The following command prints all the FATALs for a CVM. Run this command on all CVMs.
nutanix@cvm$ for i in `svmips`; do echo "CVM: $i"; ssh $i "ls -ltr /home/nutanix/data/logs/*.FATAL"; done NCC Health Check: cluster_services_down_check (nutanix.com) Part2 Vlad Drac2023-06-05T13:22:00.86I'll update this one with a smaller, if possible, command Update the default password for the root user on the node to match the admin user password echo -e "CHANGING ALL AHV HOST ROOT PASSWORDS.\nPlease input new password: "; read -rs password1; echo "Confirm new password: "; read -rs password2; if [ "$password1" == "$password2" ]; then for host in $(hostips); do echo Host $host; echo $password1 | ssh root@$host "passwd --stdin root"; done; else echo "The passwords do not match"; fi Update the default password for the nutanix user on the CVM sudo passwd nutanix Output the cluster-wide configuration of the SCMA policy ncli cluster get-hypervisor-security-config Output Example:
nutanix@NTNX-372a19a3-A-CVM:10.35.150.184:~$ ncli cluster get-hypervisor-security-config Enable Aide : false Enable Core : false Enable High Strength P... : false Enable Banner : false Schedule : DAILY Enable iTLB Multihit M... : false Enable the Advance intrusion Detection Environment (AIDE) to run on a weekly basis for the cluster.
ncli cluster edit-hypervisor-security-params enable-aide=true
ncli cluster edit-hypervisor-security-params schedule=weekly
Enable high-strength password policies for the cluster.
ncli cluster edit-hypervisor-security-params enable-high-strength-password=true Ensure CVMs require SSH keys for login instead of passwords
https://portal.nutanix.com/page/documents/kbs/details?targetId=kA0600000008gb3CAA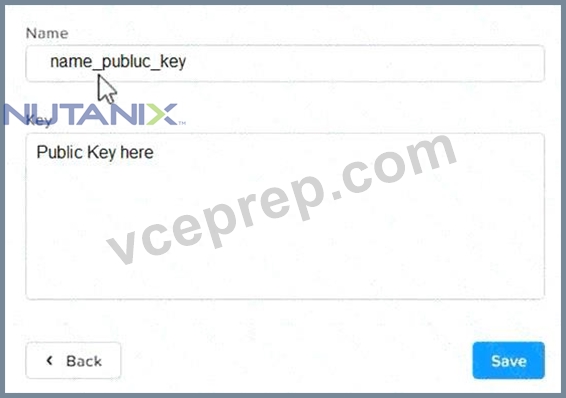
NEW QUESTION # 22
......
NCM-MCI-6.10 training dumps are created in the most unique, customized way so it can cover different areas of exam with the Quality and Price of the product which is unmatched by our Competitors. The 100% guarantee pass pass rate of NCM-MCI-6.10 training materials that guarantee you to pass your Exam and will not permit any type of failure. You will find every question and answer within NCM-MCI-6.10 Training Materials that will ensure you get any high-quality certification you’re aiming for.
NCM-MCI-6.10 Latest Braindumps Pdf: https://www.vceprep.com/NCM-MCI-6.10-latest-vce-prep.html
DOWNLOAD the newest VCEPrep NCM-MCI-6.10 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1jk9yLNsygtTr8a6eGlUFS12sJCgSeBon