Certified-Data-Engineer-Professional Latest Exam Labs - Valid Certified-Data-Engineer-Professional Test Notes

Our Software version has the advantage of simulating the real Certified-Data-Engineer-Professional exam environment. Many candidates can't successfully pass their real Certified-Data-Engineer-Professional exams for the reason that they are too nervous to performance rightly as they do the practices. This Software version of Certified-Data-Engineer-Professional practice materials will exactly help overcome their psychological fear. Besides, the scores will show out when you finish the practice, so after a few times, you will definitely do it better and better. You will be bound to pass your Certified-Data-Engineer-Professional Exam since you have perfected yourself in taking the Certified-Data-Engineer-Professional exam.
| Section | Objectives |
|---|
| Data Modeling | - Design and optimize data models
- 1. Design and implement scalable data models using Delta Lake to manage large datasets
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
|
| Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 3. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 4. Use Query Profile and Spark UI to monitor workloads
|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 2. Apply Change Data Feed to address streaming table limitations and improve latency
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 5. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
|
| Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use row filters and column masks to protect sensitive table data
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
- Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 2. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 3. Create pipeline components using control flow operators such as if/else and foreach
- 4. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 5. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 6. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 7. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 8. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
>> Certified-Data-Engineer-Professional Latest Exam Labs <<
Trusted Certified-Data-Engineer-Professional Latest Exam Labs & Useful Databricks Certification Training - Trustworthy Databricks Databricks Certified Data Engineer Professional
After paying our Certified-Data-Engineer-Professional exam torrent successfully, buyers will receive the mails sent by our system in 5-10 minutes. Then candidates can open the links to log in and use our Certified-Data-Engineer-Professional test torrent to learn immediately. Because the time is of paramount importance to the examinee, everyone hope they can learn efficiently. So candidates can use our Certified-Data-Engineer-Professional Guide questions immediately after their purchase is the great advantage of our product. It is convenient for candidates to master our Certified-Data-Engineer-Professional test torrent and better prepare for the exam. We will provide the best service for you after purchasing our exam materials.
Databricks Certified Data Engineer Professional Sample Questions (Q126-Q131):
NEW QUESTION # 126
The data engineering team maintains the following code:
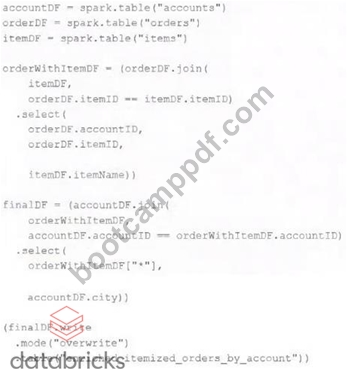
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
- B. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
- C. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- D. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
- E. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
Answer: C
Explanation:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables.
NEW QUESTION # 127
What is a method of installing a Python package scoped at the notebook level to all nodes in the currently active cluster?
- A. Install libraries from PyPi using the cluster UI
- B. Run source env/bin/activate in a notebook setup script
- C. Use &Pip install in a notebook cell
- D. Use &sh install in a notebook cell
Answer: A
Explanation:
Installing a Python package scoped at the notebook level to all nodes in the currently active cluster in Databricks can be achieved by using the Libraries tab in the cluster UI. This interface allows you to install libraries across all nodes in the cluster. While the %pip command in a notebook cell would only affect the driver node, using the cluster UI ensures that the package is installed on all nodes.
NEW QUESTION # 128
The Databricks CLI is use to trigger a run of an existing job by passing the job_id parameter. The response that the job run request has been submitted successfully includes a filed run_id.
Which statement describes what the number alongside this field represents?
- A. The total number of jobs that have been run in the workspace.
- B. The number of times the job definition has been run in the workspace.
- C. The job_id is returned in this field.
- D. The job_id and number of times the job has been are concatenated and returned.
- E. The globally unique ID of the newly triggered run.
Answer: E
Explanation:
When triggering a job run using the Databricks CLI, the run_id field in the response represents a globally unique identifier for that particular run of the job. This run_id is distinct from the job_id.
While the job_id identifies the job definition and is constant across all runs of that job, the run_id is unique to each execution and is used to track and query the status of that specific job run within the Databricks environment. This distinction allows users to manage and reference individual executions of a job directly.
NEW QUESTION # 129
The data architect has mandated that all tables in the Lakehouse should be configured as external (also known as "unmanaged") Delta Lake tables.
Which approach will ensure that this requirement is met?
- A. When data is saved to a table, make sure that a full file path is specified alongside the Delta format.
- B. When configuring an external data warehouse for all table storage, leverage Databricks for all ELT.
- C. When a database is being created, make sure that the LOCATION keyword is used.
- D. When tables are created, make sure that the EXTERNAL keyword is used in the CREATE TABLE statement.
- E. When the workspace is being configured, make sure that external cloud object storage has been mounted.
Answer: D
Explanation:
To create an external or unmanaged Delta Lake table, you need to use the EXTERNAL keyword in the CREATE TABLE statement. This indicates that the table is not managed by the catalog and the data files are not deleted when the table is dropped. You also need to provide a LOCATION clause to specify the path where the data files are stored.
For example:
CREATE EXTERNAL TABLE events ( date DATE, eventId STRING, eventType STRING, data STRING) USING DELTA LOCATION `/mnt/delta/events'; This creates an external Delta Lake table named events that references the data files in the
`/mnt/delta/events' path. If you drop this table, the data files will remain intact and you can recreate the table with the same statement.
NEW QUESTION # 130
While reviewing a query's execution in the Databricks Query Profiler, a data engineer observes that the Top Operators panel shows a Sort operator with high Time Spent and Memory Peak metrics. The Spark UI also reports frequent data spilling. How should the data engineer address this issue?
- A. Switch to a broadcast join to reduce memory usage.
- B. Convert the sort operation to a filter operation.
- C. Repartition the DataFrame to a single partition before sorting.
- D. Increase the number of shuffle partitions to better distribute data.
Answer: D
Explanation:
Increasing the number of shuffle partitions distributes the data across more tasks, reducing per- task memory pressure during the sort operation. This helps mitigate spilling by lowering memory peak usage per task and improves overall sort performance in large-scale distributed queries.
NEW QUESTION # 131
......
Our website always checks the update of Certified-Data-Engineer-Professional test questions to ensure the accuracy of our study materials and keep the most up-to-dated exam requirements. There are Certified-Data-Engineer-Professional free demo in our exam page for your reference and one-year free update are waiting for you. Valid Certified-Data-Engineer-Professional Real Dumps will the guarantee of your success and make you more confident in your career.
Valid Certified-Data-Engineer-Professional Test Notes: https://www.bootcamppdf.com/Certified-Data-Engineer-Professional_exam-dumps.html
- Certified-Data-Engineer-Professional Training Material 🥉 Real Certified-Data-Engineer-Professional Braindumps 😯 Certified-Data-Engineer-Professional Test Preparation 🥏 Open ▶ www.testkingpass.com ◀ and search for ➡ Certified-Data-Engineer-Professional ️⬅️ to download exam materials for free 🍝Certified-Data-Engineer-Professional New Dumps Ebook
- Pass Guaranteed Quiz 2026 Databricks Newest Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Latest Exam Labs 🤰 Search for 【 Certified-Data-Engineer-Professional 】 and download exam materials for free through “ www.pdfvce.com ” 📓Certified-Data-Engineer-Professional Exam Actual Tests
- Certified-Data-Engineer-Professional Training Material 📿 Exam Certified-Data-Engineer-Professional Registration 🏁 Valid Certified-Data-Engineer-Professional Learning Materials 👑 Search on ▷ www.pass4test.com ◁ for ⮆ Certified-Data-Engineer-Professional ⮄ to obtain exam materials for free download 🐰Certified-Data-Engineer-Professional Valid Test Format
- Fast-Download Certified-Data-Engineer-Professional Latest Exam Labs - Pass Certified-Data-Engineer-Professional Once - First-Grade Valid Certified-Data-Engineer-Professional Test Notes ⏹ ➠ www.pdfvce.com 🠰 is best website to obtain 【 Certified-Data-Engineer-Professional 】 for free download 🛑Certified-Data-Engineer-Professional Valid Dumps Sheet
- Top Certified-Data-Engineer-Professional Questions 🛤 100% Certified-Data-Engineer-Professional Accuracy ✌ Certified-Data-Engineer-Professional Valid Dumps Ppt 🍔 Search for ▛ Certified-Data-Engineer-Professional ▟ and easily obtain a free download on [ www.vce4dumps.com ] 🟧Certified-Data-Engineer-Professional Test Cram Pdf
- Certified-Data-Engineer-Professional Valid Dumps Sheet 💐 Certified-Data-Engineer-Professional Exam Answers 🔕 Certified-Data-Engineer-Professional Exam Answers ☣ Download ➤ Certified-Data-Engineer-Professional ⮘ for free by simply searching on 《 www.pdfvce.com 》 🏤Certified-Data-Engineer-Professional Valid Test Syllabus
- Authoritative Certified-Data-Engineer-Professional Latest Exam Labs - Find Shortcut to Pass Certified-Data-Engineer-Professional Exam ⏯ The page for free download of ➥ Certified-Data-Engineer-Professional 🡄 on ▶ www.practicevce.com ◀ will open immediately 🎫Certified-Data-Engineer-Professional Simulations Pdf
- Certified-Data-Engineer-Professional Simulations Pdf 🥂 Certified-Data-Engineer-Professional Exam Answers 😜 New Certified-Data-Engineer-Professional Braindumps Files 🍓 ⇛ www.pdfvce.com ⇚ is best website to obtain ✔ Certified-Data-Engineer-Professional ️✔️ for free download 🚡Top Certified-Data-Engineer-Professional Questions
- Valid Certified-Data-Engineer-Professional Latest Exam Labs - Leading Provider in Qualification Exams - Trustworthy Valid Certified-Data-Engineer-Professional Test Notes 🪒 Open { www.prepawayete.com } and search for ➡ Certified-Data-Engineer-Professional ️⬅️ to download exam materials for free 😡Certified-Data-Engineer-Professional Test Preparation
- Certified-Data-Engineer-Professional Test Preparation 🥖 Certified-Data-Engineer-Professional Training Material 🏉 Top Certified-Data-Engineer-Professional Questions 🧝 Immediately open 「 www.pdfvce.com 」 and search for 【 Certified-Data-Engineer-Professional 】 to obtain a free download 🧸Certified-Data-Engineer-Professional Test Book
- Certified-Data-Engineer-Professional Latest Exam Labs - Realistic Valid Databricks Certified Data Engineer Professional Test Notes Free PDF 🦈 Easily obtain free download of ➽ Certified-Data-Engineer-Professional 🢪 by searching on 「 www.vce4dumps.com 」 👄100% Certified-Data-Engineer-Professional Accuracy
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes