P.S. Free & New Data-Engineer-Associate dumps are available on Google Drive shared by PrepAwayPDF: https://drive.google.com/open?id=1If53IExjSKP8f93HWLklXS9BAowzvyU4
There is no site can compare with PrepAwayPDF site's training materials. This is unprecedented true and accurate test materials. To help each candidate to pass the exam, our Amazon elite team explore the real exam constantly. I can say without hesitation that this is definitely a targeted training material. The PrepAwayPDF's website is not only true, but the price of materials are very reasonable. When you choose our Data-Engineer-Associate products, we also provide one year of free updates. This allow you to have more ample time to prepare for the exam. So that you can eliminate your psychological tension of exam, and reach a satisfactory way.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Security and Governance | 18% | - Implement access control and authentication
- Protect sensitive data - Enforce compliance and data governance
|
| Topic 2: Data Ingestion and Transformation | 34% | - Implement data quality and validation - Transform and enrich data
|
| Topic 3: Data Store Management | 26% | - Optimize storage performance and cost - Manage data lifecycle and storage tiers - Design and implement data storage solutions
|
| Topic 4: Data Operations and Support | 22% | - Ensure reliability and scalability - Automate operational tasks - Backup, restore, and disaster recovery - Monitor and troubleshoot data pipelines
|
>> Data-Engineer-Associate Exam Questions Pdf <<
There are three different versions of our Data-Engineer-Associate exam questions to meet customers' needs you can choose the version that is suitable for you to study. If you buy our Data-Engineer-Associate test torrent, you will have the opportunity to make good use of your scattered time to learn. If you choose our Data-Engineer-Associate study torrent, you can make the most of your free time. So using our Data-Engineer-Associate Exam Prep will help customers make good use of their fragmentation time to study and improve their efficiency of learning. It will be easier for you to pass your Data-Engineer-Associate exam and get your certification in a short time.
NEW QUESTION # 147
A manufacturing company collects sensor data from its factory floor to monitor and enhance operational efficiency. The company uses Amazon Kinesis Data Streams to publish the data that the sensors collect to a data stream. Then Amazon Kinesis Data Firehose writes the data to an Amazon S3 bucket.
The company needs to display a real-time view of operational efficiency on a large screen in the manufacturing facility.
Which solution will meet these requirements with the LOWEST latency?
Answer: C
Explanation:
This solution will meet the requirements with the lowest latency because it uses Amazon Managed Service for Apache Flink to process the sensor data in real time and write it to Amazon Timestream, a fast, scalable, and serverless time series database. Amazon Timestream is optimized for storing and analyzing time series data, such as sensor data, and can handle trillions of events per day with millisecond latency. By using Amazon Timestream as a source, you can create an Amazon QuickSight dashboard that displays a real-time view of operational efficiency on a large screen in the manufacturing facility. Amazon QuickSight is a fully managed business intelligence service that can connect to various data sources, including Amazon Timestream, and provide interactive visualizations and insights123.
The other options are not optimal for the following reasons:
A. Use Amazon Managed Service for Apache Flink (previously known as Amazon Kinesis Data Analytics) to process the sensor data. Use a connector for Apache Flink to write data to an Amazon Timestream database.
Use the Timestream database as a source to create a Grafana dashboard. This option is similar to option C, but it uses Grafana instead of Amazon QuickSight to create the dashboard. Grafana is an open source visualization tool that can also connect to Amazon Timestream, but it requires additional steps to set up and configure, such as deploying a Grafana server on Amazon EC2, installing the Amazon Timestream plugin, and creating an IAM role for Grafana to access Timestream. These steps can increase the latency and complexity of the solution.
B. Configure the S3 bucket to send a notification to an AWS Lambda function when any new object is created. Use the Lambda function to publish the data to Amazon Aurora. Use Aurora as a source to create an Amazon QuickSight dashboard. This option is not suitable for displaying a real-time view of operational efficiency, as it introduces unnecessary delays and costs in the data pipeline. First, the sensor data is written to an S3 bucket by Amazon Kinesis Data Firehose, which can have a buffering interval of up to 900 seconds.
Then, the S3 bucket sends a notification to a Lambda function, which can incur additional invocation and execution time. Finally, the Lambda function publishes the data to Amazon Aurora, a relational database that is not optimized for time series data and can have higher storage and performance costs than Amazon Timestream .
D. Use AWS Glue bookmarks to read sensor data from the S3 bucket in real time. Publish the data to an Amazon Timestream database. Use the Timestream database as a source to create a Grafana dashboard. This option is also not suitable for displaying a real-time view of operational efficiency, as it uses AWS Glue bookmarks to read sensor data from the S3 bucket. AWS Glue bookmarks are a feature that helps AWS Glue jobs and crawlers keep track of the data that has already been processed, so that they can resume from where they left off. However, AWS Glue jobs and crawlers are not designed for real-time data processing, as they can have a minimum frequency of 5 minutes and a variable start-up time. Moreover, this option also uses Grafana instead of Amazon QuickSight to create the dashboard, which can increase the latency and complexity of the solution .
1: Amazon Managed Streaming for Apache Flink
2: Amazon Timestream
3: Amazon QuickSight
Analyze data in Amazon Timestream using Grafana
Amazon Kinesis Data Firehose
Amazon Aurora
AWS Glue Bookmarks
AWS Glue Job and Crawler Scheduling
NEW QUESTION # 148
A company receives .csv files that contain physical address data. The data is in columns that have the following names: Door_No, Street_Name, City, and Zip_Code. The company wants to create a single column to store these values in the following format: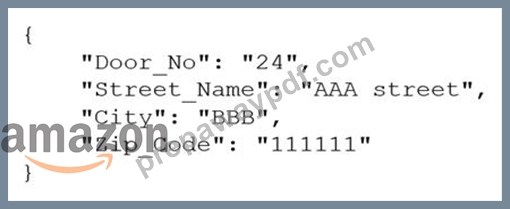
Which solution will meet this requirement with the LEAST coding effort?
Answer: A
Explanation:
The NEST TO MAP transformation allows you to combine multiple columns into a single column that contains a JSON object with key-value pairs. This is the easiest way to achieve the desired format for the physical address data, as you can simply select the columns to nest and specify the keys for each column. The NEST TO ARRAY transformation creates a single column that contains an array of values, which is not the same as the JSON object format. The PIVOT transformation reshapes the data by creating new columns from unique values in a selected column, which is not applicable for this use case. Writing a Lambda function in Python requires more coding effort than using AWS Glue DataBrew, which provides a visual and interactive interface for data transformations. References:
* 7 most common data preparation transformations in AWS Glue DataBrew (Section: Nesting and unnesting columns)
* NEST TO MAP - AWS Glue DataBrew (Section: Syntax)
NEW QUESTION # 149
A data engineer is building a new data pipeline that stores metadata in an Amazon DynamoDB table. The data engineer must ensure that all items that are older than a specified age are removed from the DynamoDB table daily.
Which solution will meet this requirement with the LEAST configuration effort?
Answer: D
Explanation:
DynamoDB Time to Live (TTL) automatically expires and deletes items based on a timestamp attribute - it requires minimal setup and runs without additional infrastructure.
The engineer only needs to define a TTL attribute (e.g., expiration_time) and set its epoch value when items are inserted.
"To automatically delete old items from a DynamoDB table, enable TTL and define a timestamp attribute.
Items are removed automatically after the specified time with no extra maintenance."
- Ace the AWS Certified Data Engineer - Associate Certification - version 2 - apple.pdf This is serverless, free, and requires no scheduling or code-based cleanup.
NEW QUESTION # 150
A company needs to implement a workflow to process transactions. Each transaction goes through multiple levels of validation. Each validation level depends on the preceding validation level.
The workflow must either process or reject each transaction within 24 hours. The workflow must run for less than 24 hours total.
Which solution will meet these requirements with the LEAST operational cost?
Answer: C
Explanation:
Option A is correct because this is a sequential, dependent workflow where each validation stage depends on the previous one, and the overall execution can last up to 24 hours. AWS states that Standard Workflows in Step Functions are ideal for long-running, durable, auditable workflows and can run for up to one year. AWS also documents the Wait for a Callback with Task Token pattern, which is specifically designed for workflows that must pause until an external process reports completion. That maps directly to multi-level validations that may complete asynchronously but still need orchestration within a bounded window.
Option B is incorrect because Express Workflows can run for only up to five minutes, so they cannot support a transaction workflow that may take many hours. Option C adds more custom code and operational management than Step Functions and does not naturally provide the same stateful orchestration, dependency tracking, and callback waiting pattern. Option D is also more operationally heavy and is better suited to data pipeline orchestration than per-transaction validation workflows. Therefore, Standard Step Functions provides the lowest operational cost while fully meeting the timing and dependency requirements.
NEW QUESTION # 151
A company uses AWS Glue Data Catalog to index data that is uploaded to an Amazon S3 bucket every day.
The company uses a daily batch processes in an extract, transform, and load (ETL) pipeline to upload data from external sources into the S3 bucket.
The company runs a daily report on the S3 data. Some days, the company runs the report before all the daily data has been uploaded to the S3 bucket. A data engineer must be able to send a message that identifies any incomplete data to an existing Amazon Simple Notification Service (Amazon SNS) topic.
Which solution will meet this requirement with the LEAST operational overhead?
Answer: D
Explanation:
AWS Glue workflows are designed to orchestrate the ETL pipeline, and you can create data quality checks to ensure the uploaded datasets are complete before running reports. If there is an issue with the data, AWS Glue workflows can trigger an Amazon EventBridge event that sends a message to an SNS topic.
* AWS Glue Workflows:
* AWS Glue workflows allow users to automate and monitor complex ETL processes. You can include data quality actions to check for null values, data types, and other consistency checks.
* In the event of incomplete data, an EventBridge event can be generated to notify via SNS.
NEW QUESTION # 152
......
To keep you updated with latest changes in the Data-Engineer-Associate test questions, we offer one-year free updates in the form of new questions according to the requirement of Data-Engineer-Associate real exam. Updated Data-Engineer-Associate vce dumps ensure the accuracy of learning materials and guarantee success of in your first attempt. Why not let our Data-Engineer-Associate Dumps Torrent help you to pass your exam without spending huge amount of money.
Pdf Demo Data-Engineer-Associate Download: https://www.prepawaypdf.com/Amazon/Data-Engineer-Associate-practice-exam-dumps.html
What's more, part of that PrepAwayPDF Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1If53IExjSKP8f93HWLklXS9BAowzvyU4