What's more, part of that DumpsFree MLA-C01 dumps now are free: https://drive.google.com/open?id=1qCg1TteZSFRBs8R8JZ6ChpSKSxJh-flm
So rest assured that with the DumpsFree MLA-C01 exam questions you will get everything that is necessary for MLA-C01 exam preparation and success. Take a decision right now and just get registered in the Amazon MLA-C01 certification exam and start preparation with DumpsFree MLA-C01 Exam Questions.You do not need to get worried about it choose the right DumpsFree AWS Certified Machine Learning Engineer - Associate exam questions formats and start this journey without wasting further time.
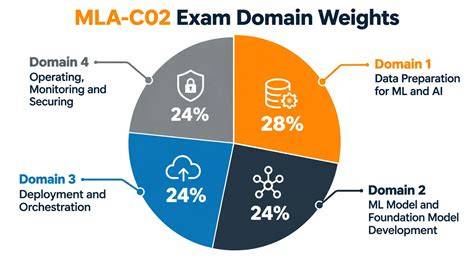
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Exam Amazon MLA-C01 Sample <<
In reaction to the phenomenon, therefore, the MLA-C01 test material is reasonable arrangement each time the user study time, as far as possible let users avoid using our latest MLA-C01 exam torrent for a long period of time, it can better let the user attention relatively concentrated time efficient learning. The MLA-C01 practice materials in every time users need to master the knowledge, as long as the user can complete the learning task in this period, the MLA-C01 test material will automatically quit learning system, to alert users to take a break, get ready for the next period of study.
NEW QUESTION # 123
A company runs an ML model on Amazon SageMaker AI. The company uses an automatic process that makes API calls to create training jobs for the model. The company has new compliance rules that prohibit the collection of aggregated metadata from training jobs.
Which solution will prevent SageMaker AI from collecting metadata from the training jobs?
Answer: D
Explanation:
Amazon SageMaker AI automatically collects aggregated metadata from training jobs to improve service reliability, performance, and operational insights. This metadata can include information such as algorithm usage, instance types, resource utilization, and job configuration details. However, AWS documentation clearly states that customers can opt out of SageMaker metadata collection to meet regulatory or compliance requirements.
SageMaker provides a supported mechanism to disable metadata tracking at the training job level. By explicitly opting out of metadata tracking when submitting training jobs-either through the AWS Management Console, AWS CLI, or SDK-the service will stop collecting aggregated metadata for those jobs. This option is specifically designed for customers with strict compliance, data residency, or regulatory constraints.
Option B is incorrect because running training jobs in a private subnet within a custom VPC controls network isolation, not service-level telemetry or metadata collection. Metadata collection occurs at the SageMaker service layer and is independent of VPC configuration.
Option C is also incorrect because encrypting training data with a customer-managed AWS KMS key protects data at rest and in transit but does not prevent SageMaker from collecting operational metadata about training jobs.
Option D is incorrect because AWS Nitro instances provide enhanced security and performance isolation at the infrastructure level but have no impact on SageMaker's metadata collection mechanisms.
Therefore, opting out of metadata tracking for training jobs is the only solution that directly addresses the compliance requirement and is explicitly supported by AWS documentation.
NEW QUESTION # 124
A company needs an AWS solution that will automatically create versions of ML models as the models are created.
Which solution will meet this requirement?
Answer: D
NEW QUESTION # 125
Case study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
The ML engineer needs to use an Amazon SageMaker built-in algorithm to train the model.
Which algorithm should the ML engineer use to meet this requirement?
Answer: D
Explanation:
Why Linear Learner?
* SageMaker'sLinear Learneralgorithm is well-suited for binary classification problems such as fraud detection. It handles class imbalance effectively by incorporating built-in options forweight balancing across classes.
* Linear Learner can capture patterns in the data while being computationally efficient.
Key Features of Linear Learner:
* Automatically weights minority and majority classes.
* Supports both classification and regression tasks.
* Handles interdependencies among features effectively through gradient optimization.
Steps to Implement:
* Use the SageMaker Python SDK to set up a training job with the Linear Learner algorithm.
* Configure the hyperparameters to enable balanced class weights.
* Train the model with the balanced dataset created using SageMaker Data Wrangler.
NEW QUESTION # 126
Case Study
A company is building a web-based AI application by using Amazon SageMaker. The application will provide the following capabilities and features: ML experimentation, training, a central model registry, model deployment, and model monitoring.
The application must ensure secure and isolated use of training data during the ML lifecycle. The training data is stored in Amazon S3.
The company must implement a manual approval-based workflow to ensure that only approved models can be deployed to production endpoints.
Which solution will meet this requirement?
Answer: B
Explanation:
To implement a manual approval-based workflow ensuring that only approved models are deployed to production endpoints, Amazon SageMaker provides integrated tools such asSageMaker Pipelinesand the SageMaker Model Registry.
SageMaker Pipelinesis a robust service for building, automating, and managing end-to-end machine learning workflows. It facilitates the orchestration of various steps in the ML lifecycle, including data preprocessing, model training, evaluation, and deployment. By integrating with theSageMaker Model Registry, it enables seamless tracking and management of model versions and their approval statuses.
Implementation Steps:
* Define the Pipeline:
* Create a SageMaker Pipeline encompassing steps for data preprocessing, model training, evaluation, and registration of the model in the Model Registry.
* Incorporate aCondition Stepto assess model performance metrics. If the model meets predefined criteria, proceed to the next step; otherwise, halt the process.
* Register the Model:
* Utilize theRegisterModelstep to add the trained model to the Model Registry.
* Set the ModelApprovalStatus parameter to PendingManualApproval during registration. This status indicates that the model awaits manual review before deployment.
* Manual Approval Process:
* Notify the designated approver upon model registration. This can be achieved by integrating Amazon EventBridge to monitor registration events and trigger notifications via AWS Lambda functions.
* The approver reviews the model's performance and, if satisfactory, updates the model's status to Approved using the AWS SDK or through the SageMaker Studio interface.
* Deploy the Approved Model:
* Configure the pipeline to automatically deploy models with an Approved status to the production endpoint. This can be managed by adding deployment steps conditioned on the model's approval status.
Advantages of This Approach:
* Automated Workflow:SageMaker Pipelines streamline the ML workflow, reducing manual interventions and potential errors.
* Governance and Compliance:The manual approval step ensures that only thoroughly evaluated models are deployed, aligning with organizational standards.
* Scalability:The solution supports complex ML workflows, making it adaptable to various project requirements.
By implementing this solution, the company can establish a controlled and efficient process for deploying models, ensuring that only approved versions reach production environments.
References:
* Automate the machine learning model approval process with Amazon SageMaker Model Registry and Amazon SageMaker Pipelines
* Update the Approval Status of a Model - Amazon SageMaker
NEW QUESTION # 127
An ML engineer has developed a binary classification model outside of Amazon SageMaker. The ML engineer needs to make the model accessible to a SageMaker Canvas user for additional tuning.
The model artifacts are stored in an Amazon S3 bucket. The ML engineer and the Canvas user are part of the same SageMaker domain.
Which combination of requirements must be met so that the ML engineer can share the model with the Canvas user? (Choose two.)
Answer: A,E
Explanation:
The SageMaker Canvas user needs permissions to access the Amazon S3 bucket where the model artifacts are stored to retrieve the model for use in Canvas.
Registering the model in the SageMaker Model Registry allows the model to be tracked and managed within the SageMaker ecosystem. This makes it accessible for tuning and deployment through SageMaker Canvas.
This combination ensures proper access control and integration within SageMaker, enabling the Canvas user to work with the model.
NEW QUESTION # 128
......
All of the traits above are available in this web-based MLA-C01 practice test of DumpsFree. The main distinction is that the Amazon MLA-C01 online practice test works with not only Windows but also Mac, Linux, iOS, and Android. Above all, taking the MLA-C01 web-based practice test while preparing for the examination does not need any software installation. Furthermore, MS Edge, Internet Explorer, Opera, Safari, Chrome, and Firefox support the web-based Amazon MLA-C01 practice test of DumpsFree.
Accurate MLA-C01 Study Material: https://www.dumpsfree.com/MLA-C01-valid-exam.html
DOWNLOAD the newest DumpsFree MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1qCg1TteZSFRBs8R8JZ6ChpSKSxJh-flm