DOWNLOAD the newest PassLeader DP-420 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1fIgHzhG_N7X4_p7-ba29iDa51iRmEzm3
You do not need to think it is too late for you to study. As the saying goes, success and opportunity are only given to those people who are well-prepared! If you really long to own the DP-420 certification, it is necessary for you to act now. We are willing to help you gain the certification. In order to meet the needs of all people, the experts of our company designed such a DP-420 Guide Torrent that can help you pass your exam successfully.
The DP-420 certification exam is designed to test candidates on a range of topics, including Azure Cosmos DB data modeling, partitioning, indexing, and querying. It also covers concepts related to Azure Functions, Azure Event Hubs, Azure Stream Analytics, and Azure Cosmos DB Change Feed. DP-420 exam is intended for professionals who have experience working with Azure Cosmos DB and are knowledgeable about cloud computing concepts and principles.
The DP-420 Certification Exam covers a wide range of topics related to Azure Cosmos DB, including data modeling, partitioning, indexing, querying, and tuning. Candidates are expected to have a deep understanding of how to use Azure Cosmos DB to build scalable, resilient, and highly available cloud-native applications. They should also be familiar with Azure services such as Azure Functions, Azure App Service, and Azure Event Grid.
If you have your own job and have little time to prepare for the exam, you can choose us. DP-420 exam bootcamp of us is high quality, and you just need to spend about 48to 72 hours, you can pass the exam. In addition, DP-420 exam bootcamp contains most of knowledge points of the exam, and you can also improve you professional ability in the process of learning. We offer you free update for 365 days after you buy DP-420 Exam Dumps. The update version will be sent to your email automatically.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 21
You need to create a data store for a directory of small and medium-sized businesses (SMBs). The data store must meet the following requirements:
* Store companies and the users employed by them. Each company will have less than 1,000 users.
* Some users have data that is greater than 2 KB.
* Associate each user to only one company.
* Provide the ability to browse by company.
* Provide the ability to browse the users by company.
* Whenever a company or user profile is selected, show a details page for the company and all the related users.
* Be optimized for reading data.
Which design should you implement to optimize the data store for reading data?
Answer: B
Explanation:
Azure Cosmos DB is a multi-model databas e that supports various data models, such as documents, key- value, graph, and column -family 3 . The core content-model of Cosmos DB's database engine is based on atom-record- sequence (ARS), which allows it to store and query different types of data in a flexible and efficien t way 3 .
To optimize the data store for reading data, you should consider the following factors:
* The size and shape of your data
* The frequency and complexity of your queries
* The latency and throughput requirements of your application
* The trade-offs between storage efficiency and query performance
Based on these factors, one possible design that you could implement is B. In a company container, create a document for each company. Embed the users into company documents. Use the company ID as the partition key .
This design has the following advantages:
* It stores companies and users as self-contained documents that can be easily retrieved by company ID 1
.
* It avoids storing redundant data or creat ing additional containers for users 1 .
* It allows you to browse b y company and browse the users by company with simple queries 1 .
* It shows a details page for the company and all the related users by fetching a single document 1 .
* It leverages the benefits of embedding data, such as reducing the number of requests , improving query performance, and simplifying data consistency 2 .
This design also has some limitations, such as:
* It may not be suitable for some users who have data that is greater than 2 KB, as it could exc eed the maximum document size limit of 2 MB 2 .
* It may not be optimal for scenarios where users need to be associated with more than one company or queried independently from companies 2 .
* It may not be scalable for companies that have more than 1,000 users, as it could result in hot partitions or throttling 2 .
Depending on your specific use case and requirements, you may need to adjust this design or choose a different one. For example, you could use a hybrid data model that combines embedding and referencing data
2 , or you could use a graph data model that expresses entities and relationships as vertices and edges.
NEW QUESTION # 22
Hotspot Question
You provision Azure resources by using the following Azure Resource Manager (ARM) template.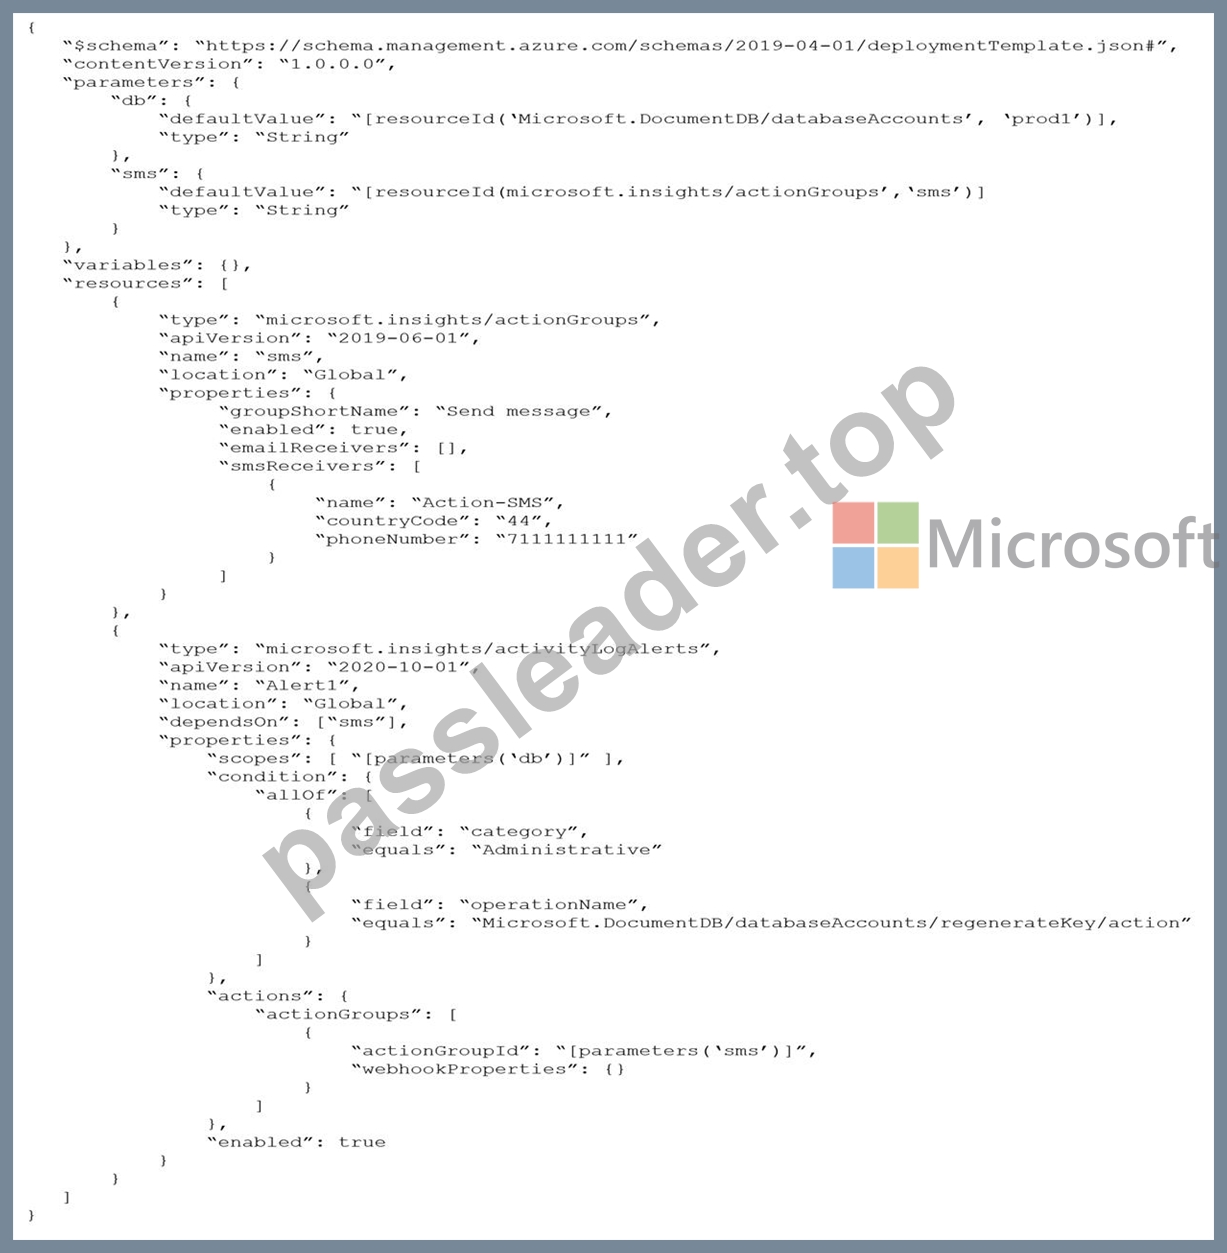
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.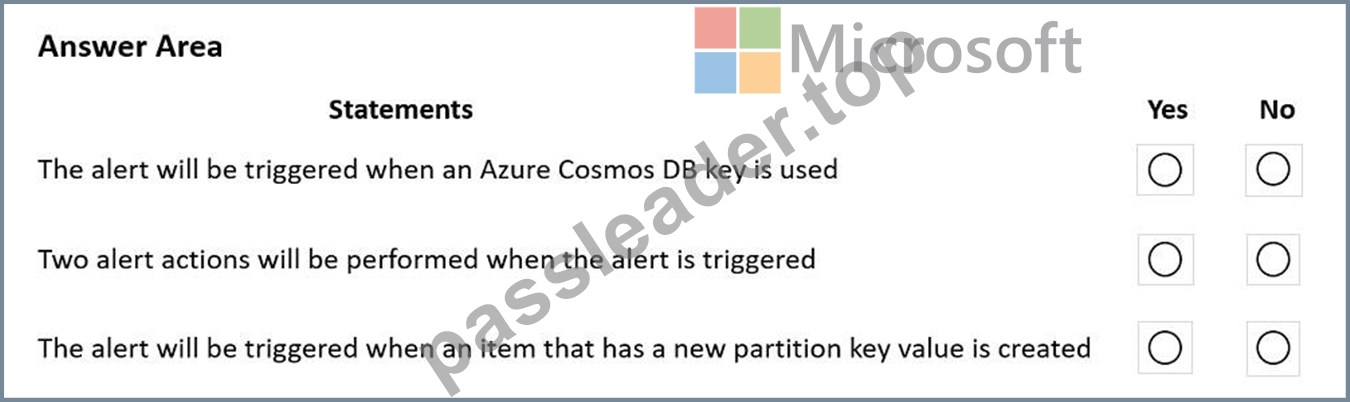
Answer:
Explanation: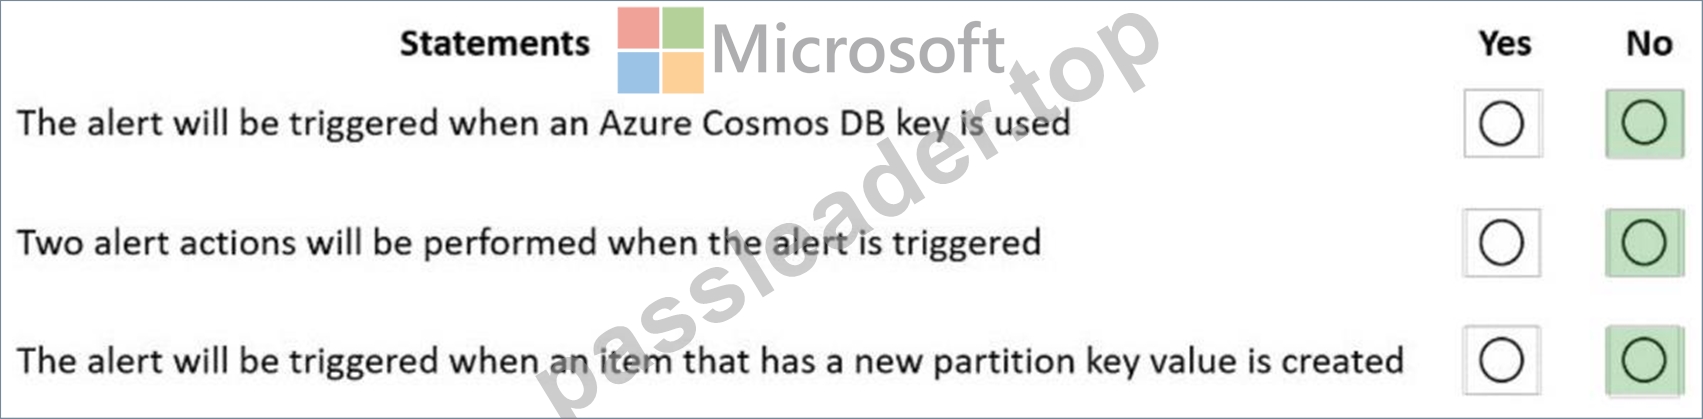
Explanation:
Box 1: No
An alert is triggered when the DB key is regenerated, not when it is used.
Note: The az cosmosdb keys regenerate command regenerates an access key for a Azure Cosmos DB database account.
Box 2: No
Only an SMS action will be taken.
Emailreceivers is empty so no email action is taken.
Box 3: No
The trigger is fired when the database account has a new key regenerated not when an item with a new partition key value is created.
Reference: https://docs.microsoft.com/en-us/cli/azure/cosmosdb/keys
NEW QUESTION # 23
You have an Apache Spark pool in Azure Synapse Analytics that runs the following Python code in a notebook.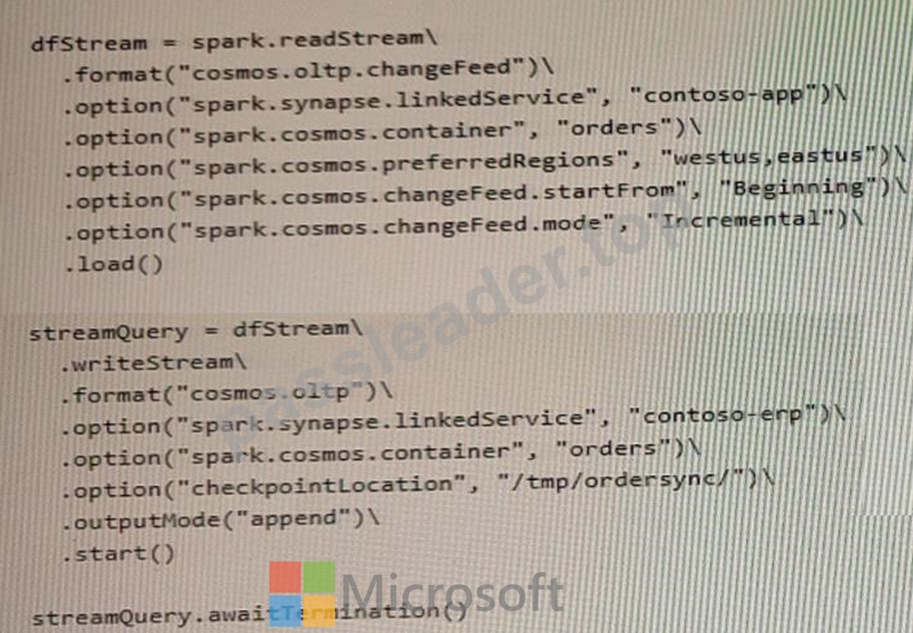
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.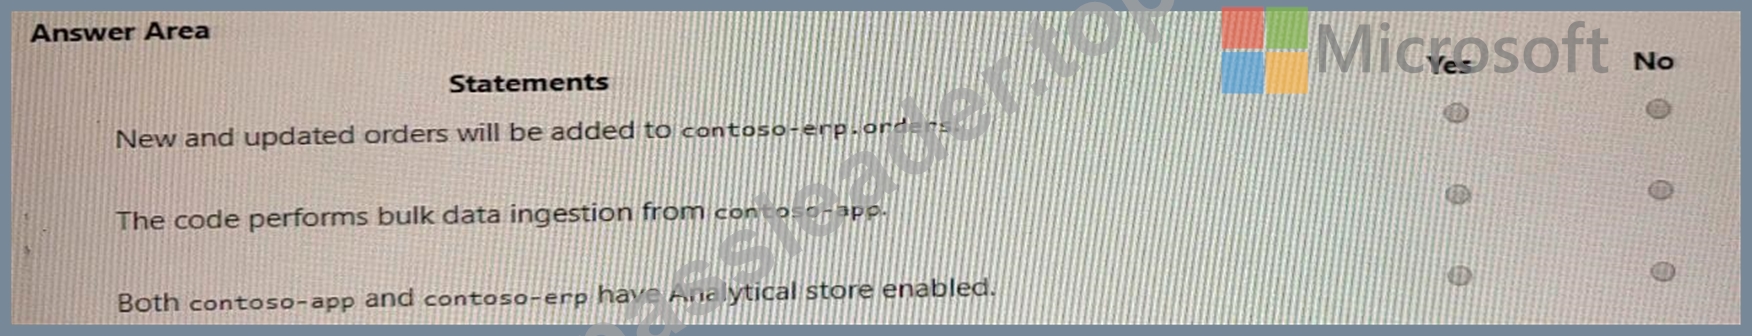
Answer:
Explanation: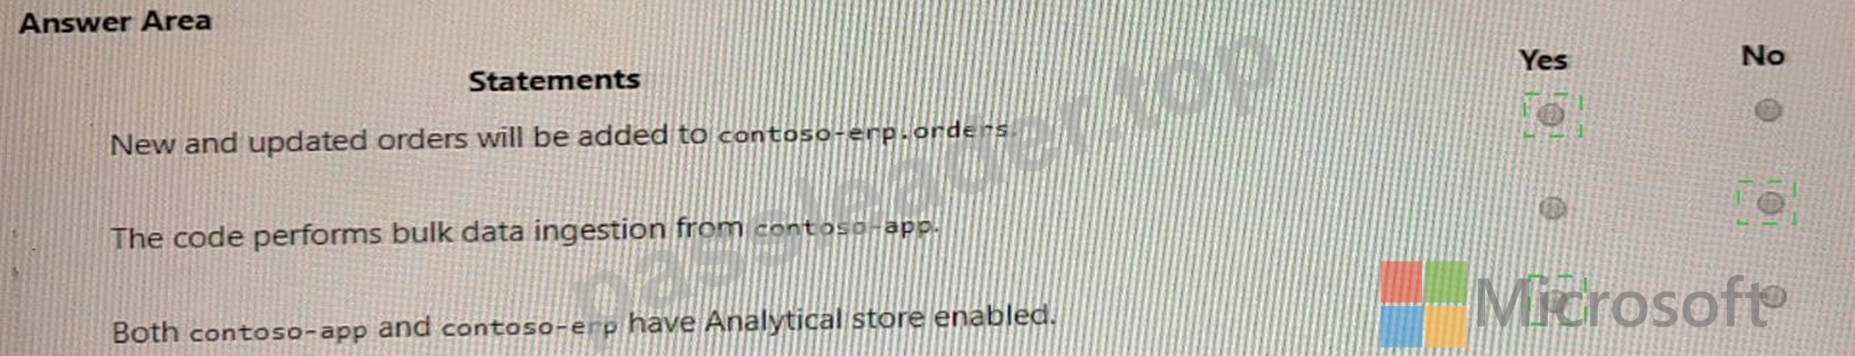
Explanation:
New and updated orders will be added to contoso-erp.orders: Yes
The code performs bulk data ingestion from contoso-app: No
Both contoso-app and contoso-erp have Analytics store enabled: Yes
The code uses the spark.readStream method to read data from a container named orders in a database named contoso-app. The data is then filtered by a condition and written to another container named orders in a database named contoso-erp using the spark.writeStream method. The write mode is set to "append", which means that new and updated orders will be added to the destination container1.
The code does not perform bulk data ingestion from contoso-app, but rather stream processing. Bulk data ingestion is a process of loading large amounts of data into a data store in batches. Stream processing is a process of continuously processing data as it arrives in real-time2.
Both contoso-app and contoso-erp have Analytics store enabled, because they are both accessed by Spark pools using the spark.cosmos.oltp method. This method requires that the containers have Analytics store enabled, which is a feature that allows Spark pools to query data stored in Azure Cosmos DB containers using SQL APIs3.
NEW QUESTION # 24
You are designing an Azure Cosmos DB for NoSQL solution to store data from IoT devices.
Writes from the devices will occur every second. Data will be retained indefinitely.
The following is a sample of the data.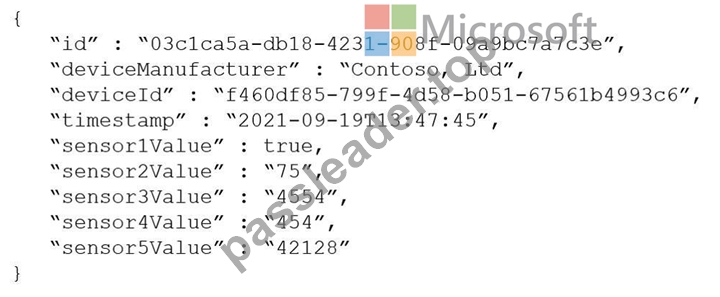
You need to select a partition key that meets the following requirements for writes:
- Minimizes the partition skew
- Avoids capacity limits
- Avoids hot partitions
What should you do?
Answer: D
Explanation:
Correct:
* Create a new synthetic key that contains deviceId and a random number.
Use a partition key with a random suffix. Distribute the workload more evenly is to append a random number at the end of the partition key value. When you distribute items in this way, you can perform parallel write operations across partitions.
* Create a new synthetic key that contains deviceId and timestamp.
Concatenate multiple properties of an item.
You can form a partition key by concatenating multiple property values into a single artificial partitionKey property. These keys are referred to as synthetic keys.
For example, consider the following example document:
{
"deviceId": "abc-123",
"date": 2018
}
For the previous document, one option is to set /deviceId or /date as the partition key. Use this option, if you want to partition your container based on either device ID or date. Another option is to concatenate these two values into a synthetic partitionKey property that's used as the partition key.
{
"deviceId": "abc-123",
"date": 2018,
"partitionKey": "abc-123-2018"
Incorrect:
* Create a new synthetic key that contains deviceId and deviceManufacturer.
All the devices could have the same manufacturer.
* Create a new synthetic key that contains deviceId and sensor1Value.
Senser1Value has only two values.
* Use deviceId as the partition key.
* Use deviceManufacturer as the partition key.
All the devices could have the same manufacturer.
* Use sensor1Value as the partition key
* Use timestamp as the partition key.
You will also not like to partition the data on "DateTime", because this will create a hot partition.
Imagine you have partitioned the data on time, then for a given minute, all the calls will hit one partition. If you need to retrieve the data for a customer, then it will be a fan-out query because data may be distributed on all the partitions.
Reference:
https://docs.microsoft.com/en-us/azure/cosmos-db/sql/synthetic-partition-keys
https://docs.microsoft.com/en-us/azure/cosmos-db/concepts-limits
NEW QUESTION # 25
You have a database in an Azure Cosmos DB Core (SQL) API account.
You plan to create a container that will store employee data for 5,000 small businesses. Each business will have up to 25 employees. Each employee item will have an emailAddress value.
You need to ensure that the emailAddress value for each employee within the same company is unique.
To what should you set the partition key and the unique key? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.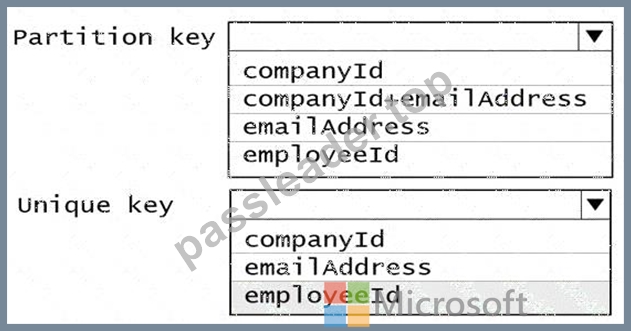
Answer:
Explanation: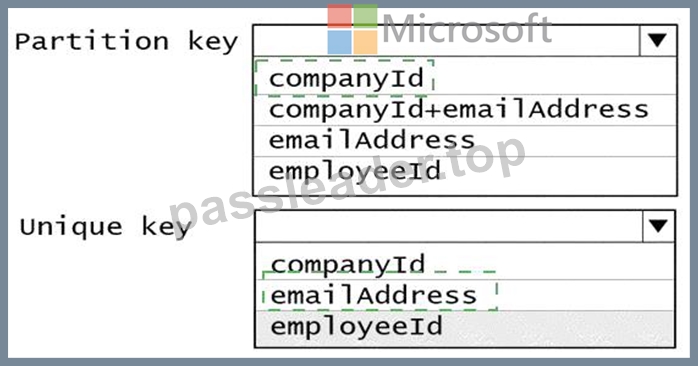
Explanation: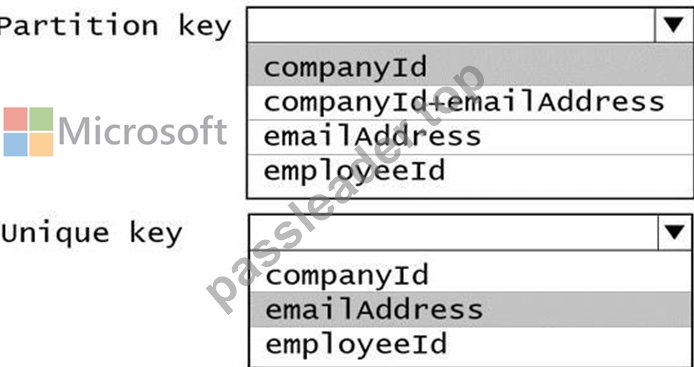
Box 1: CompanyID
After you create a container with a unique key policy, the creation of a new or an update of an existing item resulting in a duplicate within a logical partition is prevented, as specified by the unique key constraint. The partition key combined with the unique key guarantees the uniqueness of an item within the scope of the container.
For example, consider an Azure Cosmos container with Email address as the unique key constraint and CompanyID as the partition key. When you configure the user's email address with a unique key, each item has a unique email address within a given CompanyID. Two items can't be created with duplicate email addresses and with the same partition key value.
Box 2: emailAddress
Reference: https://docs.microsoft.com/en-us/azure/cosmos-db/unique-keys
NEW QUESTION # 26
......
DP-420 Official Cert Guide: https://www.passleader.top/Microsoft/DP-420-exam-braindumps.html
DOWNLOAD the newest PassLeader DP-420 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1fIgHzhG_N7X4_p7-ba29iDa51iRmEzm3