P.S. Free & New DY0-001 dumps are available on Google Drive shared by Itcertking: https://drive.google.com/open?id=1k9pPizIdRZqD-bJyTI9_V4enbJ_0Jpzp
The CompTIA DY0-001 certification topics or syllabus are updated with the passage of time. To pass the CompTIA CompTIA DataAI Certification Exam exam you have to know these topics. The Itcertking DY0-001 certification exam trainers always work on these topics and add their appropriate CompTIA DY0-001 Exam Questions And Answers in the DY0-001 exam dumps. These latest CompTIA CompTIA DataAI Certification Exam exam topics are added in all CompTIA CompTIA DataAI Certification Exam exam questions formats.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> DY0-001 Pass Leader Dumps <<
If you care about your qualification exams and have some queries about DY0-001 preparation materials, we are pleased to serve for you, you can feel free to contact us via email or online service about your doubt. Our company are established more than 10 years, our quality of DY0-001 valid practice test questions are the leading position in this filed. We believe our DY0-001 exam guide will help you pass exam easily without too much spirit & time. All our DY0-001 training materials are compiled painstakingly.
NEW QUESTION # 55
A data scientist needs to:
Build a predictive model that gives the likelihood that a car will get a flat tire.
Provide a data set of cars that had flat tires and cars that did not.
All the cars in the data set had sensors taking weekly measurements of tire pressure similar to the sensors that will be installed in the cars consumers drive.
Which of the following is the most immediate data concern?
Answer: C
Explanation:
# Granularity misalignment refers to a mismatch between the level of detail in the predictor variables and the event being predicted.
In this case, flat tires are likely discrete, infrequent events, while tire pressure is measured weekly. If the prediction model is trying to link a specific tire pressure value to a binary outcome (flat tire: yes/no), and the timing doesn't align precisely, the predictor variable (pressure) may not be granular enough to accurately associate with the event.
Why the other options are incorrect:
* B: While outliers can exist, they are not the most immediate concern given the time-series nature of the data.
* C: While domain expertise is helpful, it doesn't directly address the data structure issue.
* D: Lagged observations can be engineered in modeling but aren't the primary problem here.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 3.1 (Data Granularity):"Granularity misalignment occurs when the temporal or spatial resolution of features does not align with the prediction target."
* Data Science Process Guide, Section 2.3:"Predictive performance can suffer when temporal mismatch exists between observations and outcomes. Granularity issues must be resolved prior to modeling."
-
NEW QUESTION # 56
Which of the following JOINS would generate the largest amount of data?
Answer: D
Explanation:
# A CROSS JOIN returns the Cartesian product of the two tables - meaning every row from the first table is paired with every row from the second table. If Table A has m rows and Table B has n rows, a CROSS JOIN will return m × n rows, making it the largest possible result set of all JOIN types.
Why the other options are incorrect:
* A & B: RIGHT JOIN and LEFT JOIN return matched records plus unmatched rows from one side - but not all possible combinations.
* D: INNER JOIN returns only matched rows between tables, typically producing fewer records than a CROSS JOIN.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 5.2:"CROSS JOINs generate the Cartesian product of two datasets and should be used carefully due to the exponential growth in the number of records."
* SQL for Data Scientists, Chapter 3:"CROSS JOINs can produce very large datasets, often unintentionally, due to their non-restrictive matching logic."
-
NEW QUESTION # 57
A data analyst wants to generate the most data using tables from a database. Which of the following is the best way to accomplish this objective?
Answer: C
Explanation:
# FULL OUTER JOIN returns all rows from both tables, inserting NULLs where no match exists. This join includes the maximum possible number of records - all matches, plus all unmatched records from both sides.
Why the other options are incorrect:
* A: INNER JOIN returns only matching rows - less total data.
* B & C: LEFT/RIGHT JOIN include all rows from one table only.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 5.2:"A FULL OUTER JOIN maximizes data volume by including all matched and unmatched records from both tables."
* SQL for Data Science, Chapter 4:"Use FULL OUTER JOIN when the goal is to preserve every record from both datasets regardless of match."
-
NEW QUESTION # 58
A data scientist is designing a real-time machine-learning model that classifies a user based on initial behavior. The run times of these models are provided in the following table: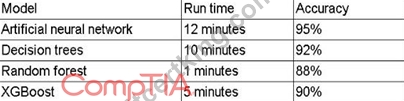
Which of the following models should the data scientist recommend for deployment?
Answer: C
Explanation:
# In real-time systems, low latency (short run time) is critical. While the Artificial Neural Network provides the highest accuracy, its 12-minute runtime makes it unsuitable for real-time inference. Random forest is the fastest but offers the lowest accuracy.
XGBoost provides an excellent balance between runtime (5 minutes) and accuracy (90%). It's well-optimized for performance and scalability, and thus is a strong candidate for real-time classification when balancing both efficiency and predictive quality.
Why the other options are less ideal:
* B: Random forest is faster but significantly less accurate.
* C: Decision trees have longer run time than XGBoost with only a 2% accuracy improvement.
* D: Artificial neural network has the highest accuracy but is too slow for real-time applications.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 4.3:"In real-time applications, model selection involves a trade-off between accuracy and inference speed. XGBoost offers competitive accuracy with efficient runtime."
* Machine Learning Systems Design Guide, Chapter 7:"XGBoost is well-suited for real-time systems due to its balance of model complexity and fast prediction times."
-
NEW QUESTION # 59
A data scientist wants to predict a person's travel destination. The options are:
* Branson, Missouri, United States
* Mount Kilimanjaro, Tanzania
* Disneyland Paris, Paris, France
* Sydney Opera House, Sydney, Australia
Which of the following models would best fit this use case?
Answer: A
Explanation:
# Linear Discriminant Analysis (LDA) is a supervised classification method used to predict a categorical target (such as travel destination) based on multiple input features. It models decision boundaries between classes - which is appropriate when predicting a fixed set of destinations.
Why the other options are incorrect:
* B: k-means is unsupervised and doesn't use labeled output like travel destination.
* C: Latent Semantic Analysis is used for extracting relationships from textual data - not categorical prediction.
* D: PCA reduces dimensionality but doesn't classify.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 4.1:"Linear Discriminant Analysis is used when the response variable is categorical and the objective is classification."
* Classification Techniques Guide, Chapter 7:"LDA excels in multi-class prediction when the input data is continuous and the output is a known category."
-
NEW QUESTION # 60
......
The pass rate is 98.65% for DY0-001 learning materials, and if you choose us, we can ensure you that you can pass the exam just one time. In addition, DY0-001 exam dumps are edited by skilled experts, who have the professional knowledge for DY0-001 exam dumps, therefore the quality and accuracy can be guaranteed. We also pass guarantee and money back guarantee for DY0-001 Learning Materials, and if you fail to pass the exam, we will give you full refund, and no other questions will be asked.
DY0-001 Preparation: https://www.itcertking.com/DY0-001_exam.html
2026 Latest Itcertking DY0-001 PDF Dumps and DY0-001 Exam Engine Free Share: https://drive.google.com/open?id=1k9pPizIdRZqD-bJyTI9_V4enbJ_0Jpzp