Databricks-Machine-Learning-Professional出題内容、Databricks-Machine-Learning-Professional資格参考書
P.S.JapancertがGoogle Driveで共有している無料の2026 Databricks Databricks-Machine-Learning-Professionalダンプ:https://drive.google.com/open?id=1ajcYTRVNFWdurfeXHivRvY5lAsn_KN26
誰もが知っているように、DatabricksのDatabricks-Machine-Learning-Professional模擬テストシミュレーションは試験の成功に重要な役割を果たします。 シミュレーションにより、Databricks-Machine-Learning-Professional試験問題の無料デモを利用して、実際の試験の状況を把握できます。 昔のことわざにあるように、敵とあなた自身を知っているので、敗北の危険なしに100回戦うことができます。 JapancertのDatabricks-Machine-Learning-Professionalトレーニング資料のシミュレーションにより、あなたの長所と短所を明確に理解できると同時に、Databricks-Machine-Learning-Professional試験について包括的に学び、簡単にDatabricks Certified Machine Learning Professional合格することができます。
Databricks Databricks-Machine-Learning-Professional Exam Overview:
| Certification Vendor: | Databricks |
|---|
| Exam Name: | Databricks Certified Machine Learning Professional |
|---|
| Exam Number: | Databricks-Machine-Learning-Professional |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Related Certifications: | Databricks Certified Machine Learning Associate |
|---|
| Exam Duration: | 120 minutes |
|---|
| Real Exam Qty: | Approximately 45–60 |
|---|
| Passing Score: | Not publicly disclosed |
|---|
| Exam Price: | $200 USD |
|---|
| Available Languages: | English |
|---|
| Exam Format: | Scenario-based questions, Multiple select, Multiple choice |
|---|
| Recommended Training: | Databricks Academy Machine Learning Training |
|---|
| Exam Registration: | Databricks Certification Portal |
|---|
| Sample Questions: | Databricks Databricks-Machine-Learning-Professional Sample Questions |
|---|
| Exam Way: | Online proctored exam (typically delivered via Databricks certification partners such as Certiverse or Pearson VUE depending on region and current program structure) |
|---|
| Pre Condition: | Recommended experience with Databricks platform and machine learning workflows; Databricks Certified Machine Learning Associate certification is often recommended but not strictly required. |
|---|
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
|---|
>> Databricks-Machine-Learning-Professional出題内容 <<
Databricks Databricks-Machine-Learning-Professional資格参考書、Databricks-Machine-Learning-Professional学習教材
当社の製品よりも高いプロファイルと低価格を備えた他の学習教材もあるかもしれませんが、Databricks-Machine-Learning-Professional学習教材の合格率は彼らのものよりもはるかに高いことを保証できます。そしてこれが最も重要です。以前のデータによると、Databricks-Machine-Learning-Professionalトレーニング質問を使用する人の98%〜99%が試験に合格しました。あなたが私たちに信頼を与えてくれるなら、私たちはあなたに成功を与えます。
Databricks Databricks-Machine-Learning-Professional 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| トピック 2 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| トピック 3 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
| トピック 4 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| トピック 5 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| トピック 6 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
| トピック 7 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| トピック 8 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| トピック 9 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| トピック 10 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
Databricks Certified Machine Learning Professional 認定 Databricks-Machine-Learning-Professional 試験問題 (Q25-Q30):
質問 # 25
A data scientist wants to remove the star_rating column from the Delta table at the location path.
To do this, they need to load in data and drop the star_rating column. Which of the following code blocks accomplishes this task?
- A. spark.read.format("delta").load(path).drop("star_rating")
- B. spark.sql("SELECT * EXCEPT star_rating FROM path")
- C. spark.read.format("delta").table(path).drop("star_rating")
- D. spark.read.table(path).drop("star_rating")
- E. Delta tables cannot be modified
正解:D
質問 # 26
A machine learning engineer has developed a machine learning pipeline that produces a scikit- learn model model and computes the RMSE rmse. MAE mae, and R-squared r2 values for the test set. They now want to log these values with the MLflow run. These values are stored in the dictionary metrics.
They run the following code block:
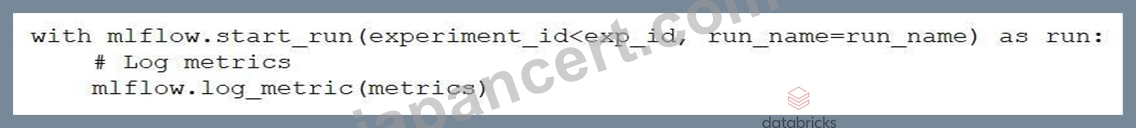
The code block produces an error.
Which changes to the code block will successfully complete the task?
- A. Replace metrics with rmse, mae, r2
- B. Replace mlflow.log_metric with mlflow.sklearn.log_metric
- C. Replace metrics with model
- D. Replace log_metric with log_metrics
正解:D
解説:
The method mlflow.log_metric() logs a single metric, while mlflow.log_metrics() is used to log multiple metrics at once from a dictionary. Since metrics is a dictionary containing rmse, mae, and r2, the correct function is mlflow.log_metrics(metrics).
質問 # 27
Why are Delta tables often used to store machine learning features?
- A. They allow faster GPU training
- B. They reduce model size
- C. They replace Spark DataFrames
- D. They support schema enforcement and time travel
正解:D
解説:
Delta Lake provides:
ACID transactions
time travel
schema enforcement
These are essential for reproducible ML pipelines.
質問 # 28
A machine learning engineer is migrating a machine learning pipeline to use Databricks Machine Learning. They have programmatically identified the best run from an MLflow Experiment and stored its URI in the model_uri variable and its Run ID in the run_id variable. They have also determined that the model was logged with the name "model". Now, the machine learning engineer wants to register that model in the MLflow Model Registry with the name "best_model".
Which of the following lines of code can they use to register the model to the MLflow Model Registry?
- A. mlflow.register_model(model_uri, "best_model")
- B. mlflow.register_model(run_id, "best_model")
- C. mlflow.register_model(f"runs:/{run_id}/best_model", "model")
- D. mlflow.register_model(model_uri, "model")
- E. mlflow.register_model(f"runs:/{run_id}/model")
正解:D
質問 # 29
A Machine Learning Engineer has deployed a customer churn prediction model to production three months ago. The model serves real-time predictions via a Databricks endpoint with inference logging enabled. They notice declining model accuracy in recent weeks and suspect data drift in customer demographics. They need to implement monitoring to track model performance degradation and input feature drift over time. Which monitoring profile type should they use?
- A. Snapshot profile - Monitor the complete inference table to compare current model performance against the baseline established at deployment.
- B. Time series profile - Monitor the inference table using timestamp-based windows to track model performance and input drift over time.
- C. Custom profile - Create a hybrid monitoring approach combining snapshot and time series profiles to capture both baseline comparisons and temporal trends.
- D. Inference profile - Monitor the inference table to track model performance metrics, prediction drift, and input feature drift across time windows.
正解:D
解説:
The inference profile is designed specifically to monitor production model behavior using inference logs. It tracks model performance metrics, prediction distributions, and input feature drift across time windows, enabling detection of performance degradation and demographic data drift after deployment.
質問 # 30
......
Databricks-Machine-Learning-Professional資格参考書: https://www.japancert.com/Databricks-Machine-Learning-Professional.html
- Databricks-Machine-Learning-Professional日本語認定対策 🔛 Databricks-Machine-Learning-Professional無料問題 🐯 Databricks-Machine-Learning-Professional日本語サンプル 🍔 今すぐ{ www.mogiexam.com }を開き、▛ Databricks-Machine-Learning-Professional ▟を検索して無料でダウンロードしてくださいDatabricks-Machine-Learning-Professional的中関連問題
- Databricks-Machine-Learning-Professional試験対策書 😬 Databricks-Machine-Learning-Professional無料問題 📮 Databricks-Machine-Learning-Professional最新資料 ➿ 最新✔ Databricks-Machine-Learning-Professional ️✔️問題集ファイルは▶ www.goshiken.com ◀にて検索Databricks-Machine-Learning-Professional関連復習問題集
- 完璧なDatabricks-Machine-Learning-Professional出題内容試験-試験の準備方法-正確的なDatabricks-Machine-Learning-Professional資格参考書 🎀 ➽ www.shikenpass.com 🢪には無料の{ Databricks-Machine-Learning-Professional }問題集がありますDatabricks-Machine-Learning-Professional科目対策
- 権威のあるDatabricks-Machine-Learning-Professional出題内容 - 合格スムーズDatabricks-Machine-Learning-Professional資格参考書 | ユニークなDatabricks-Machine-Learning-Professional学習教材 💒 [ www.goshiken.com ]に移動し、✔ Databricks-Machine-Learning-Professional ️✔️を検索して、無料でダウンロード可能な試験資料を探しますDatabricks-Machine-Learning-Professional日本語認定対策
- Databricks-Machine-Learning-Professional最新資料 🥗 Databricks-Machine-Learning-Professional関連復習問題集 ‼ Databricks-Machine-Learning-Professional模擬解説集 🎆 「 www.passtest.jp 」の無料ダウンロード➤ Databricks-Machine-Learning-Professional ⮘ページが開きますDatabricks-Machine-Learning-Professional最新資料
- Databricks-Machine-Learning-Professional学習関連題 ⬅️ Databricks-Machine-Learning-Professional模擬解説集 💐 Databricks-Machine-Learning-Professional関連合格問題 🎭 今すぐ⮆ www.goshiken.com ⮄で➤ Databricks-Machine-Learning-Professional ⮘を検索して、無料でダウンロードしてくださいDatabricks-Machine-Learning-Professional模擬解説集
- Databricks-Machine-Learning-Professional日本語復習赤本 🕑 Databricks-Machine-Learning-Professional科目対策 🍇 Databricks-Machine-Learning-Professional無料問題 🍡 ⮆ www.passtest.jp ⮄は、{ Databricks-Machine-Learning-Professional }を無料でダウンロードするのに最適なサイトですDatabricks-Machine-Learning-Professional関連合格問題
- Databricks-Machine-Learning-Professional的中関連問題 💗 Databricks-Machine-Learning-Professional日本語サンプル ✒ Databricks-Machine-Learning-Professional試験問題集 💨 ⮆ www.goshiken.com ⮄の無料ダウンロード⏩ Databricks-Machine-Learning-Professional ⏪ページが開きますDatabricks-Machine-Learning-Professional最新試験
- 有難いDatabricks-Machine-Learning-Professional出題内容 - 合格スムーズDatabricks-Machine-Learning-Professional資格参考書 | 更新するDatabricks-Machine-Learning-Professional学習教材 ⬅ ⏩ www.passtest.jp ⏪を入力して[ Databricks-Machine-Learning-Professional ]を検索し、無料でダウンロードしてくださいDatabricks-Machine-Learning-Professional合格受験記
- Databricks-Machine-Learning-Professional的中関連問題 🌼 Databricks-Machine-Learning-Professional関連合格問題 🌷 Databricks-Machine-Learning-Professional試験問題集 🛴 URL ➠ www.goshiken.com 🠰をコピーして開き、✔ Databricks-Machine-Learning-Professional ️✔️を検索して無料でダウンロードしてくださいDatabricks-Machine-Learning-Professional関連合格問題
- 有効的なDatabricks-Machine-Learning-Professional出題内容一回合格-ハイパスレートのDatabricks-Machine-Learning-Professional資格参考書 🤪 ▷ Databricks-Machine-Learning-Professional ◁の試験問題は【 www.passtest.jp 】で無料配信中Databricks-Machine-Learning-Professional模擬解説集
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, github.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026年Japancertの最新Databricks-Machine-Learning-Professional PDFダンプおよびDatabricks-Machine-Learning-Professional試験エンジンの無料共有:https://drive.google.com/open?id=1ajcYTRVNFWdurfeXHivRvY5lAsn_KN26